Nishi Family › Compare › GPU Stack
Nishi Compare · capabilities, evidence and delivery
GPU Stack
Compare capabilities and delivery evidence. Source discovery, qualification, deployment and accepted outcomes are separate; an open contract names work still to verify.
Nishi vs DirectX 12 and Vulkan 1.4 and Metal and WebGPU -- the sovereign GPU stack from the shader byte up: one NishiLang shader source emitting GLSL and WGSL through the real compiler front-end, the GE43 compute stage (storage buffers, atomics, global_invocation_id) landed 2026-09-02 with a byte-exact gate, a proven /dev/dxg submission lane (a real command accepted by the RTX 5080), an Intel Xe command-streamer framing encoder -- and the API surface the field ships (queues, command lists, heaps, fences, pipeline objects, presentation, capture, conformance, a kernel-mode driver) declared as watch contracts with done-rules. Measured 2026-09-02: 4 present rows, 14 open.
Overview
The purpose, declared position and evidence coverage of this domain. Source presence and completed acceptance are different measures.
Where we are. MEASURED 2026-09-02: the shader byte is sovereign -- nx_wgsl emits GLSL ES 3.00 and WGSL from one NishiLang source through the real compiler front-end (rung 1 fullscreen triangle proven against the hand-written stages that ship, rung 2 with structured control-flow recovery including loops, GE43 compute stage with storage buffers, atomics and global_invocation_id landed today, nx_wgsl_compute_gate 19 of 19 on the laptop build). The submission byte is sovereign -- nx_dxg (the /dev/dxg device HAL shim) has had a real command accepted by the RTX 5080 (SOVEREIGN-GPU ladder R5, _gpu_dxg_submit_gate), and nx_xe frames Intel command-streamer packets. Nothing between those two bytes exists: no command ring, heaps, fences, pipeline objects, swapchain, capture tool, conformance KATs or kernel-mode driver. The /world pages run on WebGL2, a fixed-function float raster we do not control; the WebGPU tier renders the world pass and abstains on characters.
Where we need to go. OPERATOR 2026-09-02: build our own sovereign stack from the first byte up and go all the way to be competitive with DirectX or Vulkan when we get to NishiOS and the Nishi browser -- one NishiLang rasterizer kernel with two doors (WebGPU as a pure submission pipe in third-party browsers, the dxg lane and then our own driver on NishiOS), no third-party GPU API as THE dependency, oracles and conformance suites outside the build path only. OPERATOR 2026-09-03: the target is photorealistic GTA-class output; the stack is sovereign on NishiOS and in the Nishi browser (M2 and M3, where the kernel, the memory, the threads and the present are ours); third-party browsers are the FINAL MILE (M1) -- take the maximum they expose (WebGPU compute, the cross-origin isolation the pages already pay for, cached streaming wasm) and never let them be the dependency or the ceiling; no third-party gatekeeper on system resources -- the browser compositor that owns present, the vendor UMD that owns VRAM and the store that owns install are each named on this board as the thing a rung removes, never as a limit we design to.
Research bar. DirectX 12 is measured on Microsoft's public engineering specifications for Direct3D 12: command queues and lists, heaps and placed resources, fences and enhanced barriers, pipeline state, mesh shaders, DXR, work graphs, HLSL to DXIL [@dxspecs]. Theirs: PINNED gpu.refs dxspecs (mirrored 2026-09-02, 16650 bytes). Ours: ours has the shader emitter and the dxg submit; every API object between them is a watch contract on the board.
Research bar. Vulkan 1.4 is measured on the Khronos Vulkan registry: the specification, SPIR-V as the shader interchange, timeline semaphores, synchronization2, the Conformance Test Suite [@vulkanreg]. Theirs: PINNED gpu.refs vulkanreg (mirrored 2026-09-02, 33862 bytes). Ours: the CTS is the ORACLE this board names for its conformance rung; it never enters the build path.
Research bar. Metal is measured on Apple's GPU API: command queues and buffers, heaps, events, MSL compiled to AIR, mesh shading, ray tracing. Theirs: UNPINNED at admission -- a vendor site behind scripted pages; declared, to be mirrored through nx_research_fetch before any Metal cell is coded above index level. Ours: coded 1 or index-level 2 in gpu.matrix with the notes saying so.
Research bar. WebGPU and WGSL is measured on the W3C WebGPU working draft (adapters, devices, buffers, command encoders, compute and render pipelines, limits) and the WGSL shading language [@webgpu] [@wgsl]. Theirs: PINNED gpu.refs webgpu and wgsl (mirrored 2026-09-02, 4518515 and 3092023 bytes). Ours: the third-party-browser DOOR: our kernel dispatched as compute, our framebuffer blitted; WebGPU rasterizes nothing of ours.
Research bar. Mesa NVK and RADV is measured on the field's proof that a NON-VENDOR driver reaches Vulkan conformance on NVIDIA (NVK over the GSP firmware) and AMD (RADV on the documented RDNA ISA) hardware [@nvk] [@radv]. Theirs: PINNED gpu.refs nvk and radv (mirrored 2026-09-02, 25713 and 57851 bytes). Ours: the precedent the NishiOS driver rungs stand on: the hardware interfaces exist in public and a driver written from them ships.
Latest recorded release
2026-10-01 · GP16
THE LADDER TO SOTA IS DECLARED AND ATTESTED FOR OCTOBER 2026 (cross-board ladder seat, T0 job 1790857487): five sotabar rows (SB-WEBGPU-2609, SB-NATIVEAPI-2609, SB-OPENDRIVER-2609, SB-GPUSPLAT-2609, SB-VRFOVEA-2609), five sotatarget rows (best-in-class T-BIC-DOOR, T-BIC-GPUAPI, T-BIC-DRIVER; frontier T-FR-COMPUTERASTER, T-FR-VRFOVEA) and seventeen rungrole rows (substrate 7, arm 2, contender 8); twelve rows added to gpu.refs, ten mirrors fetched through nx_research_fetch on 2026-10-01 and read from the mirrored bytes, one the estate attester's same-day arXiv fetch copied to a pinned mirror, one a gameengine mirror re-hashed today. nx_ladder gpu reads LADDERED (17 of 17 placed, no unclimbed target); nx_barfresh gpu reads FRESH with 5 of 5 ATTESTED; nx_compare_rank gpu is not refused and ranks GP4, GP5, GP8 toward version 1.0. One barscan was appended by nx_frontier_scan attest itself (the arXiv listing: 8 items, newest 2026-09) and four by attestfile from this seat's reads, because the organ answers ATTEST-UNATTESTABLE reason=no-dated-source-row-knows-this-listing for GitHub Atom feeds and for the Mesa page; its fan-out over 85 fetches read newer_sources=0 stale_bars=0.
Release entries describe recorded changes; they do not establish that every capability passed evaluation.
8 of 22 capability source symbols found|0 of them authored stronger-claims|14 open|coverage 363/1000|adoption 2 full / 6 partial
Evidence profile — what the gaps on this board actually are
Measured by nx_swcompare_evidence, read back by nx_evprofile_lib. Every figure is a count with its denominator — there is deliberately no score, no grade and no percentage anywhere in this band, because a stored scalar is a field a seat can edit and a counted partition is not.
evidence|grounded 6/6|unsupported 0|gates green 2/2|proven able to fail 1/2|never bitten 1|green at 0/0 0|open gaps 13|of them unnamed 0|of them proof withheld 0|flips ready 2
proven able to fail counts the gates that have a RECORDED RED — nx_gate_bite mutated the gate subject, rebuilt it, watched the gate go red, and that record is inside the shared TTL. never bitten is its complement over the same denominator: those gates ran and were green, and nothing has ever shown them able to detect anything, so their green is a statement about this run and not about the gate. green at 0/0 is a separate and much weaker observation — the gate printed GREEN on a zero denominator, so its own tooth counter says it examined nothing. A gate can be green, non-zero, and still never bitten; that is the common case and it is now visible instead of implied.
partition: grounded + unsupported = 6 vs present 6 · named + unnamed + withheld = 13 vs open 13 · both reconcile
liar-kill conj=GPQN · all four conjuncts held
graded document: BUILDROOT tree, 14354 bytes · gates map: PRIMARY · stamped 35d 17h ago · STALE against the shared TTL of 604800s — this is evidence about a build nobody can vouch for now · source ../knowledge/status/evstamp_gpu.verdict
| Gap class | What it is, and the work it names |
|---|---|
| FLIP-READY | A watch contract symbol is now present in the organ it named: the cell can flip on a pure data edit with no new code. These are the cheapest closures on this board and they belong before any new work. |
| STALE | This profile is older than the shared TTL, or its clock ran backwards. It is reported as unusable rather than as fresh, because being wrong in the direction of refusing is the safe direction. |
nx_swcompare_evidence gpu itself and are not carried on the stamp, so this page names the classes and the producer names the rows. That split is stated rather than hidden: a count without a worklist is not actionable, and this band is honest about which half of that it is.Production map
Follow the dependencies, declared acceptance criteria and recorded priorities. Inspect source binding before treating a rank as executable work.
Ranking source binding: STALE_OR_INVALID_BINDING. Recorded priorities require current acceptance evidence and resource checks before execution.
Recorded ranking withheld
Retained ranking is not bound to the current plan and matrix: STALE_OR_INVALID_BINDING. Historical data remains retained. Refresh the ranking after resolving the input differences. Latest execution outcome is unverified.
Declared roadmap — contract, acceptance, executor, effort
Milestones
| Milestone | Rungs | Cumulative |
|---|---|---|
| M1 · The browser door: the sovereign kernel draws through WebGPU as a pure submission pipe | GP1,GP2,GP3 | 3 u |
| M2 · The dxg door: our command ring, heaps, fences and pipelines over the proven submit, a DXIL backend for the host driver | GP4,GP5,GP6,GP7,GP8 | 8 u |
| M3 · The NishiOS door: a kernel-mode driver on documented hardware, present and compositor, the raster rung native | GP9,GP10,GP11 | 13 u |
| M4 · Proof and tooling: conformance KATs, capture and replay | GP12,GP13 | 15 u |
| M5 · Competitive parity: the NVIDIA GSP lane, mesh and ray-query stages, the bench spine | GP14,GP15,GP16 | 18 u |
| M6 · The exceed earned: integer-deterministic raster proven byte-identical on two vendors | GP17 | 19 u |
| Rung | Closes with | Definition of done (pre-declared) | Executor | Est. |
|---|---|---|---|---|
| The compute stage in the shader backend (GP1) | wgsl_compute_stage | storage buffers (read and read_write, atomic elements), atomic read-modify-write with the address supplied by the backend, the global_invocation_id builtin, the @compute entry with a named workgroup size; GLSL refuses the stage, the declaration and the builtin each BY NAME; done-rule: nx_wgsl_compute_gate asserts the depth-min kernel bytes exactly and the three refusals. LANDED 2026-09-02 (laptop 19 of 19; NAS build queued behind admission) | Organ | 1 u |
| The WebGPU door (GP2) after GP1 | rk_webgpu_door | the GE43 kernel dispatched through a WebGPU compute pipeline from OUR WGSL emit, its framebuffer blitted by the rung-1 fullscreen triangle; WebGPU performs no rasterization of ours; done-rule: the page draws the kernel's frame and the framebuffer read back equals the CPU reference kernel byte for byte on the same inputs | Organ | 1 u |
| The tier ladder (GP3) after GP2 | rk_tier_ladder | per host the door is chosen by measured capability (WebGPU present and the kernel's limits satisfied, else the sovereign wasm raster), announced on the HUD telemetry line, never by user-agent sniffing; done-rule: nx_glprobe records the door taken and a gate proves the fallback fires when WebGPU is refused | Organ | 1 u |
| The DXIL backend (GP4) after GP1 | dxil_emit_module | a third backend over nx_shader_ir emitting a DXIL container for the GE43 subset, so the dxg host driver can consume our compute kernel; done-rule: trace identity with the WGSL emit and a dispatch through nx_dxg that writes the same bytes as the WGSL door | Organ | 2 u |
| The command ring (GP5) after GP4 | gpu_cmd_ring | record a command list once, submit it with a fence through dxg_submit_hwq, replay it; done-rule: two submissions of one recorded list read back identical buffer bytes, and a gate detects a corrupted list as a refused submit | Organ | 1 u |
| Heaps and residency (GP6) after GP5 | gpu_mem_exhaust | MECHANISM LANDED 2026-09-02 (nx_gpu_mem: gpu_mem_budget / gpu_mem_heap / gpu_mem_evict over the shim's size-swept QUERYVIDEOMEMORYINFO and EVICT; nx_gpu_mem_gate GREEN on the 5080 with the window accounted byte-exactly and every evicted heap answering PAGING-PENDING on re-residency); the OPEN contract is EXHAUSTION: allocate to the LOCAL (VRAM) budget and prove the driver evicts rather than hangs -- which needs VRAM allocations the vendor UMD owns (the GP5 blocker class; the non-local segment is host RAM and is not to be exhausted), so this rung stays open on gpu_mem_exhaust | Organ | 1 u |
| Fences and barriers (GP7) after GP5 | gpu_sync_barrier | FENCE HALF LANDED 2026-09-02 (nx_gpu_sync gpu_sync_fence: a monitored fence created on the 5080 through raw dxg, CPU-signalled and CPU-waited, nx_gpu_sync_gate 10 of 10 on the GPU laptop, SKIP where there is no /dev/dxg); the OPEN contract is the barrier half: a barrier a recorded list carries between a write and a read; done-rule: a gate removes the barrier and observes the wrong read the fence discipline exists to prevent -- which needs a list the door can execute (GP5 lesson row), so this rung stays open on gpu_sync_barrier | Organ | 1 u |
| Pipeline objects (GP8) after GP4 | gpu_pipeline | a compute and a raster pipeline object carrying the bytecode from GP4 plus fixed state, cached by content hash; done-rule: the same source never compiles twice within a run, proven by the cache counter | Organ | 1 u |
| The kernel-mode driver on documented hardware (GP9) after GP5 | gpu_kmd_nishios | PCIe BAR discovery and map, ring buffer and doorbell, interrupt handling and GPU page tables for AMD RDNA in NishiLang, on the NishiOS kernel; every hardware write is volatile and NO firmware, VBIOS or EEPROM write path exists in the source (Rule 26); done-rule: a compute dispatch writes a known buffer on real hardware and nx_neverbrick_gate reads the driver GREEN | Organ | 3 u |
| Present and compositor (GP10) after GP9 | gpu_present_compositor | our own swapchain, vsync and compositor on the NishiOS door and in the Nishi browser; done-rule: nx_frame_pacing_gate reads the pacing from our present queue, not from a host compositor | Organ | 1 u |
| The raster rung on the native lane (GP11) after GP9 | gpu_raster_rung | the compute rasterizer kernel over the KMD, the contract graphics and gameengine already carry; done-rule: a frame drawn on NishiOS with no vendor driver in the process, framebuffer diff zero against the WebGPU door | Organ | 1 u |
| Conformance KATs (GP12) after GP8 | gpu_conformance_oracle | chosen Vulkan CTS and WebGPU CTS cases mirrored as KATs our doors must pass, the suites themselves run OUTSIDE the build path as oracles and their numbers pinned in gpu.bench; done-rule: the KAT set is named, the pass count is on the board, and no third-party binary is linked, forked or shelled by any organ in the lane | Gate | 1 u |
| Capture and replay (GP13) after GP5 | gpu_debug_capture | the recorded lists ARE the capture: replay a captured frame through the same ring and diff the framebuffer; done-rule: an injected one-byte change in a captured list is found by the diff | Organ | 1 u |
| The NVIDIA lane over GSP (GP14) after GP9 | gpu_nv_gsp_lane | the GSP RPC surface and the class methods NVK documents, in NishiLang, first as a compute dispatch that writes a known buffer on the RTX 5080; done-rule: the same as GP9 on NVIDIA hardware, never-brick proven the same way | Organ | 3 u |
| Mesh and ray-query stages (GP15) after GP8 | gpu_mesh_rt | a mesh-shading stage and a ray-query stage in nx_shader_ir, refused by name on every door that lacks them; done-rule: one mesh dispatch and one ray query proven on a door that has them | Organ | 1 u |
| The bench spine (GP16) after GP11 | gpu_bench_spine | frame time and dispatch throughput of the same kernel through our doors against DirectX 12 and Vulkan reference programs on the same hardware, appended to gpu.bench as receipts with host, versions and checksums (the lang.bench shape); done-rule: two runs agree and the page renders the receipt | Gate | 1 u |
| The deterministic-raster exceed (GP17) after GP11,GP14 | rk_kernel_ir | the kernel IR whose integer raster produces bit-identical frames on two vendors; done-rule: framebuffer bytes identical across AMD and NVIDIA on the same inputs, proven by a gate that runs both -- only then does gpu.matrix claim the exceed | Organ | 1 u |
Ladder to SOTA
| Rung | Role | Toward | Stands on | Why |
|---|---|---|---|---|
| GP1 | substrate | T-BIC-DOOR | - | the compute stage every door dispatches; landed |
| GP2 | contender | T-BIC-DOOR | GP1 | its done-rule is a number against the door: the framebuffer read back byte-equal to the CPU reference (measured diff=0 over 65536 lanes on 2026-09-02) |
| GP3 | substrate | T-BIC-DOOR | GP2 | the ladder that picks the door per host by measured capability and announces the refusals |
| GP4 | substrate | T-BIC-GPUAPI | GP1 | the shader interchange a host driver consumes |
| GP5 | substrate | T-BIC-GPUAPI | GP4 | record once, submit with a fence, replay: the object every other API rung stands on |
| GP6 | substrate | T-BIC-GPUAPI | GP5 | heaps and residency under the ring |
| GP7 | substrate | T-BIC-GPUAPI | GP5 | fences and barriers under the ring |
| GP8 | substrate | T-BIC-GPUAPI | GP4 | pipeline objects cached by content hash, what GP12 and GP15 stand on |
| GP9 | contender | T-BIC-DRIVER | GP5 | its done-rule is a compute dispatch on real AMD hardware with never-brick read GREEN, the RADV-class claim |
| GP10 | contender | T-FR-VRFOVEA | GP9 | its done-rule is pacing read from our own present queue; headset cadence is a present contract first |
| GP11 | contender | T-FR-COMPUTERASTER | GP9 | its done-rule is a native frame with framebuffer diff zero against the WebGPU door: the compute rasteriser on the lane we own |
| GP12 | arm | T-BIC-GPUAPI | GP8 | the conformance suites run outside the build path as oracles: a referee for the API rungs, never a competitor for the number |
| GP13 | arm | T-BIC-GPUAPI | GP5 | capture and replay triangulates the ring by framebuffer diff without competing for a number |
| GP14 | contender | T-BIC-DRIVER | GP9 | the GP9 done-rule on the RTX 5080, the card class NVK is conformant on |
| GP15 | contender | T-BIC-GPUAPI | GP8 | mesh and ray-query stages proven on a door that has them, refused by name elsewhere |
| GP16 | contender | T-BIC-GPUAPI | GP11 | frame time and dispatch throughput against Direct3D 12 and Vulkan reference programs on the same hardware, as receipts |
| GP17 | contender | T-FR-COMPUTERASTER | GP11,GP14 | framebuffer bytes identical across two vendors: the exceed no entry in the September listing claims |
Ladder verdict, counted (17 rows, more than the 12-row disclosure bar)
| Class | Count | Note |
|---|---|---|
| targets | 5 | sotatarget rows on the plan |
| best in class | 3 | targets whose class is best-in-class, by code |
| frontier | 2 | targets whose class is frontier, by code |
| undated | 0 | targets naming no bar that exists |
| bad class | 0 | targets whose class is neither word |
| duplicate | 0 | target ids an earlier row already carries |
| rungs | 17 | rung rows on the plan |
| placed | 17 | rungs carrying a rungrole row |
| unplaced | 0 | rungs with no role toward any target |
| bad role | 0 | rungrole rows naming a role the ladder does not know |
| bad target | 0 | rungrole rows naming a target no sotatarget row declares |
| rungs, summed | 17 | RECONCILED: the parts sum to the total 17 |
| substrate | 7 | what the target's own methods consume |
| arm | 2 | a sovereign arm that triangulates without competing for the number |
| contender | 8 | its done-rule is a number against the target |
| superseded | 0 | kept as capability, retired as a claim |
| placed, summed | 17 | RECONCILED: the parts sum to the total 17 |
| Class | Count | Note |
|---|---|---|
| bars | 5 | sotabar rows on the plan |
| fresh | 0 | the bar month is the current month |
| attested | 5 | an older bar with a this-month barscan reporting no newer entry |
| stale | 0 | a this-month scan saw a newer month the bar ignores |
| unattested | 0 | nobody looked this month |
| malformed | 0 | a sotabar row missing a field |
| duplicate | 0 | bar ids an earlier row already carries |
| bars, summed | 5 | RECONCILED: the parts sum to the total 5 |
| current month | 2026-10 | the month every bar is judged against |
Inspect a rung and its prerequisites
Declared nodes 17. Rank input binding: STALE_OR_INVALID_BINDING. Dependency order is authored. Implementation, acceptance evidence, authority and resource readiness are unverified. No action is recommended or dispatched here.
Plan SHA-256 78b1a3d0854d745b38eddeff65a78b976f908bedd4e4da5a6ddd6b41724881a8. Target rows 5; role rows 17. Existing risks and release worklog retain their own scope; no node completion is inferred.
Runtime observation coverage: 0 of 17 rungs have current, identity-bound execution observations. Observation may report RED. Accepted completion remains unknown; source presence, qualification and deployment do not establish it.
Use Enter or Space on a rung to inspect its contract. Prerequisite links locate another rung in this list; open its summary to inspect it. Estimates are authored effort, not forecasts.
GP1 — The compute stage in the shader backend
Prerequisites: None declared; this does not establish execution eligibility.
Contract:
wgsl_compute_stageAcceptance: storage buffers (read and read_write, atomic elements), atomic read-modify-write with the address supplied by the backend, the global_invocation_id builtin, the @compute entry with a named workgroup size; GLSL refuses the stage, the declaration and the builtin each BY NAME; done-rule: nx_wgsl_compute_gate asserts the depth-min kernel bytes exactly and the three refusals. LANDED 2026-09-02 (laptop 19 of 19; NAS build queued behind admission)
Authored effort: 1. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.GP2 — The WebGPU door
Prerequisites: GP1 (acceptance unverified)
Contract:
rk_webgpu_doorAcceptance: the GE43 kernel dispatched through a WebGPU compute pipeline from OUR WGSL emit, its framebuffer blitted by the rung-1 fullscreen triangle; WebGPU performs no rasterization of ours; done-rule: the page draws the kernel's frame and the framebuffer read back equals the CPU reference kernel byte for byte on the same inputs
Authored effort: 1. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.GP3 — The tier ladder
Prerequisites: GP2 (acceptance unverified)
Contract:
rk_tier_ladderAcceptance: per host the door is chosen by measured capability (WebGPU present and the kernel's limits satisfied, else the sovereign wasm raster), announced on the HUD telemetry line, never by user-agent sniffing; done-rule: nx_glprobe records the door taken and a gate proves the fallback fires when WebGPU is refused
Authored effort: 1. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.GP4 — The DXIL backend
Prerequisites: GP1 (acceptance unverified)
Contract:
dxil_emit_moduleAcceptance: a third backend over nx_shader_ir emitting a DXIL container for the GE43 subset, so the dxg host driver can consume our compute kernel; done-rule: trace identity with the WGSL emit and a dispatch through nx_dxg that writes the same bytes as the WGSL door
Authored effort: 2. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.GP5 — The command ring
Prerequisites: GP4 (acceptance unverified)
Contract:
gpu_cmd_ringAcceptance: record a command list once, submit it with a fence through dxg_submit_hwq, replay it; done-rule: two submissions of one recorded list read back identical buffer bytes, and a gate detects a corrupted list as a refused submit
Authored effort: 1. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.GP6 — Heaps and residency
Prerequisites: GP5 (acceptance unverified)
Contract:
gpu_mem_exhaustAcceptance: MECHANISM LANDED 2026-09-02 (nx_gpu_mem: gpu_mem_budget / gpu_mem_heap / gpu_mem_evict over the shim's size-swept QUERYVIDEOMEMORYINFO and EVICT; nx_gpu_mem_gate GREEN on the 5080 with the window accounted byte-exactly and every evicted heap answering PAGING-PENDING on re-residency); the OPEN contract is EXHAUSTION: allocate to the LOCAL (VRAM) budget and prove the driver evicts rather than hangs -- which needs VRAM allocations the vendor UMD owns (the GP5 blocker class; the non-local segment is host RAM and is not to be exhausted), so this rung stays open on gpu_mem_exhaust
Authored effort: 1. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.GP7 — Fences and barriers
Prerequisites: GP5 (acceptance unverified)
Contract:
gpu_sync_barrierAcceptance: FENCE HALF LANDED 2026-09-02 (nx_gpu_sync gpu_sync_fence: a monitored fence created on the 5080 through raw dxg, CPU-signalled and CPU-waited, nx_gpu_sync_gate 10 of 10 on the GPU laptop, SKIP where there is no /dev/dxg); the OPEN contract is the barrier half: a barrier a recorded list carries between a write and a read; done-rule: a gate removes the barrier and observes the wrong read the fence discipline exists to prevent -- which needs a list the door can execute (GP5 lesson row), so this rung stays open on gpu_sync_barrier
Authored effort: 1. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.GP8 — Pipeline objects
Prerequisites: GP4 (acceptance unverified)
Contract:
gpu_pipelineAcceptance: a compute and a raster pipeline object carrying the bytecode from GP4 plus fixed state, cached by content hash; done-rule: the same source never compiles twice within a run, proven by the cache counter
Authored effort: 1. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.GP9 — The kernel-mode driver on documented hardware
Prerequisites: GP5 (acceptance unverified)
Contract:
gpu_kmd_nishiosAcceptance: PCIe BAR discovery and map, ring buffer and doorbell, interrupt handling and GPU page tables for AMD RDNA in NishiLang, on the NishiOS kernel; every hardware write is volatile and NO firmware, VBIOS or EEPROM write path exists in the source (Rule 26); done-rule: a compute dispatch writes a known buffer on real hardware and nx_neverbrick_gate reads the driver GREEN
Authored effort: 3. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.GP10 — Present and compositor
Prerequisites: GP9 (acceptance unverified)
Contract:
gpu_present_compositorAcceptance: our own swapchain, vsync and compositor on the NishiOS door and in the Nishi browser; done-rule: nx_frame_pacing_gate reads the pacing from our present queue, not from a host compositor
Authored effort: 1. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.GP11 — The raster rung on the native lane
Prerequisites: GP9 (acceptance unverified)
Contract:
gpu_raster_rungAcceptance: the compute rasterizer kernel over the KMD, the contract graphics and gameengine already carry; done-rule: a frame drawn on NishiOS with no vendor driver in the process, framebuffer diff zero against the WebGPU door
Authored effort: 1. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.GP12 — Conformance KATs
Prerequisites: GP8 (acceptance unverified)
Contract:
gpu_conformance_oracleAcceptance: chosen Vulkan CTS and WebGPU CTS cases mirrored as KATs our doors must pass, the suites themselves run OUTSIDE the build path as oracles and their numbers pinned in gpu.bench; done-rule: the KAT set is named, the pass count is on the board, and no third-party binary is linked, forked or shelled by any organ in the lane
Authored effort: 1. Executor kind: Gate. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.GP13 — Capture and replay
Prerequisites: GP5 (acceptance unverified)
Contract:
gpu_debug_captureAcceptance: the recorded lists ARE the capture: replay a captured frame through the same ring and diff the framebuffer; done-rule: an injected one-byte change in a captured list is found by the diff
Authored effort: 1. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.GP14 — The NVIDIA lane over GSP
Prerequisites: GP9 (acceptance unverified)
Contract:
gpu_nv_gsp_laneAcceptance: the GSP RPC surface and the class methods NVK documents, in NishiLang, first as a compute dispatch that writes a known buffer on the RTX 5080; done-rule: the same as GP9 on NVIDIA hardware, never-brick proven the same way
Authored effort: 3. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.GP15 — Mesh and ray-query stages
Prerequisites: GP8 (acceptance unverified)
Contract:
gpu_mesh_rtAcceptance: a mesh-shading stage and a ray-query stage in nx_shader_ir, refused by name on every door that lacks them; done-rule: one mesh dispatch and one ray query proven on a door that has them
Authored effort: 1. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.GP16 — The bench spine
Prerequisites: GP11 (acceptance unverified)
Contract:
gpu_bench_spineAcceptance: frame time and dispatch throughput of the same kernel through our doors against DirectX 12 and Vulkan reference programs on the same hardware, appended to gpu.bench as receipts with host, versions and checksums (the lang.bench shape); done-rule: two runs agree and the page renders the receipt
Authored effort: 1. Executor kind: Gate. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.GP17 — The deterministic-raster exceed
Prerequisites: GP11 (acceptance unverified), GP14 (acceptance unverified)
Contract:
rk_kernel_irAcceptance: the kernel IR whose integer raster produces bit-identical frames on two vendors; done-rule: framebuffer bytes identical across AMD and NVIDIA on the same inputs, proven by a gate that runs both -- only then does gpu.matrix claim the exceed
Authored effort: 1. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.
Learning and practice paths
No structured learning path is declared for this plan. Existing research, roadmap and worklog remain available above.
Rung dossiers — every record that bears on a rung, in one place
nx_swcompare_evidence gpu writes it beside its stamp); every gate below reads UNRECORDED until it runs.knowledge/organ_gate.conf read from this working directory (1 rows) and from the estate root (196 rows); rows in both counted once: 0; declarations read: 197. Every declaration in either copy counts, so a stub beside the publisher can never hide the root.GP1 The compute stage in the shader backend · cell PRESENT · gate UNRECORDED
| Contract | wgsl_compute_stage · executor Organ · 1 u · stands on nothing |
|---|---|
| Definition of done | storage buffers (read and read_write, atomic elements), atomic read-modify-write with the address supplied by the backend, the global_invocation_id builtin, the @compute entry with a named workgroup size; GLSL refuses the stage, the declaration and the builtin each BY NAME; done-rule: nx_wgsl_compute_gate asserts the depth-min kernel bytes exactly and the three refusals. LANDED 2026-09-02 (laptop 19 of 19; NAS build queued behind admission) |
| Matrix cell | SHADER: the compute stage -- storage buffers (read and read_write, atomic elements), atomic read-modify-write, global_invocation_id, the @compute entry (GE43) · runtime/nx_wgsl.nx · PRESENT decl |
| Gate | nx_wgsl_compute_gate · UNRECORDED — no recorded verdict for this gate (it is declared for the organ but the evidence referee's last run did not record it: it is not on this board's gates map, or the referee has not run since the per-gate record shipped) |
| Work log | 2026-09-02 land nx_shader_ir.nx grew K_STORAGE, S_EXPR, E_ATOMIC and vec3u with builders; nx_wgsl.nx grew STAGE_COMPUTE, WG_WORKGROUP, storage-buffer emission, atomicMin with the backend-supplied address, the global_invocation_id builtin bound to gid, wgsl_compute_stage, shsrc_depth_min and the compute verb; the GLSL backend refuses the stage, the storage declaration and the builtin each by name. Laptop build: nx_wgsl compute emits 252 bytes, 14 nodes; nx_wgsl_compute_gate 19 of 19 GREEN. Sources landed on the NAS (buildroot/runtime, 18449 + 73033 + 10042 bytes, CAS receipts read back); NAS builds queued. 2026-09-02 lesson the first cut of the gate hand-counted the contract length beside the six string literals and was wrong by nine bytes on its first run: a hand-counted length beside a literal is a second copy of that literal's shape and the two drift. The gate now DERIVES the length from the literals at run time. 2026-09-03 land nx_wgsl_compute_gate HAND-ADDED to knowledge/gateroster.conf after /api/gate_run read it 19 of 19 GREEN on the FAST path with exit 0 on the NAS; the ranker's REGISTERED-DARK reading of GP1 was a gate nobody ran, and a gate nobody runs is a comment. 2026-09-03 land nx_wgsl_compute_gate 19 of 19 GREEN on the NAS via /api/gate_run (exit_code 0, subject ./nx_wgsl.elf, compute emit 782 B, contract 252 B announced = derived) and ROSTERED in knowledge/gateroster.conf, so the rung now has an execution surface -- the ranker had read it REGISTERED-DARK (registered, no cap ever minted, no surface). gpu.gates already carries its row; the honesty board can read the domain as gated evidence instead of CLAIM-ONLY on its next regen. |
GP2 The WebGPU door · cell LANDED · gate UNRECORDED
| Contract | rk_webgpu_door · executor Organ · 1 u · stands on GP1 |
|---|---|
| Definition of done | the GE43 kernel dispatched through a WebGPU compute pipeline from OUR WGSL emit, its framebuffer blitted by the rung-1 fullscreen triangle; WebGPU performs no rasterization of ours; done-rule: the page draws the kernel's frame and the framebuffer read back equals the CPU reference kernel byte for byte on the same inputs |
| Matrix cell | BROWSER: WebGPU as a pure submission pipe for the sovereign kernel (GE44, the third-party-browser door) · runtime/nx_game_page_emit.nx · LANDED decl |
| Gate | nx_game_page_emit_gate · UNRECORDED — no recorded verdict for this gate (it is declared for the organ but the evidence referee's last run did not record it: it is not on this board's gates map, or the referee has not run since the per-gate record shipped) |
| Work log | 2026-09-02 land rk_webgpu_door LANDED in runtime/nx_game_page_emit.nx (340486 -> 348297 B, five chained CAS hunks): at emit time the emitter forks the DEPLOYED shader backend (nx_wgsl compute) and embeds the captured kernel WGSL as KWGSL (never a hand-written copy; an absent capture emits KWGSL=null and a NAMED telemetry state), and nxKernelProbe(dev) under ?gpu=1&kernel=1 dispatches it through the page's WebGPU device over two hash-seeded u32 storage buffers, reads the depth buffer back and diffs it against the CPU minimum; the workgroup width is parsed from the WGSL text so the geometry has one owner. HUD telemetry gains kernel=. nx_craft_emit rebuilt on the laptop from a closure hashed identical to the NAS (23 files) and PROMOTED a08dedb7 through the content-put lane with allow_capability_loss=yes. 2026-09-02 measure matched-vintage size control: the UNEDITED NAS source built by the laptop toolchain is 519847 B against the NAS-built live 555112 B, so the 22 KB shrink of the edited laptop build (533095 B) is the toolchain, not the edit -- the edit is +13248 B on the control. nx_contentdiff live-vs-staged lost_from_live=305: source-path literals the NAS debug lane embeds (runtime/nx_tier.nx and siblings) plus the two reworded HUD literals; the laptop driver ignores --debug, so this promote DROPS crash-address resolution for this binary until the queued NAS build supersedes it. Named, not hidden. 2026-09-02 queue the DONE-RULE IS UNMEASURED: kernel diff=0 must be read in a WebGPU-capable browser on nishifamily.com/world/beach?gpu=1&kernel=1&hud=1 (the HUD line ends with kernel OK n=65536 diff=0 ms= wg=64). Headless Chromium wedges on this page and Waterfox has no WebGPU, so the first reading is the operator's or a Chromium marionette lane; until then GP2 reads present-by-symbol and incomplete-by-rule. 2026-09-02 lesson a promote whose response was dropped by the edge HAD LANDED (the retry read NOTHING-STAGED with live sha == staged) -- check the artifact before retrying; and the world emitter's MCP tool with NO arguments RUNS the whole pipeline (four such runs today), so never probe its usage with an empty argv. 2026-09-03 measure the GP2 done-rule (kernel diff=0 in a WebGPU browser) is STILL UNMEASURED, but its blocker is now NAMED by the page itself: in headless Edge the WebGPU door is refused as failed:finished-after-boot-ceiling, so the kernel probe never dispatches. The next reading needs either a longer boot ceiling under a headless lever (a conf row, not a constant) or a headed WebGPU browser; requestAdapter absence was NOT the cause. 2026-09-03 measure THE DONE-RULE IS MET. Through a REAL-TIME headless session (nishi-ops/ac_cdp.py: the Chromium sibling of the Waterfox marionette wire, DevTools protocol over a stdlib websocket, a 45 s real wait, one JS evaluation) on nishifamily.com/world/beach?gpu=1&kernel=1&hud=1&gpuboot=20000 the served page reads: door webgpu-compute refused webgpu-compute:taken,webgl2:below-taken,sovereign-cpu:below-taken and kernel OK n=65536 diff=0 ms=805 wg=64 -- the GE43 compute kernel captured from the deployed shader backend at emit time, dispatched through the browser's WebGPU door over two hash-seeded u32 storage buffers, read back and byte-equal to the CPU reference on all 65536 lanes (805 ms, workgroup 64 parsed from the WGSL). The frame line reads WebGPU (world pass) 735x368 q1 p50 6 ms. GP2 is measured; GP1's kernel is proven end to end through the door. 2026-09-03 lesson a --dump-dom under --virtual-time-budget CANNOT witness a GPU race: virtual time advances while the real requestAdapter/requestDevice work is still in flight, so every timeout-based ceiling loses (with the lever at 20 s the page still read finished-after-boot-ceiling), and without the budget the dump fires at the load event before the ladder resolves. A reading of the kernel door needs REAL seconds in a live session -- which is why the DevTools wire exists. The boot ceiling still had to become data: the lever is what a probe on a slow host will need, and the clamp is what keeps a URL from holding a visitor. 2026-09-03 queue OPERATOR 2026-09-03 reframed the ladder for this board (goal row): third-party browsers are the FINAL MILE (M1), NishiOS and the Nishi browser are where the stack is sovereign (M2, M3), and no third-party gatekeeper on system resources is designed to. Read against the ranker the same day (nx_compare_rank gpu: GP5 command ring first, GP8, GP6, GP7, GP4 toward version 1.0; GP16 was UNMAPPED -- no matrix row carried gpu_bench_spine -- and gpu.matrix now carries it): the M1 door is proven (GP1 GP2 GP3 landed, kernel diff=0 through WebGPU) and the M2 door is blocked by the vendor UMD (GP5 lesson row), so the honest next legs are the browser-door consumers (GE30 tiles and PF13 on lang LN33, GE1 cast parity on the WebGPU tier) and the GP14-lite method stream the operator paces. |
GP3 The tier ladder · cell LANDED · gate UNRECORDED
| Contract | rk_tier_ladder · executor Organ · 1 u · stands on GP2 |
|---|---|
| Definition of done | per host the door is chosen by measured capability (WebGPU present and the kernel's limits satisfied, else the sovereign wasm raster), announced on the HUD telemetry line, never by user-agent sniffing; done-rule: nx_glprobe records the door taken and a gate proves the fallback fires when WebGPU is refused |
| Matrix cell | BROWSER: the render-door ladder is DATA and every visitor sees which door drew the frame and why each higher door was refused (GP3, GE45) · runtime/nx_game_page_emit.nx · LANDED decl |
| Gate | nx_game_page_emit_gate · UNRECORDED — no recorded verdict for this gate (it is declared for the organ but the evidence referee's last run did not record it: it is not on this board's gates map, or the referee has not run since the per-gate record shipped) |
| Work log | 2026-09-03 land rk_tier_ladder LANDED: knowledge/tier_ladder.conf carries the ladder as DATA (door rows webgpu-compute levered gpu=1, webgl2 default, sovereign-cpu fallback gl=0; limit rows maxComputeInvocationsPerWorkgroup 64, maxStorageBufferBindingSize 262144, maxComputeWorkgroupsPerDimension 1024); runtime/nx_tier_ladder_lib.nx parses it (REFUSING a ladder without a fallback, a fallback that is not last, an order regression, a quote or backslash in a field, an unknown state, a non-positive limit), walks it natively (tl_pick, tl_reason) and emits the JS twin (window.__nx_ladder, window.__nx_gpu_limits, nxDoorId, nxDoor, nxDoorReport) with ONE reason vocabulary; tl_emit announces TIER-LADDER-ABSENT-AT-EMIT and emits a NAMED absence. runtime/nx_tier_ladder_gate.nx reads 36 of 36 GREEN on the NAS through /api/gate_run (PROMOTED 870811618e, REGISTERED, on knowledge/gateroster.conf, gpu.gates row). runtime/nx_game_page_emit.nx (ten CAS hunks, both trees 211851ef): func rk_tier_ladder() composes tl_emit(), tele() gains door and refused, the HUD line ends door <id> refused <door:reason,...>, the ladder resolution sets window.__sov_door through nxDoorId(requires), and gpuInit refuses a device under any conf minimum as limit:<key>=<have><<need>. nx_craft_emit rebuilt on the laptop and PROMOTED 5d5dbb2b through the content-put lane with the loss NAMED (the five rewritten JS runs: tele, line, the ladder announcement, the GPU-died and GL-died lines). nx_publish_verify grew file_ladder= and served_ladder= (NAS-built, PROMOTED cba1deb2). gpu.matrix gained the BROWSER rk_tier_ladder row. 2026-09-03 lesson thirty-three green teeth missed that the HUD's door field calls nxDoor() and the twin never defined it: every visitor would have read door ladder-absent while the gate stayed green. nx_contentdiff's LOST list, read rather than filtered, exposed it before the promote. A twin's gate must enumerate the CONSUMER's call sites, not the producer's exports -- two teeth added, both twins pinned. 2026-09-03 queue the live half of the done-rule waits on the world pipeline run launched after the promote and a headless read of the served HUD: the ordinary visitor should read door webgl2 refused webgpu-compute:levered-off,webgl2:taken,sovereign-cpu:below-taken, and ?gpu=1 on a refusing host failed:<message> or limit:<key>. nx_glprobe recording the door is NOT done -- the HUD line and publish_verify's served_ladder carry it today. 2026-09-03 measure SERVED, READ BACK: nx_publish_verify beach -> SERVED-CURRENT stamp b1788394161 file_ladder=1 served_ladder=1 (edge delta 995 B). Headless Edge (--headless=new, virtual-time budget 25 s, dump-dom) of nishifamily.com/world/beach?hud=1 reads the HUD line ending door webgl2 refused webgpu-compute:levered-off,webgl2:taken,sovereign-cpu:below-taken -- the ordinary visitor's walk, word for word what tl_pick and tl_reason return for the same inputs. Under ?gpu=1&kernel=1&hud=1 the same read ends door webgl2 refused webgpu-compute:failed:finished-after-boot-ceiling; ladder already moved on (canvas untouched),webgl2:taken,sovereign-cpu:below-taken -- the first time the page has SAID why the kernel read unrun on this host: the WebGPU init outlived the page's GPU_BOOT_MS ceiling under a virtual-time budget, and the ladder moved on. The door and the refusal are now data on every visitor's HUD; the done-rule's fallback half (WebGPU refused -> the next door draws, announced) is witnessed live. 2026-09-03 land the boot ceiling is DATA: knowledge/tier_ladder.conf grew boot 2026-09-03 measure THE BEACH ENDPOINT IS ISOLATED ON THE WIRE, MEASURED 2026-09-03 from off-LAN: GET https://nishifamily.com/world/beach answers 200 (630629 B, stamp b1788396100) with Cross-Origin-Opener-Policy same-origin, Cross-Origin-Embedder-Policy require-corp, Cross-Origin-Resource-Policy same-origin and a CSP whose worker-src allows self and blob -- emitted by nx_host_router (two literal header blocks, lines 433 and 542) on every response and checked by nx_health_eval (coep-missing). The LAN probe by bare IP answers 404 because it carries no Host header, a vantage fact not a defect. The served page constructs ZERO Workers and ZERO SharedArrayBuffers (crossOriginIsolated is never read), so the isolation is PAID and UNCONSUMED; the consumer is gameengine GE30 (tiles across Workers over one shared wasm memory) and performance PF13, and their first-byte blocker is the toolchain: atomic.rmw is ABSENT-PROVEN over 23506 runtime sources (corpus_complete=1) and no emitter names SharedArrayBuffer -- lang LN33 is the rung that lands wasm shared memory, atomics and wait or notify from the sovereign compiler. 2026-09-03 measure THE LADDER READ BACK 2026-09-03 (headless Edge, virtual-time 30 s, hud=1): renderer WebGL2 + npc-atlas 2048, door webgl2 refused webgpu-compute:levered-off,webgl2:taken,sovereign-cpu:below-taken, gl-probe webgl2-granted gpu-api 1 cast up. knowledge/tier_ladder.conf still carries door webgpu-compute levered gpu=1; flipping it to default is the GE1 data edit and it is deliberately NOT taken today because the WebGPU tier draws the world pass only (the cast reads down on that door) -- a default that loses the girls is a regression wearing a newer API. The flip follows GE1 parity, never a lever. |
GP4 The DXIL backend · cell WATCHING · gate UNRECORDED
| Contract | dxil_emit_module · executor Organ · 2 u · stands on GP1 |
|---|---|
| Definition of done | a third backend over nx_shader_ir emitting a DXIL container for the GE43 subset, so the dxg host driver can consume our compute kernel; done-rule: trace identity with the WGSL emit and a dispatch through nx_dxg that writes the same bytes as the WGSL door |
| Matrix cell | SHADER: a backend to the bytecode a host driver accepts -- DXIL for the dxg lane, SPIR-V where the host is Vulkan · runtime/nx_wgsl.nx · WATCHING decl |
| Gate | nx_wgsl_compute_gate · UNRECORDED — no recorded verdict for this gate (it is declared for the organ but the evidence referee's last run did not record it: it is not on this board's gates map, or the referee has not run since the per-gate record shipped) |
| Work log | no log row names this rung yet |
GP5 The command ring · cell WATCHING · gate NO-GATE-DECLARED
| Contract | gpu_cmd_ring · executor Organ · 1 u · stands on GP4 |
|---|---|
| Definition of done | record a command list once, submit it with a fence through dxg_submit_hwq, replay it; done-rule: two submissions of one recorded list read back identical buffer bytes, and a gate detects a corrupted list as a refused submit |
| Matrix cell | API: command queues and command lists -- record once, submit with a fence, replay · runtime/nx_gpu_api.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_gpu_api; declare nx_gpu_api TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | 2026-09-03 measure _gpu_dxg_submit_gate rebuilt and re-run on the laptop that holds the RTX 5080 (WSL /dev/dxg present): 6 of 6 GREEN -- enum=0 discrete=1 device=0 context=0 paging_queue=0 alloc=0 map_va=259 resident=259, SUBMIT #1 and #2 ret=0, four tampers rejected (-22 -22 -25 -25), positive control ret=0. Its own scope line stands: command_length=0, the GPU executes ZERO bytes; the submission channel is proven, no work is. 2026-09-03 lesson THE DXG DOOR CARRIES ONLY WHAT A VENDOR USER-MODE DRIVER PRODUCES. LX_DXSUBMITCOMMAND forwards the DMA buffer uninspected to the Windows KMD (nvlddmkm), and the WDDM DMA-buffer format is vendor-PRIVATE (pushbuffer methods plus KMD patch lists), unlike the documented GPFIFO/method interface NVK uses over nouveau/GSP. Executing a recorded command list through this door with no third party in the run path therefore needs the NVIDIA method stream GP14 names, not the DXIL container GP4 names -- GP4's dependency arrow into GP5 assumed a host driver that consumes DXIL, and on the raw dxg channel there is none (libd3d12.so + the vendor UMD would be the third party). GP5's honest dependency is a GP14-lite copy-engine method stream; the WebGPU door remains the only door that executes our kernel today. 2026-09-03 queue DISCRIMINATING EXPERIMENT (operator-paced, on the 5080 laptop, TDR risk named): record ONE list = a copy-engine method stream (SET_SRC/SET_DST/LAUNCH_DMA on the Blackwell CE class from the mirrored NVK refs) over two resident EXISTINGHEAP sysmem allocations, submit through dxg_submit_hwq with a monitored fence (the R4g sync fabric in _offc/cand__gpu_dxg_syncobj_gate), wait, read the destination back. Outcomes: bytes copied = the raw door executes vendor methods and GP5 proceeds on GP14-lite; ret -22 or a TDR = the door is UMD-only and GP4-GP8 move onto the GSP lane. Not run this session: a TDR resets the operator's display mid-session and the operator did not authorise it. |
GP6 Heaps and residency · cell WATCHING · gate NO-GATE-DECLARED
| Contract | gpu_mem_exhaust · executor Organ · 1 u · stands on GP5 |
|---|---|
| Definition of done | MECHANISM LANDED 2026-09-02 (nx_gpu_mem: gpu_mem_budget / gpu_mem_heap / gpu_mem_evict over the shim's size-swept QUERYVIDEOMEMORYINFO and EVICT; nx_gpu_mem_gate GREEN on the 5080 with the window accounted byte-exactly and every evicted heap answering PAGING-PENDING on re-residency); the OPEN contract is EXHAUSTION: allocate to the LOCAL (VRAM) budget and prove the driver evicts rather than hangs -- which needs VRAM allocations the vendor UMD owns (the GP5 blocker class; the non-local segment is host RAM and is not to be exhausted), so this rung stays open on gpu_mem_exhaust |
| Matrix cell | API: budget exhaustion on the local segment -- allocate to the VRAM budget and prove the driver evicts rather than hangs (the owed half of GP6) · runtime/nx_gpu_api.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_gpu_api; declare nx_gpu_api TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | 2026-09-03 measure _gpu_dxg_mem_recon (laptop-only probe, never promoted) size-swept the two missing ioctls on the RTX 5080: QUERYVIDEOMEMORYINFO answers ONLY at size 56 (0xC038470A) -- local budget 15,974,006,784 B, non-local 18,424,386,109 B, usage 0, available-for-reservation 8,121,221,120 / 9,346,410,782; EVICT answers ONLY at size 32 (0xC020471E) with ret 0 on a resident allocation, and the next MAKERESIDENT of that allocation returns 259 (paging pending) where an un-evicted one returns 0. Measured, not remembered. 2026-09-03 land MECHANISM: nx_dxg.nx grew dxg_query_vidmem, dxg_evict and dxg_alloc_eh_sz (the 64 KiB recipe with the size a parameter); nx_gpu_mem.nx composes gpu_mem_budget / gpu_mem_heap (allocate, place through the paging queue, make resident) / gpu_mem_evict / gpu_mem_reresident; nx_gpu_mem_gate 14 of 14 GREEN on the 5080: the device accounts a 16 x 1 MiB window EXACTLY (non-local usage 0 -> 16,777,216 -> 0 after the evicts) and every evicted heap answers PAGING-PENDING on re-residency; bite-proven RED 12 of 14 (exactly the two state teeth) on a mutant whose evict never reaches the device; gv_need SKIP off-GPU so it is not a gpu.gates row. organ_kind declares lib + oracle; sources in both trees; NAS build queued for the parity artifact. 2026-09-03 queue EXHAUSTION HALF (rung symbol gpu_mem_exhaust): allocate to the LOCAL (VRAM) budget and prove the driver evicts rather than hangs. The UMD-less EXISTINGHEAP path only creates non-local (sysmem) heaps; a VRAM heap carries vendor-private allocation data the UMD owns -- the GP5 blocker class -- and exhausting the non-local segment would exhaust the host's RAM, refused by design. Recipe: land with the GP14-lite lane or on the NishiOS driver (GP9), where the allocator is ours. |
GP7 Fences and barriers · cell WATCHING · gate NO-GATE-DECLARED
| Contract | gpu_sync_barrier · executor Organ · 1 u · stands on GP5 |
|---|---|
| Definition of done | FENCE HALF LANDED 2026-09-02 (nx_gpu_sync gpu_sync_fence: a monitored fence created on the 5080 through raw dxg, CPU-signalled and CPU-waited, nx_gpu_sync_gate 10 of 10 on the GPU laptop, SKIP where there is no /dev/dxg); the OPEN contract is the barrier half: a barrier a recorded list carries between a write and a read; done-rule: a gate removes the barrier and observes the wrong read the fence discipline exists to prevent -- which needs a list the door can execute (GP5 lesson row), so this rung stays open on gpu_sync_barrier |
| Matrix cell | API: resource barriers -- a barrier a recorded list carries between a write and a read (the barrier half of GP7) · runtime/nx_gpu_api.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_gpu_api; declare nx_gpu_api TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | 2026-09-03 land FENCE HALF: nx_dxg.nx grew the three sync-object ioctls (create 0xC0604710 size 96, signal-from-CPU 0xC0204731 size 32, wait-from-CPU 0xC028473A size 40 -- the ABI the R4g candidate size-swept live and then sat dark with for weeks); nx_gpu_sync.nx composes them as gpu_sync_fence (monitored fence created on the device, signalled to 1 and 2 from the CPU, waited for 2) and gpu_sync_device (the discrete adapter resolved to a device handle); nx_gpu_sync_gate 10 of 10 GREEN on the RTX 5080 through raw /dev/dxg (an invalid type refused, three tampers rejected -22 -22 -25, a second distinct fence still round-trips), bite-proven RED 5 of 10 on a planted type mutant, gv_need SKIP where there is no /dev/dxg. Sources in both trees; organ_kind declares the lib and the oracle; the matrix carries a present fence row and an _ABSENT_:gpu_sync_barrier watch; the rung symbol moved to gpu_sync_barrier so the ranker reads the rung as still open. 2026-09-03 queue BARRIER HALF: a barrier a recorded list carries between a write and a read, proven by removing it and observing the wrong read -- needs a command list the door can EXECUTE, which the raw dxg channel cannot carry without a vendor UMD (GP5 lesson). Recipe: land the GP14-lite copy-engine method stream (operator-paced, TDR risk named) or carry the barrier on the WebGPU door (a compute pass boundary between two dispatches over one storage buffer, framebuffer read back) -- the second is executable today on the browser door and is the cheaper next leg. |
GP8 Pipeline objects · cell WATCHING · gate NO-GATE-DECLARED
| Contract | gpu_pipeline · executor Organ · 1 u · stands on GP4 |
|---|---|
| Definition of done | a compute and a raster pipeline object carrying the bytecode from GP4 plus fixed state, cached by content hash; done-rule: the same source never compiles twice within a run, proven by the cache counter |
| Matrix cell | API: pipeline state objects -- raster and compute pipelines built once, bound per dispatch · runtime/nx_gpu_api.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_gpu_api; declare nx_gpu_api TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
GP9 The kernel-mode driver on documented hardware · cell WATCHING · gate NO-GATE-DECLARED
| Contract | gpu_kmd_nishios · executor Organ · 3 u · stands on GP5 |
|---|---|
| Definition of done | PCIe BAR discovery and map, ring buffer and doorbell, interrupt handling and GPU page tables for AMD RDNA in NishiLang, on the NishiOS kernel; every hardware write is volatile and NO firmware, VBIOS or EEPROM write path exists in the source (Rule 26); done-rule: a compute dispatch writes a known buffer on real hardware and nx_neverbrick_gate reads the driver GREEN |
| Matrix cell | DRIVER: kernel-mode driver on documented hardware (AMD RDNA ISA first), never-brick by construction · runtime/nx_gpu_kmd.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_gpu_kmd; declare nx_gpu_kmd TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
GP10 Present and compositor · cell WATCHING · gate NO-GATE-DECLARED
| Contract | gpu_present_compositor · executor Organ · 1 u · stands on GP9 |
|---|---|
| Definition of done | our own swapchain, vsync and compositor on the NishiOS door and in the Nishi browser; done-rule: nx_frame_pacing_gate reads the pacing from our present queue, not from a host compositor |
| Matrix cell | PRESENT: swapchain, vsync and compositor ownership on NishiOS and in the Nishi browser · runtime/nx_gpu_api.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_gpu_api; declare nx_gpu_api TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | 2026-10-01 queue NO RUNG ON THIS BOARD NAMES THE HEADSET STAGES: stereo or multiview submission, variable-rate or foveated shading and the eye-tracked foveation profile the OpenXR registry carries have no gpu rung, so T-FR-VRFOVEA is climbed by GP10 alone. Recipe: one rung under M5 beside GP15 with a gpu.matrix watch row (the matrix was outside this seat's scope), its done-rule a stereo pair presented from our own queue with a foveation map applied and refused by name on doors that lack it; the budget it must meet is performance SB-VR90-2608 (11.1 ms a frame at 90 Hz) and its consumers are gameengine GE82 and performance PF7. Also owed: a cls row for gpu in knowledge/subject_classes.conf (the attester printed CLASSES domain=gpu UNDECLARED) and a dated-source row for GitHub Atom feeds, so the organ and not a seat attests four of these five bars next month. |
GP11 The raster rung on the native lane · cell WATCHING · gate NO-GATE-DECLARED
| Contract | gpu_raster_rung · executor Organ · 1 u · stands on GP9 |
|---|---|
| Definition of done | the compute rasterizer kernel over the KMD, the contract graphics and gameengine already carry; done-rule: a frame drawn on NishiOS with no vendor driver in the process, framebuffer diff zero against the WebGPU door |
| Matrix cell | RASTER: the compute rasterizer kernel over the dxg lane (graphics and gameengine contract; one contract, three pages) · runtime/_hdl_build/_gpu_dxg_submit_gate.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for _gpu_dxg_submit_gate; declare _gpu_dxg_submit_gate TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
GP12 Conformance KATs · cell WATCHING · gate NO-GATE-DECLARED
| Contract | gpu_conformance_oracle · executor Gate · 1 u · stands on GP8 |
|---|---|
| Definition of done | chosen Vulkan CTS and WebGPU CTS cases mirrored as KATs our doors must pass, the suites themselves run OUTSIDE the build path as oracles and their numbers pinned in gpu.bench; done-rule: the KAT set is named, the pass count is on the board, and no third-party binary is linked, forked or shelled by any organ in the lane |
| Matrix cell | CONFORMANCE: a conformance suite as ORACLE outside the build path, a sovereign KAT set inside it · runtime/nx_gpu_api.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_gpu_api; declare nx_gpu_api TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
GP13 Capture and replay · cell WATCHING · gate NO-GATE-DECLARED
| Contract | gpu_debug_capture · executor Organ · 1 u · stands on GP5 |
|---|---|
| Definition of done | the recorded lists ARE the capture: replay a captured frame through the same ring and diff the framebuffer; done-rule: an injected one-byte change in a captured list is found by the diff |
| Matrix cell | DEBUG: capture and replay with byte-exact playback (the PIX, RenderDoc and Xcode GPU debugger class) · runtime/nx_gpu_api.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_gpu_api; declare nx_gpu_api TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
GP14 The NVIDIA lane over GSP · cell WATCHING · gate NO-GATE-DECLARED
| Contract | gpu_nv_gsp_lane · executor Organ · 3 u · stands on GP9 |
|---|---|
| Definition of done | the GSP RPC surface and the class methods NVK documents, in NishiLang, first as a compute dispatch that writes a known buffer on the RTX 5080; done-rule: the same as GP9 on NVIDIA hardware, never-brick proven the same way |
| Matrix cell | DRIVER: NVIDIA lane over the GSP firmware, the NVK precedent · runtime/nx_gpu_kmd.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_gpu_kmd; declare nx_gpu_kmd TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
GP15 Mesh and ray-query stages · cell WATCHING · gate NO-GATE-DECLARED
| Contract | gpu_mesh_rt · executor Organ · 1 u · stands on GP8 |
|---|---|
| Definition of done | a mesh-shading stage and a ray-query stage in nx_shader_ir, refused by name on every door that lacks them; done-rule: one mesh dispatch and one ray query proven on a door that has them |
| Matrix cell | MESH AND RT: mesh shaders and ray-tracing pipelines · runtime/nx_gpu_api.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_gpu_api; declare nx_gpu_api TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
GP16 The bench spine · cell WATCHING · gate NO-GATE-DECLARED
| Contract | gpu_bench_spine · executor Gate · 1 u · stands on GP11 |
|---|---|
| Definition of done | frame time and dispatch throughput of the same kernel through our doors against DirectX 12 and Vulkan reference programs on the same hardware, appended to gpu.bench as receipts with host, versions and checksums (the lang.bench shape); done-rule: two runs agree and the page renders the receipt |
| Matrix cell | BENCH: the bench spine -- frame time and dispatch throughput of ONE kernel through our doors against DirectX 12 and Vulkan programs on the same hardware, appended to gpu.bench as receipts with host, versions and checksums (GP16) · runtime/nx_gpu_api.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_gpu_api; declare nx_gpu_api TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | 2026-10-01 land THE LADDER TO SOTA IS DECLARED AND ATTESTED FOR OCTOBER 2026 (cross-board ladder seat, T0 job 1790857487): five sotabar rows (SB-WEBGPU-2609, SB-NATIVEAPI-2609, SB-OPENDRIVER-2609, SB-GPUSPLAT-2609, SB-VRFOVEA-2609), five sotatarget rows (best-in-class T-BIC-DOOR, T-BIC-GPUAPI, T-BIC-DRIVER; frontier T-FR-COMPUTERASTER, T-FR-VRFOVEA) and seventeen rungrole rows (substrate 7, arm 2, contender 8); twelve rows added to gpu.refs, ten mirrors fetched through nx_research_fetch on 2026-10-01 and read from the mirrored bytes, one the estate attester's same-day arXiv fetch copied to a pinned mirror, one a gameengine mirror re-hashed today. nx_ladder gpu reads LADDERED (17 of 17 placed, no unclimbed target); nx_barfresh gpu reads FRESH with 5 of 5 ATTESTED; nx_compare_rank gpu is not refused and ranks GP4, GP5, GP8 toward version 1.0. One barscan was appended by nx_frontier_scan attest itself (the arXiv listing: 8 items, newest 2026-09) and four by attestfile from this seat's reads, because the organ answers ATTEST-UNATTESTABLE reason=no-dated-source-row-knows-this-listing for GitHub Atom feeds and for the Mesa page; its fan-out over 85 fetches read newer_sources=0 stale_bars=0. 2026-10-01 measure ABSTENTIONS NAMED 2026-10-01: www.w3.org answered 403 (RF-DEFINITIVE, nothing saved) for both /standards/history/webgpu/ and /TR/webgpu/, so the WebGPU Recommendation-track status was NOT re-read this month and stands on the mirror of 2026-09-02 (Candidate Recommendation Draft, 1 September 2026); export.arxiv.org answered 429 twice, a minute apart, to this seat's narrower query (Gaussian splatting AND rasterization or rasterizer or WebGPU or compute shader), so that listing does not exist on this board and SB-GPUSPLAT stands on the attester's fetch of the gameengine listing, copied to cmp_gpu_arxiv_splat_202610.xml because rf_ee4fb3f8.raw is rewritten on every attest; the foveated arXiv listing is the mirror of 2026-09-27 and was not re-fetched. WITNESS COUNT STATED, NOT CLAIMED: the WebGPU, native-API and VR bars each stand on two or three sources from one or two bodies (Khronos, the W3C group, one browser vendor, one compiler vendor), SB-OPENDRIVER on Mesa alone and SB-GPUSPLAT on one arXiv listing; none is a three-independent-witness triangulation with a peer-reviewed paper yet, and Metal stays UNPINNED (the existing debt row). |
GP17 The deterministic-raster exceed · cell WATCHING · gate NO-GATE-DECLARED
| Contract | rk_kernel_ir · executor Organ · 1 u · stands on GP11, GP14 |
|---|---|
| Definition of done | the kernel IR whose integer raster produces bit-identical frames on two vendors; done-rule: framebuffer bytes identical across AMD and NVIDIA on the same inputs, proven by a gate that runs both -- only then does gpu.matrix claim the exceed |
| Matrix cell | RASTER: integer-deterministic rasterization -- bit-identical frames across vendors by construction · runtime/nx_shader_ir.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_shader_ir; declare nx_shader_ir TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
dossiers=17 cells_joined=17 no_matrix_row=0 (sum 17) gates_recorded=0 gates_unrecorded=4 no_gate_declared=13 (sum 17 of cells_joined) evgates=UNSTAMPED
Capability comparisons
Compare the field, search individual capabilities and open their source and adoption evidence. Documented presence does not establish comparative quality.
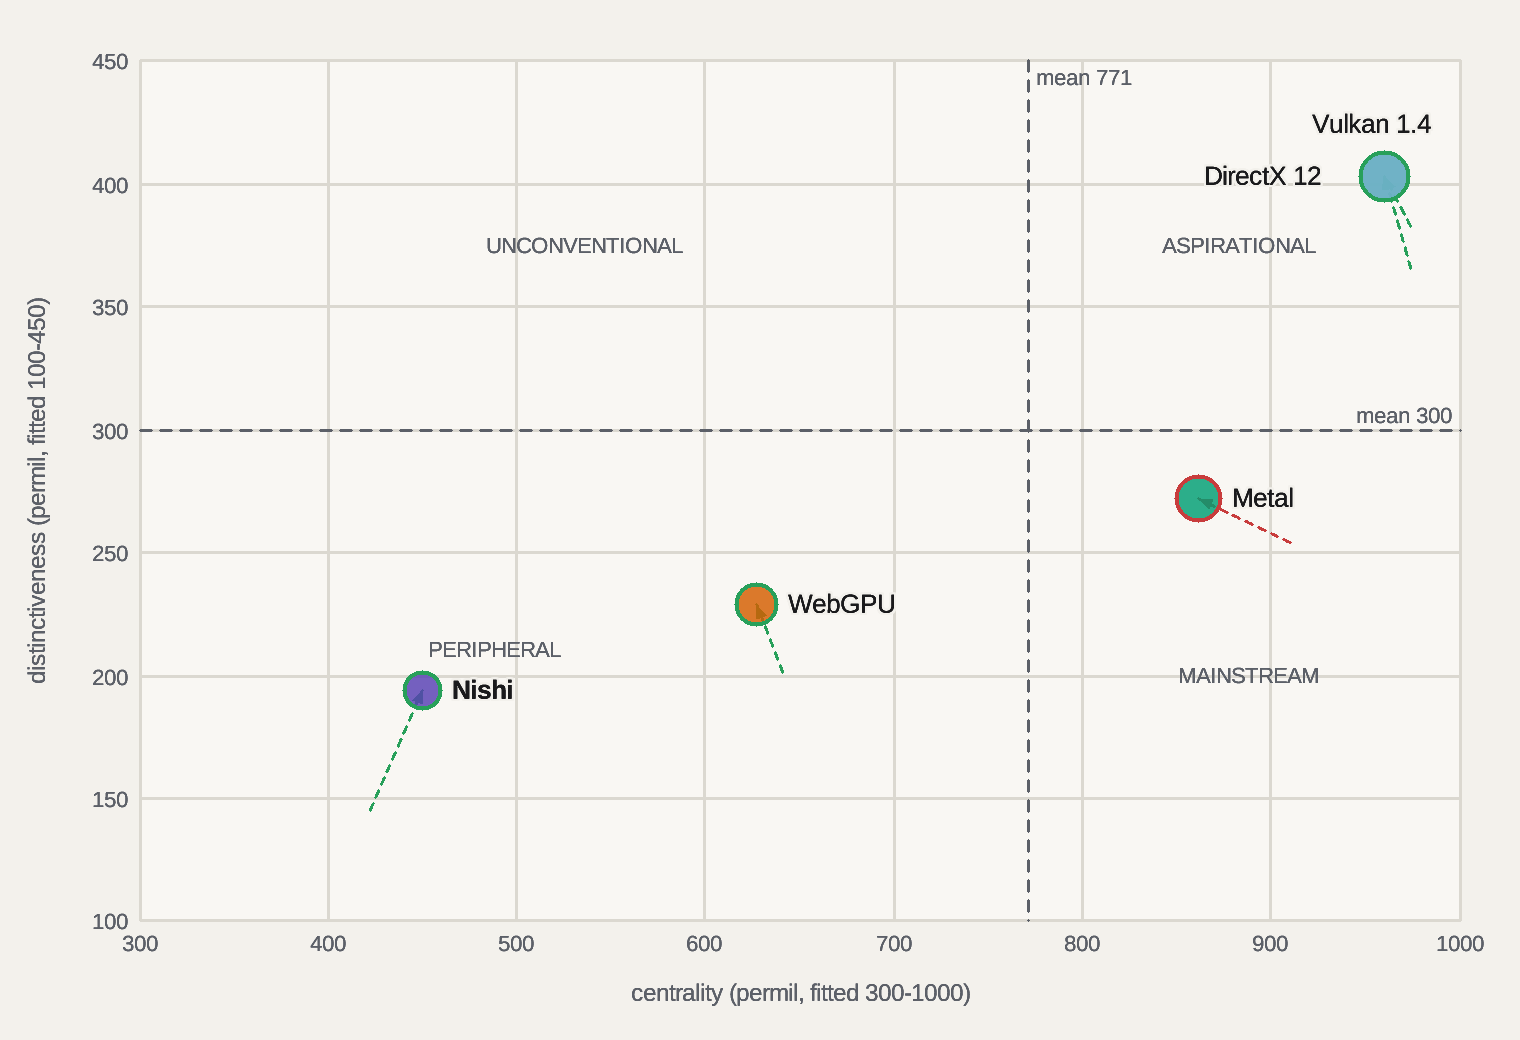
Position map — centrality and distinctiveness
The four-quadrant map the field uses for brand strategy (Dawar and Bagga, HBR June 2015), re-derived from this matrix on every publish. Centrality is the share of the category's feature mass a player covers, each feature weighted by how many hold it; distinctiveness is the average lead over each rival on the rows the player holds; breadth is the depth-weighted share of the whole matrix (the bubble); depth is how deeply the rows held are held; momentum is the day-over-day move off the spine (green rising, red falling, grey until day two); the dashed path runs first day → previous day → today. Dividers are the category means. Axes are fitted to the field of play, so read the tick numerals, not the frame. Rival marks are documented presence, so a rival's position reads the record, never its quality. The picture grades its own readability below; the table beside it is the same data for a screen reader or a second method.
knowledge/compare/gpu.cdmap (cut|x|y, cube|x|y|z); absent = the HBR defaultsbubble area = breadth · ring = momentum (green rising, red falling, grey until day two) · dashed = category means · axes fitted to the field of play: centrality 300–1000, distinctiveness 100–450 of 0–1000 permil (the full range put every player in one corner)
readability of the 2D cut, self-graded by the layout ruler: label overlaps 0 · labels over marks 0 · off-canvas 0 · unresolved labels 0 · mark overlaps 1 (a fact of the data: two players that close are that close) · data spread 662 permil of the plot · quadrant words unseated 0
text contrast, measured with wcag2-ratio (floors from contrast.conf), light theme: labels 16.24 (floor 4.50) · notes 16.24 (floor 4.50) · quadrant words 5.89 (floor 4.50) · tick numerals 5.89 (floor 4.50) · axis titles 5.59 (floor 4.50) · dark theme: labels 13.78 (floor 4.50) · quadrant words 5.55 (floor 4.50) · axis titles 5.97 (floor 4.50) · dark classes under their floor 0 (one figure serves both themes: a dark shortfall is a token to fix, never a class to hide) · classes refused under their floor 0 (a refused class is not drawn; the scale classes are measured, never hidden) · export: SVG PNG (receipt, rendered by the estate's own rasteriser from this page)

readability of the 3D cube, self-graded by the layout ruler: label overlaps 0 · labels over marks 0 · off-canvas 0 · unresolved labels 0 · mark overlaps 3 (a fact of the data: two players that close are that close) · data spread 105 permil of the plot
10 panels over 5 registered axes, every pair once (the lower axis on x, the higher on y) · each panel fitted to its own field of play, first and last tick numerals shown · no labels in a small cut, the legend names the colours; the grade below reports the mark terms only (MM summed over the panels, spread averaged)
readability of the small multiples, self-graded by the layout ruler: label overlaps 0 · labels over marks 0 · off-canvas 0 · unresolved labels 0 · mark overlaps 10 (a fact of the data: two players that close are that close) · data spread 677 permil of the plot
| Player | Quadrant | centrality | distinctiveness | breadth | depth | momentum | Rows held | Days on spine | First seen |
|---|---|---|---|---|---|---|---|---|---|
| Nishi | Peripheral | 450 | 194 | 266 | 666 | +76 since 2026-09-23 | 6 | 10 | 2026-09-15 |
| DirectX 12 | Aspirational | 960 | 403 | 866 | 1000 | +6 since 2026-09-23 | 13 | 10 | 2026-09-15 |
| Vulkan 1.4 | Aspirational | 960 | 403 | 866 | 1000 | +23 since 2026-09-23 | 13 | 10 | 2026-09-15 |
| Metal | Mainstream | 862 | 272 | 644 | 878 | -30 since 2026-09-23 | 11 | 10 | 2026-09-15 |
| WebGPU | Peripheral | 627 | 229 | 400 | 750 | +14 since 2026-09-23 | 8 | 10 | 2026-09-15 |
| Day | Matrix rows reviewed | Players recorded |
|---|---|---|
| 2026-09-15 | 22 | 5 |
| 2026-09-16 | 22 | 5 |
| 2026-09-17 | 22 | 5 |
| 2026-09-18 | 22 | 5 |
| 2026-09-19 | 22 | 5 |
| 2026-09-20 | 22 | 5 |
| 2026-09-21 | 22 | 5 |
| 2026-09-22 | 22 | 5 |
| 2026-09-23 | 22 | 5 |
| 2026-10-08 | 15 | 5 |
players 5|matrix rows 15|feature mass 51|centrality mean 771|distinctiveness mean 300|axes 5|spine days 10 (shown 10)|rows written today 0|readability defects 2D 0 cube 0|spine knowledge/status/cdmap/gpu.spine
Capability matrix — measured against source
◉ authored stronger claim; source present● present◐ partial○ absent? unassessed; excluded from relative comparison · click any capability for its evidence
Peer cell coverage: authored assessed 88, unassessed 0. Authored assessments are not verified outcomes.
No capabilities match this filter or search.
| Capability | Nishi | DirectX 12 | Vulkan 1.4 | Metal | WebGPU |
|---|---|---|---|---|---|
| SHADER | |||||
one NishiLang shader source emitting GLSL ES 3.00 and WGSL through the real compiler front-end (rung 1 and rung 2)Measured:wgsl_emit_module exists in runtime/nx_wgsl.nx, verified at emit. Two backends over one IR, trace-identity oracle, structured control-flow recovery with loops. DirectX takes HLSL to DXIL through its own compiler [dxspecs]; Vulkan consumes SPIR-V from any front-end [vulkanreg]; Metal compiles MSL; WebGPU takes WGSL text [wgsl]. Ours is the only one where the shader language IS the systems language: a shader is an ordinary NishiLang function. Adoption: REGISTRY-UNCERTAIN — PARTIAL: registry evidence is malformed, ambiguous or unverified: repair the registry before lifecycle promotion.Pros Implementing source symbol found; runtime acceptance separateCons behind DirectX 12 (leads), Vulkan 1.4 (leads), Metal (leads), WebGPU (leads); not adopted yet: registry evidence is malformed, ambiguous or unverified: repair the registry before lifecycle promotion | ● | ◉ | ◉ | ◉ | ◉ |
the compute stage -- storage buffers (read and read_write, atomic elements), atomic read-modify-write, global_invocation_id, the @compute entry (GE43)Measured:wgsl_compute_stage exists in runtime/nx_wgsl.nx, verified at emit. LANDED 2026-09-02: nx_wgsl compute emits the depth-min kernel (atomicMin over a u32 depth buffer) and the GLSL backend REFUSES it by name three ways; nx_wgsl_compute_gate 19 of 19 on the laptop build, NAS build queued. Every rival has compute [dxspecs] [vulkanreg] [webgpu]; WebGL2, the tier every /world page runs on today, has none -- which is why the door for this kernel is WebGPU. Adoption: REGISTRY-UNCERTAIN — PARTIAL: registry evidence is malformed, ambiguous or unverified: repair the registry before lifecycle promotion.Pros Implementing source symbol found; runtime acceptance separateCons behind DirectX 12 (leads), Vulkan 1.4 (leads), Metal (leads), WebGPU (leads); not adopted yet: registry evidence is malformed, ambiguous or unverified: repair the registry before lifecycle promotion | ● | ◉ | ◉ | ◉ | ◉ |
a backend to the bytecode a host driver accepts -- DXIL for the dxg lane, SPIR-V where the host is VulkanDARK —runtime/nx_wgsl.nx EXISTS but does not declare dxil_emit_module: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. /dev/dxg hands work to the WINDOWS host driver [wsldxg], which takes D3D12 pipelines with DXIL shaders [dxspecs]; a text dialect cannot cross that boundary. Contract: a third backend over nx_shader_ir emitting DXIL containers for the GE43 subset, proven against the WGSL emit by trace identity and against the host by a dispatch that writes the same bytes. Vulkan and Metal code 1 (their own bytecode is an equivalent target); WebGPU 0 (WGSL text only, no bytecode).Pros none measured yetCons behind DirectX 12 (leads), Vulkan 1.4, Metal; open contract; expected source declaration not established | ○ | ◉ | ● | ● | ○ |
| SUBMIT | |||||
a real command submission accepted by the GPU through the /dev/dxg device HAL (SOVEREIGN-GPU ladder R5)Measured:dxg_submit_hwq exists in runtime/_hdl_build/nx_dxg.nx, verified at emit. The consolidated dxg shim: open, enumerate, device, context, paging queue, allocation, VA map, residency, hardware queue, submit -- and _gpu_dxg_submit_gate records a command ACCEPTED by the RTX 5080 through it [wsldxg]. Every rival submits through a vendor user-mode driver; ours submits through the paravirtualised kernel device with no vendor library in the process. Adoption: LIB-WIRED importers=6 nonval=3 — fully adopted (top of its ladder).Pros Implementing source symbol found; runtime acceptance separate; fully adopted on the estate ladderCons behind DirectX 12 (leads), Vulkan 1.4 (leads), Metal (leads), WebGPU (leads) | ● | ◉ | ◉ | ◉ | ◉ |
Intel Xe command-streamer framing encoder (the Intel R1 rung)Measured:xe_mi_cmd exists in runtime/_hdl_build/nx_xe.nx, verified at emit. GFXPIPE headers and MI commands framed in NishiLang: the first byte of a bare-metal submission path on documented Intel hardware. DirectX and Vulkan reach Xe through Intel's drivers; Metal and WebGPU do not target Xe directly. rival marks uncited — the Yes, Best or Part codes on this row are an observation read with no reference mark behind them Adoption: LIB-GATE-ONLY importers=1 — PARTIAL: imported only by validation organs (gates, tests, benches): wire it into a shipping program.Pros Implementing source symbol found; runtime acceptance separate; ahead of Metal, WebGPUCons behind DirectX 12 (leads), Vulkan 1.4 (leads); not adopted yet: imported only by validation organs (gates, tests, benches): wire it into a shipping program | ● | ◉ | ◉ | ○ | ○ |
| API | |||||
command queues and command lists -- record once, submit with a fence, replayOpen — watchingruntime/nx_gpu_api.nx : gpu_cmd_ring, re-measured on every compare beat. Ship that symbol and this mark flips itself; the comparewatch- plane row flips with it. The shape D3D12 command queues and lists [dxspecs] and Vulkan queues and command buffers [vulkanreg] share, and that WebGPU exposes as command encoders [webgpu]. Contract: a sovereign command ring over the dxg submit (and later the KMD) with recorded lists replayed bit-identically, proven by a gate that submits the same list twice and reads the same buffer bytes back.Pros none measured yetCons behind DirectX 12 (leads), Vulkan 1.4 (leads), Metal (leads), WebGPU (leads); open contract; expected source declaration not established | ○ | ◉ | ◉ | ◉ | ◉ |
explicit memory heaps, placed resources and residency -- allocate, place, make resident, EVICT, the budget READ from the device (GP6)Measured:gpu_mem_heap exists in runtime/_hdl_build/nx_gpu_mem.nx, verified at emit. LANDED 2026-09-02: gpu_mem_budget reads the RTX 5080's segment budgets through QUERYVIDEOMEMORYINFO (local 15,974,006,784 B, non-local 18,424,386,109 B, size-swept live: one size answers), gpu_mem_heap allocates an EXISTINGHEAP of any page-aligned size, places it through the paging queue and makes it resident, gpu_mem_evict evicts through the device's own EVICT (size 32, swept live). nx_gpu_mem_gate 12+ teeth GREEN on the 5080: the device accounts a 16 x 1 MiB window EXACTLY (usage 0 -> 16,777,216 -> back), and every evicted heap answers PAGING-PENDING on re-residency where a resident one answers 0. SKIPs by name off-GPU, so not a gpu.gates row. SCOPE: these heaps are non-local (sysmem-backed, UMD-less); a VRAM heap and budget EXHAUSTION on the local segment need the vendor UMD's allocation data -- the GP5 blocker class -- and stay a watch (gpu_mem_exhaust). D3D12 heaps and placed resources [dxspecs], Vulkan memory types and heaps [vulkanreg]; Metal heaps at index level; WebGPU hides memory entirely [webgpu]. Adoption: LIB-GATE-ONLY importers=1 — PARTIAL: imported only by validation organs (gates, tests, benches): wire it into a shipping program.Pros Implementing source symbol found; runtime acceptance separate; ahead of WebGPUCons behind DirectX 12 (leads), Vulkan 1.4 (leads); not adopted yet: imported only by validation organs (gates, tests, benches): wire it into a shipping program | ● | ◉ | ◉ | ● | ○ |
budget exhaustion on the local segment -- allocate to the VRAM budget and prove the driver evicts rather than hangs (the owed half of GP6)Open — watchingruntime/nx_gpu_api.nx : gpu_mem_exhaust, re-measured on every compare beat. Ship that symbol and this mark flips itself; the comparewatch- plane row flips with it. Needs local-segment (VRAM) allocations, which the UMD-less EXISTINGHEAP path cannot create; exhausting the non-local segment would exhaust the host's RAM and is refused by design. Waits on the GP14-lite lane or a NishiOS driver. rival marks uncited — the Yes, Best or Part codes on this row are an observation read with no reference mark behind themPros none measured yetCons behind DirectX 12 (leads), Vulkan 1.4 (leads), Metal; open contract; expected source declaration not established | ○ | ◉ | ◉ | ● | ○ |
timeline fences -- a monotonic fence the CPU signals and waits on (the fence half of GP7)Measured:gpu_sync_fence exists in runtime/_hdl_build/nx_gpu_sync.nx, verified at emit. LANDED 2026-09-02: gpu_sync_fence creates a MONITORED_FENCE sync object on the device through the nx_dxg shim (three sync ioctls folded in from the R4g candidate that sat dark for weeks), signals it to 1 and 2 from the CPU and waits for 2 -- a round trip that completes only when the signals advanced the real fence. nx_gpu_sync_gate 10 of 10 GREEN on the RTX 5080 (an invalid type refused, three tampers rejected, a second fence still round-trips), bite-proven RED 5 of 10 on a planted type mutant; it SKIPs by name where there is no /dev/dxg, which is why it is deliberately not a gpu.gates row. D3D12 fences [dxspecs], Vulkan timeline semaphores [vulkanreg], Metal events at index level; WebGPU orders submissions implicitly [webgpu]. Adoption: LIB-WIRED importers=3 nonval=1 — fully adopted (top of its ladder).Pros Implementing source symbol found; runtime acceptance separate; ahead of WebGPU; fully adopted on the estate ladderCons behind DirectX 12 (leads), Vulkan 1.4 (leads) | ● | ◉ | ◉ | ● | ○ |
resource barriers -- a barrier a recorded list carries between a write and a read (the barrier half of GP7)Open — watchingruntime/nx_gpu_api.nx : gpu_sync_barrier, re-measured on every compare beat. Ship that symbol and this mark flips itself; the comparewatch- plane row flips with it. D3D12 enhanced barriers [dxspecs]; Vulkan synchronization2 [vulkanreg]; Metal at index level; WebGPU implicit [webgpu]. Contract: a barrier the recorded list carries, proven by a gate that removes it and observes the wrong read -- which needs a list the dxg door can EXECUTE, and the raw channel carries only what a vendor UMD produces (gpu.plan GP5 lesson row), so this half waits on the GP14-lite method stream or the WebGPU door.Pros none measured yetCons behind DirectX 12 (leads), Vulkan 1.4 (leads), Metal; open contract; expected source declaration not established | ○ | ◉ | ◉ | ● | ○ |
pipeline state objects -- raster and compute pipelines built once, bound per dispatchOpen — watchingruntime/nx_gpu_api.nx : gpu_pipeline, re-measured on every compare beat. Ship that symbol and this mark flips itself; the comparewatch- plane row flips with it. All four rivals bake state into pipeline objects [dxspecs] [vulkanreg] [webgpu]. Contract: a pipeline object carrying the shader bytecode from the emitter row above plus fixed state, cached by content hash so the same source never compiles twice.Pros none measured yetCons behind DirectX 12 (leads), Vulkan 1.4 (leads), Metal (leads), WebGPU (leads); open contract; expected source declaration not established | ○ | ◉ | ◉ | ◉ | ◉ |
| RASTER | |||||
the compute rasterizer kernel over the dxg lane (graphics and gameengine contract; one contract, three pages)DARK —runtime/_hdl_build/_gpu_dxg_submit_gate.nx EXISTS but does not declare gpu_raster_rung: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. Every rival rasterizes natively through vendor drivers; ours is the compute-shader rasterizer over the proven submission lane. This row is the SAME watch as graphics.matrix and gameengine.matrix carry, so it flips on all three boards at once or on none. rival marks uncited — the Yes, Best or Part codes on this row are an observation read with no reference mark behind themPros none measured yetCons behind DirectX 12 (leads), Vulkan 1.4 (leads), Metal (leads), WebGPU (leads); open contract; expected source declaration not established | ○ | ◉ | ◉ | ◉ | ◉ |
integer-deterministic rasterization -- bit-identical frames across vendors by constructionDARK —runtime/nx_shader_ir.nx EXISTS but does not declare rk_kernel_ir: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. No rival API guarantees cross-vendor bit identity of a float fixed-function raster; the GE43 depth test is already atomicMin over u32, integer end to end. The exceed this board is built to earn is deliberately NOT claimed here: it becomes claimable when rk_kernel_ir lands and its gate proves two vendors produce identical bytes.Pros none measured yetCons open contract; expected source declaration not established | ○ | ○ | ○ | ○ | ○ |
| PRESENT | |||||
swapchain, vsync and compositor ownership on NishiOS and in the Nishi browserOpen — watchingruntime/nx_gpu_api.nx : gpu_present_compositor, re-measured on every compare beat. Ship that symbol and this mark flips itself; the comparewatch- plane row flips with it. DXGI swapchains [dxspecs], VK_KHR_swapchain [vulkanreg], CAMetalLayer at index level; WebGPU presents through the browser compositor, which owns timing [webgpu] -- the limit banked as a GE42 lesson row. Contract: our own present queue and compositor on the NishiOS door, frame pacing measured by nx_frame_pacing_gate.Pros none measured yetCons behind DirectX 12 (leads), Vulkan 1.4 (leads), Metal (leads), WebGPU; open contract; expected source declaration not established | ○ | ◉ | ◉ | ◉ | ◐ |
| MESH AND RT | |||||
mesh shaders and ray-tracing pipelinesOpen — watchingruntime/nx_gpu_api.nx : gpu_mesh_rt, re-measured on every compare beat. Ship that symbol and this mark flips itself; the comparewatch- plane row flips with it. D3D12 mesh shaders and DXR [dxspecs]; Vulkan mesh shading and ray tracing [vulkanreg]; Metal at index level; WebGPU has neither in the current draft [webgpu]. Contract: a mesh-shading stage and a ray-query stage in nx_shader_ir, refused by name on every door that lacks them.Pros none measured yetCons behind DirectX 12 (leads), Vulkan 1.4 (leads), Metal (leads); open contract; expected source declaration not established | ○ | ◉ | ◉ | ◉ | ○ |
| DEBUG | |||||
capture and replay with byte-exact playback (the PIX, RenderDoc and Xcode GPU debugger class)Open — watchingruntime/nx_gpu_api.nx : gpu_debug_capture, re-measured on every compare beat. Ship that symbol and this mark flips itself; the comparewatch- plane row flips with it. Every rival ships a capture tool; WebGPU relies on browser devtools. Contract: the recorded command lists ARE the capture -- replay a captured frame through the same ring and diff the framebuffer bytes; the integer kernel makes the diff exact rather than approximate. rival marks uncited — the Yes, Best or Part codes on this row are an observation read with no reference mark behind themPros none measured yetCons behind DirectX 12 (leads), Vulkan 1.4 (leads), Metal (leads), WebGPU; open contract; expected source declaration not established | ○ | ◉ | ◉ | ◉ | ◐ |
| CONFORMANCE | |||||
a conformance suite as ORACLE outside the build path, a sovereign KAT set inside itOpen — watchingruntime/nx_gpu_api.nx : gpu_conformance_oracle, re-measured on every compare beat. Ship that symbol and this mark flips itself; the comparewatch- plane row flips with it. The Vulkan CTS [vulkanreg], the D3D12 HLK, the WebGPU CTS [webgpu]; Metal at index level. Contract: chosen CTS cases mirrored as KATs our door must pass, with the suite itself run OUTSIDE (operator law: no third party in the build or run path), its numbers pinned in gpu.bench.Pros none measured yetCons behind DirectX 12 (leads), Vulkan 1.4 (leads), Metal, WebGPU (leads); open contract; expected source declaration not established | ○ | ◉ | ◉ | ● | ◉ |
| DRIVER | |||||
kernel-mode driver on documented hardware (AMD RDNA ISA first), never-brick by constructionOpen — watchingruntime/nx_gpu_kmd.nx : gpu_kmd_nishios, re-measured on every compare beat. Ship that symbol and this mark flips itself; the comparewatch- plane row flips with it. AMD publishes its shader ISA references [amdisadocs], and RADV is the field's proof that a non-vendor driver on that documented ISA reaches Vulkan conformance [radv]. Contract: PCIe BAR map, ring buffer and doorbell, interrupts and GPU page tables in NishiLang; every hardware write volatile (VRAM and registers), NO firmware, VBIOS or EEPROM write path exists in the source, proven by nx_neverbrick_gate.Pros none measured yetCons behind DirectX 12 (leads), Vulkan 1.4 (leads), Metal (leads); open contract; expected source declaration not established | ○ | ◉ | ◉ | ◉ | ○ |
NVIDIA lane over the GSP firmware, the NVK precedentOpen — watchingruntime/nx_gpu_kmd.nx : gpu_nv_gsp_lane, re-measured on every compare beat. Ship that symbol and this mark flips itself; the comparewatch- plane row flips with it. NVK reaches Vulkan 1.4 conformance on Turing and later by talking to NVIDIA's GSP firmware rather than a vendor driver [nvk]; the laptop's RTX 5080 is that hardware. Contract: the GSP RPC surface and the class methods NVK documents, in NishiLang, first as a compute dispatch that writes a known buffer.Pros none measured yetCons behind DirectX 12 (leads), Vulkan 1.4 (leads); open contract; expected source declaration not established | ○ | ◉ | ◉ | ○ | ○ |
| BROWSER | |||||
WebGPU as a pure submission pipe for the sovereign kernel (GE44, the third-party-browser door)Measured:rk_webgpu_door exists in runtime/nx_game_page_emit.nx, verified at emit. The kernel from the rows above dispatched through WebGPU compute with WGSL from OUR emitter and a fullscreen blit of OUR framebuffer -- WebGPU does no rasterization of ours [webgpu]. Only WebGPU codes here; the native APIs are not browser doors. Contract: the same kernel bytes through this door and through dxg, framebuffer diff zero. Adoption: REGISTRY-UNCERTAIN — PARTIAL: registry evidence is malformed, ambiguous or unverified: repair the registry before lifecycle promotion.Pros Implementing source symbol found; runtime acceptance separate; ahead of DirectX 12, Vulkan 1.4, MetalCons behind WebGPU (leads); not adopted yet: registry evidence is malformed, ambiguous or unverified: repair the registry before lifecycle promotion | ● | ○ | ○ | ○ | ◉ |
the render-door ladder is DATA and every visitor sees which door drew the frame and why each higher door was refused (GP3, GE45)Measured:rk_tier_ladder exists in runtime/nx_game_page_emit.nx, verified at emit. knowledge/tier_ladder.conf carries one door row per renderer (order, default/levered/fallback state, URL lever, required capability, badge) and limit rows naming the GPUSupportedLimits minima the GE43 kernel needs; nx_tier_ladder_lib parses it, walks it natively (tl_pick, tl_reason) and emits the JS twin (window.__nx_ladder, nxDoorId, nxDoor, nxDoorReport) the page walks, so the HUD telemetry line ends `door <id> refused <door:reason,...>` with levered-off, capability-absent, failed:<message> or limit:<key> as the words. The rivals enumerate adapters and feature levels (DXGI adapters and D3D feature levels [dxspecs], vkEnumeratePhysicalDevices and feature queries [vulkanreg], WebGPU requestAdapter and requestDevice limits [webgpu]; Metal at index level) but leave the fallback ladder to the application; ours is data the gate pins (nx_tier_ladder_gate: a truth table over the walk, five refused-conf neg-controls, the JS twin pinned to the same ids, limits and reason words). Landed 2026-09-02; the flip is the receipt, the served HUD line is the proof. Adoption: REGISTRY-UNCERTAIN — PARTIAL: registry evidence is malformed, ambiguous or unverified: repair the registry before lifecycle promotion.Pros Implementing source symbol found; runtime acceptance separateCons not adopted yet: registry evidence is malformed, ambiguous or unverified: repair the registry before lifecycle promotion | ● | ● | ● | ● | ● |
| BENCH | |||||
the bench spine -- frame time and dispatch throughput of ONE kernel through our doors against DirectX 12 and Vulkan programs on the same hardware, appended to gpu.bench as receipts with host, versions and checksums (GP16)Open — watchingruntime/nx_gpu_api.nx : gpu_bench_spine, re-measured on every compare beat. Ship that symbol and this mark flips itself; the comparewatch- plane row flips with it. ADDED 2026-09-03 because nx_compare_rank gpu read GP16 UNMAPPED (no matrix row carried its symbol) -- a rung the ranker cannot price is a rung it cannot schedule. DirectX ships PIX timing captures and Vulkan the CTS performance cases [dxspecs] [vulkanreg]; Metal at index level; WebGPU exposes timestamp queries behind a feature [webgpu]. Contract: two runs agree, the lang.bench receipt shape, the page renders the receipt, and no oracle enters the run path.Pros none measured yetCons behind DirectX 12 (leads), Vulkan 1.4 (leads), Metal, WebGPU; open contract; expected source declaration not established | ○ | ◉ | ◉ | ● | ◐ |
| Class | Count | Note |
|---|---|---|
| rows with rival marks | 21 | rows carrying a Yes, Best or Part in a rival column |
| cited | 17 | a reference mark resolves to a pinned mirror |
| uncited | 4 | an observation read, badged until a reference lands |
| rows, summed | 21 | RECONCILED: the parts sum to the total 21 |
Delivery and evidence
Inspect risks, technical debt, rendered observations, experiments and references. Read scope and limitations alongside every result.
Risk register
| Risk | Likelihood x impact | Mitigation |
|---|---|---|
| The board reads as a plan for a vendor driver nobody can ship | likely x high | the ladder stands on precedents that shipped (NVK, RADV) and on hardware whose interfaces are public; every rung has a done-rule a gate can read, and the first three rungs reuse the emitter and the dxg lane that already exist. |
| A host API limit is discovered late and the door cannot carry the kernel | possible x high | the GE42 lesson rows already bank the WebGPU limits (32-bit atomics, storage binding size, 256 invocations, no f64, compositor-owned present); the tier ladder (GP3) exists so a refused door falls back to the sovereign wasm raster rather than to a black page. |
| Never-brick is violated by a driver rung | possible x critical | no firmware, VBIOS or EEPROM write path may exist in any driver source; nx_neverbrick_gate reads the driver before any deploy row can name it, and the done-rule of GP9 and GP14 names that gate. |
Release history and work log
| When | Rung | Kind | Entry |
|---|---|---|---|
| 2026-09-02 | GP1 | land | nx_shader_ir.nx grew K_STORAGE, S_EXPR, E_ATOMIC and vec3u with builders; nx_wgsl.nx grew STAGE_COMPUTE, WG_WORKGROUP, storage-buffer emission, atomicMin with the backend-supplied address, the global_invocation_id builtin bound to gid, wgsl_compute_stage, shsrc_depth_min and the compute verb; the GLSL backend refuses the stage, the storage declaration and the builtin each by name. Laptop build: nx_wgsl compute emits 252 bytes, 14 nodes; nx_wgsl_compute_gate 19 of 19 GREEN. Sources landed on the NAS (buildroot/runtime, 18449 + 73033 + 10042 bytes, CAS receipts read back); NAS builds queued. |
| 2026-09-02 | GP1 | lesson | the first cut of the gate hand-counted the contract length beside the six string literals and was wrong by nine bytes on its first run: a hand-counted length beside a literal is a second copy of that literal's shape and the two drift. The gate now DERIVES the length from the literals at run time. |
| 2026-09-02 | GP2 | land | rk_webgpu_door LANDED in runtime/nx_game_page_emit.nx (340486 -> 348297 B, five chained CAS hunks): at emit time the emitter forks the DEPLOYED shader backend (nx_wgsl compute) and embeds the captured kernel WGSL as KWGSL (never a hand-written copy; an absent capture emits KWGSL=null and a NAMED telemetry state), and nxKernelProbe(dev) under ?gpu=1&kernel=1 dispatches it through the page's WebGPU device over two hash-seeded u32 storage buffers, reads the depth buffer back and diffs it against the CPU minimum; the workgroup width is parsed from the WGSL text so the geometry has one owner. HUD telemetry gains kernel=. nx_craft_emit rebuilt on the laptop from a closure hashed identical to the NAS (23 files) and PROMOTED a08dedb7 through the content-put lane with allow_capability_loss=yes. |
| 2026-09-02 | GP2 | measure | matched-vintage size control: the UNEDITED NAS source built by the laptop toolchain is 519847 B against the NAS-built live 555112 B, so the 22 KB shrink of the edited laptop build (533095 B) is the toolchain, not the edit -- the edit is +13248 B on the control. nx_contentdiff live-vs-staged lost_from_live=305: source-path literals the NAS debug lane embeds (runtime/nx_tier.nx and siblings) plus the two reworded HUD literals; the laptop driver ignores --debug, so this promote DROPS crash-address resolution for this binary until the queued NAS build supersedes it. Named, not hidden. |
| 2026-09-02 | GP2 | queue | the DONE-RULE IS UNMEASURED: kernel diff=0 must be read in a WebGPU-capable browser on nishifamily.com/world/beach?gpu=1&kernel=1&hud=1 (the HUD line ends with kernel OK n=65536 diff=0 ms= wg=64). Headless Chromium wedges on this page and Waterfox has no WebGPU, so the first reading is the operator's or a Chromium marionette lane; until then GP2 reads present-by-symbol and incomplete-by-rule. |
| 2026-09-02 | GP2 | lesson | a promote whose response was dropped by the edge HAD LANDED (the retry read NOTHING-STAGED with live sha == staged) -- check the artifact before retrying; and the world emitter's MCP tool with NO arguments RUNS the whole pipeline (four such runs today), so never probe its usage with an empty argv. |
| 2026-09-03 | GP3 | land | rk_tier_ladder LANDED: knowledge/tier_ladder.conf carries the ladder as DATA (door rows webgpu-compute levered gpu=1, webgl2 default, sovereign-cpu fallback gl=0; limit rows maxComputeInvocationsPerWorkgroup 64, maxStorageBufferBindingSize 262144, maxComputeWorkgroupsPerDimension 1024); runtime/nx_tier_ladder_lib.nx parses it (REFUSING a ladder without a fallback, a fallback that is not last, an order regression, a quote or backslash in a field, an unknown state, a non-positive limit), walks it natively (tl_pick, tl_reason) and emits the JS twin (window.__nx_ladder, window.__nx_gpu_limits, nxDoorId, nxDoor, nxDoorReport) with ONE reason vocabulary; tl_emit announces TIER-LADDER-ABSENT-AT-EMIT and emits a NAMED absence. runtime/nx_tier_ladder_gate.nx reads 36 of 36 GREEN on the NAS through /api/gate_run (PROMOTED 870811618e, REGISTERED, on knowledge/gateroster.conf, gpu.gates row). runtime/nx_game_page_emit.nx (ten CAS hunks, both trees 211851ef): func rk_tier_ladder() composes tl_emit(), tele() gains door and refused, the HUD line ends door <id> refused <door:reason,...>, the ladder resolution sets window.__sov_door through nxDoorId(requires), and gpuInit refuses a device under any conf minimum as limit:<key>=<have><<need>. nx_craft_emit rebuilt on the laptop and PROMOTED 5d5dbb2b through the content-put lane with the loss NAMED (the five rewritten JS runs: tele, line, the ladder announcement, the GPU-died and GL-died lines). nx_publish_verify grew file_ladder= and served_ladder= (NAS-built, PROMOTED cba1deb2). gpu.matrix gained the BROWSER rk_tier_ladder row. |
| 2026-09-03 | GP3 | lesson | thirty-three green teeth missed that the HUD's door field calls nxDoor() and the twin never defined it: every visitor would have read door ladder-absent while the gate stayed green. nx_contentdiff's LOST list, read rather than filtered, exposed it before the promote. A twin's gate must enumerate the CONSUMER's call sites, not the producer's exports -- two teeth added, both twins pinned. |
| 2026-09-03 | GP3 | queue | the live half of the done-rule waits on the world pipeline run launched after the promote and a headless read of the served HUD: the ordinary visitor should read door webgl2 refused webgpu-compute:levered-off,webgl2:taken,sovereign-cpu:below-taken, and ?gpu=1 on a refusing host failed:<message> or limit:<key>. nx_glprobe recording the door is NOT done -- the HUD line and publish_verify's served_ladder carry it today. |
| 2026-09-03 | GP1 | land | nx_wgsl_compute_gate HAND-ADDED to knowledge/gateroster.conf after /api/gate_run read it 19 of 19 GREEN on the FAST path with exit 0 on the NAS; the ranker's REGISTERED-DARK reading of GP1 was a gate nobody ran, and a gate nobody runs is a comment. |
| 2026-09-03 | GP3 | measure | SERVED, READ BACK: nx_publish_verify beach -> SERVED-CURRENT stamp b1788394161 file_ladder=1 served_ladder=1 (edge delta 995 B). Headless Edge (--headless=new, virtual-time budget 25 s, dump-dom) of nishifamily.com/world/beach?hud=1 reads the HUD line ending door webgl2 refused webgpu-compute:levered-off,webgl2:taken,sovereign-cpu:below-taken -- the ordinary visitor's walk, word for word what tl_pick and tl_reason return for the same inputs. Under ?gpu=1&kernel=1&hud=1 the same read ends door webgl2 refused webgpu-compute:failed:finished-after-boot-ceiling; ladder already moved on (canvas untouched),webgl2:taken,sovereign-cpu:below-taken -- the first time the page has SAID why the kernel read unrun on this host: the WebGPU init outlived the page's GPU_BOOT_MS ceiling under a virtual-time budget, and the ladder moved on. The door and the refusal are now data on every visitor's HUD; the done-rule's fallback half (WebGPU refused -> the next door draws, announced) is witnessed live. |
| 2026-09-03 | GP2 | measure | the GP2 done-rule (kernel diff=0 in a WebGPU browser) is STILL UNMEASURED, but its blocker is now NAMED by the page itself: in headless Edge the WebGPU door is refused as failed:finished-after-boot-ceiling, so the kernel probe never dispatches. The next reading needs either a longer boot ceiling under a headless lever (a conf row, not a constant) or a headed WebGPU browser; requestAdapter absence was NOT the cause. |
| 2026-09-03 | GP3 | land | the boot ceiling is DATA: knowledge/tier_ladder.conf grew boot |
| 2026-09-03 | GP2 | measure | THE DONE-RULE IS MET. Through a REAL-TIME headless session (nishi-ops/ac_cdp.py: the Chromium sibling of the Waterfox marionette wire, DevTools protocol over a stdlib websocket, a 45 s real wait, one JS evaluation) on nishifamily.com/world/beach?gpu=1&kernel=1&hud=1&gpuboot=20000 the served page reads: door webgpu-compute refused webgpu-compute:taken,webgl2:below-taken,sovereign-cpu:below-taken and kernel OK n=65536 diff=0 ms=805 wg=64 -- the GE43 compute kernel captured from the deployed shader backend at emit time, dispatched through the browser's WebGPU door over two hash-seeded u32 storage buffers, read back and byte-equal to the CPU reference on all 65536 lanes (805 ms, workgroup 64 parsed from the WGSL). The frame line reads WebGPU (world pass) 735x368 q1 p50 6 ms. GP2 is measured; GP1's kernel is proven end to end through the door. |
| 2026-09-03 | GP2 | lesson | a --dump-dom under --virtual-time-budget CANNOT witness a GPU race: virtual time advances while the real requestAdapter/requestDevice work is still in flight, so every timeout-based ceiling loses (with the lever at 20 s the page still read finished-after-boot-ceiling), and without the budget the dump fires at the load event before the ladder resolves. A reading of the kernel door needs REAL seconds in a live session -- which is why the DevTools wire exists. The boot ceiling still had to become data: the lever is what a probe on a slow host will need, and the clamp is what keeps a URL from holding a visitor. |
| 2026-09-03 | GP5 | measure | _gpu_dxg_submit_gate rebuilt and re-run on the laptop that holds the RTX 5080 (WSL /dev/dxg present): 6 of 6 GREEN -- enum=0 discrete=1 device=0 context=0 paging_queue=0 alloc=0 map_va=259 resident=259, SUBMIT #1 and #2 ret=0, four tampers rejected (-22 -22 -25 -25), positive control ret=0. Its own scope line stands: command_length=0, the GPU executes ZERO bytes; the submission channel is proven, no work is. |
| 2026-09-03 | GP5 | lesson | THE DXG DOOR CARRIES ONLY WHAT A VENDOR USER-MODE DRIVER PRODUCES. LX_DXSUBMITCOMMAND forwards the DMA buffer uninspected to the Windows KMD (nvlddmkm), and the WDDM DMA-buffer format is vendor-PRIVATE (pushbuffer methods plus KMD patch lists), unlike the documented GPFIFO/method interface NVK uses over nouveau/GSP. Executing a recorded command list through this door with no third party in the run path therefore needs the NVIDIA method stream GP14 names, not the DXIL container GP4 names -- GP4's dependency arrow into GP5 assumed a host driver that consumes DXIL, and on the raw dxg channel there is none (libd3d12.so + the vendor UMD would be the third party). GP5's honest dependency is a GP14-lite copy-engine method stream; the WebGPU door remains the only door that executes our kernel today. |
| 2026-09-03 | GP5 | queue | DISCRIMINATING EXPERIMENT (operator-paced, on the 5080 laptop, TDR risk named): record ONE list = a copy-engine method stream (SET_SRC/SET_DST/LAUNCH_DMA on the Blackwell CE class from the mirrored NVK refs) over two resident EXISTINGHEAP sysmem allocations, submit through dxg_submit_hwq with a monitored fence (the R4g sync fabric in _offc/cand__gpu_dxg_syncobj_gate), wait, read the destination back. Outcomes: bytes copied = the raw door executes vendor methods and GP5 proceeds on GP14-lite; ret -22 or a TDR = the door is UMD-only and GP4-GP8 move onto the GSP lane. Not run this session: a TDR resets the operator's display mid-session and the operator did not authorise it. |
| 2026-09-03 | GP1 | land | nx_wgsl_compute_gate 19 of 19 GREEN on the NAS via /api/gate_run (exit_code 0, subject ./nx_wgsl.elf, compute emit 782 B, contract 252 B announced = derived) and ROSTERED in knowledge/gateroster.conf, so the rung now has an execution surface -- the ranker had read it REGISTERED-DARK (registered, no cap ever minted, no surface). gpu.gates already carries its row; the honesty board can read the domain as gated evidence instead of CLAIM-ONLY on its next regen. |
| 2026-09-03 | GP7 | land | FENCE HALF: nx_dxg.nx grew the three sync-object ioctls (create 0xC0604710 size 96, signal-from-CPU 0xC0204731 size 32, wait-from-CPU 0xC028473A size 40 -- the ABI the R4g candidate size-swept live and then sat dark with for weeks); nx_gpu_sync.nx composes them as gpu_sync_fence (monitored fence created on the device, signalled to 1 and 2 from the CPU, waited for 2) and gpu_sync_device (the discrete adapter resolved to a device handle); nx_gpu_sync_gate 10 of 10 GREEN on the RTX 5080 through raw /dev/dxg (an invalid type refused, three tampers rejected -22 -22 -25, a second distinct fence still round-trips), bite-proven RED 5 of 10 on a planted type mutant, gv_need SKIP where there is no /dev/dxg. Sources in both trees; organ_kind declares the lib and the oracle; the matrix carries a present fence row and an _ABSENT_:gpu_sync_barrier watch; the rung symbol moved to gpu_sync_barrier so the ranker reads the rung as still open. |
| 2026-09-03 | GP7 | queue | BARRIER HALF: a barrier a recorded list carries between a write and a read, proven by removing it and observing the wrong read -- needs a command list the door can EXECUTE, which the raw dxg channel cannot carry without a vendor UMD (GP5 lesson). Recipe: land the GP14-lite copy-engine method stream (operator-paced, TDR risk named) or carry the barrier on the WebGPU door (a compute pass boundary between two dispatches over one storage buffer, framebuffer read back) -- the second is executable today on the browser door and is the cheaper next leg. |
| 2026-09-03 | GP6 | measure | _gpu_dxg_mem_recon (laptop-only probe, never promoted) size-swept the two missing ioctls on the RTX 5080: QUERYVIDEOMEMORYINFO answers ONLY at size 56 (0xC038470A) -- local budget 15,974,006,784 B, non-local 18,424,386,109 B, usage 0, available-for-reservation 8,121,221,120 / 9,346,410,782; EVICT answers ONLY at size 32 (0xC020471E) with ret 0 on a resident allocation, and the next MAKERESIDENT of that allocation returns 259 (paging pending) where an un-evicted one returns 0. Measured, not remembered. |
| 2026-09-03 | GP6 | land | MECHANISM: nx_dxg.nx grew dxg_query_vidmem, dxg_evict and dxg_alloc_eh_sz (the 64 KiB recipe with the size a parameter); nx_gpu_mem.nx composes gpu_mem_budget / gpu_mem_heap (allocate, place through the paging queue, make resident) / gpu_mem_evict / gpu_mem_reresident; nx_gpu_mem_gate 14 of 14 GREEN on the 5080: the device accounts a 16 x 1 MiB window EXACTLY (non-local usage 0 -> 16,777,216 -> 0 after the evicts) and every evicted heap answers PAGING-PENDING on re-residency; bite-proven RED 12 of 14 (exactly the two state teeth) on a mutant whose evict never reaches the device; gv_need SKIP off-GPU so it is not a gpu.gates row. organ_kind declares lib + oracle; sources in both trees; NAS build queued for the parity artifact. |
| 2026-09-03 | GP6 | queue | EXHAUSTION HALF (rung symbol gpu_mem_exhaust): allocate to the LOCAL (VRAM) budget and prove the driver evicts rather than hangs. The UMD-less EXISTINGHEAP path only creates non-local (sysmem) heaps; a VRAM heap carries vendor-private allocation data the UMD owns -- the GP5 blocker class -- and exhausting the non-local segment would exhaust the host's RAM, refused by design. Recipe: land with the GP14-lite lane or on the NishiOS driver (GP9), where the allocator is ours. |
| 2026-09-03 | GP3 | measure | THE BEACH ENDPOINT IS ISOLATED ON THE WIRE, MEASURED 2026-09-03 from off-LAN: GET https://nishifamily.com/world/beach answers 200 (630629 B, stamp b1788396100) with Cross-Origin-Opener-Policy same-origin, Cross-Origin-Embedder-Policy require-corp, Cross-Origin-Resource-Policy same-origin and a CSP whose worker-src allows self and blob -- emitted by nx_host_router (two literal header blocks, lines 433 and 542) on every response and checked by nx_health_eval (coep-missing). The LAN probe by bare IP answers 404 because it carries no Host header, a vantage fact not a defect. The served page constructs ZERO Workers and ZERO SharedArrayBuffers (crossOriginIsolated is never read), so the isolation is PAID and UNCONSUMED; the consumer is gameengine GE30 (tiles across Workers over one shared wasm memory) and performance PF13, and their first-byte blocker is the toolchain: atomic.rmw is ABSENT-PROVEN over 23506 runtime sources (corpus_complete=1) and no emitter names SharedArrayBuffer -- lang LN33 is the rung that lands wasm shared memory, atomics and wait or notify from the sovereign compiler. |
| 2026-09-03 | GP3 | measure | THE LADDER READ BACK 2026-09-03 (headless Edge, virtual-time 30 s, hud=1): renderer WebGL2 + npc-atlas 2048, door webgl2 refused webgpu-compute:levered-off,webgl2:taken,sovereign-cpu:below-taken, gl-probe webgl2-granted gpu-api 1 cast up. knowledge/tier_ladder.conf still carries door webgpu-compute levered gpu=1; flipping it to default is the GE1 data edit and it is deliberately NOT taken today because the WebGPU tier draws the world pass only (the cast reads down on that door) -- a default that loses the girls is a regression wearing a newer API. The flip follows GE1 parity, never a lever. |
| 2026-09-03 | GP2 | queue | OPERATOR 2026-09-03 reframed the ladder for this board (goal row): third-party browsers are the FINAL MILE (M1), NishiOS and the Nishi browser are where the stack is sovereign (M2, M3), and no third-party gatekeeper on system resources is designed to. Read against the ranker the same day (nx_compare_rank gpu: GP5 command ring first, GP8, GP6, GP7, GP4 toward version 1.0; GP16 was UNMAPPED -- no matrix row carried gpu_bench_spine -- and gpu.matrix now carries it): the M1 door is proven (GP1 GP2 GP3 landed, kernel diff=0 through WebGPU) and the M2 door is blocked by the vendor UMD (GP5 lesson row), so the honest next legs are the browser-door consumers (GE30 tiles and PF13 on lang LN33, GE1 cast parity on the WebGPU tier) and the GP14-lite method stream the operator paces. |
| 2026-10-01 | GP16 | land | THE LADDER TO SOTA IS DECLARED AND ATTESTED FOR OCTOBER 2026 (cross-board ladder seat, T0 job 1790857487): five sotabar rows (SB-WEBGPU-2609, SB-NATIVEAPI-2609, SB-OPENDRIVER-2609, SB-GPUSPLAT-2609, SB-VRFOVEA-2609), five sotatarget rows (best-in-class T-BIC-DOOR, T-BIC-GPUAPI, T-BIC-DRIVER; frontier T-FR-COMPUTERASTER, T-FR-VRFOVEA) and seventeen rungrole rows (substrate 7, arm 2, contender 8); twelve rows added to gpu.refs, ten mirrors fetched through nx_research_fetch on 2026-10-01 and read from the mirrored bytes, one the estate attester's same-day arXiv fetch copied to a pinned mirror, one a gameengine mirror re-hashed today. nx_ladder gpu reads LADDERED (17 of 17 placed, no unclimbed target); nx_barfresh gpu reads FRESH with 5 of 5 ATTESTED; nx_compare_rank gpu is not refused and ranks GP4, GP5, GP8 toward version 1.0. One barscan was appended by nx_frontier_scan attest itself (the arXiv listing: 8 items, newest 2026-09) and four by attestfile from this seat's reads, because the organ answers ATTEST-UNATTESTABLE reason=no-dated-source-row-knows-this-listing for GitHub Atom feeds and for the Mesa page; its fan-out over 85 fetches read newer_sources=0 stale_bars=0. |
| 2026-10-01 | GP16 | measure | ABSTENTIONS NAMED 2026-10-01: www.w3.org answered 403 (RF-DEFINITIVE, nothing saved) for both /standards/history/webgpu/ and /TR/webgpu/, so the WebGPU Recommendation-track status was NOT re-read this month and stands on the mirror of 2026-09-02 (Candidate Recommendation Draft, 1 September 2026); export.arxiv.org answered 429 twice, a minute apart, to this seat's narrower query (Gaussian splatting AND rasterization or rasterizer or WebGPU or compute shader), so that listing does not exist on this board and SB-GPUSPLAT stands on the attester's fetch of the gameengine listing, copied to cmp_gpu_arxiv_splat_202610.xml because rf_ee4fb3f8.raw is rewritten on every attest; the foveated arXiv listing is the mirror of 2026-09-27 and was not re-fetched. WITNESS COUNT STATED, NOT CLAIMED: the WebGPU, native-API and VR bars each stand on two or three sources from one or two bodies (Khronos, the W3C group, one browser vendor, one compiler vendor), SB-OPENDRIVER on Mesa alone and SB-GPUSPLAT on one arXiv listing; none is a three-independent-witness triangulation with a peer-reviewed paper yet, and Metal stays UNPINNED (the existing debt row). |
| 2026-10-01 | GP10 | queue | NO RUNG ON THIS BOARD NAMES THE HEADSET STAGES: stereo or multiview submission, variable-rate or foveated shading and the eye-tracked foveation profile the OpenXR registry carries have no gpu rung, so T-FR-VRFOVEA is climbed by GP10 alone. Recipe: one rung under M5 beside GP15 with a gpu.matrix watch row (the matrix was outside this seat's scope), its done-rule a stereo pair presented from our own queue with a foveation map applied and refused by name on doors that lack it; the budget it must meet is performance SB-VR90-2608 (11.1 ms a frame at 90 Hz) and its consumers are gameengine GE82 and performance PF7. Also owed: a cls row for gpu in knowledge/subject_classes.conf (the attester printed CLASSES domain=gpu UNDECLARED) and a dated-source row for GitHub Atom feeds, so the organ and not a seat attests four of these five bars next month. |
Person · product · place — not yet measured for this domain
knowledge/compare/gpu.ppp (rows surface|nishi or c1..c4|label|url|connect naming OUR live surface and each rival's front door), run nx_ppp_probe domain gpu, and this section fills itself on the next beat: the same ruler on both sides — privacy and CX (third-party hosts, tracker classes, cookies, security headers), design and longevity (design hygiene, computed WCAG contrast, render-blocking resources, unsized media, script weight, theme and motion queries), findability (landmarks, skip link, on-site search, breadcrumb, headings, internal links).The field — discovered, not chosen
Rows written by nx_field_discover from gpu.seeds: the industry's own lists (Wikipedia wikitext, GitHub topics, awesome lists) read mechanically, every candidate counted across seeds. The matrix columns above are a SEAT'S pick; this band is the population they were picked from, and the stats line measures one against the other. A rival here is a lead, never a verdict — it earns a column when its capabilities are read and pinned.
| Class | Count | Note |
|---|---|---|
| seeds | 3 | |
| scanned | 3 | |
| fetched | 2 | |
| reused | 1 | |
| failed | 0 | |
| named | 3 | |
| candidates | 3 | |
| mentions | 3 | |
| capped | 0 |
| Rank | Rival | Seeds | Mentions | First seed | Kind | Link |
|---|---|---|---|---|---|---|
| 1 | DirectX 12 | 1 | 1 | col0-directx | named | https://microsoft.github.io/DirectX-Specs/ |
| 2 | Vulkan 1.4 | 1 | 1 | col1-vulkan | named | https://registry.khronos.org/vulkan/ |
| 3 | WebGPU | 1 | 1 | col3-webgpu | named | https://www.w3.org/TR/webgpu/ |
field candidates 3|shown 3 of 3|matrix columns in the field 3 of 4|discovered rivals with no column 0|malformed rows 0 (counted, never rendered)|read-capped 0
Exclusive and shared capabilities
This board grades 22 capabilities: 17 exclusive to it and 5 shared with other boards. Shared rows on this page: 5 = home here 2 + home elsewhere 0 + ambiguous 3 + undecided 0 + refused 0 (partition 5); undecided = unmapped 0 + unproven 0 + unevidenced 0; homonyms 1; since the previous census: new 0, resolved 0. Census FRESH age_s=374.
| Capability | Organ | Boards grading it | Home | Rule | Evidence | Standing on this board |
|---|---|---|---|---|---|---|
| wgsl_emit_module | nx_wgsl.nx | graphics, gpu+ | gpu | gates | gates | home here |
| gpu_raster_rung | _gpu_dxg_submit_gate.nx | graphics, gameengine*, gpu* | — | ambiguous | plan | ambiguous |
| rk_kernel_ir | - | gameengine:runtime/nx_raster_kernel.nx, gpu:runtime/nx_shader_ir.nx | — | homonym | - | homonym |
| wgsl_compute_stage | nx_wgsl.nx | gameengine*, gpu*+ | gpu | rung | plan+gates | home here |
| rk_webgpu_door | nx_game_page_emit.nx | gameengine*, gpu* | — | ambiguous | plan | ambiguous |
| rk_tier_ladder | nx_game_page_emit.nx | gameengine*, gpu* | — | ambiguous | plan | ambiguous |
Gaps from the record — what the estate does that no board carries
The record census (nx_goalmap record) reads the invoked-tool population and every plan queue row and files each organ or directive that NO matrix, plan or gates row names. A row here is a callout the boards missed: adjudicate it onto a board or declare it infrastructure. Census state STALE (age 1396821 s), sources read 4 of 7 declared — a BLIND census is a FLOOR: unread sources can only add rows.
| kind | name | board | source | evidence |
|---|---|---|---|---|
| directive | nx_glprobe | gpu | plan-queue | rung=GP3 |
rows shown 1|this board's directives 1|estate-wide un-boarded organs 452 (listed in full on /compare/ecosystem)|census rows 639|malformed 0 (counted, never rendered)
References
- [dxspecs] Microsoft. DirectX-Specs: engineering specifications for Direct3D 12 features (index page) publisher · read in our library
knowledge/fetched/cmp_gpu_dxspecs.html· pinh6c447e6f193c086f407946db680b958b13e6658653119471dcb90a2dec6ee065· accessed 2026-09-02 · vendor-docGrounds: SHADER: one NishiLang shader source emitting GLSL ES 3.00 and WGSL through the real compiler front-end (rung 1 and rung 2) - [vulkanreg] The Khronos Group. Vulkan Registry: specification, headers and Conformance Test Suite links publisher · read in our library
knowledge/fetched/cmp_gpu_vulkanreg.html· pinhb9403c61a7e0d5241fcbbe44264f9c48dedade5abd45f2c3066c12eb8574fac0· accessed 2026-09-02 · mirrored-indexGrounds: API: command queues and command lists -- record once, submit with a fence, replay - [webgpu] W3C GPU for the Web Working Group. WebGPU (Working Draft) publisher · read in our library
knowledge/fetched/cmp_gpu_webgpu.html· pinh0d023bfca4b19c7b89ee5aaf9f0d21fbfc4bb8d01bf15790ace6cebb2a517ee5· accessed 2026-09-02 · published-standardGrounds: BROWSER: WebGPU as a pure submission pipe for the sovereign kernel (GE44, the third-party-browser door) - [wgsl] W3C GPU for the Web Working Group. WebGPU Shading Language (Working Draft) publisher · read in our library
knowledge/fetched/cmp_gpu_wgsl.html· pinh13b0646fd903e205423d1810aa108374fc3bc50beec6f706819f18311d4b3eba· accessed 2026-09-02 · published-standardGrounds: SHADER: the compute stage -- storage buffers (read and read_write, atomic elements), atomic read-modify-write, global_invocation_id, the @compute entry (GE43) - [wsldxg] Microsoft Learn. GPU accelerated machine learning in WSL: the /dev/dxg paravirtualised GPU lane publisher · read in our library
knowledge/fetched/cmp_gpu_wsldxg.html· pinh50c2ab164cbb8f5ad9a30f25dec716a078a8eb9778816a4cc29b630976009f25· accessed 2026-09-02 · vendor-docGrounds: SUBMIT: a real command submission accepted by the GPU through the /dev/dxg device HAL (SOVEREIGN-GPU ladder R5) - [nvk] Mesa 3D. NVK: the open-source Vulkan driver for NVIDIA GPUs over the GSP firmware publisher · read in our library
knowledge/fetched/cmp_gpu_nvk.html· pinh9481186f9d899c42aaa6716b2504efddc3210f8ad0b59a5ca8e676bb6e4a7803· accessed 2026-09-02 · vendor-docGrounds: DRIVER: NVIDIA lane over the GSP firmware, the NVK precedent - [amdisadocs] AMD GPUOpen. AMD GPU architecture programming documentation: the RDNA and CDNA instruction set architecture references (index) publisher · read in our library
knowledge/fetched/cmp_gpu_amdisadocs.html· pinh0cfd22d580435b2c604bf966babadf827252f04cf4e73a29fd5b8c37ecbf99ce· accessed 2026-09-02 · vendor-docGrounds: DRIVER: kernel-mode driver on documented hardware (AMD RDNA ISA first), never-brick by construction - [radv] Mesa 3D. RADV: the open-source Vulkan driver for AMD GPUs publisher · read in our library
knowledge/fetched/cmp_gpu_radv.html· pinh87c24bd1de8f831994515f9a8b042e8908da320ef6237a051f9dbaf71d870cd3· accessed 2026-09-02 · vendor-docGrounds: DRIVER: kernel-mode driver on documented hardware (AMD RDNA ISA first), never-brick by construction - [gpuweb_commits_202610] gpuweb. Recent commits to the WebGPU and WGSL specification repository (Atom feed), fetched and read 2026-10-01: newest commit 2026-09-23, Set adapter.state to consumed (pull 10470), whose message says the conformance suite already expects it and Dawn implements it; no October commit publisher · read in our library
knowledge/fetched/cmp_gpu_gpuweb_commits_202610.xml· pinhb472d7e703d0c823b38d279b560f5c75a8ba8c69f406a4cf2d1ecf6003427301· accessed 2026-10-01 · mirrored-indexGrounds: SB-WEBGPU-2609 - [chrome_webgpu_news_202610] Chrome for Developers. What's New in WebGPU, the series index, fetched and read 2026-10-01: newest heading Chrome 153-154 (WGSL buffer_view extension, WGSL swizzle_assignment extension, WGSL extension updates, Dawn updates), then 151-152 subgroup size control, 149-150 immediates, 147-148 WGSL linear_indexing and WebGPU on Linux NVIDIA, 146 compatibility mode on OpenGL ES 3.1 and transient attachments publisher · read in our library
knowledge/fetched/cmp_gpu_chrome_webgpu_news_202610.html· pinh9b52752a4f5521e0ace46c6fd9d075547de4a111d70ed2e162e139dee566d019· accessed 2026-10-01 · vendor-docGrounds: SB-WEBGPU-2609 - [chrome_webgpu_153_154] Chrome for Developers. New in WebGPU 153-154, the page states Published: September 15, 2026: the WGSL language extension buffer_view and the swizzle_assignment extension publisher · read in our library
knowledge/fetched/cmp_gpu_chrome_webgpu_153_154.html· pinhaf6fd73c3332b6b13c2fd396474a7903d3623e3eda1cd2d5c24369ba266f11a1· accessed 2026-10-01 · vendor-docGrounds: SB-WEBGPU-2609 - [dxc_releases_202610] Microsoft. DirectXShaderCompiler releases (Atom feed), fetched and read 2026-10-01: newest DX Compiler Release for September 2026 (v1.9.2609, 2026-09-29: HLSL language updates with the hlsl-2026-compat warning group, SPIR-V backend improvements, compiler correctness and stability fixes), Shader Model 6.10 Preview Release (May 2026) Patch 2 on 2026-08-12, DX Compiler Release for July 2026 on 2026-07-29 publisher · read in our library
knowledge/fetched/cmp_gpu_dxc_releases_202610.xml· pinhd73ae1f69aa436defc7bfee4e98d91652bee0a69ae7786fec33a70f872f10f15· accessed 2026-10-01 · vendor-docGrounds: SB-NATIVEAPI-2609 - [mesa_relnotes_26_2_3] Mesa 3D. Mesa 26.2.3 Release Notes, dated 2026-09-16 in the page title (the previous page is 26.2.2 dated 2026-09-02): a bug-fix release; its bug list names an NVK memory leak in CmdCopyBufferToImage in 26.2.0, 26.2.1 and 26.2.2 and its change list carries nvk: Fix memory leak in compute save/restore publisher · read in our library
knowledge/fetched/cmp_gpu_mesa_relnotes_26_2_3.html· pinhc8e5c97cf1a979a4f0217b7fdc22457c0e779c5869c048356889335046f2c1f8· accessed 2026-10-01 · vendor-docGrounds: SB-OPENDRIVER-2609 - [mesa_relnotes_202610] Mesa 3D. Release Notes index, fetched and read 2026-10-01: 26.2.3 is the newest entry in the navigation list publisher · read in our library
knowledge/fetched/cmp_gpu_mesa_relnotes_202610.html· pinh07e54cbb77ed63a40e9302d4432d2d8d27f444f5c85cd681c927c75c5802c2f5· accessed 2026-10-01 · mirrored-indexGrounds: SB-OPENDRIVER-2609 - [arxiv_splat_202610] arXiv API listing, 3D Gaussian splatting AND (real-time OR level of detail OR streaming), newest first, 30 entries, newest 2026-09-30 (EffGS 2609.39553), no October entry; the bytes are the estate attester's fetch of 2026-10-01 (knowledge/fetched/rf_ee4fb3f8.raw) copied to a pinned mirror because that scratch file is overwritten on every attest; abstracts read on this board: TileGS 2609.03613, From Splats to Silicon 2609.06157, Atlas 2609.02352, EffGS 2609.39553 publisher · read in our library
knowledge/fetched/cmp_gpu_arxiv_splat_202610.xml· pinh5f66d1ad896313fa13cc053aab351a6c054dbcc066c8f0914a6f976089e5dcfd· accessed 2026-10-01 · mirrored-indexGrounds: SB-GPUSPLAT-2609 - [openxr_sdk_releases_202610] The Khronos Group. OpenXR-SDK-Source releases (Atom feed), fetched and read 2026-10-01: newest OpenXR SDK 1.1.63 (dated 2026-09-01 in its notes, published 2026-09-02) with ratified extensions XR_KHR_extended_result_name_lengths, XR_EXT_spatial_container, XR_EXT_spatial_container_self_rendering and XR_EXT_spatial_image_tracking and vendor extensions XR_BD_spatial_light_estimation, XR_BD_camera_image and XR_SONY_hdr_metadata; no foveation extension is new in it; 1.1.62 on 2026-08-03 publisher · read in our library
knowledge/fetched/cmp_gpu_openxr_sdk_releases_202610.xml· pinh15e0b3f9a59139cdd4bba4c5d63766eb5332bdb630d9d3a3dd7930fd20f8560f· accessed 2026-10-01 · mirrored-indexGrounds: SB-VRFOVEA-2609 - [openxr_meta_fov_eye] The Khronos Group. OpenXR 1.1 reference page XR_META_foveation_eye_tracked (registry version 1.1.63): depends on OpenXR 1.0, XR_FB_foveation and XR_FB_foveation_configuration; names XR_FOVEATION_CENTER_SIZE_META, XrFoveationEyeTrackedProfileCreateInfoMETA, XrFoveationEyeTrackedStateMETA and xrGetFoveationEyeTrackedStateMETA publisher · read in our library
knowledge/fetched/cmp_gpu_openxr_meta_foveation_eye_tracked.html· pinh4a738838f96be83dd98f525cfb60455f38c4882d6b157901ccd3b779c56395db· accessed 2026-10-01 · published-standardGrounds: SB-VRFOVEA-2609 - [openxr_fb_foveation] The Khronos Group. OpenXR 1.1 reference page XR_FB_foveation (registry version 1.1.63): depends on OpenXR 1.0 and XR_FB_swapchain_update_state; names XrFoveationProfileCreateInfoFB, XrSwapchainCreateInfoFoveationFB, XrSwapchainStateFoveationFB and xrCreateFoveationProfileFB publisher · read in our library
knowledge/fetched/cmp_gpu_openxr_fb_foveation.html· pinhbc27c44953852a45131659809b1b55bd55a5703e541ac07401976c954e8c1f41· accessed 2026-10-01 · published-standardGrounds: SB-VRFOVEA-2609 - [arxiv_vrsplat_202609] arXiv API listing held by gameengine (foveated or virtual reality or headset AND Gaussian splatting, 40 of 104 entries, feed stamped 2026-09-27), pin re-verified 2026-10-01 and read on this board for Hybrid Foveated Path Tracing with Peripheral Gaussians 2601.22026, GeoFovea-GS and PowerGS; NOT re-fetched this month because export.arxiv.org answered 429 publisher · read in our library
knowledge/fetched/cmp_gameengine_arxiv_vrsplat_202609.xml· pinh183ba1236e69521184d4769369b1e04532bc9ec00ef134247618b1bcf154f6c1· accessed 2026-09-27 · mirrored-indexGrounds: SB-VRFOVEA-2609
generated by nx_swcompare_matrix (sovereign NishiLang organ) from knowledge/compare/gpu.matrix · source checks show implementation presence; runtime and user-outcome evidence are reported separately · JavaScript supports page controls