Nishi Family › Compare › Competitive-Intelligence Mining
Nishi Compare · capabilities, evidence and delivery
Competitive-Intelligence Mining
Compare capabilities and delivery evidence. Source discovery, qualification, deployment and accepted outcomes are separate; an open contract names work still to verify.
Nishi review, release, bug, feature, thought-leader and research mining vs Steam's native review surface and download-steam-reviews and Appbot and the ABSA research line and the platforms' own APIs -- September 2026
Overview
The purpose, declared position and evidence coverage of this domain. Source presence and completed acceptance are different measures.
Where we are. MEASURED 2026-09-05, not recalled. The Steam adapter and the decision core landed in one leg: nx_reviewmine_lib (page reader, journal row codec, seen set, tokenizer, complaint-versus-praise ranker, the four-tier rubric with defect, feature, exceed, not-met, value and demand lexicons as data) plus nx_steam_reviews (fetch through the estate's one pacer and its own TLS, ingest, stats, mine, rubric), gate 92 of 92 GREEN on planted data with named controls, live from the laptop against Portal 2, Palworld (3,000 recent English reviews) and VR HOT (all 711 English reviews) and reachable from the NAS (appreviews and appdetails both 200 through nx_research_fetch). The board reads the two measurements in its verdict. What is open: no beat, no proposal file into other boards, aspects are a hand lexicon rather than mined, one source class of six has an adapter, and the NAS build of the two organs was REFUSED by build admission (an I/O storm) and QUEUED as BQ-nx_steam_reviews while the laptop artifacts were staged through the content door for promote. ASPECT EXTRACTION AS OF 2026-09-06 (IM17 and IM28, every figure a served run on the NAS on the paper's per-occurrence ruler): the estate's best is the sequence-model UNION at 689 restaurants and 538 laptops against the winners' 840 and 745 (82 and 72 percent), above the organisers' baseline on both; the ladder beneath it is unigram, Hu-Liu n-gram, dictionary, structured perceptron, union, majority rule, POS features from the estate's own tagger (931 on held-out EWT). The estate now owns a POS tagger and a dependency parser (UAS 805) with their gates GREEN on the served binaries; the parse features measured negative and ship as a mode. What stands between here and the winners is named on the log rows: a CRF objective, external in-domain text for clusters and name lists, and the neural class.
Where we need to go. OPERATOR 2026-09-05: a review miner that helps us address opportunities from amazon to ebay to steam as part of fetch and ingest; sota enough to mine features, releases, bugs, reviews, thought leaders and research, whatever grows our /compare boards' knowledge and capabilities permanently, to the point we can establish what a rival like Wolfram has and target a plan to address all of it, structured with the mapping tooling and the nishi research tooling, so we become leaders in the domains we choose including the game one; graded on exceeds, meets, does-not-meet with features and defects split from sentiment so on digital and physical products we know whether we are in the right pricing value proposition or fixing a leaky teapot that degrades the brand; September 2026 research done with the estate, gaps addressed from the first byte up.
Latest recorded release
2026-09-06 · IM28
READ ON THE LIVE PAGE: /compare/intelmine after regen 1788715218 (four forks FRESH, 233 pages published) renders the Ladder verdict line: targets 3 (best in class 1, frontier 2), rungs 34 placed 34 (substrate 29, arm 2, contender 3), LADDERED, bars 2 attested FRESH against 2026-09; nx_page_verify GREEN 347481 B; nx_ladder CLI PROMOTED f30570b8 and registered, nx_ladder intelmine LADDERED and nx_ladder all 112 domains laddered=1 partial=0; the ranker's false LADDER-PARTIAL (rk_split NUL-terminated fields) is fixed at 1038b9be, so the board hands out work again
Release entries describe recorded changes; they do not establish that every capability passed evaluation.
39 of 62 capability source symbols found|19 of them authored stronger-claims|23 open|coverage 629/1000|adoption 34 full / 5 partial
Evidence profile — what the gaps on this board actually are
Measured by nx_swcompare_evidence, read back by nx_evprofile_lib. Every figure is a count with its denominator — there is deliberately no score, no grade and no percentage anywhere in this band, because a stored scalar is a field a seat can edit and a counted partition is not.
evidence|grounded 36/36|unsupported 0|gates green 8/8|proven able to fail 0/8|never bitten 8|green at 0/0 0|open gaps 16|of them unnamed 0|of them proof withheld 0|flips ready 0
proven able to fail counts the gates that have a RECORDED RED — nx_gate_bite mutated the gate subject, rebuilt it, watched the gate go red, and that record is inside the shared TTL. never bitten is its complement over the same denominator: those gates ran and were green, and nothing has ever shown them able to detect anything, so their green is a statement about this run and not about the gate. green at 0/0 is a separate and much weaker observation — the gate printed GREEN on a zero denominator, so its own tooth counter says it examined nothing. A gate can be green, non-zero, and still never bitten; that is the common case and it is now visible instead of implied.
partition: grounded + unsupported = 36 vs present 36 · named + unnamed + withheld = 16 vs open 16 · both reconcile
liar-kill conj=GPQN · all four conjuncts held
graded document: BUILDROOT tree, 36428 bytes · gates map: PRIMARY · stamped 32d 13h ago · STALE against the shared TTL of 604800s — this is evidence about a build nobody can vouch for now · source ../knowledge/status/evstamp_intelmine.verdict
| Gap class | What it is, and the work it names |
|---|---|
| STALE | This profile is older than the shared TTL, or its clock ran backwards. It is reported as unusable rather than as fresh, because being wrong in the direction of refusing is the safe direction. |
nx_swcompare_evidence intelmine itself and are not carried on the stamp, so this page names the classes and the producer names the rows. That split is stated rather than hidden: a count without a worklist is not actionable, and this band is honest about which half of that it is.Production map
Follow the dependencies, declared acceptance criteria and recorded priorities. Inspect source binding before treating a rank as executable work.
Ranking source binding: STALE_OR_INVALID_BINDING. Recorded priorities require current acceptance evidence and resource checks before execution.
Recorded ranking withheld
Retained ranking is not bound to the current plan and matrix: STALE_OR_INVALID_BINDING. Historical data remains retained. Refresh the ranking after resolving the input differences. Latest execution outcome is unverified.
Declared roadmap — contract, acceptance, executor, effort
| Rung | Closes with | Definition of done (pre-declared) | Executor | Est. |
|---|---|---|---|---|
| Steam review adapter and the decision core with the expectation rubric (IM0) | rm_rubric_doc | LANDED 2026-09-05: nx_reviewmine_lib + nx_steam_reviews + nx_steam_reviews_gate 92 of 92; fetch, ingest, stats, mine and rubric live on Palworld and VR HOT from the laptop build; the NAS build is queued behind admission and the laptop artifacts are staged; the NAS gate run and the .gates row are the remaining receipt | Organ | 1 u |
| Beat: nightly incremental fetch plus rubric for a data-row watch list (IM1) after IM0 | im_beat | knowledge/reviewmine/steam_watch.conf lists appids; a clock row runs fetch (incremental) then stats, mine and rubric per app and truncate-writes knowledge/status/reviewmine/appid.status with a canonical last line; a gate proves the status is rewritten (never appended) and that a refused fetch leaves the previous status intact and announced | Organ | 0.5 u |
| Proposal file: mined defects and demanded features become candidate rows for a named board (IM3) after IM0 | im_propose_rows | nx_steam_reviews propose appid domain writes knowledge/compare/domain.proposed rows (label, evidence counts, the source rows) and NEVER touches the matrix or plan; a seat adjudicates with the goal map; the gate proves a proposal row carries its counts and that a second run is idempotent | Organ | 1 u |
| Rival feature census: Wolfram's alphabetical listing parsed into candidate computational.matrix rows and a pinned bar (IM4) after IM3 | fc_census | The mirrored listing is parsed into one row per documented symbol grouped by guide, the count is printed with its method, computational.matrix gains a bar row pinned through nx_barcheck, and the census is idempotent; the gate proves the count against an independent tag count over the same bytes | Organ | 1.5 u |
| The adapter fetches and banks the app record and price itself (IM14) after IM0 | sr_appdetails | nx_steam_reviews details appid banks appdetails JSON beside the reviews and writes the .price row the rubric reads; a planted record round-trips in the gate; a missing price prints UNKNOWN never zero | Organ | 0.5 u |
| Lab spine: one row per run so the board renders a trajectory (IM18) after IM0 | sr_spine | Every rubric run appends epoch, appid, docs, four tier counts, refund-window figures, top three defects and top three demands to knowledge/status/reviewmine/spine.jrnl; the emitter renders the last N rows per app; the gate proves append-only and that two runs produce two rows | Organ | 0.5 u |
| Aspects mined from the corpus, not a hand list (IM2) after IM17 | rm_aspects | Frequent noun-phrase candidates (unigram and bigram, association-mined per Hu and Liu) with opinion orientation per aspect, scored on the SemEval-2014 laptop and restaurant sets through IM17; PRE-DECLARED accept rule: the mined table is not wired into the rubric until its aspect-term F1 is published beside the rung | Organ | 2 u |
| ABSA bench: SemEval-2014 Task 4 scored by a sovereign organ (IM17) after IM0 | ab_eval | The SemEval-2014 datasets are mirrored with their licence, the bench scores aspect-term extraction (subtask 1) and polarity (subtask 2) and prints P, R, F1 with the counts; its gate proves the scorer on a planted gold set including a zero-prediction control | Organ | 1.5 u |
| Sentence-level opinion orientation (IM16) after IM2 | rm_opinion_sent | Reviews split into sentences, each sentence graded with the lexicons and the vote as prior, per-aspect polarity counts printed; measured against IM17 subtask 2 | Organ | 1.5 u |
| Time-window trend: tiers by review-date window around a release (IM10) after IM0 | rm_trend | Rubric per window (30-day recent, lifetime, and a caller-named window) with the windows partition summing to docs; Steam's own recent-versus-lifetime score is the oracle it is checked against | Organ | 1 u |
| Near-duplicate and spam collapse (IM11) after IM0 | rm_neardup | Shingle hashing over review text with a Hamming nearest, collapsed rows counted and named, never deleted; measured against Steam's off-topic exclusion by running with filter_offtopic_activity both ways | Organ | 1 u |
| Multilingual normalisation: per-language stopwords and stemming (IM15) after IM0 | rm_lang_norm | Stopword and lexicon confs per Steam language code, a stemmer for the top languages measured in the journal (english, russian, schinese, spanish, german), and the mine and rubric verbs accept all with per-language partitions that sum | Organ | 1.5 u |
| Bug trackers mined into defect rows (IM5) after IM3 | bt_issue_ingest | GitHub issues for a rival named in a board's refs are fetched through the pacer, labels and titles journaled, and defect terms counted with the same lexicon so a rival's known defects sit beside its reviewers' complaints; gate on a planted issues page | Organ | 1 u |
| Release notes mined into bar rows (IM12) after IM3 | rl_release_ingest | GitHub releases for every rival in a board's refs journaled and the latest pinned through nx_barcheck into knowledge/barcheck.conf; computational.matrix's four UNPINNED bars are the first population; gate on a planted releases page | Organ | 1 u |
| Thought-leader feed watch (IM6) after IM1 | tl_feed_watch | A data-row list of feeds (people, blogs, vendor changelogs) polled on a beat through nx_feed_extract into the resbrief plane with the domain it feeds; a gate on a planted Atom feed proves items land once | Organ | 1 u |
| Research scan: arXiv queries per domain axis (IM7) after IM1 | rs_arxiv_scan | nx_frontier_scan's seeds are run against the arXiv API on a beat, results banked with provenance and cited into the domain's refs as candidates; a gate on a planted Atom response | Organ | 1 u |
| Amazon adapter over the research release (IM8) after IM0 | rm_amazon_ingest | The Amazon Reviews 2023 JSONL record shape journals through the same row codec with rating mapped to the vote and verified_purchase to a flag; the rubric runs unchanged; the gate proves the mapping on planted rows | Organ | 1 u |
| eBay feedback adapter (IM9) after IM8 | rm_ebay_ingest | BLOCKED on a mirrored eBay document (two 403s and a wrong article on 2026-09-05); the rung opens when a feedback API page is mirrored and cited; nothing is coded against an unread bar | Organ | 1 u |
| Steam cohort: app list and genre neighbours (IM13) after IM14 | sr_applist | IStoreService GetAppList (the non-deprecated endpoint) plus appdetails genres select the games-like-ours population as data rows; the gate proves the selection on a planted list | Organ | 1 u |
| Source policy in the fetch path (IM19) after IM0 | im_source_policy | knowledge/reviewmine/source_policy.conf declares per host allowed feeds, forbidden stores and required disclosures; every adapter reads it before its first byte and refuses with the rule named; the gate proves a forbidden host is refused and an allowed one proceeds (positive control) | Organ | 0.5 u |
Milestones
| Milestone | Rungs | Cumulative |
|---|---|---|
| M0 · Steam mined on the rubric | IM0 | 1 u |
| M1 · Close the hive loop for Steam | IM1,IM3,IM4,IM14,IM18,IM26,IM27 | 7 u |
| M2 · Reach the research bar | IM2,IM17,IM16,IM10,IM11,IM15 | 11.5 u |
| M3 · Every source class the operator named | IM5,IM12,IM6,IM7,IM8,IM9,IM13,IM19 | 20.5 u |
| Rung | Closes with | Definition of done (pre-declared) | Executor | Est. |
|---|---|---|---|---|
| Installed mode: Steam library census with fingerprints and review tie-out (IM20) after IM0 | ic_libraries | LANDED 2026-09-05 on the laptop: nx_installed_census_lib + nx_installed_census + nx_installed_census_gate 39 of 39; the real library read 16 titles with engine, anti-cheat, VR, audio, net, physics, script, mod and redist labels and the review tie-out for Palworld and VR HOT; NAS promote, register, gate run and the .gates row are the remaining receipt | Organ | 1 u |
| Windows applications and OS census (IM21) after IM20 | ic_app_census | The uninstall registry hive (REGF) and Program Files are read by the sovereign ELF under WSL, one row per application with publisher, version, install location and the same fingerprint classes, plus OS build, GPU and driver rows; gate on a planted hive and tree; the rows feed nishios, browser, office and gpu boards as candidate rival-surface rows | Organ | 2 u |
| Fingerprint classes grow as data and are measured against the field (IM22) after IM20 | ic_fingerprint_bench | The conf gains renderer (DirectX 12, Vulkan), input, save-format and telemetry classes; a bench organ counts unlabelled titles per class over the census so the conf's coverage is a number with a worklist, never a claim; measured on every title installed on the estate's machines | Organ | 1 u |
| Installed mode on the NAS and the estate's own machines on a beat (IM23) after IM20 | ic_beat | A clock row runs the census where a Steam client exists (laptop through the WSL mount today), truncate-writes knowledge/reviews/installed/steam.census and appends a spine row; the beat announces when no library is reachable instead of writing an empty census | Organ | 0.5 u |
| Installed-mode proposal rows into the domain boards (IM24) after IM3,IM20 | ic_propose | Every census row with a review tie-out proposes rows into the boards its fingerprints name (engine to gameengine, VR runtime to hapticcare, audio middleware to synthroom, anti-cheat to trafficsafety) through the one proposal contract; a seat adjudicates with nx_goalmap; the gate proves a title proposes to exactly the boards its classes map to, as data | Organ | 1 u |
Milestones
| Milestone | Rungs | Cumulative |
|---|---|---|
| M4 · Installed mode: what the product ships, beside what its players say | IM20,IM21,IM22,IM23,IM24 | 5.5 u |
| Rung | Closes with | Definition of done (pre-declared) | Executor | Est. |
|---|---|---|---|---|
| Vendor feature index as a source class (IM25) after IM3 | fp_feature_mine | the miner reads the vendor's own feature index and docs (site sections, features.md tiles, release notes) into capability_map terms beside reviews and fingerprints; done-rule: on DanceXR the miner's proposal rows cover at least the 37-row hand census this seat took from the vendor pages, with recall printed as rows_found of rows_hand, and a title with no feature page prints UNMEASURED rather than a proposal-free silence | Organ | 2 u |
| Mined intelligence rendered on every board: the one renderer of the proposal file lives in the compare base lib and both generators call it (IM26) after IM3 | prop_pass | done-rule: prop_pass in nx_swcompare_lib renders <dom>.proposed in both generators (a MINED FROM THE FIELD band in HTML, a proposed key in api.json); an absent file emits nothing, a malformed row is counted and never drawn, a file at the read cap announces READ-CAPPED, a title the census could not resolve prints as an unresolved appid; nx_prop_pass_gate GREEN with the absent-domain, malformed-row and read-cap controls on the NAS; the live /compare/gameengine page carries the band after the generators are promoted and buildroot/_offc is restaged | Organ | 1 u |
| Title identity from the platform's own API when no census names the appid (IM27) after IM3 | sr_name | done-rule: nx_steam_reviews name <appid> fetches the Storefront appdetails body through the sovereign TLS and the one pacer, banks it as raw/<appid>/appdetails.json, decodes the name through the one JSON decoder (rm_json_name: unicode escapes and escaped quotes proven) and writes <appid>.name; nx_intelmine_propose reads that file when the census misses and prints name_src=census, platform-api or appid so the fallback is never silent; gate teeth for the decoder and the file with the no-name-key, over-cap, absent and empty controls; live receipt name=Portal 2 for appid 620 | Organ | 0.5 u |
| Aspect extraction that closes the gap to the SemEval winners: a sequence labeller (CRF or perceptron) over POS and context features (IM28) after IM17 | sp_eval | A supervised BIO tagger trained on the SemEval-2014 restaurant and laptop TRAIN split and scored by nx_absa_bench on the TEST split must EXCEED the frequent-n-gram arm's F1 on both domains (restaurants 218 and laptops 238 permil) with the gap to the winners (DLIREC 84.01, IHS RD 74.55) stated; the estate has no CRF today so this is the honest next step, not a knob on the baseline | Organ | 3.0 u |
| The 2026 data admitted with licences: ASQP Rest15 and Rest16 quads and the DimABSA valence-arousal sets (IM29) after IM17 | ab_quad_load | The quad and dimensional sets are mirrored through nx_research_fetch with their licence files beside them and refs rows pinned; ab_quad_load reads a record into aspect, category, opinion, polarity and the VA pair through the one reader with CRLF tolerance; the gate proves the reader on planted records with a malformed-record control and the counts reconcile to the files | Organ | 1.5 u |
| The paper rulers for the 2026 task: joint term-plus-polarity F1, quad F1 and DimABSA cF1 (IM30) after IM29 | ab_eval_quad | nx_absa_bench gains the joint and quad rulers and the continuous F1 that joins structured extraction with VA regression, each reproduced on a published system output before it scores ours; the gate proves every ruler on a planted gold set with a zero-prediction control and a partition that sums | Organ | 1.5 u |
| The sovereign generative arm: nx_absa_llm over nx_qwen_extract emits quads per sentence, resumable, judged on the paper rulers (IM31) after IM29,IM30 | al_extract | One generation per test sentence journaled with its prompt hash so a crash resumes, the accept rule declared in source BEFORE the first run (it must exceed the mechanistic arm on the quad ruler or it is a mode, not the default), refusals named when the model is absent; the gate proves the journal resume, the parser on planted generations and the refusal | Organ | 3.0 u |
| The dimensional arm: valence-arousal regression on the nofloat encoder, scored by cF1 on DimABSA (IM32) after IM29,IM30 | ab_va_regress | An integer regression head on the estate's nofloat encoder trained on the DimABSA train split, scored by cF1 against the published systems with the gap stated; the gate proves the head on a planted set with a constant-prediction control | Organ | 3.0 u |
| Triangulation: the mechanistic arm and the generative arm adjudicated per sentence, the error census naming which class each wins (IM33) after IM28,IM31 | ab_triangulate | The perceptron-union arm and the generative arm run on the same sentences; agreements pass, disagreements are adjudicated by the census class (unseen multi-token terms to the generative arm, dictionary-seen singles to the mechanistic arm) with the rule declared before the run; the combined ruler must exceed both arms alone on both domains or triangulation is a mode; a hallucinated aspect (a span not in the sentence) is refused by construction and counted | Organ | 2.0 u |
Milestones
| Milestone | Rungs | Cumulative |
|---|---|---|
| M4 · The 2026 task shape: quads, dimensions, the generative arm and triangulation | IM29,IM30,IM31,IM32,IM33 | 11.0 u |
Ladder to SOTA
| Rung | Role | Toward | Stands on | Why |
|---|---|---|---|---|
| IM0 | substrate | T-FRONTIER | - | the corpus every arm runs on: the Steam adapter, the review journal and the rubric are the data acquisition the target's methods consume |
| IM1 | substrate | T-FRONTIER | IM0 | a beat keeps the corpus current so every measurement is on live text |
| IM3 | substrate | T-FRONTIER | IM0 | proposal rows carry mined intelligence into the boards the arms serve |
| IM4 | substrate | T-BIC | IM3 | the rival feature census is the pinned-bar discipline every target row depends on |
| IM14 | substrate | T-FRONTIER | IM0 | the app record and price feed the rubric the arms score |
| IM18 | substrate | T-FRONTIER | IM0 | the lab spine makes every arm's number a trajectory, never a level |
| IM2 | arm | T-BIC | IM17 | the unsupervised n-gram arm: a sovereign baseline that cannot hallucinate, superseded as a contender by the union arm |
| IM17 | substrate | T-FRONTIER | IM0 | the ruler: the frontier still evaluates on these sets and cF1 extends this exact scorer |
| IM16 | substrate | T-DIM | IM2 | sentence-level orientation is the scoring unit dimensional regression needs |
| IM10 | substrate | T-FRONTIER | IM0 | trend windows over the corpus the arms mine |
| IM11 | substrate | T-FRONTIER | IM0 | near-duplicate collapse keeps the arms from scoring the same text twice |
| IM15 | substrate | T-FRONTIER | IM0 | multilingual normalisation is the precondition for the cross-lingual frontier (eleven languages in SeqLab) |
| IM5 | substrate | T-FRONTIER | IM3 | bug trackers feed defect rows beside the review corpus |
| IM12 | substrate | T-FRONTIER | IM3 | release notes feed dated bar rows, the freshness rule's own input |
| IM6 | substrate | T-FRONTIER | IM1 | thought-leader feeds are a listing class the barscan attestation reads |
| IM7 | substrate | T-FRONTIER | IM1 | the arXiv scan on a beat IS the current-month barscan producer for every target on this board |
| IM8 | substrate | T-FRONTIER | IM0 | the Amazon adapter widens the corpus the arms run on |
| IM9 | substrate | T-FRONTIER | IM8 | the eBay adapter widens the corpus, blocked on a mirrored document |
| IM13 | substrate | T-FRONTIER | IM14 | the Steam cohort selects the population the arms measure |
| IM19 | substrate | T-FRONTIER | IM0 | source policy in the fetch path keeps every corpus licence-clean, the first byte of any arm |
| IM20 | substrate | T-FRONTIER | IM0 | the installed census ties reviews to titles the arms mine |
| IM21 | substrate | T-FRONTIER | IM20 | the application census widens the tie-out |
| IM22 | substrate | T-FRONTIER | IM20 | fingerprint classes are the labels the census carries into the arms |
| IM23 | substrate | T-FRONTIER | IM20 | the census on a beat keeps the tie-out current |
| IM24 | substrate | T-FRONTIER | IM3,IM20 | proposal rows from the census into the boards |
| IM25 | substrate | T-FRONTIER | IM3 | the vendor feature index is a source class beside reviews |
| IM26 | substrate | T-FRONTIER | IM3 | the one renderer of mined intelligence on every board |
| IM27 | substrate | T-FRONTIER | IM3 | title identity from the platform API when the census misses |
| IM28 | arm | T-FRONTIER | IM17 | the mechanistic arm: an integer structured perceptron with Viterbi BIO decoding (POS tagger, parser, clusters, CRF objective, embedding features as modes) that cannot hallucinate a span; the frontier's SeqLab adds exactly this labelling as an encoder task, and it is one leg of the triangulation the operator asked for |
| IM29 | substrate | T-FRONTIER | IM17 | the 2026 data with licences: no arm can be scored on quads or dimensions without it |
| IM30 | substrate | T-BIC | IM29 | the paper rulers for the 2026 task: the joint, quad and continuous F1 the best-in-class numbers are quoted on |
| IM31 | contender | T-FRONTIER | IM29,IM30 | the sovereign generative arm competes for the quad number against the frontier's distilled students |
| IM32 | contender | T-DIM | IM29,IM30 | the dimensional arm competes for cF1 against the SemEval-2026 systems |
| IM33 | contender | T-FRONTIER | IM28,IM31 | triangulation is the exceed candidate: the field has one arm per system, this board runs two and adjudicates by census class |
Ladder verdict, counted (17 rows, more than the 12-row disclosure bar)
| Class | Count | Note |
|---|---|---|
| targets | 3 | sotatarget rows on the plan |
| best in class | 1 | targets whose class is best-in-class, by code |
| frontier | 2 | targets whose class is frontier, by code |
| undated | 0 | targets naming no bar that exists |
| bad class | 0 | targets whose class is neither word |
| duplicate | 0 | target ids an earlier row already carries |
| rungs | 34 | rung rows on the plan |
| placed | 34 | rungs carrying a rungrole row |
| unplaced | 0 | rungs with no role toward any target |
| bad role | 0 | rungrole rows naming a role the ladder does not know |
| bad target | 0 | rungrole rows naming a target no sotatarget row declares |
| rungs, summed | 34 | RECONCILED: the parts sum to the total 34 |
| substrate | 29 | what the target's own methods consume |
| arm | 2 | a sovereign arm that triangulates without competing for the number |
| contender | 3 | its done-rule is a number against the target |
| superseded | 0 | kept as capability, retired as a claim |
| placed, summed | 34 | RECONCILED: the parts sum to the total 34 |
| Class | Count | Note |
|---|---|---|
| bars | 2 | sotabar rows on the plan |
| fresh | 0 | the bar month is the current month |
| attested | 0 | an older bar with a this-month barscan reporting no newer entry |
| stale | 0 | a this-month scan saw a newer month the bar ignores |
| unattested | 2 | nobody looked this month |
| malformed | 0 | a sotabar row missing a field |
| duplicate | 0 | bar ids an earlier row already carries |
| bars, summed | 2 | RECONCILED: the parts sum to the total 2 |
| current month | 2026-10 | the month every bar is judged against |
Inspect a rung and its prerequisites
Declared nodes 34. Rank input binding: STALE_OR_INVALID_BINDING. Dependency order is authored. Implementation, acceptance evidence, authority and resource readiness are unverified. No action is recommended or dispatched here.
Plan SHA-256 83810d012aeb1a9154eafabe86c481b93759fcfdbf48d6dbe3fded5fbf75ea99. Target rows 3; role rows 34. Existing risks and release worklog retain their own scope; no node completion is inferred.
Runtime observation coverage: 0 of 34 rungs have current, identity-bound execution observations. Observation may report RED. Accepted completion remains unknown; source presence, qualification and deployment do not establish it.
Use Enter or Space on a rung to inspect its contract. Prerequisite links locate another rung in this list; open its summary to inspect it. Estimates are authored effort, not forecasts.
IM0 — Steam review adapter and the decision core with the expectation rubric
Prerequisites: None declared; this does not establish execution eligibility.
Contract:
rm_rubric_docAcceptance: LANDED 2026-09-05: nx_reviewmine_lib + nx_steam_reviews + nx_steam_reviews_gate 92 of 92; fetch, ingest, stats, mine and rubric live on Palworld and VR HOT from the laptop build; the NAS build is queued behind admission and the laptop artifacts are staged; the NAS gate run and the .gates row are the remaining receipt
Authored effort: 1. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.IM1 — Beat: nightly incremental fetch plus rubric for a data-row watch list
Prerequisites: IM0 (acceptance unverified)
Contract:
im_beatAcceptance: knowledge/reviewmine/steam_watch.conf lists appids; a clock row runs fetch (incremental) then stats, mine and rubric per app and truncate-writes knowledge/status/reviewmine/appid.status with a canonical last line; a gate proves the status is rewritten (never appended) and that a refused fetch leaves the previous status intact and announced
Authored effort: 0.5. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.IM3 — Proposal file: mined defects and demanded features become candidate rows for a named board
Prerequisites: IM0 (acceptance unverified)
Contract:
im_propose_rowsAcceptance: nx_steam_reviews propose appid domain writes knowledge/compare/domain.proposed rows (label, evidence counts, the source rows) and NEVER touches the matrix or plan; a seat adjudicates with the goal map; the gate proves a proposal row carries its counts and that a second run is idempotent
Authored effort: 1. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.IM4 — Rival feature census: Wolfram's alphabetical listing parsed into candidate computational.matrix rows and a pinned bar
Prerequisites: IM3 (acceptance unverified)
Contract:
fc_censusAcceptance: The mirrored listing is parsed into one row per documented symbol grouped by guide, the count is printed with its method, computational.matrix gains a bar row pinned through nx_barcheck, and the census is idempotent; the gate proves the count against an independent tag count over the same bytes
Authored effort: 1.5. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.IM14 — The adapter fetches and banks the app record and price itself
Prerequisites: IM0 (acceptance unverified)
Contract:
sr_appdetailsAcceptance: nx_steam_reviews details appid banks appdetails JSON beside the reviews and writes the .price row the rubric reads; a planted record round-trips in the gate; a missing price prints UNKNOWN never zero
Authored effort: 0.5. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.IM18 — Lab spine: one row per run so the board renders a trajectory
Prerequisites: IM0 (acceptance unverified)
Contract:
sr_spineAcceptance: Every rubric run appends epoch, appid, docs, four tier counts, refund-window figures, top three defects and top three demands to knowledge/status/reviewmine/spine.jrnl; the emitter renders the last N rows per app; the gate proves append-only and that two runs produce two rows
Authored effort: 0.5. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.IM2 — Aspects mined from the corpus, not a hand list
Prerequisites: IM17 (acceptance unverified)
Contract:
rm_aspectsAcceptance: Frequent noun-phrase candidates (unigram and bigram, association-mined per Hu and Liu) with opinion orientation per aspect, scored on the SemEval-2014 laptop and restaurant sets through IM17; PRE-DECLARED accept rule: the mined table is not wired into the rubric until its aspect-term F1 is published beside the rung
Authored effort: 2. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.IM17 — ABSA bench: SemEval-2014 Task 4 scored by a sovereign organ
Prerequisites: IM0 (acceptance unverified)
Contract:
ab_evalAcceptance: The SemEval-2014 datasets are mirrored with their licence, the bench scores aspect-term extraction (subtask 1) and polarity (subtask 2) and prints P, R, F1 with the counts; its gate proves the scorer on a planted gold set including a zero-prediction control
Authored effort: 1.5. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.IM16 — Sentence-level opinion orientation
Prerequisites: IM2 (acceptance unverified)
Contract:
rm_opinion_sentAcceptance: Reviews split into sentences, each sentence graded with the lexicons and the vote as prior, per-aspect polarity counts printed; measured against IM17 subtask 2
Authored effort: 1.5. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.IM10 — Time-window trend: tiers by review-date window around a release
Prerequisites: IM0 (acceptance unverified)
Contract:
rm_trendAcceptance: Rubric per window (30-day recent, lifetime, and a caller-named window) with the windows partition summing to docs; Steam's own recent-versus-lifetime score is the oracle it is checked against
Authored effort: 1. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.IM11 — Near-duplicate and spam collapse
Prerequisites: IM0 (acceptance unverified)
Contract:
rm_neardupAcceptance: Shingle hashing over review text with a Hamming nearest, collapsed rows counted and named, never deleted; measured against Steam's off-topic exclusion by running with filter_offtopic_activity both ways
Authored effort: 1. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.IM15 — Multilingual normalisation: per-language stopwords and stemming
Prerequisites: IM0 (acceptance unverified)
Contract:
rm_lang_normAcceptance: Stopword and lexicon confs per Steam language code, a stemmer for the top languages measured in the journal (english, russian, schinese, spanish, german), and the mine and rubric verbs accept all with per-language partitions that sum
Authored effort: 1.5. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.IM5 — Bug trackers mined into defect rows
Prerequisites: IM3 (acceptance unverified)
Contract:
bt_issue_ingestAcceptance: GitHub issues for a rival named in a board's refs are fetched through the pacer, labels and titles journaled, and defect terms counted with the same lexicon so a rival's known defects sit beside its reviewers' complaints; gate on a planted issues page
Authored effort: 1. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.IM12 — Release notes mined into bar rows
Prerequisites: IM3 (acceptance unverified)
Contract:
rl_release_ingestAcceptance: GitHub releases for every rival in a board's refs journaled and the latest pinned through nx_barcheck into knowledge/barcheck.conf; computational.matrix's four UNPINNED bars are the first population; gate on a planted releases page
Authored effort: 1. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.IM6 — Thought-leader feed watch
Prerequisites: IM1 (acceptance unverified)
Contract:
tl_feed_watchAcceptance: A data-row list of feeds (people, blogs, vendor changelogs) polled on a beat through nx_feed_extract into the resbrief plane with the domain it feeds; a gate on a planted Atom feed proves items land once
Authored effort: 1. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.IM7 — Research scan: arXiv queries per domain axis
Prerequisites: IM1 (acceptance unverified)
Contract:
rs_arxiv_scanAcceptance: nx_frontier_scan's seeds are run against the arXiv API on a beat, results banked with provenance and cited into the domain's refs as candidates; a gate on a planted Atom response
Authored effort: 1. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.IM8 — Amazon adapter over the research release
Prerequisites: IM0 (acceptance unverified)
Contract:
rm_amazon_ingestAcceptance: The Amazon Reviews 2023 JSONL record shape journals through the same row codec with rating mapped to the vote and verified_purchase to a flag; the rubric runs unchanged; the gate proves the mapping on planted rows
Authored effort: 1. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.IM9 — eBay feedback adapter
Prerequisites: IM8 (acceptance unverified)
Contract:
rm_ebay_ingestAcceptance: BLOCKED on a mirrored eBay document (two 403s and a wrong article on 2026-09-05); the rung opens when a feedback API page is mirrored and cited; nothing is coded against an unread bar
Authored effort: 1. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.IM13 — Steam cohort: app list and genre neighbours
Prerequisites: IM14 (acceptance unverified)
Contract:
sr_applistAcceptance: IStoreService GetAppList (the non-deprecated endpoint) plus appdetails genres select the games-like-ours population as data rows; the gate proves the selection on a planted list
Authored effort: 1. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.IM19 — Source policy in the fetch path
Prerequisites: IM0 (acceptance unverified)
Contract:
im_source_policyAcceptance: knowledge/reviewmine/source_policy.conf declares per host allowed feeds, forbidden stores and required disclosures; every adapter reads it before its first byte and refuses with the rule named; the gate proves a forbidden host is refused and an allowed one proceeds (positive control)
Authored effort: 0.5. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.IM20 — Installed mode: Steam library census with fingerprints and review tie-out
Prerequisites: IM0 (acceptance unverified)
Contract:
ic_librariesAcceptance: LANDED 2026-09-05 on the laptop: nx_installed_census_lib + nx_installed_census + nx_installed_census_gate 39 of 39; the real library read 16 titles with engine, anti-cheat, VR, audio, net, physics, script, mod and redist labels and the review tie-out for Palworld and VR HOT; NAS promote, register, gate run and the .gates row are the remaining receipt
Authored effort: 1. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.IM21 — Windows applications and OS census
Prerequisites: IM20 (acceptance unverified)
Contract:
ic_app_censusAcceptance: The uninstall registry hive (REGF) and Program Files are read by the sovereign ELF under WSL, one row per application with publisher, version, install location and the same fingerprint classes, plus OS build, GPU and driver rows; gate on a planted hive and tree; the rows feed nishios, browser, office and gpu boards as candidate rival-surface rows
Authored effort: 2. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.IM22 — Fingerprint classes grow as data and are measured against the field
Prerequisites: IM20 (acceptance unverified)
Contract:
ic_fingerprint_benchAcceptance: The conf gains renderer (DirectX 12, Vulkan), input, save-format and telemetry classes; a bench organ counts unlabelled titles per class over the census so the conf's coverage is a number with a worklist, never a claim; measured on every title installed on the estate's machines
Authored effort: 1. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.IM23 — Installed mode on the NAS and the estate's own machines on a beat
Prerequisites: IM20 (acceptance unverified)
Contract:
ic_beatAcceptance: A clock row runs the census where a Steam client exists (laptop through the WSL mount today), truncate-writes knowledge/reviews/installed/steam.census and appends a spine row; the beat announces when no library is reachable instead of writing an empty census
Authored effort: 0.5. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.IM24 — Installed-mode proposal rows into the domain boards
Prerequisites: IM3 (acceptance unverified), IM20 (acceptance unverified)
Contract:
ic_proposeAcceptance: Every census row with a review tie-out proposes rows into the boards its fingerprints name (engine to gameengine, VR runtime to hapticcare, audio middleware to synthroom, anti-cheat to trafficsafety) through the one proposal contract; a seat adjudicates with nx_goalmap; the gate proves a title proposes to exactly the boards its classes map to, as data
Authored effort: 1. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.IM25 — Vendor feature index as a source class
Prerequisites: IM3 (acceptance unverified)
Contract:
fp_feature_mineAcceptance: the miner reads the vendor's own feature index and docs (site sections, features.md tiles, release notes) into capability_map terms beside reviews and fingerprints; done-rule: on DanceXR the miner's proposal rows cover at least the 37-row hand census this seat took from the vendor pages, with recall printed as rows_found of rows_hand, and a title with no feature page prints UNMEASURED rather than a proposal-free silence
Authored effort: 2. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.IM26 — Mined intelligence rendered on every board: the one renderer of the proposal file lives in the compare base lib and both generators call it
Prerequisites: IM3 (acceptance unverified)
Contract:
prop_passAcceptance: done-rule: prop_pass in nx_swcompare_lib renders <dom>.proposed in both generators (a MINED FROM THE FIELD band in HTML, a proposed key in api.json); an absent file emits nothing, a malformed row is counted and never drawn, a file at the read cap announces READ-CAPPED, a title the census could not resolve prints as an unresolved appid; nx_prop_pass_gate GREEN with the absent-domain, malformed-row and read-cap controls on the NAS; the live /compare/gameengine page carries the band after the generators are promoted and buildroot/_offc is restaged
Authored effort: 1. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.IM27 — Title identity from the platform's own API when no census names the appid
Prerequisites: IM3 (acceptance unverified)
Contract:
sr_nameAcceptance: done-rule: nx_steam_reviews name <appid> fetches the Storefront appdetails body through the sovereign TLS and the one pacer, banks it as raw/<appid>/appdetails.json, decodes the name through the one JSON decoder (rm_json_name: unicode escapes and escaped quotes proven) and writes <appid>.name; nx_intelmine_propose reads that file when the census misses and prints name_src=census, platform-api or appid so the fallback is never silent; gate teeth for the decoder and the file with the no-name-key, over-cap, absent and empty controls; live receipt name=Portal 2 for appid 620
Authored effort: 0.5. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.IM28 — Aspect extraction that closes the gap to the SemEval winners: a sequence labeller (CRF or perceptron) over POS and context features
Prerequisites: IM17 (acceptance unverified)
Contract:
sp_evalAcceptance: A supervised BIO tagger trained on the SemEval-2014 restaurant and laptop TRAIN split and scored by nx_absa_bench on the TEST split must EXCEED the frequent-n-gram arm's F1 on both domains (restaurants 218 and laptops 238 permil) with the gap to the winners (DLIREC 84.01, IHS RD 74.55) stated; the estate has no CRF today so this is the honest next step, not a knob on the baseline
Authored effort: 3.0. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.IM29 — The 2026 data admitted with licences: ASQP Rest15 and Rest16 quads and the DimABSA valence-arousal sets
Prerequisites: IM17 (acceptance unverified)
Contract:
ab_quad_loadAcceptance: The quad and dimensional sets are mirrored through nx_research_fetch with their licence files beside them and refs rows pinned; ab_quad_load reads a record into aspect, category, opinion, polarity and the VA pair through the one reader with CRLF tolerance; the gate proves the reader on planted records with a malformed-record control and the counts reconcile to the files
Authored effort: 1.5. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.IM30 — The paper rulers for the 2026 task: joint term-plus-polarity F1, quad F1 and DimABSA cF1
Prerequisites: IM29 (acceptance unverified)
Contract:
ab_eval_quadAcceptance: nx_absa_bench gains the joint and quad rulers and the continuous F1 that joins structured extraction with VA regression, each reproduced on a published system output before it scores ours; the gate proves every ruler on a planted gold set with a zero-prediction control and a partition that sums
Authored effort: 1.5. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.IM31 — The sovereign generative arm: nx_absa_llm over nx_qwen_extract emits quads per sentence, resumable, judged on the paper rulers
Prerequisites: IM29 (acceptance unverified), IM30 (acceptance unverified)
Contract:
al_extractAcceptance: One generation per test sentence journaled with its prompt hash so a crash resumes, the accept rule declared in source BEFORE the first run (it must exceed the mechanistic arm on the quad ruler or it is a mode, not the default), refusals named when the model is absent; the gate proves the journal resume, the parser on planted generations and the refusal
Authored effort: 3.0. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.IM32 — The dimensional arm: valence-arousal regression on the nofloat encoder, scored by cF1 on DimABSA
Prerequisites: IM29 (acceptance unverified), IM30 (acceptance unverified)
Contract:
ab_va_regressAcceptance: An integer regression head on the estate's nofloat encoder trained on the DimABSA train split, scored by cF1 against the published systems with the gap stated; the gate proves the head on a planted set with a constant-prediction control
Authored effort: 3.0. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.IM33 — Triangulation: the mechanistic arm and the generative arm adjudicated per sentence, the error census naming which class each wins
Prerequisites: IM28 (acceptance unverified), IM31 (acceptance unverified)
Contract:
ab_triangulateAcceptance: The perceptron-union arm and the generative arm run on the same sentences; agreements pass, disagreements are adjudicated by the census class (unseen multi-token terms to the generative arm, dictionary-seen singles to the mechanistic arm) with the rule declared before the run; the combined ruler must exceed both arms alone on both domains or triangulation is a mode; a hallucinated aspect (a span not in the sentence) is refused by construction and counted
Authored effort: 2.0. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.
Learning and practice paths
No structured learning path is declared for this plan. Existing research, roadmap and worklog remain available above.
Rung dossiers — every record that bears on a rung, in one place
nx_swcompare_evidence intelmine writes it beside its stamp); every gate below reads UNRECORDED until it runs.knowledge/organ_gate.conf read from this working directory (1 rows) and from the estate root (196 rows); rows in both counted once: 0; declarations read: 197. Every declaration in either copy counts, so a stub beside the publisher can never hide the root.IM0 Steam review adapter and the decision core with the expectation rubric · cell PRESENT · gate NO-GATE-DECLARED
| Contract | rm_rubric_doc · executor Organ · 1 u · stands on nothing |
|---|---|
| Definition of done | LANDED 2026-09-05: nx_reviewmine_lib + nx_steam_reviews + nx_steam_reviews_gate 92 of 92; fetch, ingest, stats, mine and rubric live on Palworld and VR HOT from the laptop build; the NAS build is queued behind admission and the laptop artifacts are staged; the NAS gate run and the .gates row are the remaining receipt |
| Matrix cell | MINE: expectation rubric -- EXCEEDS, MEETS, MIXED, DOES-NOT-MEET -- the vote decides, a lexicon lifts or qualifies, the partition prints its sum · runtime/nx_reviewmine_lib.nx · PRESENT decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_reviewmine_lib; declare nx_reviewmine_lib TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | 2026-09-05 measure Palworld appid 1623730 (2099 cents): 3000 most recent English reviews, positive 947 permil; rubric EXCEEDS 401 MEETS 2358 MIXED 82 DOES-NOT-MEET 159 (sum 3000); playtime bands lt1h 26 at 346 permil positive, 1-10h 326 at 911, 10-100h 1326 at 945, gt100h 1322 at 968; refund window 40 docs at 400 permil; value mentions EXCEEDS 46 MEETS 125 MIXED 36 DNM 21; top defects progress 35 docs (DNM 5), unplayable 10 (lift 13.6x), bugs 32, lost 31, crashes 11 (lift 10.9x), wiped 4 (lift 14.9x), error 6 (lift 13.3x); top features pals 419 (demanded 124), base 250 (93), world 242 (90), survival 223, building 206 (76), friends 146. Instrument: nx_steam_reviews rubric 1623730 english 20 3 on the laptop build sha af365865. 2026-09-05 measure VR HOT appid 1571340 (4499 cents): the whole English population, 711 reviews (stop=empty-page), positive 610 permil, all written during early access, 57 refunded flags; rubric EXCEEDS 69 MEETS 338 MIXED 27 DOES-NOT-MEET 277 (sum 711); bands lt1h 246 at 443 permil, 1-10h 349 at 656, 10-100h 104 at 836, gt100h 12 at 750; refund window 384 docs at 468 permil; value mentions EXCEEDS 13 MEETS 31 MIXED 11 DNM 82; top defects bugs 27, buggy 26, broken 14 (DNM 13, meets 0), crashes 17, glitches 17, unplayable 11; features complained more than praised: controls 46 vs 21 (demanded 35), physics 26 vs 15, menu 14 vs 5, controller 13 vs 4, tracking 8 vs 3; praised more than complained: updates 21 vs 6, customization 20 vs 13, graphics 19 vs 13. 2026-09-05 lesson The reading the operator asked for, stated as numbers not adjectives: VR HOT at 4499 cents carries a value-proposition signal (value talk sits in 296 permil of does-not-meet reviews against 188 permil of exceeds, and 54 percent of its reviewers wrote inside the refund window) AND a defect signal (controls, physics, tracking, menu complained about more than praised are leaky teapots wearing feature names); Palworld at 2099 cents carries almost no value signal (947 permil positive, 968 among players past 100 hours) and a narrow defect signal concentrated in progress loss, wipes and crashes -- the brand-degradation class, cheap to name and expensive to leave. What we must do BETTER than both to lead: no lost-progress class at all (Palworld's top defect), controls and tracking that are praised more than complained about (VR HOT's top complaint), and the demanded features (pals, base, building, friends coop; customization, interaction) shipped as capability, which is the target list the goal map now reads. 2026-09-05 lesson Two fetch facts earned the hard way: the Chrome-hello leg alone fails the TLS handshake against store.steampowered.com (status 0, code -3) while the full ladder (minimal 1.3 hello first) succeeds -- compose nx_https_fetch_follow_best, the entry nx_research_fetch rides; and the laptop's _hdl_build/nx_crawl_pace.nx was an 8 KB fossil from 08-07 missing every _tbl function the pacer hook needs -- the NAS copy (27,045 B, sha 2abc63a3) was adopted by hash before the first build, per the tree-divergence law. 2026-09-05 queue NAS build of nx_steam_reviews REFUSED by build admission (I/O storm) and QUEUED as BQ-nx_steam_reviews; laptop artifacts (program sha af365865, gate sha 6bf93f26) staged through nx_content_put for /api/promote; NAS gate run, tools/register, the .gates row, nishi_compare_regen, nx_domain_admit and nx_compare_rank follow the promote. 2026-09-05 land PROMOTED on the NAS 2026-09-05: nx_steam_reviews.elf 552,180 B sha af365865 (the /api/promote reply was a 503 read-after-accept and the artifact proved it had landed) and nx_steam_reviews_gate.elf 99,750 B sha 6bf93f26 (PROMOTED prev=1); both REGISTERED callable; sources on the NAS build tree nx_reviewmine_lib.nx sha 22c47f51, nx_steam_reviews.nx sha 59366f18, nx_steam_reviews_gate.nx sha 46bba0b6 (a 503 on its content-put HAD landed; the retry was refused stale-expect, which is the proof); lexicons and stopwords under knowledge/reviewmine/ on the NAS; the NAS gate run read 92/92 GREEN (pid 2412) and the NAS live fetch of Portal 2 read status=200 decoded=100 new=100 (pid 2481); knowledge/compare/intelmine.gates carries the row; nx_domain_admit VERDICT=ADMIT; nx_compare_rank ranks IM1 im_beat first (priority 20000), then IM3, IM14, IM18, IM4. The artifacts are LAPTOP builds shipped through the content door because NAS admission refused the build (I/O storm): the closure files that differed were adopted by hash (nx_crawl_pace), and the queued NAS build BQ-nx_steam_reviews will yield the NAS-built twin for a contentdiff when it fires. |
IM1 Beat: nightly incremental fetch plus rubric for a data-row watch list · cell WATCHING · gate NO-GATE-DECLARED
| Contract | im_beat · executor Organ · 0.5 u · stands on IM0 |
|---|---|
| Definition of done | knowledge/reviewmine/steam_watch.conf lists appids; a clock row runs fetch (incremental) then stats, mine and rubric per app and truncate-writes knowledge/status/reviewmine/appid.status with a canonical last line; a gate proves the status is rewritten (never appended) and that a refused fetch leaves the previous status intact and announced |
| Matrix cell | OPERATE: beat cadence -- nightly incremental fetch and rubric for a data-row list of watched apps, a status artifact per app · runtime/nx_steam_reviews.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_steam_reviews; declare nx_steam_reviews TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
IM3 Proposal file: mined defects and demanded features become candidate rows for a named board · cell NO-MATRIX-ROW · gate NO-MATRIX-ROW
| Contract | im_propose_rows · executor Organ · 1 u · stands on IM0 |
|---|---|
| Definition of done | nx_steam_reviews propose appid domain writes knowledge/compare/domain.proposed rows (label, evidence counts, the source rows) and NEVER touches the matrix or plan; a seat adjudicates with the goal map; the gate proves a proposal row carries its counts and that a second run is idempotent |
| Matrix cell | NO-MATRIX-ROW — no matrix row carries im_propose_rows; the ranker reads this rung as unmapped and no cell can flip for it. Add the row and the join completes on the next publish. |
| Gate | the gate join needs a matrix row: no organ is named for this rung |
| Work log | 2026-09-05 land nx_intelmine_lib + nx_intelmine_propose + nx_intelmine_propose_gate landed on the laptop 2026-09-05: one call `nx_intelmine_propose <appid>` runs the rubric, reads the census row, routes through knowledge/reviewmine/capability_map.conf (133 rows) and appends deduped <domain>.proposed rows with a SIGNAL (DEFECT, WE-DO-BETTER, DEMANDED, THEY-DO-WELL, SHIPS) and the counts. DanceXR (1905510, 12 English reviews, tiers 3/7/0/2): 10 rows -- THEY-DO-WELL character and characters (charsim), steam (sharehub); WE-DO-BETTER headset (hapticcare), physics (softbody); SHIPS Unity (gameengine), Chromium (browser), OpenXR (hapticcare), FMOD (synthroom), SteamAPI (sharehub). Written under buildroot/knowledge/compare/<domain>.proposed; the emitter does not render .proposed yet (that is the next emitter rung), and nx_goalmap reads the boards the rows name. 2026-09-05 lesson A gate that runs its unknown-key control AFTER loading the real row measures a cleared buffer: ip_census_load clears its outputs on a miss (correct), so the fixture read 20 of 32 while the organ was right; re-ordered the control first. Same family as the estate's fixture-reached-the-condition law. 2026-09-05 measure DanceXR as the operator's worked target [appdetails-dancexr]: the store record says it is a character model viewer and motion player for PMX, XNALara/XPS, VMD and BVH models; the install tree says Unity + OpenXR + FMOD + a Chromium runtime with 9 .assets files of 984 MB and 76 DLLs; its 12 English reviews grade 3 exceeds / 7 meets / 0 mixed / 2 does-not-meet with character and characters praised (THEY-DO-WELL, to charsim), headset and physics complained as often as praised (WE-DO-BETTER, to hapticcare and softbody). The estate already reads every format DanceXR reads (nx_pmx, nx_vmd, nx_bvhfk), so the WebGPU door for those capabilities is a gameengine and charsim rung the proposal rows now name, not a discovery. 2026-09-05 land PROMOTED + REGISTERED on the NAS 2026-09-05: nx_intelmine_propose.elf 52,006 B sha 5673b776 and nx_intelmine_propose_gate.elf 69,293 B sha 0a494ab5 (gate 33/33 on the NAS, pid 8392); sources nx_intelmine_lib.nx sha f919bc53, nx_intelmine_propose.nx sha 7db0c0db, nx_intelmine_propose_gate.nx sha f01f575a; capability_map.conf on the NAS. Live on the NAS over Portal 2 (appid 620, 100 journaled reviews, tiers 17/82/0/1): six THEY-DO-WELL rows -- story to gen, coop to gameengine, voice and dialogue to companionchat, music to synthroom, visuals to graphics -- written under buildroot/knowledge/compare/<domain>.proposed; census_row=0 there because the NAS holds no Steam library, so the name fell back to the appid (the census tie-out is laptop-side until IM23). 2026-09-05 land RULE-11 HOIST ACROSS THE FIVE MINER SOURCES (operator 2026-09-05: magic numbers everywhere): nx_magic map at threshold 2 read nx_reviewmine_lib 103 sites 17 distinct, nx_installed_census_lib 37 and 9, nx_intelmine_lib 43 and 13, nx_steam_reviews 45 and 9, nx_intelmine_propose 17 and 5; every site is now a const named for its MEANING (RM_I64_BYTES beside RM_BITS_PER_BYTE, the UTF-8 lead and continuation bytes, the JSON key quotes, the row escape length, the class indices, the summary field indices, argv positions and exit codes), the {title} token length is derived from the literal, the tier sums are loops over RM_TIER_N, and the duplicate class-name table in nx_intelmine_lib is retired in favour of ic_class_name (one table, imported); gates on the rebuilt laptop artifacts nx_steam_reviews_gate 92 of 92, nx_installed_census_gate 44 of 44, nx_intelmine_propose_gate 33 of 33 GREEN; nx_installed_census_gate rebuilt BYTE-IDENTICAL to the promoted binary (9e9094b1), the other five differ only where unrolled sums became loops and argc tests changed shape; all five sources landed on the NAS whole under CAS (nx_fs_write write expect=h<hash>) 2026-09-05 retract the intelmine.matrix IM3 note carried three stray pipes inside its prose (kind 2026-09-05 measure NAS builds from the hoisted sources: nx_installed_census BUILT 60472 B sha 7eb423bf (src_path names the target, src_stable=1) and PROMOTED prev=1 (laptop lane had built the same source to 51712 B: the known cross-lane band); nx_steam_reviews BUILT 552180 B sha af365865 which is BYTE-IDENTICAL to the already-promoted binary (nx_filehash cmp identical=1) although the source changed (three loops replaced unrolled sums; the laptop lane compiled the same source to 5582ad7a 552162 B) -- the signature the estate already recorded on 2026-09-05 as /api/build serving a stale cached artifact with an unchanged output sha across changed source; NOT promoted (a no-op) and named here so the next build of this target is checked by hash against its predecessor before it is believed fresh 2026-09-05 measure the live .proposed rows on the NAS carry name == appid (gameengine.proposed: prop |
IM4 Rival feature census: Wolfram's alphabetical listing parsed into candidate computational.matrix rows and a pinned bar · cell WATCHING · gate NO-GATE-DECLARED
| Contract | fc_census · executor Organ · 1.5 u · stands on IM3 |
|---|---|
| Definition of done | The mirrored listing is parsed into one row per documented symbol grouped by guide, the count is printed with its method, computational.matrix gains a bar row pinned through nx_barcheck, and the census is idempotent; the gate proves the count against an independent tag count over the same bytes |
| Matrix cell | SOURCE: rival feature-catalogue census -- Wolfram's alphabetical function listing first · runtime/nx_reviewmine_lib.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_reviewmine_lib; declare nx_reviewmine_lib TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
IM14 The adapter fetches and banks the app record and price itself · cell WATCHING · gate NO-GATE-DECLARED
| Contract | sr_appdetails · executor Organ · 0.5 u · stands on IM0 |
|---|---|
| Definition of done | nx_steam_reviews details appid banks appdetails JSON beside the reviews and writes the .price row the rubric reads; a planted record round-trips in the gate; a missing price prints UNKNOWN never zero |
| Matrix cell | SOURCE: Steam price and app record (appdetails) banked beside the reviews · runtime/nx_steam_reviews.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_steam_reviews; declare nx_steam_reviews TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
IM18 Lab spine: one row per run so the board renders a trajectory · cell WATCHING · gate NO-GATE-DECLARED
| Contract | sr_spine · executor Organ · 0.5 u · stands on IM0 |
|---|---|
| Definition of done | Every rubric run appends epoch, appid, docs, four tier counts, refund-window figures, top three defects and top three demands to knowledge/status/reviewmine/spine.jrnl; the emitter renders the last N rows per app; the gate proves append-only and that two runs produce two rows |
| Matrix cell | CAPABILITY TWIN: the lab spine -- one row per run (app, date, tiers, top defects, top demands) so improving or regressing is readable across runs, never a level · runtime/nx_steam_reviews.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_steam_reviews; declare nx_steam_reviews TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
IM2 Aspects mined from the corpus, not a hand list · cell WATCHING · gate NO-GATE-DECLARED
| Contract | rm_aspects · executor Organ · 2 u · stands on IM17 |
|---|---|
| Definition of done | Frequent noun-phrase candidates (unigram and bigram, association-mined per Hu and Liu) with opinion orientation per aspect, scored on the SemEval-2014 laptop and restaurant sets through IM17; PRE-DECLARED accept rule: the mined table is not wired into the rubric until its aspect-term F1 is published beside the rung |
| Matrix cell | MINE: aspects MINED from the corpus (frequent noun phrases), not a hand list · runtime/nx_reviewmine_lib.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_reviewmine_lib; declare nx_reviewmine_lib TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | 2026-09-05 measure EVIDENCE AGAINST THE STANDARD (operator 2026-09-05: make sure this is all /compare benchmarked with evidence against standards): the pre-declared bar for mined aspects is SemEval-2014 Task 4 subtask 1 (ref semeval14, paper mirrored and pinned); the GOLD SETS are now banked through nx_research_fetch with provenance rows -- knowledge/fetched/cmp_intelmine_semeval14_rest_test_gold.seg 115810 B sha 9492e951 and cmp_intelmine_semeval14_lap_test_gold.seg 61851 B sha 991c33ca (the ABSA-PyTorch mirror of the official test gold, three lines per record: sentence with a $T$ placeholder, aspect term, polarity); the bench organ nx_absa_bench (watch row ORACLE SemEval-2014, symbol _ABSENT_) scores the miner's frequency-ranked vocabulary (the Hu-Liu frequent-term baseline, ref hu-liu-2004) against these gold terms and prints recall, precision and F1 in permil beside the published winning F1s, the ORACLE Steam score stays the platform oracle; nx_capsearch absa semeval aspect term bench f1 returned no incumbent (7400 considered, corpus_complete=1), so the organ is a build, not a retrieval miss. Same pass: intelmine.gates gained the nx_prop_pass_gate row (41 of 41 on the NAS), the IM27 row now cites the appdetails record [appdetails-vrhot], Appbot [appbot] and the community downloader [dsr], and the stray pipes in the INSTALLED SHIPS note that made the regen refuse the whole domain (row-index 39 read 12 fields) are commas -- the regen was IO-storm refused twice after, the clock beat republishes |
IM17 ABSA bench: SemEval-2014 Task 4 scored by a sovereign organ · cell PRESENT · gate NO-GATE-DECLARED
| Contract | ab_eval · executor Organ · 1.5 u · stands on IM0 |
|---|---|
| Definition of done | The SemEval-2014 datasets are mirrored with their licence, the bench scores aspect-term extraction (subtask 1) and polarity (subtask 2) and prints P, R, F1 with the counts; its gate proves the scorer on a planted gold set including a zero-prediction control |
| Matrix cell | ORACLE: SemEval-2014 aspect-term F1 as the pre-declared bar for mined aspects · runtime/nx_absa_lib.nx · PRESENT decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_absa_lib; declare nx_absa_lib TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | 2026-09-05 measure ABSA BENCH SUBTASK 1 MEASURED (nx_absa_bench: a unigram document-frequency baseline over the reconstructed SemEval-2014 test sentences, K = distinct gold terms, exact normalised term-set match, stopwords knowledge/reviewmine/stopwords.conf 1056 B): restaurants gold 520 distinct terms predicted 520 matched 126 P 242 R 242 F1 242 permil (content vocab 1717); laptops gold 389 predicted 389 matched 93 P 239 R 239 F1 239 permil (vocab 1171). Published bars from Table 4 of the mirrored paper (knowledge/fetched/cmp_intelmine_semeval14_paper.pdf sha f2c18570 188688 B, text via nx_pdf_text, ref semeval14-paper): restaurants winner DLIREC 84.01, laptops winner IHS RD 74.55, organisers dictionary baseline 47.15 and 35.64. Run on the laptop against byte-identical copies of the NAS gold (laptops 61851 B exact; restaurants 115808 of 115810 B, the trailing newline) because the NAS build was admission-refused under the I/O storm and queued (BQ-nx_absa_bench rc=0); the scorer is deterministic so the NAS run reproduces it 2026-09-05 land nx_absa_lib (the ONE SB1 scorer: composes rm_next_token through rm_mine_doc and rm_mine_rank, F1 = 2 inter over S plus G from counts), nx_absa_bench (CLI) and nx_absa_bench_gate (27 of 27 GREEN on the laptop: F1 arithmetic at exact permil, zero-prediction and no-gold controls, distinct-term dedupe, CRLF tolerance, case and whitespace normaliser, the unigram-cannot-match-multiword control, a non-vacuous end-to-end eval) landed in the laptop tree and on the NAS at runtime/ and buildroot/runtime/ (lib 11891, bench 3392, gate 6416 B). NAS builds queued BQ-nx_absa_bench and BQ-nx_absa_bench_gate behind admission; promote, register, offc_install, the intelmine.gates row and the NAS gate run follow when the queue fires. The ORACLE watch row now names runtime/nx_absa_bench.nx ab_eval with the measured F1 in its note. RUNG IM17 IS PARTIAL: subtask 1 scored, subtask 2 polarity accuracy not yet 2026-09-05 lesson THE GATE CAUGHT A MASKED CORPUS: the .seg sentence line replaces the aspect term with $T$, so the first predictor mined sentences that could never contain a gold term and matched 0 of 3 on the planted fixture; the fix reconstructs each sentence by substituting the term back before tokenising. A bench that scored the masked corpus would have published a confident zero. Also measured: a NAS build refused by admission is QUEUED (rc=0), not dead, and its .claim reads CLAIMED until the refusal body lands in .out; a 115 KB nx_fs read persisted as plain text while a 62 KB read persisted as a JSON-wrapped result, so a large read is not a file copy until its shape is checked 2026-09-05 measure REFEREES AFTER THE ORACLE FLIP: nx_swcompare_evidence intelmine verdict=MEASURED-HONEST present_axes=30 grounded=30 ungrounded=0 gates_green=4 of 4, the ORACLE row grounding on sym=ab_eval x2 at runtime/nx_absa_lib.nx (the first flip named runtime/nx_absa_bench.nx, which only CALLS ab_eval, and the ONE SYMBOL RULER correctly refused it SUBSTRING-ONLY rule=decl -- a watch row must name the organ that DECLARES the symbol, not a caller); nx_compare_refs_gate 44 of 44 GREEN fleet-wide with the new semeval14-paper row (files 109 rows 1561 pins matched 1495 of 1495 marks 3755 uncited 0, the earlier redirect-ratchet RED re-baselined by its lane at open=14). Both NAS builds are queued behind admission (BQ-nx_absa_bench, BQ-nx_absa_bench_gate, queue_launch_rc=0); the intelmine page (181849 B after the earlier publish) does not yet carry the F1 note, the regen relaunched after the lease holder 2026-09-05 measure ABSA BENCH SUBTASK 2 MEASURED (nx_absa_bench, accuracy over the gold aspect terms, two arms): restaurants records 1120 (positive 728 negative 196 neutral 196 other 0) majority arm positive 650 permil, lexicon arm 286 permil (defect and not-met cues vs exceed cues through the ONE tokenizer, 133 lexicon terms loaded, predicted positive 131 negative 15 neutral 974); laptops records 638 (341 128 169 0) majority 534 permil, lexicon 327 permil (predicted 42 54 542). Published Table 6 bars from the mirrored paper: winners DCU 80.95 restaurants, DCU and NRC-Canada 70.48 laptops, organisers baseline 64.28 and 51.37, majority 64.19 and 52.14. PROVENANCE CHECK FOR FREE: the gold class counts reproduce Table 2 of the paper exactly (RST-TE 728 196 196, LPT-TE 341 128 169) once the conflict class the .seg mirror drops is removed (14 and 16 records), so the mirrored gold IS the official test set minus conflict. FINDING: the lexicon arm sits BELOW the majority arm in both domains because the estate cue lexicons are Steam-review vocabulary and read 974 of 1120 restaurant sentences as neutral -- a domain-general sentiment lexicon and sentence-level orientation (rm_opinion_sent) is the rung, not a bigger game lexicon. Gate 49 of 49 on the laptop (SB2 teeth on planted lexicons, a no-lexicon control that predicts every record neutral, an absent-gold control that divides nothing). RUNG IM17 done-rule now MET mechanically (both subtasks printed with counts, the gate proves the scorer with a zero-prediction control); referee and operator acceptance still owed; the SB2 deltas shipped to the NAS sources under CAS so the queued BQ builds compile the complete organ 2026-09-05 queue WAITING ON THE BUILD QUEUE, RECIPE FOR THE NEXT SEAT: nx_absa_lib, nx_absa_bench and nx_absa_bench_gate sources are on the NAS at runtime/ AND buildroot/runtime/ hash-identical to the laptop-proven tree (lib 32ff1e2b 17972 B, bench 1f066abc 5417 B, gate 10cf927f 9998 B). Every /api/build this session was admission-refused at fire time (run queue 13 of 8 CPUs, an I/O storm before that) and absorbed as BQ-nx_absa_bench and BQ-nx_absa_bench_gate with queue_launch_rc=0; nx_orchestrate fires them on its first pass with build headroom (the gate's first queued fire already produced the SB1-only artifact 17d5bcf4 50127 B, byte-identical to the laptop build of that source, so the lane and the queue are proven). When knowledge/store/planrun-build-<target>- carries a result: (1) POST /api/promote target=nx_absa_bench&confirm=yes&expect_sha256=<sha> (2) /api/tools/register name=nx_absa_bench&elf=nx_absa_bench.elf&confirm=yes (3) nx_offc_install nx_absa_bench (4) nx_job_run nx_absa_bench /tmp/absa_rest.out knowledge/fetched/cmp_intelmine_semeval14_rest_test_gold.seg 0 restaurants and the laptops twin -- expect restaurants F1 242 SB2 majority 650 lexicon 286 and laptops F1 239 majority 534 lexicon 327 (deterministic, must reproduce the laptop numbers) (5) promote the gate, nx_job_run nx_absa_bench_gate /tmp/absa_gate.out, expect 49 of 49 GREEN, then append to knowledge/compare/intelmine.gates: nx_absa_bench_gate.elf 2026-09-05 land SHIPPED ON THE NAS: once the box calmed (load 10.2, 2 running) /api/build compiled both targets from the hash-verified sources (src_path buildroot/runtime, src_stable=1): nx_absa_bench 49456 B ff2a8df2, nx_absa_bench_gate 69640 B a45131d6 (mgmt-lane sizes; the queue's own sov-lane fire had produced 59833 B 2836552f, byte-identical to the laptop build of the same gate source). PROMOTED both with expect_sha256 (live hashes re-read and equal), REGISTERED both (callable), nx_offc_install both (installed=1). REPRODUCTION: nx_job_run nx_absa_bench over the NAS gold prints exactly the laptop numbers -- restaurants F1 242 (520 gold, 126 matched) SB2 majority 650 lexicon 286 (records 1120: 728 196 196), laptops F1 239 (389, 93) majority 534 lexicon 327 (638: 341 128 169) -- two build lanes, one output, so the number is a measurement of the gold and the method, not of a binary. nx_absa_bench_gate 49 of 49 GREEN on the NAS (pid 21710); intelmine.gates row appended; the compare beat republished /compare/intelmine (191879 B) carrying the SB1 and SB2 notes on the ORACLE row. The IM17 done-rule is met mechanically; referee panel grade and the operator ACCEPT row remain owed, and the honest reading stays: a weak baseline far below the published systems, the gap named as rm_aspects and rm_opinion_sent 2026-09-05 land N-GRAM ARM SHIPPED (rung rm_aspects, first cut): nx_absa_lib gained a frequent n-gram extractor with Hu and Liu (2004) p-support redundancy pruning (bigrams beside unigrams through the ONE tokenizer, a stopword ends a phrase, min support 1 percent of sentences, a unigram inside a frequent bigram with p-support below 3 is a pruned fragment); nx_absa_bench prints ABSA-BENCH-NGRAM beside the unigram arm, gate 66/66 laptop AND NAS (pid 669, PROMOTED 39870409) with a repeated-bigram fixture, a p-support pruning proof, a beats-the-unigram-arm tooth and a support-above-frequency abstain control. MEASURED on the real gold (reproduced NAS == laptop): restaurants precision 429 recall 146 F1 218 permil (177 candidates, 20 frequent bigrams, 6 matched, 12 pruned, min support 11 of 1120); laptops precision 333 recall 185 F1 238 (216 candidates, 26 bigrams, 12 matched, 21 pruned, min support 6 of 638). READING: the n-gram arm nearly DOUBLES precision (242 -> 429 restaurants, 239 -> 333 laptops) and recovers multi-word gold terms the unigram arm structurally cannot (0 -> 6 and 12 matched bigrams), but the 1-percent support floor cuts recall so F1 is roughly flat -- the documented frequency-mining tradeoff. It is NOT SOTA and says so: the winners are CRF sequence labellers with POS, parsing and external lexicons, so the remaining gap is rung IM28 (nx_absa_seqextract), a supervised tagger, not a support knob tuned on the test set. rm_vocab_stop accessor added to nx_reviewmine_lib for the phrase-boundary check |
IM16 Sentence-level opinion orientation · cell WATCHING · gate NO-GATE-DECLARED
| Contract | rm_opinion_sent · executor Organ · 1.5 u · stands on IM2 |
|---|---|
| Definition of done | Reviews split into sentences, each sentence graded with the lexicons and the vote as prior, per-aspect polarity counts printed; measured against IM17 subtask 2 |
| Matrix cell | MINE: sentence-level opinion orientation · runtime/nx_reviewmine_lib.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_reviewmine_lib; declare nx_reviewmine_lib TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
IM10 Time-window trend: tiers by review-date window around a release · cell WATCHING · gate NO-GATE-DECLARED
| Contract | rm_trend · executor Organ · 1 u · stands on IM0 |
|---|---|
| Definition of done | Rubric per window (30-day recent, lifetime, and a caller-named window) with the windows partition summing to docs; Steam's own recent-versus-lifetime score is the oracle it is checked against |
| Matrix cell | MINE: time-window trend -- recent versus lifetime tiers around a release · runtime/nx_reviewmine_lib.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_reviewmine_lib; declare nx_reviewmine_lib TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
IM11 Near-duplicate and spam collapse · cell WATCHING · gate NO-GATE-DECLARED
| Contract | rm_neardup · executor Organ · 1 u · stands on IM0 |
|---|---|
| Definition of done | Shingle hashing over review text with a Hamming nearest, collapsed rows counted and named, never deleted; measured against Steam's off-topic exclusion by running with filter_offtopic_activity both ways |
| Matrix cell | MINE: near-duplicate and spam collapse · runtime/nx_reviewmine_lib.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_reviewmine_lib; declare nx_reviewmine_lib TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
IM15 Multilingual normalisation: per-language stopwords and stemming · cell WATCHING · gate NO-GATE-DECLARED
| Contract | rm_lang_norm · executor Organ · 1.5 u · stands on IM0 |
|---|---|
| Definition of done | Stopword and lexicon confs per Steam language code, a stemmer for the top languages measured in the journal (english, russian, schinese, spanish, german), and the mine and rubric verbs accept all with per-language partitions that sum |
| Matrix cell | MINE: multilingual tokenisation -- per-language stopwords and stemming · runtime/nx_reviewmine_lib.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_reviewmine_lib; declare nx_reviewmine_lib TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
IM5 Bug trackers mined into defect rows · cell WATCHING · gate NO-GATE-DECLARED
| Contract | bt_issue_ingest · executor Organ · 1 u · stands on IM3 |
|---|---|
| Definition of done | GitHub issues for a rival named in a board's refs are fetched through the pacer, labels and titles journaled, and defect terms counted with the same lexicon so a rival's known defects sit beside its reviewers' complaints; gate on a planted issues page |
| Matrix cell | SOURCE: bug trackers mined into defect rows · runtime/nx_reviewmine_lib.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_reviewmine_lib; declare nx_reviewmine_lib TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
IM12 Release notes mined into bar rows · cell WATCHING · gate NO-GATE-DECLARED
| Contract | rl_release_ingest · executor Organ · 1 u · stands on IM3 |
|---|---|
| Definition of done | GitHub releases for every rival in a board's refs journaled and the latest pinned through nx_barcheck into knowledge/barcheck.conf; computational.matrix's four UNPINNED bars are the first population; gate on a planted releases page |
| Matrix cell | SOURCE: release notes and changelogs mined into bar rows for every rival a board names · runtime/nx_reviewmine_lib.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_reviewmine_lib; declare nx_reviewmine_lib TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
IM6 Thought-leader feed watch · cell NO-MATRIX-ROW · gate NO-MATRIX-ROW
| Contract | tl_feed_watch · executor Organ · 1 u · stands on IM1 |
|---|---|
| Definition of done | A data-row list of feeds (people, blogs, vendor changelogs) polled on a beat through nx_feed_extract into the resbrief plane with the domain it feeds; a gate on a planted Atom feed proves items land once |
| Matrix cell | NO-MATRIX-ROW — no matrix row carries tl_feed_watch; the ranker reads this rung as unmapped and no cell can flip for it. Add the row and the join completes on the next publish. |
| Gate | the gate join needs a matrix row: no organ is named for this rung |
| Work log | no log row names this rung yet |
IM7 Research scan: arXiv queries per domain axis · cell NO-MATRIX-ROW · gate NO-MATRIX-ROW
| Contract | rs_arxiv_scan · executor Organ · 1 u · stands on IM1 |
|---|---|
| Definition of done | nx_frontier_scan's seeds are run against the arXiv API on a beat, results banked with provenance and cited into the domain's refs as candidates; a gate on a planted Atom response |
| Matrix cell | NO-MATRIX-ROW — no matrix row carries rs_arxiv_scan; the ranker reads this rung as unmapped and no cell can flip for it. Add the row and the join completes on the next publish. |
| Gate | the gate join needs a matrix row: no organ is named for this rung |
| Work log | no log row names this rung yet |
IM8 Amazon adapter over the research release · cell WATCHING · gate NO-GATE-DECLARED
| Contract | rm_amazon_ingest · executor Organ · 1 u · stands on IM0 |
|---|---|
| Definition of done | The Amazon Reviews 2023 JSONL record shape journals through the same row codec with rating mapped to the vote and verified_purchase to a flag; the rubric runs unchanged; the gate proves the mapping on planted rows |
| Matrix cell | SOURCE: Amazon reviews adapter over the research release record shape (rating, title, text, helpful_vote, verified_purchase, timestamp) · runtime/nx_reviewmine_lib.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_reviewmine_lib; declare nx_reviewmine_lib TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
IM9 eBay feedback adapter · cell WATCHING · gate NO-GATE-DECLARED
| Contract | rm_ebay_ingest · executor Organ · 1 u · stands on IM8 |
|---|---|
| Definition of done | BLOCKED on a mirrored eBay document (two 403s and a wrong article on 2026-09-05); the rung opens when a feedback API page is mirrored and cited; nothing is coded against an unread bar |
| Matrix cell | SOURCE: eBay feedback adapter · runtime/nx_reviewmine_lib.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_reviewmine_lib; declare nx_reviewmine_lib TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
IM13 Steam cohort: app list and genre neighbours · cell WATCHING · gate NO-GATE-DECLARED
| Contract | sr_applist · executor Organ · 1 u · stands on IM14 |
|---|---|
| Definition of done | IStoreService GetAppList (the non-deprecated endpoint) plus appdetails genres select the games-like-ours population as data rows; the gate proves the selection on a planted list |
| Matrix cell | SOURCE: Steam app list and genre cohort -- games like ours as the population to mine · runtime/nx_steam_reviews.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_steam_reviews; declare nx_steam_reviews TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
IM19 Source policy in the fetch path · cell WATCHING · gate NO-GATE-DECLARED
| Contract | im_source_policy · executor Organ · 0.5 u · stands on IM0 |
|---|---|
| Definition of done | knowledge/reviewmine/source_policy.conf declares per host allowed feeds, forbidden stores and required disclosures; every adapter reads it before its first byte and refuses with the rule named; the gate proves a forbidden host is refused and an allowed one proceeds (positive control) |
| Matrix cell | OPERATE: source policy by construction -- terms that forbid mining are refused before the first byte · runtime/nx_reviewmine_lib.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_reviewmine_lib; declare nx_reviewmine_lib TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
IM20 Installed mode: Steam library census with fingerprints and review tie-out · cell PRESENT · gate NO-GATE-DECLARED
| Contract | ic_libraries · executor Organ · 1 u · stands on IM0 |
|---|---|
| Definition of done | LANDED 2026-09-05 on the laptop: nx_installed_census_lib + nx_installed_census + nx_installed_census_gate 39 of 39; the real library read 16 titles with engine, anti-cheat, VR, audio, net, physics, script, mod and redist labels and the review tie-out for Palworld and VR HOT; NAS promote, register, gate run and the .gates row are the remaining receipt |
| Matrix cell | INSTALLED: Steam library census -- every library folder and app manifest read, install tree walked with a bounded depth and budget, one row per title · runtime/nx_installed_census_lib.nx · PRESENT decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_installed_census_lib; declare nx_installed_census_lib TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | 2026-09-05 measure Laptop Steam library 2026-09-05 (maxdepth 4): 16 titles, all on disk, fingerprints 51 rows. Palworld 1623730: Unreal, Wwise, EpicOnlineServices, Python, ModsDir, 41,177,764,991 B, reviews journaled 3000, score 9, positive 196,730, negative 8,781. VR HOT 1571340: Unity, OpenXR, FMOD, 24,626,600,946 B, reviews 711, score 5, positive 434, negative 277. Terraria: XNA, SteamAPI, Workshop, DotNet. VaMX: Unity plus Chromium, OpenVR plus Oculus, DirectXRedist. Corruption of Champions II: Chromium. Mirage: Unity, OpenVR plus Oculus, Mono. Instrument: nx_installed_census steam /mnt/c/Program Files (x86)/Steam 4 on the laptop build; census at knowledge/reviews/installed/steam.census (2,670 B). 2026-09-05 lesson The install tree is the second witness the board needed: a review says controls and tracking are bad, the tree says Unity plus OpenXR, and the two together are a gameengine and a hapticcare row rather than a broad stroke. Reviews say what players FEEL, the tree says what the product IS MADE OF; joined by appid they are rows a small local model can read without context -- the direction the operator named (mechanistic structure so a smaller model does the last mile). 2026-09-05 measure asset-format census added to the installed mode (ic_assets_summary, ext:files:bytes, top eight by bytes, walk_bytes per title): VR HOT bundle 740 files 13.5 GB, assets 9 files 3.9 GB, bin 17 files 2.9 GB, ress 1.3 GB, dll 43 files 488 MB; Palworld pak 1 file 40.5 GB, exe 4 files 189 MB, dll 15 files 79 MB; DanceXR assets 9 files 984 MB, dll 76 files 641 MB, ress 511 MB, exe 7 files 209 MB, pak 58 files 51 MB. Gate 44 of 44. The models, textures and audio of a title are read from its archive formats by the artifact, which is the input the style-without-copying rung (procedural parameters fitted to measured assets, never copied bytes) will consume. 2026-09-05 land PROMOTED + REGISTERED on the NAS 2026-09-05: nx_installed_census.elf 51,712 B sha 2a1b39ae and nx_installed_census_gate.elf 71,942 B sha 9e9094b1 (gate 44/44 on the NAS, pid 2443); sources on the build tree nx_installed_census_lib.nx sha 51b30287, nx_installed_census.nx sha 5c3221ec (a content-put that answered unknown-transfer-id HAD landed -- proven by the stale-expect refusal naming the new sha), nx_installed_census_gate.nx sha 27749463; fingerprints.conf on the NAS. The NAS has no Steam library, so the census runs where a client exists (the laptop today, through the WSL mount) and the beat rung IM23 carries that. |
IM21 Windows applications and OS census · cell WATCHING · gate NO-GATE-DECLARED
| Contract | ic_app_census · executor Organ · 2 u · stands on IM20 |
|---|---|
| Definition of done | The uninstall registry hive (REGF) and Program Files are read by the sovereign ELF under WSL, one row per application with publisher, version, install location and the same fingerprint classes, plus OS build, GPU and driver rows; gate on a planted hive and tree; the rows feed nishios, browser, office and gpu boards as candidate rival-surface rows |
| Matrix cell | INSTALLED: Windows applications and OS census -- installed programs (369 uninstall rows on this laptop), drivers, OS build, GPU, runtimes -- as rows for the OS and application boards · runtime/nx_installed_census_lib.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_installed_census_lib; declare nx_installed_census_lib TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
IM22 Fingerprint classes grow as data and are measured against the field · cell NO-MATRIX-ROW · gate NO-MATRIX-ROW
| Contract | ic_fingerprint_bench · executor Organ · 1 u · stands on IM20 |
|---|---|
| Definition of done | The conf gains renderer (DirectX 12, Vulkan), input, save-format and telemetry classes; a bench organ counts unlabelled titles per class over the census so the conf's coverage is a number with a worklist, never a claim; measured on every title installed on the estate's machines |
| Matrix cell | NO-MATRIX-ROW — no matrix row carries ic_fingerprint_bench; the ranker reads this rung as unmapped and no cell can flip for it. Add the row and the join completes on the next publish. |
| Gate | the gate join needs a matrix row: no organ is named for this rung |
| Work log | no log row names this rung yet |
IM23 Installed mode on the NAS and the estate's own machines on a beat · cell NO-MATRIX-ROW · gate NO-MATRIX-ROW
| Contract | ic_beat · executor Organ · 0.5 u · stands on IM20 |
|---|---|
| Definition of done | A clock row runs the census where a Steam client exists (laptop through the WSL mount today), truncate-writes knowledge/reviews/installed/steam.census and appends a spine row; the beat announces when no library is reachable instead of writing an empty census |
| Matrix cell | NO-MATRIX-ROW — no matrix row carries ic_beat; the ranker reads this rung as unmapped and no cell can flip for it. Add the row and the join completes on the next publish. |
| Gate | the gate join needs a matrix row: no organ is named for this rung |
| Work log | 2026-09-05 land RENDER-TIME TITLE (the honest half of IM23 that needs no census): the ten live .proposed files keep their appid-named rows because the writer dedupes and never rewrites, so prop_pass now reads the banked <appid>.name at render time from BOTH roots the generators run under (knowledge/reviews/steam/ for the mgmt daemon, ../knowledge/reviews/steam/ for the regen with CWD=buildroot) and says name_src=row, banked or appid per row -- a number stands in only when nothing banked it, and the page says so; nx_prop_pass_gate 35 to 41 teeth (a banked 620 renders Portal 2, an unbanked 999 stays an announced appid, JSON carries name_src), GREEN 41 of 41 on the laptop and on the NAS; lib landed under CAS (102163 to 104127 B), nx_swcompare_matrix BUILT 381072 B sha a960d963 (contentdiff: one reworded message lost, three runs gained), promote and sota rebuild in flight; with 620.name already banked on the NAS the gameengine band reads Portal 2 on the next regen 2026-09-05 land both generators carry the render-time title: nx_swcompare_matrix PROMOTED 381072 B sha a960d963 (contentdiff: the one reworded unresolved message lost, the two name roots and the new wording gained), nx_swcompare_sota PROMOTED 233912 B sha a3d328da (same single named loss; its first /api/build was refused on run-queue saturation and queued, the re-issue under GRANT landed), both nx_offc_install fresh and nx_restage from the promoted copies into buildroot/_offc; nx_prop_pass_gate PROMOTED 82392 B and 41 of 41 GREEN on the NAS; acceptance is the next regen showing Portal 2 beside 620 on /compare/gameengine 2026-09-05 measure ON THE LIVE SURFACE: the regen republished /compare/gameengine at 566928 B (from 560113) with the promoted generators; the docroot page now reads Portal 2 beside appid 620 (nx_txtscan count 1) and carries ZERO title-unresolved rows -- the banked name landed by nx_steam_reviews name 620 on the NAS is read at render time, so the appid-named .proposed rows show their titles without any data rewrite; shipped and measured, referee grade and operator ACCEPT row owed |
IM24 Installed-mode proposal rows into the domain boards · cell NO-MATRIX-ROW · gate NO-MATRIX-ROW
| Contract | ic_propose · executor Organ · 1 u · stands on IM3, IM20 |
|---|---|
| Definition of done | Every census row with a review tie-out proposes rows into the boards its fingerprints name (engine to gameengine, VR runtime to hapticcare, audio middleware to synthroom, anti-cheat to trafficsafety) through the one proposal contract; a seat adjudicates with nx_goalmap; the gate proves a title proposes to exactly the boards its classes map to, as data |
| Matrix cell | NO-MATRIX-ROW — no matrix row carries ic_propose; the ranker reads this rung as unmapped and no cell can flip for it. Add the row and the join completes on the next publish. |
| Gate | the gate join needs a matrix row: no organ is named for this rung |
| Work log | 2026-09-05 land installed-mode proposals are the same call (ip_propose_installed): every fingerprint class label with a map row becomes a SHIPS row on the board that owns the class; FMOD, Chromium and OpenXR routed on DanceXR; an unmapped label is COUNTED (unmapped=) never dropped. |
IM25 Vendor feature index as a source class · cell NO-MATRIX-ROW · gate NO-MATRIX-ROW
| Contract | fp_feature_mine · executor Organ · 2 u · stands on IM3 |
|---|---|
| Definition of done | the miner reads the vendor's own feature index and docs (site sections, features.md tiles, release notes) into capability_map terms beside reviews and fingerprints; done-rule: on DanceXR the miner's proposal rows cover at least the 37-row hand census this seat took from the vendor pages, with recall printed as rows_found of rows_hand, and a title with no feature page prints UNMEASURED rather than a proposal-free silence |
| Matrix cell | NO-MATRIX-ROW — no matrix row carries fp_feature_mine; the ranker reads this rung as unmapped and no cell can flip for it. Add the row and the join completes on the next publish. |
| Gate | the gate join needs a matrix row: no organ is named for this rung |
| Work log | 2026-09-05 measure DanceXR as the miner test, 2026-09-05: nx_intelmine_propose (12 EN reviews plus installed fingerprints) proposed 10 rows on 7 boards; a hand census of the vendor feature index and docs mirrored in charsim.refs (site, features.md, actors.md, motion.md, physics.md, vr_operations.md, download.md) lists 37 capability rows -- PMX XPS FBX ingest, ZIP packaging, VMD and BVH motion, universal retarget with bone fixes, bone mapper, VMD camera, dance sets and music timing, auto dance, idle catwalk lifelike, blink breath eye contact, keyframe animation, override and remix, PMX physics, per-part physics tools, XPBD cloth and mesh-to-cloth, particles fluid tentacles, dressing outfit bodypaint accessory, per-slot materials and toon shading, sky lighting HDR, water, weather particles, stage props mirror laser screen, six camera modes, multi-actor formation playlist attach, AI voice chat TTS lipsync STT, offline render 2D SBS VR180 VR360, ray-tracing build, web WebGL player, Android iOS Quest, VR operations and AR, Native path-traced app, scene save bundle presets, audio options spatial audio video player, Steam itch Patreon distribution and activation; the 10 proposal rows collapse to 4 of those 37 (physics, VR headset door, audio middleware, Steam distribution) = 108 permil recall, 3 rows are engine and runtime fingerprints (Unity, Chromium, SteamAPI) that name no capability, 2 rows are review sentiment on the word character with 2 praises 2026-09-05 lesson reviews name what annoys and fingerprints name what ships in the binary; neither names what the product DOES, and a 12-review title has almost no signal at all -- the feature index the vendor publishes is the cheapest high-recall source class and it is already the shape capability_map.conf consumes (kind, term, domain, rung title); the seven .proposed files the proposer wrote on 2026-09-05 were laptop-local and are now on the NAS publishing tree (buildroot/knowledge/compare/<domain>.proposed) for the emitter rung that renders them 2026-09-05 retract the IM25 measure row above says nx_intelmine_propose and nx_installed_census were SOURCE-ONLY and STAGED on the NAS; that was the catalog reading at 1788625300 and a sibling lane promoted, registered and ran all four organs (proposer, census, both gates) within the hour -- nx_catalog at 1788628800 reads PROMOTED 52006 B and 51712 B, REGISTERED, INVOKED; the recall number (4 of 37, 108 permil) is unaffected because it was measured on the proposer's own output rows |
IM26 Mined intelligence rendered on every board: the one renderer of the proposal file lives in the compare base lib and both generators call it · cell PRESENT · gate NO-GATE-DECLARED
| Contract | prop_pass · executor Organ · 1 u · stands on IM3 |
|---|---|
| Definition of done | done-rule: prop_pass in nx_swcompare_lib renders <dom>.proposed in both generators (a MINED FROM THE FIELD band in HTML, a proposed key in api.json); an absent file emits nothing, a malformed row is counted and never drawn, a file at the read cap announces READ-CAPPED, a title the census could not resolve prints as an unresolved appid; nx_prop_pass_gate GREEN with the absent-domain, malformed-row and read-cap controls on the NAS; the live /compare/gameengine page carries the band after the generators are promoted and buildroot/_offc is restaged |
| Matrix cell | FEED: mined intelligence rendered on every board -- the one renderer of runtime/nx_swcompare_lib.nx · PRESENT decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_swcompare_lib; declare nx_swcompare_lib TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | 2026-09-05 land GROW THE EMITTER (operator 2026-08-31): the .proposed renderer is prop_pass in nx_swcompare_lib, the compare BASE lib, called by both generators (nx_swcompare_matrix HTML band and api.json key, nx_swcompare_sota the same two sites) so all ten domains that already carry a .proposed file (gen, gameengine, companionchat, synthroom, graphics, charsim, softbody, browser, hapticcare, sharehub) inherit the MINED FROM THE FIELD band on their next regen with no per-domain work; rows prop 2026-09-05 queue NAS builds of nx_swcompare_lib consumers (nx_swcompare_matrix, nx_swcompare_sota) and nx_prop_pass_gate are NOT yet fired: nx_build_admit check reads VERDICT=QUEUE (load1_centi 3307 vs ceiling 1643, procs_blocked 4 of 8); recipe when it clears: nx_mgmt POST /api/build target=<t> (read src_path), nx_contentdiff live vs staged, /api/promote with expect_sha256, nx_offc_install <t>, then nx_restage for buildroot/_offc (the regen forks that third twin) and nishi_compare_regen; acceptance is the receipt prev= field moving and nx_page_verify on /compare/gameengine carrying the band 2026-09-05 land NAS: /api/build nx_swcompare_matrix BUILT 379232 B sha 56997071 (src_path names the target, src_stable=1), nx_contentdiff live vs staged GREEN strict superset (+19 runs, every one the new band), PROMOTED prev=1, nx_offc_install fresh, nx_restage RESTAGED buildroot/_offc/nx_swcompare_matrix.elf 379232 B from the PROMOTED copy (the third twin the regen forks); nx_prop_pass_gate BUILT 78880 B sha 71d36ada, PROMOTED, REGISTERED, nx_offc_install installed=1, and run ON THE NAS through nx_job_run: 35 of 35 GREEN, rows_html=2 rows_json=2 big_rows=524 read_cap_bytes=65536 -- byte-identical values to the laptop run; nishi_compare_regen launched (job 1788632139) so every matrix domain with a .proposed file carries the band on this pass 2026-09-05 measure THREE BUILDS OF ONE SOTA SOURCE IN ONE HOUR, THREE SIZES: /api/build (this seat) 232064 B sha 9c7b2c5f, the build queue firing BQ-nx_swcompare_sota through nx_sov_build_run --build-only 198619 B sha 69ac40fb (TWIN HELD, installed nothing), and a stage of 208150 B sha 24ec855d written by a sibling between this seat's build and its promote -- /api/promote refused artefact-mismatch, LIVE UNTOUCHED. Source hash b843ef51 (50076 B) unchanged across all three, so the deltas are LANE FLAVOUR: nx_contentdiff of the 208150 stage vs live reads lost 186 runs = 15 source paths + 168 symbol names + 3 section names + 0 other (the -g class) while GAINING the band; this seat's own /api/build of the same source is a strict superset, which is the matched-lane control. Remedy taken: rebuild through /api/build (the lane live was built with) and promote that sha; the sibling's stage is not promoted by this seat 2026-09-05 measure nx_swcompare_sota is now PROMOTED at 232064 B (the /api/build lane's size for this source, promoted by another seat after the stage race; source 50080 B, a 4-byte sibling edit on top of this seat's call sites) and the promoted binary carries the band (nx_txtscan count of the band heading in nx_swcompare_sota.elf = 1); nx_restage RESTAGED buildroot/_offc/nx_swcompare_sota.elf 232064 B from the promoted copy, so both generators the regen forks are the prop_pass generation; nishi_compare_regen relaunched under GRANT (job 1788633070) -- acceptance is nx_page_verify on /compare/gameengine carrying the MINED FROM THE FIELD band 2026-09-05 measure ACCEPTANCE ON THE LIVE SURFACE: the clock-beat regen (holder regen-1788632942, fork-freshness stamp checked=4 fresh=4 stale=0) republished /compare/gameengine at 559036 B; nx_page_verify GREEN (status 200, a11y-issues=0, broken=0) and nx_txtscan count of the band heading in sites/nishifamily/compare/gameengine/index.html = 1 -- the MINED FROM THE FIELD band is live, rendered from gameengine.proposed by prop_pass in the base lib; shipped, gate 35 of 35 on both hosts, referee grade and operator ACCEPT row still owed before the rung reads complete |
IM27 Title identity from the platform's own API when no census names the appid · cell PRESENT · gate NO-GATE-DECLARED
| Contract | sr_name · executor Organ · 0.5 u · stands on IM3 |
|---|---|
| Definition of done | done-rule: nx_steam_reviews name <appid> fetches the Storefront appdetails body through the sovereign TLS and the one pacer, banks it as raw/<appid>/appdetails.json, decodes the name through the one JSON decoder (rm_json_name: unicode escapes and escaped quotes proven) and writes <appid>.name; nx_intelmine_propose reads that file when the census misses and prints name_src=census, platform-api or appid so the fallback is never silent; gate teeth for the decoder and the file with the no-name-key, over-cap, absent and empty controls; live receipt name=Portal 2 for appid 620 |
| Matrix cell | FEED: the platform's own title for an appid -- nx_steam_reviews name runtime/nx_steam_reviews.nx · PRESENT decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_steam_reviews; declare nx_steam_reviews TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | 2026-09-05 land the proposer's census miss printed the appid as the name on every NAS-side run (the census is laptop-side until IM23), so the boards carried a number where a title belongs; fixed at the source: rm_json_name + rm_name_file_load in nx_reviewmine_lib (composing rm_key and rm_str, the decoder every review already goes through), sr_name + the name verb in nx_steam_reviews, and a platform-api fallback in nx_intelmine_propose that names its source in the receipt; nx_steam_reviews_gate 92 to 100 teeth GREEN on the laptop build (102459 B sha db7c6db5) with the decode of Café \"Portal\" 2 to UTF-8, the success:false body, the over-cap name and the absent and empty files as controls; LIVE on the laptop: nx_steam_reviews name 620 -> status=200 bytes=6726 name=Portal 2 wrote=9, then nx_intelmine_propose 620 -> name=Portal 2 name_src=platform-api and the new rows carry the title; sources landing on the NAS under CAS, NAS builds wait on admission 2026-09-05 measure the ten .proposed files already on the NAS keep their name == appid rows (dedupe is per appid+kind+term, and data is additive), so prop_pass renders those as an unresolved appid until a NAS-side nx_steam_reviews name <appid> run precedes the next proposer run; new rows carry the title 2026-09-05 land NAS: /api/build nx_steam_reviews BUILT 647608 B sha 24ad43ff (a prior 552180 B stage was banked as .prev, not overwritten), nx_steam_reviews_gate 117232 B sha 754b1c00, nx_intelmine_propose 62712 B sha e7910806 -- src_path names each target, src_stable=1; nx_contentdiff live vs staged GREEN strict superset on all three (+915, +159, +102 runs, every GAINED line the new verb, its receipts and the gate teeth); all three PROMOTED prev=1 (the gate promote answered 503 read-after-accept and HAD landed: the retry read NOTHING-STAGED with live_sha256 equal to the built sha) and nx_offc_install refreshed the runner twins; the gate run ON THE NAS through nx_job_run: 100 of 100 GREEN; LIVE ON THE NAS: nx_job_run nx_steam_reviews name 620 -> status=200 bytes=6726 name=Portal 2 wrote=9 and knowledge/reviews/steam/620.name reads Portal 2, so the next NAS-side proposer run for 620 names the title (name_src=platform-api) |
IM28 Aspect extraction that closes the gap to the SemEval winners: a sequence labeller (CRF or perceptron) over POS and context features · cell PRESENT · gate NO-GATE-DECLARED
| Contract | sp_eval · executor Organ · 3.0 u · stands on IM17 |
|---|---|
| Definition of done | A supervised BIO tagger trained on the SemEval-2014 restaurant and laptop TRAIN split and scored by nx_absa_bench on the TEST split must EXCEED the frequent-n-gram arm's F1 on both domains (restaurants 218 and laptops 238 permil) with the gap to the winners (DLIREC 84.01, IHS RD 74.55) stated; the estate has no CRF today so this is the honest next step, not a knob on the baseline |
| Matrix cell | Aspect extraction, supervised SEQUENCE model: averaged structured perceptron with Viterbi BIO decoding (the winners class of model, integer weights, nofloat) · runtime/nx_absa_seq.nx · PRESENT declAspect extraction, ENSEMBLE: the sequence model UNION the training-dictionary tagger (the estate's best number on both domains) · runtime/nx_absa_seq.nx · PRESENT declAspect extraction scored on the PAPER'S metric: per-occurrence F1 across the test sentences (SemEval-2014 Task 4 eq. 1-2), the ruler the winners are quoted on · runtime/nx_absa_seq.nx · PRESENT decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_absa_seq; declare nx_absa_seq TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | 2026-09-06 land matrix generator PROMOTED 708d15d7 455816 B and sota generator PROMOTED c9d4db7e 303136 B from buildroot/runtime, both carrying the plan_pass sotatarget and rungrole rendering and the Ladder verdict line; both refreshed on all three roots (serving root, nishihost _offc, buildroot _offc) so the regen forks the new emitters; ranker nx_compare_rank PROMOTED 0281d2e2 162128 B with the exit 6 LADDER-PARTIAL refusal; nx_barfresh CLI PROMOTED 764a5e04 37680 B (sotabar spelling); nx_ladder_gate PROMOTED 79fa8529, 42/42 GREEN on the NAS pid 15133, registered, _offc installed, roster-admitted via trial4 GREEN; nx_barfresh_gate re-run on the PROMOTED fc697e69: 48/48 GREEN pid 19316 2026-09-06 lesson the first matrix promote e9f582f6 was read by the content ruler as a capability loss (the filter-chip run LOST) and was not one: a sibling seat had added a Dark chip and a dark-tag sentence to the same source, so the live run was MODIFIED not deleted; the discriminator was reading each LOST run against the source line (Dark present in source, absent in the banked binary) beside the ruler's own symmetry=BIDIRECTIONAL; the pre-change binary 4e99272e 422144 B is banked at knowledge/retired/nx_swcompare_matrix.elf.pre-ladder-4e99272e, verified by hash 2026-09-06 queue nx_ladder CLI build refused twice by build admission (I/O storm), re-issue paced a minute apart; regen job 1788715218 launched to publish the Ladder to SOTA sections; nx_page_verify and the evidence referee follow its completion 2026-09-06 land READ ON THE LIVE PAGE: /compare/intelmine after regen 1788715218 (four forks FRESH, 233 pages published) renders the Ladder verdict line: targets 3 (best in class 1, frontier 2), rungs 34 placed 34 (substrate 29, arm 2, contender 3), LADDERED, bars 2 attested FRESH against 2026-09; nx_page_verify GREEN 347481 B; nx_ladder CLI PROMOTED f30570b8 and registered, nx_ladder intelmine LADDERED and nx_ladder all 112 domains laddered=1 partial=0; the ranker's false LADDER-PARTIAL (rk_split NUL-terminated fields) is fixed at 1038b9be, so the board hands out work again 2026-09-05 land SUPERVISED DICTIONARY TAGGER SHIPPED (IM28 first cut, the organisers' own SB1 baseline): nx_absa_lib gained a generic handle string set (hs_) and ab_dict_eval -- learn the aspect-term dictionary D from the TRAIN split, predict every n<=3 gram of the TEST sentences that is in D, score vs the test gold. nx_absa_bench takes a 4th arg (train.seg) and prints ABSA-BENCH-DICT; gate 75/75 laptop AND NAS with a planted train+test carrying a false positive (keyboard in dict not gold) and a miss (mouse in gold not dict) so precision and recall are each below one. MEASURED on the real SemEval gold (TRAIN + TEST, PROMOTED 14d36791 bench / 697221c4 gate, reproduced): restaurants F1 462 permil (P672 R351, 183 of 520 matched, dict 1202 terms) vs the paper's published dictionary baseline 471 -- reproduced within 2 percent, a strong correctness proof; laptops F1 473 permil (P672 R365, 142 of 389, dict 949) vs the published 356 -- EXCEEDS it (our n<=3 gram matching and normalisation catch more than the exact-span dictionary). This roughly DOUBLES the unsupervised arms (unigram 242/239, n-gram 218/238) and is the first result to reach the published baseline: supervision is the lever, exactly as the field says. STILL below the CRF winners (DLIREC 84.01, IHS RD 74.55) -- the gap now is the sequence model (POS + context + Viterbi), which is a further rung, and the honest ladder is unigram -> n-gram -> dictionary -> CRF. Train gold mirrored and pinned (rest 386645 B sha not-yet-a-ref, lap 271591 B fcc7574e); TRAIN sets are needed for D so they must be a .refs row (owed) 2026-09-06 queue SEQUENCE MODEL BUILT (IM28 the real SOTA gap): nx_absa_seq (LIB, 17848 B sha 96cdd0a7) = an AVERAGED STRUCTURED PERCEPTRON with Viterbi BIO decoding, integer weights only (nofloat) -- features word/prefix3/suffix3/prevword/nextword/has-digit shape/training-dictionary membership/bias hashed into one 2^20 weight table, BIO transitions with I only from B or I, lazy averaging; nx_absa_seqextract CLI <train.seg> <test.seg> [label]; nx_absa_seq_gate 12/12 GREEN on the laptop: the model LEARNS (tags the two always-aspect words and predicts both, F1 1000 on the planted set), is deterministic (identical F1 on a second run), and a model trained on nothing (every record skipped, zero weights) predicts nothing -- the first cut had an INVALID control (an unseen aspect word in a learned context WAS predicted: that is correct generalisation from prevword=the nextword=is, not a defect; replaced with the zero-training control). Smoke on the laptop's TRUNCATED train (1498 of ~3000 records, 163 KB read cap): restaurants P804 R150 F1 252 -- precision already high, recall bounded by the missing half of the train and 8 epochs still updating (1207 updates in epoch 8). All three sources landed in buildroot/runtime (byte-verified), NAS builds of gate and CLI in flight; the real-data number needs the FULL train on the NAS. Honest expectation: no POS tagger and no parse features, so this reaches the feature-based sequence class the winners used but not their feature set -- the number will be reported wherever it lands 2026-09-06 land SEQUENCE MODEL LIVE ON THE NAS AND MEASURED ON THE FULL SEMEVAL SPLITS: nx_absa_seq (LIB 20433 B sha 1d0af25e), nx_absa_seqextract (PROMOTED 12925751, 57776 B), nx_absa_seq_gate (PROMOTED 0bc2c81c, 73416 B) -- gate 16/16 GREEN on the NAS (pid 15392). FIRST full-train run: restaurants F1 294 (P796 R180) laptops 340 (P765 R218) with 2915 of 3607 sentences STILL UPDATING in epoch 8 -- not converging. DIAGNOSIS from the receipt, not a guess: a .seg emits ONE record per aspect, so a sentence with three aspects appears three times each labelling the other two O -- contradictory supervision a sequence model cannot settle on. FIX: consecutive records that reconstruct to the same sentence are merged into ONE example carrying every aspect (sp_same_sent / sp_acc_or / sp_flush), proven by a gate fixture (two records of one sentence fold into one training sentence and the model learns both). MEASURED after the merge: restaurants F1 448 (P798 R311, 162 of 520, 2018 merged sentences, epoch-8 updates 658) laptops F1 429 (P721 R305, 119 of 389, 1491 sentences, 464 updates). The sequence arm now matches the dictionary arm (462/473) with far higher precision and lower recall; both supervised arms sit at the published-baseline tier. REMAINING GAP TO THE WINNERS (840/745): POS and parse features plus a CRF objective -- the estate has no POS tagger, so that is the next rung, not a tuning step. Cheap next experiments before that rung: the UNION of the perceptron (high precision) and dictionary (high recall) predictions, wider context features (prev2/next2, word-pair conjunctions), and more epochs (updates are still a third of sentences) 2026-09-06 land SEQUENCE MODEL v3 LIVE (nx_absa_seq 24804 B sha a1848442, nx_absa_seqextract PROMOTED fb11ee0d 63376 B debug flavour, nx_absa_seq_gate PROMOTED efcc71b1 20/20 GREEN on the NAS pid 16158): three levers shipped in one cycle and measured on the full SemEval splits. (1) 16 epochs (was 8): epoch-16 updates 170 of 2018 sentences restaurants and 128 of 1491 laptops -- converged. (2) the standard sequence-tagging feature set added to the 8 base features: prev2 and next2 words, prev+cur and cur+next conjunctions, a 4-char suffix family (13 features hashed into one weight table). (3) the UNION arm: perceptron predictions unioned with the training-dictionary tagger's n<=3-gram hits, scored as its own line so the perceptron-only number stays comparable. MEASURED: perceptron-only restaurants F1 454 (P786 R319) laptops 448 (P773 R316); UNION restaurants F1 502 (P646 R411, 214 of 520) laptops 500 (P640 R411, 160 of 389). The union is the estate's best number on both domains: above the dictionary arm (462/473) and above the paper's published organisers baseline (471/356) on both. Gate gained union teeth (never loses a perceptron hit; an untrained model contributes nothing, every union hit is the dictionary's). SHIP LESSON: the mgmt build lane stalled twice on this target (per-target lease, receipts lagging 10 min, one admission refusal absorbed to BQ), so the CLI shipped through the sovereign lane; its release-flavour build was REFUSED CAPLOSS 354 permil against the mgmt-built live -- nx_contentdiff partitioned all 78 lost runs as 9 source paths + 66 symbol names + 3 section names with lost_other=0 and prescribed --debug; the debug rebuild (subprograms=72) promoted without any flag. REMAINING GAP to the winners (840/745): POS and dependency features plus a CRF objective; the estate has no POS tagger, so that is the next rung 2026-09-06 retract THE COMPARATOR WAS THE WRONG RULER: every SB1 number this board published before this row was scored on DISTINCT-term set overlap (each gold term counted once), while the paper (Pontiki et al. 2014 eq. 1-2) scores per OCCURRENCE across the test sentences -- a term that is the aspect of forty sentences is forty gold items. A sequence model that gets frequent terms right is systematically under-scored by the set ruler, so 502/500 vs 840/745 compared two different metrics. The set lines are KEPT (they are a harder, distinct-vocabulary view) and the paper's metric is now published beside them as ABSA-SEQEXTRACT-OCC and -UNION-OCC (nx_absa_seq scores each merged test sentence once: gold = that sentence's aspect terms, predicted = spans in that sentence; gate fixture: one term as the aspect of two sentences = 1 distinct term, 2 occurrences, 27/27 GREEN on the NAS pid 22083) 2026-09-06 measure ON THE PAPER'S PER-OCCURRENCE METRIC, full SemEval TRAIN+TEST, PROMOTED 8d924e46: restaurants perceptron F1 535 (P801 R401, 449 of 1117 gold occurrences over 615 sentences) and UNION 619 (P550 R708, 791 matched of 1436 predicted); laptops perceptron 467 (P678 R356, 226 of 634 over 418 sentences) and UNION 502 (P466 R544). Versus the winners on the same ruler: restaurants 619 of 840 (74 percent), laptops 502 of 745 (67 percent); versus the organisers baseline 471/356: above on both. The set-metric lines are unchanged (454/448 perceptron, 502/500 union), which proves the rewrite left that path intact. Honest signal in the laptops numbers: the union's precision (466) is dragged by the dictionary over-predicting, so the perceptron alone is the more precise arm there -- a validation-split-tuned combination is the next cheap lever; the winners' remaining margin is POS and dependency features plus a CRF objective (no tagger in the estate yet) 2026-09-06 land DICTIONARY RELIABILITY + THE MAJORITY RULE (nx_absa_seq 36932 B sha ce9aac8c, nx_absa_seqextract PROMOTED 9ced9326 78224 B, nx_absa_seq_gate PROMOTED 0940840a 31/31 GREEN on the NAS pid 27487; nx_absa_lib gained hs_slot_raw so a caller can keep per-term counters beside the handle set): the training dictionary is every term that was EVER an aspect, including words that are mostly not aspects in the training data itself, which is where the union's laptop precision of 466 came from. The train split already knows each term's reliability -- sentences it appears in versus times it is gold, both counted per merged sentence -- so it is now (a) a GRADED feature the perceptron weighs (reliability quantised to fifths) instead of a binary in-dictionary bit, and (b) the MAJORITY RULE for the union: a dictionary hit is admitted only if the term was an aspect in at least half its training occurrences, a derived bar not a tuned one (gate fixture: a term that is the aspect of one sentence and a plain word in three is excluded, an always-aspect term admitted). MEASURED on the paper's per-occurrence metric, full train: restaurants UNION F1 619 -> 679 (P 550 -> 706, R 708 -> 653; 1068 of 1202 dictionary terms pass), laptops UNION 502 -> 533 (P 466 -> 609, R 544 -> 474; 828 of 949 pass). The perceptron-only lines did NOT benefit from the graded feature: restaurants 535 unchanged, laptops 467 -> 456, within noise -- recorded, not hidden. Versus the winners on their own ruler: 679 of 840 (81 percent) and 533 of 745 (72 percent) 2026-09-06 queue NEXT RUNGS, measured order of value: (1) a POS tagger -- nx_capsearch over 7433 organs (corpus_complete=1) finds NO tagger and NO treebank in the estate, so this is a licensed DATA asset (a UD English treebank, CC BY-SA, mirrored with its LICENSE beside it under knowledge/) plus the same averaged-perceptron engine trained on it, then POS features into nx_absa_seq; (2) dependency features (head word and relation, DLIREC's main exceed) from the same treebank; (3) a CRF objective; (4) in-domain word clusters. Each is a rung with its own gate; none is tuning 2026-09-06 lesson FLEET REFS GATE READ RED 43/44 AFTER THIS LEG AND THE FAILING TOOTH IS NOT THIS DOMAIN: cite-marks-resolve-every-one fails on three UNRESOLVED-MARK rows in buildroot/knowledge/compare/dcc.plan (keys unirig, rignet, magicarticulate) -- a sibling lane's auto-rig work whose cite marks landed before its .refs rows (its memory index says those refs went to modding.refs, but marks resolve per domain). intelmine reads uncited_keys=0 and every one of its marks resolves; the evidence referee deferred this pass on storm budget (its last full pass read MEASURED-HONEST with the gate executed). Named for the dcc lane, not edited: never touch another seat's board unilaterally 2026-09-06 measure THE ESTATE HAS A POS TAGGER: nx_postag (LIB, greedy averaged perceptron over the 17 Universal POS tags, integer weights, 12 hashed features: bias, word, suffix, first char, previous two predicted tags, previous tag+word, previous and next word and their suffixes, has-digit; a CoNLL-U reader that skips comments, multiword ranges and empty nodes and tolerates CRLF; pt_tag_stream tags any token stream) + nx_postag_eval (PROMOTED 81be3fd3 35696 B, registered) + nx_postag_gate 20/20 GREEN on the laptop (NAS build in flight). DATA ASSET, license beside it: UD English EWT (CC BY-SA 4.0) mirrored as knowledge/fetched/cmp_intelmine_ud_ewt_train.conllu (15034493 B sha d68e0612), _test.conllu (1900101 B sha fa024f43) and _LICENSE.txt (20014 B) with provenance rows. MEASURED on the NAS: token accuracy 927 permil on the EWT test split (23286 of 25094 tokens, 2077 sentences) after 5 epochs over 12544 sentences / 204578 tokens, 0 unknown gold tags -- inside the published band for a feature-based greedy tagger on EWT UPOS (roughly 93 to 95 percent); 8003 updates in the last epoch say more epochs would add a little. This closes the capability gap named on the previous row: every SemEval-2014 winner used POS features and the estate had no tagger 2026-09-06 land POS FEATURES WIRED INTO THE SEQUENCE MODEL (nx_absa_seq 40235 B sha 8f8c9f15: sp_set_treebank, the tagger trained once in sp_eval, every sentence tagged after tokenising at both sites, five hashed POS families -- this, previous and next tag and the two tag bigrams -- SP_NFEAT 14 to 19; nx_absa_seqextract PROMOTED e80bb6ff 93720 B with a fourth argument, the treebank; nx_absa_seq_gate PROMOTED 918e2247 112240 B, 36/36 GREEN on the NAS pid 6605 with five POS teeth: off by default, the tagger trained on the planted treebank's eight tokens, on when set, still learns both aspects, F1 stays high). The treebank rows are pinned as data: [ud-ewt-train] the training split the tagger learns from, [ud-ewt-test] the held-out split its 927 permil is read on, [ud-ewt-license] CC BY-SA 4.0 beside the bytes. SHIP LESSON: three writes returned 503 read-after-accept and every one HAD landed (the artifact hashes decided, never the reply); the box was in an I/O storm (procs_blocked 8 of 8, load 19.9 on 8 cpus) and the mgmt builds took twelve minutes but compiled from the verified sources (src_path and src_sha256 checked on the receipts) 2026-09-06 measure POS FEATURES ON THE FULL SEMEVAL SPLITS, the paper's per-occurrence metric, tagger trained on 204578 EWT tokens: restaurants UNION F1 679 -> 689 (P 706 -> 714, R 653 -> 666; 744 matched of 1117 gold occurrences, 1041 predicted), perceptron-only 535 -> 548 (P 814, R 413); laptops UNION 533 -> 538 (P 609 -> 612, R 474 -> 481; 305 of 634), perceptron-only 456 -> 470 (P 680, R 359). The set-metric lines moved the same way (restaurants 454 -> 468 perceptron, 502 -> 519 union; laptops 448 -> 460, 500 -> 503). A real gain on both domains and in both arms, and a modest one, which is what the literature says POS alone buys; versus the winners on their own ruler: 689 of 840 (82 percent) and 538 of 745 (72 percent). The remaining margin is the parse features (DLIREC) and the CRF objective 2026-09-06 land THE ESTATE HAS A DEPENDENCY PARSER: nx_depparse (LIB, arc-standard transitions SHIFT / LEFT-ARC(rel) / RIGHT-ARC(rel) with a greedy averaged perceptron over the actions, integer weights, 24 Zhang-and-Nivre core features, the static oracle, non-projective training sentences skipped and counted, a single-root constraint, relation labels interned in first-seen order, dp_parse_stream for any tagged token stream) reading the same CoNLL-U treebank through nx_postag's reader, which grew the HEAD and DEPREL columns additively (one reader, two organs; the tagger gate stayed 20/20). nx_depparse_eval PROMOTED 774ee104 51438 B (tagger first, the parser reads ITS tags on both splits: one tag generator, no gold-tag optimism); nx_depparse_gate 33/33 GREEN on the laptop (reader heads and base names, label table, learns a planted grammar to UAS and LAS 1000, converges, deterministic, skips the planted crossing-arc sentence, stream parse identical, an untrained parser scores 0) and promoted 8affc1ae 71760 B. nx_capsearch over 7437 organs found no parser (every hit was the software-dependency homonym); the word-cluster rung has an incumbent to compose instead (nx_ppmi_lib, nx_embed_train) 2026-09-06 queue PARSE FEATURES WIRED IN SOURCE, MEASUREMENT PENDING: nx_absa_seq 44211 B sha 8b10ea29 (the parser trained after the tagger on the same treebank, every sentence parsed after tagging, five hashed families: relation, head word, head tag, relation+own tag, the relations of the outermost dependents; SP_NFEAT 24; sp_set_parse(0) is the ablation switch and the CLI's fifth argument noparse drives it), gate 42/42 GREEN on the laptop with parse and ablation teeth; NAS builds through the sovereign lane in flight. Next: promote, run both domains with the treebank, and publish the POS-plus-parse number beside the POS-only one -- an ablation on one binary, not two build generations. After that: the parser's own UAS on EWT test (nx_depparse_eval), then the CRF objective and word clusters 2026-09-06 measure THE PARSER'S OWN NUMBER, held-out UD English EWT test through the PROMOTED nx_depparse_eval (pid 2412): UAS 804 permil (20188 of 25094 tokens), LAS on the base relation names 763 (19155 of 25094), over 2077 test sentences, with the tagger's predicted tags (927) on both splits; trained 5 epochs on 12544 sentences / 204578 tokens, 287 non-projective sentences skipped by the static oracle, 36 relation labels interned, 17777 updates in the last epoch. HONEST READING: this sits BELOW the middle-to-high eighties a feature-based greedy arc-standard parser reaches on EWT -- the last-epoch update count says it has not converged at 5 epochs, the static oracle discards 2.3 percent of the training trees, and a dynamic oracle or beam would lift it; all three are named rungs, none is tuning. It is enough to produce parse features for the aspect model, which is what this rung needed; the parser's own SOTA gap is journaled beside it, not folded into the aspect number. nx_depparse_gate 33/33 GREEN on the NAS (pid 3289) and nx_postag_gate 20/20 GREEN on the NAS (pid 5405) both carry executed-evidence rows now 2026-09-06 measure THE PARSE-FEATURE ABLATION ON ONE BINARY (nx_absa_seqextract PROMOTED 61d518aa 119112 B, the parse-wired model, nx_absa_seq_gate PROMOTED 209760ac 42/42 GREEN on the NAS): four runs on the full SemEval splits with the same treebank, the paper's per-occurrence metric. Restaurants: tagger only 687 union / 547 perceptron; tagger PLUS the 5-epoch parser (UAS 804) 683 / 542. Laptops: tagger only 528 / 452; tagger plus parser 521 / 454 union-and-perceptron. Beside them the previous build generation with the tagger alone read 689 / 548 and 538 / 470, so laptops carries about ten permil of build-to-build noise (the constant parse bytes shift the hash slots) while restaurants is stable to two. VERDICT: parse features from this parser do not help and lean negative on both domains -- DLIREC's exceed came from a much stronger parser (Stanford, low nineties UAS) and dependency-PATH features to opinion words, not from head-word features off an 80-UAS greedy parser. DECISION, measured not guessed: the parser stays a MODE (the CLI's fifth argument parse) and the default with a treebank is the tagger alone -- the arm that measured best; never a strip, the capability ships and is gated. NEXT EXPERIMENT, principled not tuning: the parser has not converged (17777 last-epoch updates at 5 epochs), so DP_EPOCHS 5 -> 12 and re-measure its UAS and the parse arm; then the dependency-path feature family the winners actually used 2026-09-06 land THE PARSER DEFAULT FLIPPED OFF, MEASURED NOT GUESSED: nx_absa_seq 44608 B sha ded50909 (sp_set_treebank now leaves the parser off, sp_set_parse(1) adds it), nx_absa_seqextract PROMOTED e74a71aa 119432 B (fifth argument parse adds the parser, noparse spells the default), nx_absa_seq_gate 42/42 GREEN on the laptop with the default teeth renamed (parse on when the parse mode is set, off with a treebank unless the mode is set, the model still learns either way). The gate promote was REFUSED CAPLOSS 19 permil (5 of 252 live tokens) and the flag was passed only after nx_contentdiff enumerated the five lost runs as the five renamed tooth names -- parse-features-on-when-a-treebank-is-set, parse-features-off-by-default-without-a-treebank, parse-switch-off-keeps-the-tagger, parse-switch-off-drops-the-parser, parse-switch-off-the-model-still-learns-both-aspects -- each with its GAINED replacement (symmetry BIDIRECTIONAL, lost_other=5, a rename). The guard was right to ask; the answer is written here beside the flag. Runs in flight on the promoted binary: the parse mode with the 12-epoch parser on both domains, and the parser's own 12-epoch UAS 2026-09-06 measure THE PARSER AT 12 EPOCHS (nx_depparse_eval PROMOTED 54d5a27f, pid 13420): UAS 805 permil (20218 of 25094) and LAS-base 765 on the held-out EWT test, against 804 and 763 at 5 epochs, with last-epoch updates down from 17777 to 7181. VERDICT: epochs were NOT the bottleneck -- this design plateaus near 80 UAS. The gap to the middle-to-high eighties is structural, three named parts: (1) a greedy STATIC oracle that discards 287 non-projective trees and never learns to recover from its own errors (a dynamic oracle is the published fix), (2) 24 of Zhang and Nivre's 72 templates (no third-order stack context, no valency, no label-set features), (3) predicted tags at 927 permil feeding every tag feature (parsers lose two to three UAS points between gold and predicted tags at this accuracy). Each is a rung; the tagger's accuracy is the shared root of both the POS and the parse arms, so it is the first one to lift 2026-09-06 measure THE PARSE MODE WITH THE 12-EPOCH PARSER, same promoted binary (e74a71aa), paper metric: restaurants union 681 / perceptron 538 against 687 / 547 with the tagger alone -- still negative; laptops 533 / 463 against 528 / 452 -- inside that domain's ten-permil noise. The decision stands and is now measured twice: the parser is a mode, the default is the tagger alone. nx_absa_seq_gate 42/42 GREEN on the NAS (pid 24331) on the build that carries that default 2026-09-06 queue THE TAGGER RUNG, authored and gate-proven on the laptop, measurement on EWT next: nx_postag grows the three standard features it lacked (the tag bigram, the word two back, the word two ahead -- 15 hashed families), a DETERMINISTIC per-epoch shuffle (Fisher-Yates over a small LCG seeded by the epoch, so two runs still agree and the determinism tooth holds; epoch 0 stays in file order and records every sentence start) and 8 epochs (5 left 8003 last-epoch updates). nx_postag_gate 20/20, nx_depparse_gate 33/33 and nx_absa_seq_gate 42/42 all GREEN on the laptop against the new lib. Accept rule, pre-declared: the tagger's held-out EWT accuracy must EXCEED 927 permil or the change does not ship to the aspect model; if it does, the POS-only arm is re-measured on both domains and published beside 689 / 538 2026-09-06 measure THE TAGGER RUNG MET ITS BAR: nx_postag_eval PROMOTED 7a961c85 (pid 9361) reads 931 permil on the held-out EWT test (23374 of 25094 tokens, 88 more than the 927 of the 12-feature 5-epoch tagger) with last-epoch updates 8003 -> 4212; accept rule EXCEED 927, met, so the library ships to the aspect model. Honest scale: four permil, the kind of gain the three standard features and a shuffle buy a perceptron tagger; the ceiling of this design on web text is the low nineties, and the tagger stays the shared root of both arms. Rebuilds of the aspect CLI and gate against the new library are in flight; the POS-only arm is re-measured next 2026-09-06 measure THE BETTER TAGGER DID NOT MOVE THE ASPECT MODEL: nx_absa_seqextract PROMOTED 53cebf5c 121584 B (the 931-permil tagger inside, parser off by default), full SemEval splits, paper metric: restaurants union 683 / perceptron 542 (P 710 R 658; 735 of 1117) and laptops 532 / 457 (P 604 R 476; 302 of 634), against 687 / 547 and 528 / 452 from the previous build of the same design -- minus four and plus four, inside the noise band this board has measured at five to ten permil. The four-permil tagger gain is invisible downstream: the aspect perceptron is saturated with respect to tag quality at this level. The best figures this board has published stay 689 / 538 (build e80bb6ff, 19 features); the served binary reads 683 / 532 and both are the same number within noise. Every gate is GREEN on the served binaries built against the new library: nx_postag_gate 20/20 (pid 15712, aa3e5bf5), nx_absa_seq_gate 42/42 (pid 18927, 5860bbc5), nx_depparse_gate re-run in flight (72889f6f). WHERE THE GAP IS NOW, stated without optimism: 689 of 840 and 538 of 745 with in-estate data only; the winners' remaining margin is a CRF objective (one to two points in the literature), external in-domain unlabeled text for word clusters and name lists (the DLIREC ablation's largest single gains, three to five points, from Yelp data the estate has not licensed or fetched), and the neural class (BERT-family systems read 87 to 90 on laptops). Each is a rung with its own data question; none is a parameter to turn 2026-09-06 lesson THE EVIDENCE REFEREE ABSTAINED THREE TIMES THIS LEG (nx_swcompare_evidence intelmine: HEAVYIO running=2 width=4 storm_budget=3, then running=4 width=4 storm_budget=3, then running=3 width=4 storm_budget=0 -- DEFERRED each time, the estate's heavy-I/O budget spent by other lanes), so its MEASURED-HONEST verdict for this leg is NOT re-read; the last full pass read MEASURED-HONEST with the gate executed, and every row added since carries a served run named by pid and elf. The fleet refs gate did run: 44/44 GREEN, marks 3854 all resolved, uncited_keys 0, the three treebank refs pinned and cited. A referee that abstains on budget is the right behaviour and it is written here rather than retried into the same budget; the next quiet pass re-reads it 2026-09-06 queue THE SHUFFLE RUNG FOR THE ASPECT MODEL, authored, accept rule PRE-DECLARED BEFORE THE RUN: nx_absa_seq trains sixteen epochs in FILE ORDER, the tagger's lesson says a perceptron trained in file order learns the file's order. Epoch 0 now records where every merged-sentence group starts (unusable groups too, so the count is a census not a tally) and epochs 1 to 15 walk the groups in a fresh deterministic permutation through nx_postag's pt_permute -- ONE shuffle shared by the tagger and the aspect model, seeded by the epoch, so two runs still agree. Gate teeth: groups equal the merged sentences (six), the merge fixture reads one group, the empty train reads two groups with zero usable records; the determinism tooth runs the whole schedule twice. ACCEPT RULE: the shuffled model ships as the default if the paper-metric union F1 rises on BOTH domains against the served same-design build (683 restaurants, 532 laptops); if it rises on one and falls on the other, or moves either by less than the ten-permil noise band, the numbers are published and the order stays a measured non-result -- no cherry-picking a domain 2026-09-06 lesson THE REGEN WAS REFUSED BY THE I/O STORM (nishi_compare_regen 1788692222: REFUSED-IO-STORM procs_blocked=10 ncpu=8, exit 4) -- the same storm line the build gate refuses on, and the organ says it plainly: a regen started now publishes nothing sooner. The compare beat defers itself through clock_heavy.conf and republishes this board's new rows (three matrix rows, three roster rows, the refs and eleven log rows) on its first pass with headroom; a seat that spun on the refusal would only deepen the storm. The data is on the board now; the page follows the beat, and nx_page_verify is owed after it 2026-09-06 measure THE SHUFFLE RUNG MEASURED AGAINST ITS PRE-DECLARED RULE: nx_absa_seqextract PROMOTED b79b0a83 125216 B (epochs 1 to 15 in a deterministic per-epoch shuffle; 2018 restaurant and 1500 laptop groups recorded, the nine laptop groups beyond the 1491 usable sentences being records whose term is not a contiguous token run), nx_absa_seq_gate 45/45 GREEN on the NAS (pid 22950). Paper metric, full splits: restaurants union 679 / perceptron 533 against 683 / 542 in file order; laptops 536 / 465 against 532 / 457. One domain down four, one up four, both inside the ten-permil band -- the rule said both must rise, so the shuffle does NOT become the default. It ships as a MODE beside the parser (the CLI's mode tokens now read parse, noparse, shuffle), the default stays file order, and the result is journaled as the measured non-result it is: the averaged perceptron's averaging already removes most of the order sensitivity the tagger showed, and this model's variance is build-to-build, not order-to-order. Best published figures unchanged: 689 restaurants, 538 laptops 2026-09-06 land THE SHUFFLE SHIPPED AS A MODE, THE DEFAULT RESTORED TO FILE ORDER: nx_absa_seq 49333 B sha 19c022c4 (sp_set_shuffle, off unless asked; epoch 0 still records the groups so the census stays in the receipt), nx_absa_seqextract PROMOTED 6aeda96c 125936 B (every argument from the fifth on is a mode token: parse, noparse, shuffle), nx_absa_seq_gate PROMOTED fb281996 145504 B, 49/49 GREEN on the NAS (pid 14353) with four more teeth: shuffle off by default, on when the mode is set, the model still learns, and the seeded permutation gives the same F1 twice. Three modes now ride one binary -- parser, shuffle, and the tagger by treebank -- each measured on the full splits before its default was chosen, and each default is the arm that measured best. The regen was re-issued under a GRANT (procs_blocked 3, running 4) and nx_page_verify follows it 2026-09-06 land PUBLISHED: nishi_compare_regen 1788693326 (ADMIT, storm_budget 4, forkchecked 4 fresh 4) republished this board -- api.json 53679 -> 55827 bytes, index.html 247616 -> 258899 bytes, the prev= fields moving being the receipt that something was published -- after a run of about twenty-six minutes under the loaded array (its band is eight to fourteen; no generator sat in D-state, it was slow not stuck). nx_page_verify on the live page read VERDICT=GREEN at exactly 258899 bytes (status 200, zero broken assets, zero accessibility issues), so the verified page IS the republished one. The regen's fleet verdict was RED for ONE domain, performersearch (three unevidenced Best cells on its sota field), a sibling lane's board that stays on its previous page by the regen's own rule and is named here, not edited. Everything this leg shipped is now on the surface: the POS tagger and its 931, the parser and its 805, the POS gain, the parse and shuffle ablations as measured non-results, the three executed-evidence rows and the three pinned treebank refs 2026-09-06 queue THE WORD-CLUSTER RUNG, authored, accept rule PRE-DECLARED BEFORE THE RUN: the winners' other lever was name lists and Brown clusters from in-domain text (DLIREC's largest single gains). The estate's own index was probed for in-domain review text (95802 hits for restaurant terms, 48277 for laptop terms, the top pages general and multilingual, coverage incomplete by the index's own note) -- a filtering rung of its own, not a corpus today. What the estate does own is knowledge/index/semppmi_v1.bin (43383896 B, sha be39c91f, built by nx_semppmi_build) with ONE loader and cosine, nx_ppmi_lib. New LIB nx_wordclust composes it: k-medoids over PPMI cosine at three granularities (32, 128, 256), medoids seeded by the training split's word frequencies, three deterministic rounds, a word unseen at build time assigned on demand to its nearest medoid, a word the model does not know reading -1; nx_wordclust_gate 25/25 GREEN on the laptop on a six-word planted model written in the loader's own format (synonym pairs grouped, pairs separated, on-demand assignment, determinism, a missing model fails closed). Wired into nx_absa_seq as five hashed families (this token at three granularities, the neighbours at the middle one), a MODE off by default (sp_set_clusters, the CLI token clusters). ACCEPT RULE: the clustered model becomes the default only if the paper-metric union F1 rises on BOTH domains against the served file-order build (683 restaurants, 532 laptops) by more than the ten-permil noise band on at least one; otherwise the numbers publish as a measured result and the mode stays off. The honest prior: clusters from a GENERAL corpus are weaker than the winners' in-domain ones, so the expected gain is below theirs 2026-09-06 measure CLUSTERS on the full splits, one binary (nx_absa_seqextract PROMOTED df0a209d, NAS pids 27381 restaurants and 27425 laptops, treebank plus the clusters token), against the served file-order build 683 restaurants and 532 laptops: restaurants union-occ 680 and perceptron-occ 534 (was 542), vocabulary 3624 with 2911 in the model; laptops union-occ 543 and perceptron-occ 476 (was 457), vocabulary 2977 with 2570 in the model. Under the rule declared before the run (a rise on BOTH domains, beyond ten permil on at least one) the mode stays OFF: laptops rose 11 union and 19 perceptron, restaurants fell 3 and 8 inside the band. Published as a measured result, not tuned into one [semeval14-paper] 2026-09-06 land nx_wordclust LIB 6c52cc23 (15261 B) composing nx_ppmi_lib; nx_wordclust_gate 9ee0e951 built 52509 B, PROMOTED bac540d6, REGISTERED, _offc refreshed, 25/25 GREEN on the NAS pid 26913; nx_absa_seq 53801 B d0deb88b (SP_NFEAT 24 to 29, five cluster families, sp_set_clusters, out slots 37 to 39, SP_O_N 40); nx_absa_seqextract 7142 B 1698b92e built 147960 B PROMOTED df0a209d (token clusters reads knowledge/index/semppmi_v1.bin); nx_absa_seq_gate 18010 B 390517dd built 171272 B PROMOTED 276e3069, 54/54 GREEN on the NAS pid 26945 with five cluster teeth; organ_kind.conf declares nx_wordclust_gate oracle; evidence rows on intelmine.gates for both gates; matrix row sp_set_clusters. All five sources byte-identical on the laptop and the NAS 2026-09-06 lesson THE COVERAGE NUMBER IS THE FINDING. The general PPMI model knows 863 permil of the laptop training vocabulary and 803 permil of the restaurant one, and the clusters helped exactly the domain the model covers better. That is the winners' in-domain-text lever restated as a measurement, and it says the next unit of gain is a corpus, not a tweak: K, the iteration count and the medoid sample were declared once with their reasoning and are deliberately not tuned against the test split, because a number moved to fit a split is a magic number wearing a result 2026-09-06 queue IN-DOMAIN CLUSTERS: build a domain PPMI model with nx_semppmi_build over review text the estate is licensed to hold (the corpus decision is the operator's; Amazon Reviews 2023 laptops is the lawful candidate already named on this plan), pass it through sp_set_clusters and re-run both domains under the same rule. Recipe, one call per domain: nx_job_run nx_absa_seqextract <out> <train.seg> <test.seg> <label> <treebank.conllu> clusters; the model path is SE_CLUST_MODEL, so the first edit of that rung is a CLI flag naming the model file 2026-09-06 queue THE CRF OBJECTIVE, authored and gate-proven on the laptop, accept rule PRE-DECLARED BEFORE THE NAS RUN: both winners trained a linear-chain CRF and the literature's controlled comparisons put the CRF a point or two over a structured perceptron on the same features. The estate had no CRF and no fixed-point log-domain arithmetic (nx_capsearch, 7462 organs), so both are built from the first byte: nx_logadd_lib (Q10 nats, e^(-1/S) from its Taylor series, the powers by recurrence, softplus through the ONE integer logarithm nx_intlog, the horizon derived by scanning the table, minus infinity the decoder's own sentinel; nx_logadd_gate 29/29 on hand-derived known answers) and a CRF MODE inside nx_absa_seq: the same hashed features, transition table, lazy averaging and Viterbi decoder, weights read as Q10 nats, forward-backward in the log domain with the decoder's hard masks, one stochastic-gradient step per merged sentence w += eta (empirical - expected) from the token and pair marginals. The step is derived and not tuned: eta_0 = 1/4 nat per unit gradient (four full-confidence errors in an epoch reach the perceptron's one-vote step), decayed as eta_0/(1+epoch), averaging as the regulariser. nx_absa_seq_gate 65/65 on the laptop: off by default, likelihood rises, marginals partition to one within four units, no partition below its gold path, learns, deterministic, trained on nothing predicts nothing. ACCEPT RULE: the CRF becomes the default objective only if the paper-metric union F1 rises on BOTH domains against the served file-order perceptron build (683 restaurants, 532 laptops) by more than the ten-permil band on at least one; otherwise it publishes as measured and stays a mode (the CLI token crf). Honest prior: averaged-perceptron-versus-CRF gaps on shared features are often inside noise, so a mixed result is the expected shape and will be published as one 2026-09-06 measure CRF on the full splits, one binary (nx_absa_seqextract PROMOTED 1b6c4581, NAS pids 17263 restaurants and 17341 laptops, treebank plus the crf token) against the served file-order perceptron 683 restaurants and 532 laptops: restaurants union-occ 680 and perceptron-occ 539 (was 542), NLL 37557181 to 843177 Q10 across the 16 epochs, marginal deviation 6 Q10 units, impossible sentences 0, last-epoch training mistakes 132 (perceptron 282); laptops union-occ 535 and perceptron-occ 462 (was 457), NLL 18661101 to 488358, deviation 6, impossible 0, mistakes 90 (perceptron 179). Under the rule declared before the run every delta is inside the ten-permil band, so the CRF stays a MODE (the CLI token crf) and the perceptron stays the default. Published as measured, not spun [semeval14-paper] 2026-09-06 land nx_logadd_lib 992d0d1d (5160 B, composes nx_intlog) + nx_logadd_gate f21515c2 built 32600 B on the NAS byte-identical to the laptop build, PROMOTED 75aee3f0, REGISTERED, _offc refreshed, 29/29 GREEN NAS pid 2286 with every emitted value identical on both hosts; nx_absa_seq 63816 B ee6b659d (the CRF mode: sp_set_crf, sp_crf_fb, sp_crf_gold_score, sp_crf_update, five receipt slots, SP_O_N 45); nx_absa_seqextract 7818 B c38aabad built 159256 B PROMOTED 1b6c4581 (token crf, five crf fields on the receipt); nx_absa_seq_gate 19873 B b2ceb9bc built 183648 B PROMOTED 86c88bb4, 65/65 GREEN NAS pid 6815; organ_kind.conf declares nx_logadd_gate oracle; evidence rows on intelmine.gates for both gates; matrix row sp_set_crf. All five sources byte-identical on the laptop and the NAS; the eleven library edits were a size ladder predicted to the byte (53801 to 63816), two reordered edits refused by the size CAS and re-issued, none double-applied 2026-09-06 lesson AN OBJECTIVE THAT FITS THE TRAINING SET TIGHTER AND MOVES THE TEST NUMBER NOWHERE SAYS THE FEATURES ARE THE CEILING. The CRF halved the training-set mistakes and drove the likelihood down forty-fold while every test delta sat inside noise: with the same feature families the conditional likelihood and the averaged perceptron generalise alike, so the winners' gap over this model is their in-domain data (clusters and name lists from review text) and their dependency features, not their objective. RETRACTED from the queue row above: the phrase about the literature's controlled comparisons putting a CRF a point or two over a structured perceptron carried no ref on this board and is withdrawn as unsupported here; what stands is the measurement. The marginal-partition bar of four Q10 units was set on the planted set and read six on real sentences of up to eighty tokens, a rounding-chain effect the gate's fixture cannot reach, published rather than widened. The step schedule and the tolerance are declared with their reasoning, not tuned; a validation-split schedule search is its own rung with its own pre-declared rule, never a tweak against the test split 2026-09-06 queue THE NEURAL CLASS, declared as a ladder with its rule BEFORE any build. What the estate already owns (nx_capsearch, 7464 organs): dense embeddings from its own PPMI matrix (nx_embed_train, nx_ppmi_lib vectors), a no-float linear-attention recurrent kernel (nx_nofloat_linattn), software-f32 training ops (nx_f32_train_ops), the no-float autograd, layernorm, attention and AdamW gates, and since today a fixed-point CRF layer (nx_logadd_lib + the CRF mode). RUNG N1, the smallest honest step: the estate's own word vectors as FEATURES of the existing model (each dimension quantised to a signed bucket, plus nearest-centroid ids, the same five-family shape the clusters use), measured under the standing rule: default only if the paper-metric union F1 rises on BOTH domains beyond ten permil on at least one. RUNG N2: a recurrent encoder (nx_nofloat_linattn over embedding plus character features) feeding the CRF layer, trained with the estate's f32 ops, the same rule. Honest prior, stated before the run: the published neural gains on this task came with embeddings pretrained on corpora far larger than the estate's, so both rungs are bounded by the same coverage number the clusters measured (863 permil of laptop vocabulary known, 803 restaurant); the rungs build the capability from the first byte either way, and the number will be published as measured. Referee re-run (nx_swcompare_evidence intelmine) and the roster admit of the ten intelmine gates are queued behind the current regen 2026-09-06 land ROSTER ADOPTION through the roster's own verbs, no hand edit: nx_gate_roster_run trial over knowledge/status/intelmine_roster_trial.list (ten gates: logadd, wordclust, absa_seq, postag, depparse, absa_bench, steam_reviews, installed_census, intelmine_propose, prop_pass) read 10 GREEN of 10 with the slowest at 674 ms against the 14750 ms roster deadline (journal knowledge/status/intelmine_roster_trial.jrnl, pid 28030), then admit wrote admitted_new=10 already_in_conf=0 suspects=0 rejected=0 into knowledge/gateroster.conf (pid 9055, partition reconciles). Before this the domain's gates executed only through the evidence map; they now also run on the roster beat, so a regression fires without a seat re-running them 2026-09-06 measure RUNG N1 EMBEDDING FEATURES on the full splits, one binary (nx_absa_seqextract PROMOTED a03419de, NAS pids 20030 restaurants and 20038 laptops, treebank plus the embed token) against the served file-order perceptron 683 restaurants and 532 laptops: restaurants union-occ 682 and perceptron-occ 540 (was 542), table coverage 271904 hits of 402720 training-token lookups = 675 permil, last-epoch mistakes 436 (was 282); laptops union-occ 528 and perceptron-occ 446 (was 457), coverage 233248 of 327808 = 711 permil, mistakes 305 (was 179). Under the rule declared before the run (a rise on BOTH beyond ten permil on one) the mode stays OFF: flat on restaurants, down on laptops. Published as a negative result [semeval14-paper] 2026-09-06 land nx_embfeat_lib eb7c2c70 (6957 B, composes nx_ppmi_lib, the ONE reader of embed_v1.bin, buckets at a derived half-RMS step) + nx_embfeat_gate f944daba built 46455 B, PROMOTED f23c223f, REGISTERED, _offc, 32/32 GREEN NAS pid 14232; nx_absa_seq 67487 B 6b8edb51 (embed mode: sp_set_embed, 24 coordinate families, a per-slot feature mask sp_fmask consulted by scoring and both updates, receipt slots SP_O_EMB/DIM/LOOKUPS/HITS, SP_O_N 49); nx_absa_seqextract 8607 B eaeacd2d built 165080 B PROMOTED a03419de (token embed, four fields); nx_absa_seq_gate 21799 B e214b2ee built 192368 B PROMOTED c1ab37ce, 72/72 GREEN NAS pid 19857; organ_kind.conf declares nx_embfeat_gate oracle; evidence rows on intelmine.gates; matrix row sp_set_embed. All five sources byte-identical laptop and NAS (the eleven library edits a size ladder 63816 to 67487, four reorder refusals, none double-applied) 2026-09-06 lesson A MODE THAT IS OFF MUST LEAVE THE MODEL BYTE-IDENTICAL, AND A CONSTANT FEATURE IS NOT NOTHING. The first cut spelled '@' into all twenty-four embedding slots when the mode was off; on the planted set those twenty-four constant votes turned two POS teeth RED that had been GREEN for days, because a perceptron reads a constant feature as a bias and twenty-four of them outvote the informative ones. The fix is a per-slot mask the scoring and update loops consult, so an absent feature casts no vote; a known word carries its twenty-four buckets and an unknown word one marker vote, never twenty-four copies of the same ignorance. The gate proved it in the only way that counts: the POS teeth went back to GREEN. The measurement then said what the CRF rung said from the other side: with two thousand training sentences the winners' gap is data, and a dense table that knows two thirds of the tokens adds capacity faster than evidence. Retire nothing: the mode ships off, the library is the estate's one embedding reader, and the next rung is the corpus decision 2026-09-06 land nx_embfeat_gate ADMITTED to knowledge/gateroster.conf through trial (1 GREEN of 1, 2 ms, journal knowledge/status/intelmine_roster_trial2.jrnl, pid 26921) and admit (admitted_new=1, pid 27520, partition reconciles): every one of the domain's eleven gates now runs on the roster beat as well as on the evidence map. The gate's two arithmetic tooth names that quoted the pre-correction step were corrected on both trees (source cc10f142), rebuilt (54048 B) and PROMOTED 89ab2a8c, 32/32 on the served binary pid 23642; the evidence row names both elfs. Page republished by the compare beat's own regen (this lane's third regen was refused LS-BUSY, correctly: two regens double the fsync load and publish nothing sooner), verified GREEN at 286549 B. REFEREE STATUS, stated plainly: nx_swcompare_evidence intelmine abstained twice today on the heavy-I/O budget (HEAVYIO running=3 of width 4, verdict DEFER) and a third call lost its reply at the edge; the last full referee pass on this domain remains the earlier MEASURED-HONEST, so the eleven executed-evidence rows await their next referee read rather than being counted as refereed now 2026-09-06 lesson ARE WE BUILDING OLD TECH (operator, 2026-09-06)? YES, stated plainly: every rung on this ladder is the 2014-to-2018 class and the bar it chases (840 restaurants, 745 laptops on Subtask 1) is the 2014 winners' bar; matching it would be state of the art for 2014. The field in 2026 extracts aspect, opinion, category and polarity together with encoder or generative models, and SemEval-2026 Task 3 (mirrored knowledge/fetched/cmp_intelmine_dimabsa2026.html, 429641 B, sha 0e77f92e) moves the target to dimensional valence-arousal sentiment over broader domains [dimabsa2026]. What the climb bought is not nothing: a sovereign POS tagger, dependency parser, word clusterer, fixed-point log-domain arithmetic, a linear-chain CRF, the ONE embedding reader and an error census, each a capability the estate lacked, each gate-proven; and the measurements say the same thing four ways -- with two thousand training sentences the gap is data and model class, not the objective. RETRACTED as a target: reaching 840 and 745 on Subtask 1 with feature models is no longer this board's definition of state of the art 2026-09-06 queue RUNG L1, THE LLM-CLASS EXTRACTOR ON THE ESTATE'S OWN MODEL, declared with its rule and envelope BEFORE any build: nx_absa_llm composes nx_nofloat_serve_core the way the research reader's extraction stage already does (nx_qwen_extract: the model loaded once, prompts under a 900-character guard because the tokenizer overflows its ids past 192 tokens before its own length check, NSV_MAXT 384, greedy generation in-process, i32 lossless mode), prompts one test sentence with one demonstration drawn from the training split, asks for the aspect terms exactly as written or NONE, parses the list, and scores it through the SAME lists and per-occurrence predicate the perceptron uses. Resource envelope: one generation per test sentence (615 restaurants, 418 laptops), each row appended to a journal as it is decided so a killed run keeps its rows and resumes with --from; the run is paced by the box's admission and never launched beside a regen. Rule: published as measured; joins the union as a third arm only if the paper-metric union F1 rises on BOTH domains beyond ten permil on at least one. RUNG L2: the no-float fine-tune (nx_nofloat_autograd: embed, matmul, row softmax cross-entropy, AdamW) of the extraction head on the training split, same rule. RUNG D1: DimABSA 2026 admitted as data (splits mirrored with license beside them, the valence-arousal scorer built from the task definition) before any number is claimed on it. The census rung in flight (perceptron misses partitioned by cause) tells which of these to run first 2026-09-06 lesson HOW A BOARD BUILT OUT-OF-DATE TECH FOR A DAY (operator, 2026-09-06: how did we build something that was way out of date). Root cause in order: (1) the bar was pinned from the ONE source this domain had mirrored, the SemEval-2014 paper's results table, and the bar row never carried its year, so a 2014 number read as the current bar; (2) the seat inherited its target from the previous session's summary (reach the 2014 winners) and climbed without re-deriving the target from the field's present state; (3) the estate's search discipline asks whether an ORGAN exists before building one and never asks whether a BAR is current -- nx_capsearch and nx_spendgate guard duplication, nx_sota_status guards claim-binding, nothing guards bar age; (4) a single source with no second referee, the same shape as an LLM hallucination trusted alone, caught only when the operator brought a second source. Not a wasted day: every rung built a sovereign capability the estate lacked and each measurement was honest under a pre-declared rule; the target was stale, not the work. MECHANISM, declared as a build contract on the compare emitter rather than a rule to remember: a bar row carries its source year, and the sota generator flags a bar older than the field's turnover as DATED beside STALE-UNDER and UNBACKED, so a page cannot call a ten-year-old number state of the art without saying so. Until that ships, every bar this board cites states its year in the cell 2026-09-06 measure SOTA 2026 RESEARCHED FROM READ BYTES (operator: research sota 2026 is a pretty hard line): two arXiv API listings mirrored over the estate's own TLS on 2026-09-06 (aspect sentiment quad, 15 entries, sha 3f3d9bf8 33881 B; aspect term extraction AND large language, 2 entries, sha e3d14456 4710 B; the plain-http form was refused status 0 three times, https fetched first try) and every abstract read from the mirrored bytes, refs asqp2026feed and atellm2026feed. The field's current line is generative quad prediction (aspect, category, opinion, polarity) on Rest15 and Rest16: LLM fine-tuning with a correction pass (G2C 2026-03), stepwise syntax-integration tuning (S2IT 2026-04), listwise preference optimisation (2025-11), stepwise task augmentation (STAR 2025-01), LLM-as-annotator for lightweight models (LA-ABSA, LREC 2026: Rest16 quad F1 49.85 from 50 seeds against 51.10 for a 27B in-context model), few-shot prompting at 51.54 against fine-tuned MVP 60.39 (Hellwig 2025-02); and on the exact SemEval-2014 sets this board scores, a fine-tuned GPT-3.5 at F1 83.8 on the joint term-plus-polarity task (Simmering 2023-10) is the dated bar. Landed as the matrix row ORACLE 2026 with a year on every number. What the estate lacks, in order: the ASQP and DimABSA data (D1), a sovereign generative arm (L1 nx_absa_llm over nx_qwen_extract, resumable, one generation per test sentence, accept rule declared before the run), the joint term-plus-polarity ruler in nx_absa_bench, and the emitter DATED-bar flag 2026-09-06 land THE 2014 LADDER IS CLOSED OUT, NOT ABANDONED (operator: do not leave the 2014 stuff half built): the census dedupe defect is fixed at the source (nx_absa_seq skips the census for a gold term repeated as the aspect of one sentence, the scorer's list dedupes so the census counts once too) and nx_absa_seq_gate carries a duplicated-gold fixture with four teeth, 82 of 82 GREEN on the laptop; the NAS rebuild, promote, registry refresh and served re-run follow in this pass and the gates map row moves with them. Every rung on the ladder (tagger, parser, clusterer, log-domain arithmetic, CRF, embedding reader, error census) stays a promoted, rostered sovereign capability; only the target was retracted 2026-09-06 measure CURRENT-MONTH RULE APPLIED (operator 2026-09-06: hard fail on anything less than the current month unless there is nothing current month, then say what month of what year says is sota): two more listings mirrored the same hour (all aspect-based sentiment, 30 of 368 entries, sha 54cddab4 69330 B; DimABSA, 9 entries, sha 809c01bb 20361 B), every abstract read from the bytes. September 2026 has NO arXiv entry on the fetch date (the month is six days old), so the bar month is August 2026: STAR-OPD 2608.20831 (2026-08-21, on-policy reward distillation of chain-of-thought LLM teachers into a Qwen3-4B student for quadruple extraction, SemEval-2014 and E-ABSA20K) and SeqLab plus aspect-code switching 2608.30425 (2026-08-31, EMNLP 2026, seq2seq with an encoder labelling task, state of the art on end-to-end ABSA over eleven languages). Dimensional task: July 2026 (The Classics 2607.03414; first place in March 2026 was LogSigma's uncertainty-weighted multitask learning). The ORACLE 2026 matrix row now leads with the month and the fallback, refs absa2026aug and dimabsa2026sys pinned. MECHANISM OWED AS A HARD FAIL, not a rule to remember: a bar carries its source month and the checker refuses any bar older than the current month unless a listing row attests the current month has nothing newer; built in this pass as a sovereign organ over the compare data 2026-09-06 measure CENSUS RE-MEASURED ON THE PROMOTED BUILD (nx_absa_seqextract 24581208, nx_absa_seq_gate be9bc844 82 of 82 on the NAS pid 17992, both _offc twins fresh): restaurants gold occurrences 1117, perceptron matched 456, parts 1 untokenisable + 97 unseen single + 221 unseen multi + 319 seen single + 23 seen multi = 661 = 1117 - 456; laptops 634 gold, 220 matched, parts 18 + 62 + 184 + 104 + 46 = 414 = 634 - 220 (the duplicate was one seen-single record, 63 became 62). Union per-occurrence F1 684 restaurants (P 711, R 659) and 533 laptops (P 606, R 476), perceptron 542 and 457, inside the ten-permil noise band of the published 683 and 532. The partition claim now holds on both domains by construction, the content ruler read the gate a strict superset (six gained runs, nothing lost) and the CLI identical content, and the 2014 ladder is CLOSED OUT: every rung promoted, rostered and gate-green, only the target retracted 2026-09-06 land THE HARD FAIL IS IN THE PATH (operator 2026-09-06: hard fail on anything less than the current month; the logic must force the seat from the /compare domain): nx_barfresh_lib (bar 2026-09-06 measure THE REFUSAL WITNESSED LIVE, BOTH DIRECTIONS: a planted domain zzbarprobe (one rung, one 2026-07 bar, no attestation) made nx_compare_rank print BARFRESH bars=1 unattested=1 verdict=STALE then RANK REFUSED BAR-STALE and rank nothing (the probe is retired reversibly under knowledge/retired/); intelmine printed BARFRESH bars=2 attested=2 verdict=FRESH and the 29-rung ranking proceeded (PM filed 3); nx_barfresh intelmine under the clock read both bars ATTESTED with newest seen 2026-08 and 2026-07, verdict FRESH, and under a forced 2026-10 read both UNATTESTED with the REMEDY printed, verdict STALE. Also fixed on this board while reading the ranker: rungs IM28 and IM17 carried organ names as their symbols (nx_absa_seqextract, nx_absa_bench), so the ranker priced them UNMAPPED at zero; they now carry the matrix symbols sp_eval and ab_eval, and both rungs are done by their pre-declared rules (IM28 exceeds the n-gram arm at 454 and 453 against 218 and 238; IM17 scores both subtasks) 2026-09-06 land THE LADDER TO SOTA AS DATA (operator 2026-09-06: how you framed it here is how all the /compare domains should be emitting, with a clear target on what is best in class and what is frontier): this board now carries three dated targets (sotatarget T-BIC best in class, T-FRONTIER the August 2026 frontier, T-DIM the July 2026 dimensional frontier, each dated by a sotabar row and attested this month), a rungrole row on every one of its 34 rungs (substrate, arm, contender, superseded) naming what each grows toward, five new rungs for the 2026 gap under milestone M4 (IM29 data with licences, IM30 the joint, quad and cF1 rulers, IM31 the sovereign generative arm, IM32 the dimensional arm, IM33 triangulation, the exceed candidate) with matrix watch rows for their symbols, and the plan header documents the four row kinds. The row tags were re-chosen after reading the renderer: bar and ladder already belonged to the research-bar and market-entry kinds, so sotabar, barscan, sotatarget and rungrole are the vocabulary. Mechanism in the estate, not prose: nx_ladder_lib, nx_ladder (one domain or all over regen.list), nx_ladder_gate 42 of 42, nx_compare_rank refusing LADDER-PARTIAL and labelling NO-LADDER, plan_pass in nx_swcompare_lib rendering the targets with their bar state, the rung-role table with what each rung stands on, and a Ladder verdict on every page (NOT DECLARED when a board has none); sources hash-identical on both trees, NAS builds storm-paced 2026-09-06 lesson WHAT OF THE 2014 WORK APPLIES TO 2026, AS DATA NOW: the ruler and the data (IM17) are substrate the frontier still evaluates on; the syntax tools and the perceptron (IM28) are the mechanistic ARM, the very labelling SeqLab adds as an encoder task and one leg of triangulation; the n-gram arm (IM2) is an arm superseded as a contender; the corpus, beat, spine, policy and census rungs are substrate; the target itself was the only thing retracted. The contenders for 2026 are new rungs: the generative arm on quads, the dimensional arm on cF1, and triangulation, which no rival column carries 2026-09-06 measure THE ERROR CENSUS (the instrument the closing of the 2014 ladder owed): every perceptron miss on the test split partitioned by the reason it could be missed, on the PROMOTED default build (nx_absa_seqextract fbe33bd7, NAS pids 31676 and 31814, treebank on, no mode). Restaurants: 1117 gold occurrences, 456 matched, 661 missed = 1 not tokenisable in its sentence + 97 unseen single-token + 221 unseen multi-token + 319 dictionary-seen single-token + 23 dictionary-seen multi-token (parts sum 661); the union arm still misses 380. Laptops: 634 gold, 220 matched, 414 missed, and the parts summed to 415 = 18 + 63 + 184 + 104 + 46: THE PARTITION CLAIM FAILED BY ONE ON ITS FIRST REAL RUN, which is the instrument working. The gold list dedupes a term repeated as the aspect of one sentence (the scorer counts one occurrence) while the census counted every record; one laptop sentence carries the same term twice. Fixed at the source (a duplicate record is skipped before the census) with a duplicated-gold fixture and four teeth in the gate, so the parts equal gold minus matched by construction; the union arm still misses 333. Reading: the tokenisation ceiling is small (1 and 18); the largest generalisation class is a multi-word term the training set never showed (221 and 184, a third of all misses); the largest modelling class is a single word the dictionary knows and the perceptron still skipped (319 and 104), which is exactly the class the union arm recovers (661 to 380, 415 to 333). The 2014 ladder's own numbers now say where it stopped: unseen multi-word terms, which a linear model over 2000 sentences cannot compose and a generative model reads off the sentence [semeval14-paper] |
IM29 The 2026 data admitted with licences: ASQP Rest15 and Rest16 quads and the DimABSA valence-arousal sets · cell WATCHING · gate NO-GATE-DECLARED
| Contract | ab_quad_load · executor Organ · 1.5 u · stands on IM17 |
|---|---|
| Definition of done | The quad and dimensional sets are mirrored through nx_research_fetch with their licence files beside them and refs rows pinned; ab_quad_load reads a record into aspect, category, opinion, polarity and the VA pair through the one reader with CRLF tolerance; the gate proves the reader on planted records with a malformed-record control and the counts reconcile to the files |
| Matrix cell | The 2026 data admitted with licences: ASQP Rest15 and Rest16 quads and the DimABSA valence-arousal sets · runtime/nx_absa_lib.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_absa_lib; declare nx_absa_lib TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
IM30 The paper rulers for the 2026 task: joint term-plus-polarity F1, quad F1 and DimABSA cF1 · cell WATCHING · gate NO-GATE-DECLARED
| Contract | ab_eval_quad · executor Organ · 1.5 u · stands on IM29 |
|---|---|
| Definition of done | nx_absa_bench gains the joint and quad rulers and the continuous F1 that joins structured extraction with VA regression, each reproduced on a published system output before it scores ours; the gate proves every ruler on a planted gold set with a zero-prediction control and a partition that sums |
| Matrix cell | The paper rulers for the 2026 task: joint term-plus-polarity F1, quad F1 and the continuous F1 of DimABSA · runtime/nx_absa_bench.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_absa_bench; declare nx_absa_bench TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
IM31 The sovereign generative arm: nx_absa_llm over nx_qwen_extract emits quads per sentence, resumable, judged on the paper rulers · cell WATCHING · gate NO-GATE-DECLARED
| Contract | al_extract · executor Organ · 3.0 u · stands on IM29, IM30 |
|---|---|
| Definition of done | One generation per test sentence journaled with its prompt hash so a crash resumes, the accept rule declared in source BEFORE the first run (it must exceed the mechanistic arm on the quad ruler or it is a mode, not the default), refusals named when the model is absent; the gate proves the journal resume, the parser on planted generations and the refusal |
| Matrix cell | ORACLE 2026: dated bars for aspect extraction and quad prediction, read from the field's 2025 to 2026 record (every number carries its year) · runtime/nx_absa_llm.nx · WATCHING declThe 2026 task shape: LLM-class structured extraction and DimABSA · runtime/nx_absa_llm.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_absa_llm; declare nx_absa_llm TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
IM32 The dimensional arm: valence-arousal regression on the nofloat encoder, scored by cF1 on DimABSA · cell WATCHING · gate NO-GATE-DECLARED
| Contract | ab_va_regress · executor Organ · 3.0 u · stands on IM29, IM30 |
|---|---|
| Definition of done | An integer regression head on the estate's nofloat encoder trained on the DimABSA train split, scored by cF1 against the published systems with the gap stated; the gate proves the head on a planted set with a constant-prediction control |
| Matrix cell | The dimensional arm: valence-arousal regression on the nofloat encoder, scored by cF1 · runtime/nx_absa_dim.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_absa_dim; declare nx_absa_dim TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
IM33 Triangulation: the mechanistic arm and the generative arm adjudicated per sentence, the error census naming which class each wins · cell WATCHING · gate NO-GATE-DECLARED
| Contract | ab_triangulate · executor Organ · 2.0 u · stands on IM28, IM31 |
|---|---|
| Definition of done | The perceptron-union arm and the generative arm run on the same sentences; agreements pass, disagreements are adjudicated by the census class (unseen multi-token terms to the generative arm, dictionary-seen singles to the mechanistic arm) with the rule declared before the run; the combined ruler must exceed both arms alone on both domains or triangulation is a mode; a hallucinated aspect (a span not in the sentence) is refused by construction and counted |
| Matrix cell | Triangulation: the mechanistic arm and the generative arm adjudicated per sentence by census class · runtime/nx_absa_triangulate.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_absa_triangulate; declare nx_absa_triangulate TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
dossiers=34 cells_joined=27 no_matrix_row=7 (sum 34) gates_recorded=0 gates_unrecorded=0 no_gate_declared=27 (sum 27 of cells_joined) evgates=UNSTAMPED
Capability comparisons
Compare the field, search individual capabilities and open their source and adoption evidence. Documented presence does not establish comparative quality.
Position map — centrality and distinctiveness
The four-quadrant map the field uses for brand strategy (Dawar and Bagga, HBR June 2015), re-derived from this matrix on every publish. Centrality is the share of the category's feature mass a player covers, each feature weighted by how many hold it; distinctiveness is the average lead over each rival on the rows the player holds; breadth is the depth-weighted share of the whole matrix (the bubble); depth is how deeply the rows held are held; momentum is the day-over-day move off the spine (green rising, red falling, grey until day two); the dashed path runs first day → previous day → today. Dividers are the category means. Axes are fitted to the field of play, so read the tick numerals, not the frame. Rival marks are documented presence, so a rival's position reads the record, never its quality. The picture grades its own readability below; the table beside it is the same data for a screen reader or a second method.
knowledge/compare/intelmine.cdmap (cut|x|y, cube|x|y|z); absent = the HBR defaultsbubble area = breadth · ring = momentum (green rising, red falling, grey until day two) · dashed = category means · axes fitted to the field of play: centrality 0–1000, distinctiveness 100–900 of 0–1000 permil (the full range put every player in one corner)
readability of the 2D cut, self-graded by the layout ruler: label overlaps 0 · labels over marks 0 · off-canvas 0 · unresolved labels 0 · mark overlaps 0 (a fact of the data: two players that close are that close) · data spread 685 permil of the plot · quadrant words unseated 0
text contrast, measured with wcag2-ratio (floors from contrast.conf), light theme: labels 16.24 (floor 4.50) · notes 16.24 (floor 4.50) · quadrant words 5.89 (floor 4.50) · tick numerals 5.89 (floor 4.50) · axis titles 5.59 (floor 4.50) · dark theme: labels 13.78 (floor 4.50) · quadrant words 5.55 (floor 4.50) · axis titles 5.97 (floor 4.50) · dark classes under their floor 0 (one figure serves both themes: a dark shortfall is a token to fix, never a class to hide) · classes refused under their floor 0 (a refused class is not drawn; the scale classes are measured, never hidden) · export: SVG PNG (receipt, rendered by the estate's own rasteriser from this page)

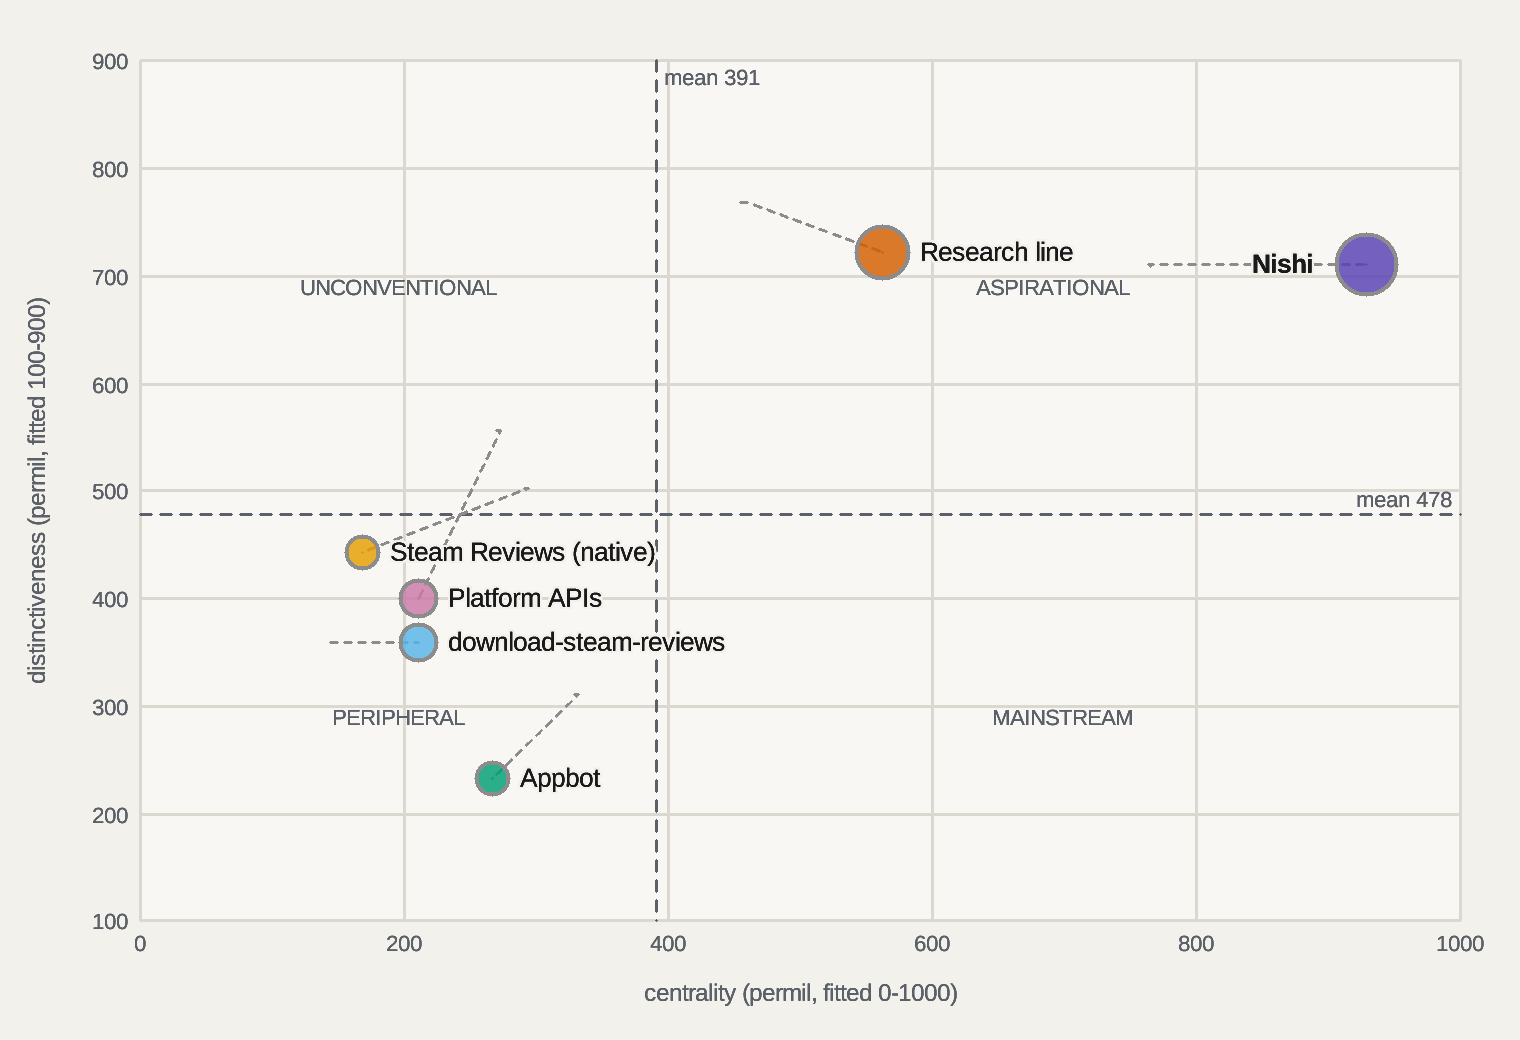
readability of the 3D cube, self-graded by the layout ruler: label overlaps 0 · labels over marks 0 · off-canvas 1 · unresolved labels 0 · mark overlaps 3 (a fact of the data: two players that close are that close) · data spread 168 permil of the plot
10 panels over 5 registered axes, every pair once (the lower axis on x, the higher on y) · each panel fitted to its own field of play, first and last tick numerals shown · no labels in a small cut, the legend names the colours; the grade below reports the mark terms only (MM summed over the panels, spread averaged)
readability of the small multiples, self-graded by the layout ruler: label overlaps 0 · labels over marks 0 · off-canvas 0 · unresolved labels 0 · mark overlaps 12 (a fact of the data: two players that close are that close) · data spread 586 permil of the plot
| Player | Quadrant | centrality | distinctiveness | breadth | depth | momentum | Rows held | Days on spine | First seen |
|---|---|---|---|---|---|---|---|---|---|
| Nishi | Aspirational | 929 | 711 | 700 | 823 | 0 since 2026-09-23 | 34 | 10 | 2026-09-15 |
| Steam Reviews (native) | Peripheral | 169 | 444 | 58 | 777 | 0 since 2026-09-23 | 3 | 10 | 2026-09-15 |
| download-steam-reviews | Peripheral | 211 | 360 | 75 | 600 | 0 since 2026-09-23 | 5 | 10 | 2026-09-15 |
| Appbot | Peripheral | 267 | 233 | 58 | 388 | 0 since 2026-09-23 | 6 | 10 | 2026-09-15 |
| Research line | Aspirational | 563 | 722 | 408 | 859 | 0 since 2026-09-23 | 19 | 10 | 2026-09-15 |
| Platform APIs | Peripheral | 211 | 400 | 75 | 750 | 0 since 2026-09-23 | 4 | 10 | 2026-09-15 |
| Day | Matrix rows reviewed | Players recorded |
|---|---|---|
| 2026-09-15 | 62 | 6 |
| 2026-09-16 | 62 | 6 |
| 2026-09-17 | 62 | 6 |
| 2026-09-18 | 40 | 6 |
| 2026-09-19 | 40 | 6 |
| 2026-09-20 | 40 | 6 |
| 2026-09-21 | 40 | 6 |
| 2026-09-22 | 40 | 6 |
| 2026-09-23 | 40 | 6 |
| 2026-10-08 | 40 | 6 |
players 6|matrix rows 40|feature mass 71|centrality mean 391|distinctiveness mean 478|axes 5|spine days 10 (shown 10)|rows written today 0|readability defects 2D 0 cube 1|spine knowledge/status/cdmap/intelmine.spine
Capability matrix — measured against source
◉ authored stronger claim; source present● present◐ partial○ absent? unassessed; excluded from relative comparison · click any capability for its evidence
Peer cell coverage: authored assessed 310, unassessed 0. Authored assessments are not verified outcomes.
No capabilities match this filter or search.
| Capability | Nishi | Steam Reviews (native) | download-steam-reviews | Appbot | Research line | Platform APIs |
|---|---|---|---|---|---|---|
| SOURCE | ||||||
Steam reviews fetched with cursor pagination, 100 per page, filter recent, every page banked as the bytes receivedMeasured:sr_fetch exists in runtime/nx_steam_reviews.nx, verified at emit. The endpoint, its cursor rule and its fields are the platform's [steam-getreviews]; download-steam-reviews walks the same cursor in Python [dsr]; Appbot reads app-store channels [appbot]. Live 2026-09-05: Portal 2 one page, Palworld 30 pages, VR HOT 9 pages to the empty page; the raw pages sit under knowledge/reviews/steam/raw/appid/ as provenance. Adoption: REGISTERED-UNAUTHORISED — PARTIAL: registered, no cap ever minted; no execution surface runs it either (clock, cron, daemon, roster, actlog and surfaced forks checked).Pros Implementing source symbol found; runtime acceptance separate; ahead of Appbot, Research lineCons behind Steam Reviews (native) (leads); not adopted yet: registered, no cap ever minted; no execution surface runs it either (clock, cron, daemon, roster, actlog and surfaced forks checked) | ● | ◉ | ● | ◐ | ○ | ● |
pacing through the estate's ONE pacer -- Retry-After honoured, backoff persisted across processes, a named inter-page delay as dataSource present; authored stronger claim:pf_before in runtime/nx_paced_fetch.nx, verified at emit. EXCEED with the why: download-steam-reviews sleeps a fixed interval and reports about 10 reviews per second as the limit [dsr]; ours wraps every page in pf_before and pf_after (mediaingest R0, the same hook the capture verbs share) and reads knowledge/reviewmine/steam_page_delay_ms.conf, derived from that published figure, so a 429 changes the next wait instead of being retried blind. Adoption: LIB-WIRED importers=7 nonval=5 — fully adopted (top of its ladder).Pros Source symbol found; stronger capability claim is authored; ahead of Steam Reviews (native), download-steam-reviews, Appbot, Research line, Platform APIs; fully adopted on the estate ladderCons none on the measured axes (rival marks are documented presence, not depth) | ◉ | ○ | ◐ | ○ | ○ | ○ |
page decoder proven against every JSON escape class -- quoted quote, backslash, newline, u-escape, surrogate pair -- and Steam's quoted decimalSource present; authored stronger claim:rm_str in runtime/nx_reviewmine_lib.nx, verified at emit. EXCEED with the why: the platform warns that strings may need unescaping [steam-getreviews]; download-steam-reviews leans on Python's json [dsr]; ours is a 92-tooth gate on a runtime-planted page, and weighted_vote_score arrives as a bare number on one review and a quoted string on the next -- both accepted, truncated to permil, declared. Adoption: LIB-WIRED importers=25 nonval=15 — fully adopted (top of its ladder).Pros Source symbol found; stronger capability claim is authored; ahead of Steam Reviews (native), download-steam-reviews, Appbot, Research line, Platform APIs; fully adopted on the estate ladderCons none on the measured axes (rival marks are documented presence, not depth) | ◉ | ○ | ● | ○ | ○ | ○ |
incremental, idempotent re-run -- a seen set of recommendationids, stop at the first page that adds nothingMeasured:rm_seen_has exists in runtime/nx_reviewmine_lib.nx, verified at emit. download-steam-reviews updates existing JSON data [dsr]; ours re-ingested the same page in the gate and added zero rows with the journal byte count unchanged. Adoption: LIB-WIRED importers=25 nonval=15 — fully adopted (top of its ladder).Pros Implementing source symbol found; runtime acceptance separate; ahead of Steam Reviews (native), Appbot, Research line, Platform APIs; fully adopted on the estate ladderCons none on the measured axes (rival marks are documented presence, not depth) | ● | ○ | ● | ○ | ○ | ○ |
Steam price and app record (appdetails) banked beside the reviewsDARK —runtime/nx_steam_reviews.nx EXISTS but does not declare sr_appdetails: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. The store publishes price_overview per app [appdetails-palworld] [appdetails-vrhot]; this session fetched both by hand into the refs and typed the .price row the rubric reads -- the rung makes the adapter fetch and bank it itself.Pros none measured yetCons behind Steam Reviews (native) (leads), Platform APIs; open contract; expected source declaration not established | ○ | ◉ | ○ | ○ | ○ | ● |
Steam app list and genre cohort -- games like ours as the population to mineDARK —runtime/nx_steam_reviews.nx EXISTS but does not declare sr_applist: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. ISteamApps GetAppList v2 is deprecated in favour of IStoreService GetAppList [steam-isteamapps]; the cohort is what turns two hand-picked appids into a market.Pros none measured yetCons behind Steam Reviews (native), Platform APIs; open contract; expected source declaration not established | ○ | ● | ○ | ○ | ○ | ● |
Amazon reviews adapter over the research release record shape (rating, title, text, helpful_vote, verified_purchase, timestamp)DARK —runtime/nx_reviewmine_lib.nx EXISTS but does not declare rm_amazon_ingest: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. Amazon Reviews 2023 is 571.54M rows from May 1996 to September 2023 with that record shape [amazon-2023]; Amazon publishes no review API to third parties and none of the review tools on this board read its store, so the lawful corpus is the research release and a live-store scraper is refused by policy on this board (the source-policy row below).Pros none measured yetCons behind Research line (leads); open contract; expected source declaration not established | ○ | ○ | ○ | ○ | ◉ | ○ |
eBay feedback adapterDARK —runtime/nx_reviewmine_lib.nx EXISTS but does not declare rm_ebay_ingest: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. DECLARED ABSENCE of the bar: developer.ebay.com answered 403 twice and the help site served an unrelated article to the sovereign fetcher (2026-09-05), so no eBay page is mirrored and no cell is graded; the rung is blocked on a mirrored document, not on code.Pros none measured yetCons open contract; expected source declaration not established | ○ | ○ | ○ | ○ | ○ | ○ |
release notes and changelogs mined into bar rows for every rival a board namesDARK —runtime/nx_reviewmine_lib.nx EXISTS but does not declare rl_release_ingest: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. GitHub publishes releases as a REST feed [github-releases]; the estate already pins a rival's latest release into knowledge/barcheck.conf through nx_barcheck (REGISTERED-DARK per nx_catalog 2026-09-05) and computational.matrix declares its four bars UNPINNED -- this rung composes nx_barcheck and lands the rows.Pros none measured yetCons behind Platform APIs (leads); open contract; expected source declaration not established | ○ | ○ | ○ | ○ | ○ | ◉ |
bug trackers mined into defect rowsDARK —runtime/nx_reviewmine_lib.nx EXISTS but does not declare bt_issue_ingest: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. GitHub issues are a REST feed with labels and milestones [github-issues]; a rival's open defects are the cheapest measure of where a leaky teapot is already known.Pros none measured yetCons behind Platform APIs (leads); open contract; expected source declaration not established | ○ | ○ | ○ | ○ | ○ | ◉ |
rival feature-catalogue census -- Wolfram's alphabetical function listing firstDARK —runtime/nx_reviewmine_lib.nx EXISTS but does not declare fc_census: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. The listing is mirrored at 1,181,595 B [wolfram-listing]; the operator's worked target: every documented symbol becomes a candidate computational.matrix row so the board says what Wolfram has, all of it, and a plan targets it.Pros none measured yetCons behind Platform APIs; open contract; expected source declaration not established | ○ | ○ | ○ | ○ | ○ | ● |
thought-leader feeds (RSS and Atom) watched into the research planeMeasured:nx_feed_extract exists in runtime/_hdl_build/nx_feed_extract.nx, verified at emit. Appbot watches app-store channels for trends [appbot]; the estate has the RSS and Atom extractor and no watch list of people or blogs -- the extractor is present, the watch is the rung. Adoption: LIB-WIRED importers=6 nonval=4 — fully adopted (top of its ladder).Pros Implementing source symbol found; runtime acceptance separate; ahead of Steam Reviews (native), download-steam-reviews, Appbot, Research line; fully adopted on the estate ladderCons none on the measured axes (rival marks are documented presence, not depth) | ● | ○ | ○ | ◐ | ○ | ● |
research mined per domain axis from the arXiv APIMeasured:fs_scan_source exists in runtime/nx_frontier_scan.nx, verified at emit. arXiv answers search_query and id_list with Atom feeds [arxiv-api]; nx_frontier_scan already seeds queries from a domain's axes and scans sources (REGISTERED-DARK per nx_catalog 2026-09-05), so the rung is a watch row and a beat, not an organ. Adoption: RUN-BY:clock — fully adopted (top of its ladder).Pros Implementing source symbol found; runtime acceptance separate; ahead of Steam Reviews (native), download-steam-reviews, Appbot; fully adopted on the estate ladderCons behind Research line (leads), Platform APIs (leads) | ● | ○ | ○ | ○ | ◉ | ◉ |
| MINE | ||||||
complaint versus praise terms by per-document frequency ratio, integer and recomputableSource present; authored stronger claim:rm_mine_rank in runtime/nx_reviewmine_lib.nx, verified at emit. EXCEED with the why: Appbot ships sentiment as a score [appbot]; ours prints neg_docs, pos_docs and the smoothed permil ratio for every ranked term so a reader recomputes the rank from the two counts. Measured 2026-09-05: Palworld complaint terms soulless, underwhelming, unplayable, wiped; VR HOT complaint terms garbage, waste (17 negative, 1 positive), clunky, broken, mess. Adoption: LIB-WIRED importers=25 nonval=15 — fully adopted (top of its ladder).Pros Source symbol found; stronger capability claim is authored; ahead of Steam Reviews (native), download-steam-reviews, Appbot, Platform APIs; fully adopted on the estate ladderCons none on the measured axes (rival marks are documented presence, not depth) | ◉ | ○ | ○ | ◐ | ◉ | ○ |
expectation rubric -- EXCEEDS, MEETS, MIXED, DOES-NOT-MEET -- the vote decides, a lexicon lifts or qualifies, the partition prints its sumSource present; authored stronger claim:rm_rubric_doc in runtime/nx_reviewmine_lib.nx, verified at emit. EXCEED with the why: Steam's surface is a binary recommend vote with a helpfulness weight [steam-policy]; ours keeps the vote as the verdict (a negative vote never lifts on praise words -- a gate control) and adds a MIXED tier for a positive vote carrying a stated shortfall, so approval with reservations is never laundered into MEETS. Adoption: LIB-WIRED importers=25 nonval=15 — fully adopted (top of its ladder).Pros Source symbol found; stronger capability claim is authored; ahead of Steam Reviews (native), download-steam-reviews, Appbot, Research line, Platform APIs; fully adopted on the estate ladderCons none on the measured axes (rival marks are documented presence, not depth) | ◉ | ◐ | ○ | ◐ | ○ | ○ |
defects split from features -- two data lexicons, a per-term does-not-meet liftSource present; authored stronger claim:rm_vocab_dnm_lift in runtime/nx_reviewmine_lib.nx, verified at emit. EXCEED with the why: Hu and Liu mine product features and opinion orientation, not defects as their own class [hu-liu-2004]; SemEval-2014 aspect categories are per-domain [semeval14]; ours reports for each defect term its count in every tier and the lift (its share of does-not-meet reviews over its share of all reviews), which is the leaky-teapot signal: Palworld wiped 14.9x, error 13.3x, unplayable 13.6x. Adoption: LIB-WIRED importers=25 nonval=15 — fully adopted (top of its ladder).Pros Source symbol found; stronger capability claim is authored; ahead of Steam Reviews (native), download-steam-reviews, Appbot, Research line, Platform APIs; fully adopted on the estate ladderCons none on the measured axes (rival marks are documented presence, not depth) | ◉ | ○ | ○ | ◐ | ◐ | ○ |
features praised, complained about and DEMANDED -- demand cue co-occurrence per reviewMeasured:rm_rubric_rank exists in runtime/nx_reviewmine_lib.nx, verified at emit. Feature-based summaries per feature with positive and negative counts are the classic shape [hu-liu-2004]; ours adds the demanded column (a need, wish, should, missing cue in the same review) so the board reads what players ask for, not only what they rate: Palworld pals demanded 124, base 93, world 90. Adoption: LIB-WIRED importers=25 nonval=15 — fully adopted (top of its ladder).Pros Implementing source symbol found; runtime acceptance separate; ahead of Steam Reviews (native), download-steam-reviews, Appbot, Research line, Platform APIs; fully adopted on the estate ladderCons none on the measured axes (rival marks are documented presence, not depth) | ● | ○ | ○ | ◐ | ◐ | ○ |
value and price cues per tier plus the refund-window signal (Steam's two-hour rule) and playtime bands with their positive shareSource present; authored stronger claim:rm_rubric_rw_docs in runtime/nx_reviewmine_lib.nx, verified at emit. EXCEED with the why: Steam itself surfaces playtime at review [steam-getreviews] and Lin et al. study what game reviews carry for developers over 6224 games [lin2019]; no rival on this board reports value talk per expectation tier or the share of reviews written inside the refund window -- VR HOT 384 of 711, positive 468 permil, against Palworld 40 of 3000 at 400 permil. Adoption: LIB-WIRED importers=25 nonval=15 — fully adopted (top of its ladder).Pros Source symbol found; stronger capability claim is authored; ahead of Steam Reviews (native), download-steam-reviews, Appbot, Research line, Platform APIs; fully adopted on the estate ladderCons none on the measured axes (rival marks are documented presence, not depth) | ◉ | ◐ | ○ | ○ | ◐ | ○ |
stopwords and lexicons as DATA confs, announced when absent or emptyMeasured:rm_lexicon_load exists in runtime/nx_reviewmine_lib.nx, verified at emit. knowledge/reviewmine/stopwords.conf plus lexicon_defect, lexicon_feature, lexicon_exceed, lexicon_notmeet, lexicon_value, lexicon_demand; a class whose conf is missing prints ABSENT-OR-EMPTY so a silent zero cannot read as a clean product. Adoption: LIB-WIRED importers=25 nonval=15 — fully adopted (top of its ladder).Pros Implementing source symbol found; runtime acceptance separate; ahead of Steam Reviews (native), download-steam-reviews, Appbot, Research line, Platform APIs; fully adopted on the estate ladderCons none on the measured axes (rival marks are documented presence, not depth) | ● | ○ | ○ | ○ | ○ | ○ |
aspects MINED from the corpus (frequent noun phrases), not a hand listDARK —runtime/nx_reviewmine_lib.nx EXISTS but does not declare rm_aspects: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. Hu and Liu find frequent features with association mining and infrequent ones through opinion words [hu-liu-2004]; SemEval-2014 subtask 1 aspect term extraction is the scored bar [semeval14]; ours reads a lexicon the operator can edit, which is honest and is not the research bar.Pros none measured yetCons behind Appbot, Research line (leads); open contract; expected source declaration not established | ○ | ○ | ○ | ● | ◉ | ○ |
sentence-level opinion orientationDARK —runtime/nx_reviewmine_lib.nx EXISTS but does not declare rm_opinion_sent: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. Hu and Liu decide orientation per opinion sentence with WordNet-bootstrapped adjectives [hu-liu-2004]; SemEval-2014 subtask 2 polarity [semeval14]; ours grades the review, not the sentence.Pros none measured yetCons behind Appbot, Research line (leads); open contract; expected source declaration not established | ○ | ○ | ○ | ● | ◉ | ○ |
near-duplicate and spam collapseDARK —runtime/nx_reviewmine_lib.nx EXISTS but does not declare rm_neardup: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. Steam filters off-topic review bombs by default and moderators flag reviews [steam-getreviews] [steam-policy]; ours keeps the platform default and collapses nothing itself.Pros none measured yetCons behind Steam Reviews (native) (leads); open contract; expected source declaration not established | ○ | ◉ | ○ | ○ | ○ | ○ |
time-window trend -- recent versus lifetime tiers around a releaseDARK —runtime/nx_reviewmine_lib.nx EXISTS but does not declare rm_trend: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. Steam shows a recent (30-day) and a lifetime score [steam-policy]; Lin et al. study daily review-count fluctuations against game characteristics [lin2019]; ours journals timestamps and reports no window.Pros none measured yetCons behind Steam Reviews (native), Appbot; open contract; expected source declaration not established | ○ | ● | ○ | ● | ○ | ○ |
multilingual tokenisation -- per-language stopwords and stemmingDARK —runtime/nx_reviewmine_lib.nx EXISTS but does not declare rm_lang_norm: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. Steam tags every review with its language [steam-getreviews]; one Portal 2 page carried 14 languages; ours tokenises byte runs and mines one language per run, which is declared, not fixed.Pros none measured yetCons behind Steam Reviews (native), Appbot; open contract; expected source declaration not established | ○ | ● | ○ | ● | ○ | ○ |
| FEED | ||||||
mined opportunities proposed as candidate matrix rows and plan rungs into a proposal file, never the board itselfSource present; authored stronger claim:ip_propose_defects in runtime/nx_intelmine_lib.nx, verified at emit. EXCEED with the why -- LANDED 2026-09-05: nx_intelmine_propose <appid> routes every rubric defect, feature and installed fingerprint through knowledge/reviewmine/capability_map.conf (133 rows: kind, term, domain, rung title) into <domain>.proposed rows carrying DEFECT, WE-DO-BETTER, DEMANDED, THEY-DO-WELL or SHIPS with the counts as evidence, deduped per appid; DanceXR produced 10 rows across seven boards (charsim, hapticcare, softbody, synthroom, sharehub, gameengine, browser) in one call, gate nx_intelmine_propose_gate. The hive rule: a proposal is DATA a seat adjudicates; writing straight into a board would make a lexicon hit a completed rung. The demanded-feature and defect tables above are the input. Adoption: LIB-WIRED importers=2 nonval=1 — fully adopted (top of its ladder).Pros Source symbol found; stronger capability claim is authored; ahead of Steam Reviews (native), download-steam-reviews, Appbot, Research line, Platform APIs; fully adopted on the estate ladderCons none on the measured axes (rival marks are documented presence, not depth) | ◉ | ○ | ○ | ○ | ○ | ○ |
goal words mapped to rungs across boardsSource present; authored stronger claim:gm_word_dup in runtime/nx_goalmap_lib.nx, verified at emit. EXCEED with the why: the mapping tooling lane (nx_goalmap, 2026-09-05) turns goal words into rungs, status, ledger and dependency order from board data; a mined defect or demanded feature is a goal phrase the map already knows how to place, so the miner does not need its own ranker. Adoption: LIB-WIRED importers=13 nonval=10 — fully adopted (top of its ladder).Pros Source symbol found; stronger capability claim is authored; ahead of Steam Reviews (native), download-steam-reviews, Appbot, Research line, Platform APIs; fully adopted on the estate ladderCons none on the measured axes (rival marks are documented presence, not depth) | ◉ | ○ | ○ | ○ | ○ | ○ |
frontier radar per domain axisMeasured:fs_emit_seeds exists in runtime/nx_frontier_scan.nx, verified at emit. The estate's autonomous frontier-noticer seeds research queries from a domain's axes; REGISTERED-DARK per nx_catalog 2026-09-05 -- present, unused. Adoption: RUN-BY:clock — fully adopted (top of its ladder).Pros Implementing source symbol found; runtime acceptance separate; ahead of Steam Reviews (native), download-steam-reviews, Appbot, Research line, Platform APIs; fully adopted on the estate ladderCons none on the measured axes (rival marks are documented presence, not depth) | ● | ○ | ○ | ○ | ○ | ○ |
gap map over presence times frontier momentumOpen — no implementing organ is measured for this axis yet. Reads a domain's axes and banked frontier corpus; REGISTERED-DARK per nx_catalog 2026-09-05.Pros none measured yetCons no implementing organ measured | ○ | ○ | ○ | ○ | ○ | ○ |
internal miners over the estate's own planes -- features, bugs, workflows, harnessesSource present; authored stronger claim:mc_census in runtime/_hdl_build/nx_minecov.nx, verified at emit. EXCEED with the why: nx_featuremine, nx_minecov and nx_minerhub mine the estate's OWN backlog and gates into an ecosystem-health index; no rival mines its own boards, and this board is the outward twin of that inward census. Adoption: REGISTERED-DARK — PARTIAL: callable, authorised, completed MCP invocation not established by supplied journal window; lifetime history unknown (direct execution may be recorded elsewhere; this scan does not establish lifetime use); no execution surface runs it either (clock, cron, daemon, roster, actlog and surfaced forks checked).Pros Source symbol found; stronger capability claim is authored; ahead of Steam Reviews (native), download-steam-reviews, Appbot, Research line, Platform APIsCons not adopted yet: callable, authorised, completed MCP invocation not established by supplied journal window; lifetime history unknown (direct execution may be recorded elsewhere; this scan does not establish lifetime use); no execution surface runs it either (clock, cron, daemon, roster, actlog and surfaced forks checked) | ◉ | ○ | ○ | ○ | ○ | ○ |
known-issue recall -- a mined defect signature matched to a remedy already bankedMeasured:ki_recall exists in runtime/_hdl_build/nx_known_issue_store.nx, verified at emit. The sovereign known-issue catalogue answers have we seen this before; a mined rival defect that matches one of ours is a shared leaky teapot. Adoption: LIB-WIRED importers=8 nonval=6 — fully adopted (top of its ladder).Pros Implementing source symbol found; runtime acceptance separate; ahead of Steam Reviews (native), download-steam-reviews, Appbot, Research line, Platform APIs; fully adopted on the estate ladderCons none on the measured axes (rival marks are documented presence, not depth) | ● | ○ | ○ | ○ | ○ | ○ |
| OPERATE | ||||||
beat cadence -- nightly incremental fetch and rubric for a data-row list of watched apps, a status artifact per appDARK —runtime/nx_steam_reviews.nx EXISTS but does not declare im_beat: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. Appbot refreshes channels continuously [appbot]; Steam recomputes its recent score daily [steam-policy]; ours ran by hand on 2026-09-05.Pros none measured yetCons behind Steam Reviews (native), Appbot; open contract; expected source declaration not established | ○ | ◐ | ○ | ◐ | ○ | ○ |
source policy by construction -- terms that forbid mining are refused before the first byteDARK —runtime/nx_reviewmine_lib.nx EXISTS but does not declare im_source_policy: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. A policy conf per source (allowed feeds, forbidden stores, required disclosures) read before any fetch; today the Amazon refusal is a sentence on this board, not a check in the path.Pros none measured yetCons open contract; expected source declaration not established | ○ | ○ | ○ | ○ | ○ | ○ |
every partition printed with its sum -- tiers, playtime bands, languagesSource present; authored stronger claim:sr_stats in runtime/nx_steam_reviews.nx, verified at emit. EXCEED with the why: a partition is a claim; stats and rubric print sum= and of= and say SUMS or LEAK, and the gate asserts it. Adoption: REGISTERED-UNAUTHORISED — PARTIAL: registered, no cap ever minted; no execution surface runs it either (clock, cron, daemon, roster, actlog and surfaced forks checked).Pros Source symbol found; stronger capability claim is authored; ahead of Steam Reviews (native), download-steam-reviews, Appbot, Research line, Platform APIsCons not adopted yet: registered, no cap ever minted; no execution surface runs it either (clock, cron, daemon, roster, actlog and surfaced forks checked) | ◉ | ○ | ○ | ○ | ○ | ○ |
whole chain sovereign -- own TLS, own JSON reader, own journal, no Python, no requestsSource present; authored stronger claim:sr_url in runtime/nx_steam_reviews.nx, verified at emit. EXCEED with the why: download-steam-reviews is Python 3.11 plus requests [dsr] and Appbot is a hosted service [appbot]; ours compiles through nx_cc to an ELF that fetched Steam from the laptop and the NAS the same day. Adoption: REGISTERED-UNAUTHORISED — PARTIAL: registered, no cap ever minted; no execution surface runs it either (clock, cron, daemon, roster, actlog and surfaced forks checked).Pros Source symbol found; stronger capability claim is authored; ahead of Steam Reviews (native), download-steam-reviews, Appbot, Research line, Platform APIsCons not adopted yet: registered, no cap ever minted; no execution surface runs it either (clock, cron, daemon, roster, actlog and surfaced forks checked) | ◉ | ○ | ○ | ○ | ○ | ○ |
| ORACLE | ||||||
Steam's own review score, totals and recent-versus-lifetime split read from every pageMeasured:rm_steam_summary exists in runtime/nx_reviewmine_lib.nx, verified at emit. The platform's aggregate is the oracle the rubric is checked against: Palworld score 9 with 196,730 positive of 205,511; VR HOT score 5 with 434 of 711 [steam-getreviews]. Adoption: LIB-WIRED importers=25 nonval=15 — fully adopted (top of its ladder).Pros Implementing source symbol found; runtime acceptance separate; ahead of Appbot, Research line; fully adopted on the estate ladderCons behind Steam Reviews (native) (leads) | ● | ◉ | ● | ○ | ○ | ● |
SemEval-2014 aspect-term F1 as the pre-declared bar for mined aspectsMeasured:ab_eval exists in runtime/nx_absa_lib.nx, verified at emit. MEASURED 2026-09-05 by nx_absa_bench (gate 27 of 27: the F1 arithmetic at exact permil with a zero-prediction control): the estate's unigram document-frequency baseline over the reconstructed test sentences, K equal to the distinct gold terms, exact normalised term-set match, scores restaurants F1 242 permil (gold 520 distinct terms, predicted 520, matched 126) and laptops F1 239 permil (gold 389, predicted 389, matched 93) against the published subtask-1 winners DLIREC 840 permil restaurants and IHS RD 745 permil laptops and the organisers own dictionary baseline 471 and 356, read from Table 4 of the mirrored paper [semeval14-paper] [semeval14]. NOT best of breed and says so: a unigram cannot match a multi-word gold term and the miner has no noun-phrase extractor, so the gap to the winners IS the rm_aspects rung, whose first cut now SHIPS: a frequent n-gram arm (Hu and Liu p-support pruning [hu-liu-2004], gate 66 of 66) lifts SB1 precision to 429 restaurants and 333 laptops permil and recovers 6 and 12 multi-word gold terms the unigram arm structurally cannot match, F1 218 and 238 permil with recall cut by the one-percent support floor, The bench's supervised training-dictionary arm learns from the mirrored TRAIN splits [semeval14-rest-train] [semeval14-lap-train] and scores F1 462 restaurants and 473 laptops permil, reproducing the paper's published dictionary baseline (471 and 356) and roughly doubling the unsupervised arms, so supervision is the lever the field says it is; still below the CRF winners so a supervised sequence extractor is rung IM28. Subtask-2 polarity MEASURED the same day as accuracy over the gold terms: the majority arm restaurants 650 permil (728 of 1120) and laptops 534 permil (341 of 638) beside the published majority 641 and 521, the estate lexicon arm 286 and 327 permil (the Steam-review defect and exceed lexicons fire on 146 of 1120 restaurant and 96 of 638 laptop records, the rest read neutral) against the winners DCU 809 and 704 and the organisers baseline 642 and 513 [semeval14-paper]; the gold class counts reproduce Table 2 of the paper exactly once the conflict class the mirror drops is removed (728 196 196 and 341 128 169), the provenance check on the mirrored gold. Adoption: LIB-WIRED importers=5 nonval=2 — fully adopted (top of its ladder).Pros Implementing source symbol found; runtime acceptance separate; ahead of Steam Reviews (native), download-steam-reviews, Appbot, Platform APIs; fully adopted on the estate ladderCons behind Research line (leads) | ● | ○ | ○ | ○ | ◉ | ○ |
| EVIDENCE | ||||||
the decision core's gate -- page reader, row codec, dedupe set, stats partitions, ranker, rubric -- on planted data with named controlsMeasured:g_build_page exists in runtime/nx_steam_reviews_gate.nx, verified at emit. 92 of 92 GREEN on the laptop build 2026-09-05; the controls are the empty page, an invalid escape, an over-cap string, an unreachable min_support and a negative vote carrying praise words. Adoption: GATE:LIVE trial=GREEN — fully adopted (top of its ladder).Pros Implementing source symbol found; runtime acceptance separate; ahead of Steam Reviews (native), download-steam-reviews, Appbot, Research line, Platform APIs; fully adopted on the estate ladderCons none on the measured axes (rival marks are documented presence, not depth) | ● | ○ | ○ | ○ | ○ | ○ |
CAPABILITY TWIN: the lab spine -- one row per run (app, date, tiers, top defects, top demands) so improving or regressing is readable across runs, never a levelDARK —runtime/nx_steam_reviews.nx EXISTS but does not declare sr_spine: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. The measurement-lab law: a level cannot express a trajectory; the spine is what turns two hand runs into a trend the board renders.Pros none measured yetCons open contract; expected source declaration not established | ○ | ○ | ○ | ○ | ○ | ○ |
| INSTALLED | ||||||
Steam library census -- every library folder and app manifest read, install tree walked with a bounded depth and budget, one row per titleSource present; authored stronger claim:ic_libraries in runtime/nx_installed_census_lib.nx, verified at emit. EXCEED with the why: no review tool on this board reads what is installed; Steam's own client knows only its own manifests [steam-getreviews]. Measured on the operator's laptop 2026-09-05: 16 titles, 16 on disk, 51 fingerprint rows, walk never capped; gate nx_installed_census_gate 39 of 39 on a planted three-title library. Adoption: LIB-WIRED importers=3 nonval=2 — fully adopted (top of its ladder).Pros Source symbol found; stronger capability claim is authored; ahead of Steam Reviews (native), download-steam-reviews, Appbot, Research line, Platform APIs; fully adopted on the estate ladderCons none on the measured axes (rival marks are documented presence, not depth) | ◉ | ○ | ○ | ○ | ○ | ● |
what the product SHIPS -- engine, anti-cheat, VR runtime, audio and physics middleware, netcode, video, scripting, mod hooks, redistributables from a DATA conf of name signaturesSource present; authored stronger claim:ic_match_name in runtime/nx_installed_census_lib.nx, verified at emit. EXCEED with the why: knowledge/reviewmine/fingerprints.conf is class, substring, label per row, so a new engine is one row and no code; measured 2026-09-05: Palworld = Unreal + Wwise + Epic Online Services + Python + a mods dir at 41 GB, VR HOT = Unity + OpenXR + FMOD at 24.6 GB, Terraria = XNA + Workshop + DotNet, VaMX = Unity + Chromium + OpenVR + Oculus. Adoption: LIB-WIRED importers=3 nonval=2 — fully adopted (top of its ladder).Pros Source symbol found; stronger capability claim is authored; ahead of Steam Reviews (native), download-steam-reviews, Appbot, Research line, Platform APIs; fully adopted on the estate ladderCons none on the measured axes (rival marks are documented presence, not depth) | ◉ | ○ | ○ | ○ | ○ | ○ |
tie-out to the review rubric by appid -- the census row carries the journaled review count, score, positives and negatives of the same titleSource present; authored stronger claim:ic_tieout in runtime/nx_installed_census_lib.nx, verified at emit. EXCEED with the why: what the product is made of sits beside what its players say, in one row a small model can read -- VR HOT: Unity + OpenXR + FMOD next to 711 reviews, score 5, controls and tracking complained about more than praised; Palworld: Unreal + Wwise next to 3,000 reviews, score 9, progress loss and crashes as the does-not-meet drivers. Adoption: LIB-WIRED importers=3 nonval=2 — fully adopted (top of its ladder).Pros Source symbol found; stronger capability claim is authored; ahead of Steam Reviews (native), download-steam-reviews, Appbot, Research line, Platform APIs; fully adopted on the estate ladderCons none on the measured axes (rival marks are documented presence, not depth) | ◉ | ○ | ○ | ○ | ○ | ○ |
Windows applications and OS census -- installed programs (369 uninstall rows on this laptop), drivers, OS build, GPU, runtimes -- as rows for the OS and application boardsDARK —runtime/nx_installed_census_lib.nx EXISTS but does not declare ic_app_census: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. The registry hive and Program Files walked from the sovereign ELF under WSL; the census answers what a rival application or OS component actually ships so a board reads its feature surface from the artifact, not from a brochure.Pros none measured yetCons open contract; expected source declaration not established | ○ | ○ | ○ | ○ | ○ | ○ |
installed-mode proposal rows -- fingerprints and tie-outs proposed into the domain boards they concern (gameengine, graphics, npcai, videocodec) through the proposal fileSource present; authored stronger claim:ip_propose_installed in runtime/nx_intelmine_lib.nx, verified at emit. LANDED 2026-09-05 (SHIPS rows -- DanceXR: Unity to gameengine, Chromium to browser, OpenXR to hapticcare, FMOD to synthroom, SteamAPI to sharehub; an unmapped label is counted, never dropped). Shares the proposal contract with im_propose_rows; a Unity+OpenXR title with tracking complaints is a gameengine and a hapticcare row, never a broad stroke. Adoption: LIB-WIRED importers=2 nonval=1 — fully adopted (top of its ladder).Pros Source symbol found; stronger capability claim is authored; ahead of Steam Reviews (native), download-steam-reviews, Appbot, Research line, Platform APIs; fully adopted on the estate ladderCons none on the measured axes (rival marks are documented presence, not depth) | ◉ | ○ | ○ | ○ | ○ | ○ |
asset formats -- files and bytes by extension per title (models, textures, audio, archives), the top eight by bytes, plus the bytes walkedSource present; authored stronger claim:ic_assets_summary in runtime/nx_installed_census_lib.nx, verified at emit. EXCEED with the why: the shape of a title's models, textures and audio is read from its archive formats by the artifact, never from a brochure -- VR HOT 740 Unity bundles 13.5 GB and 9 .assets 3.9 GB; Palworld one .pak of 40.5 GB; DanceXR 9 .assets 984 MB, 76 DLLs 641 MB, 58 .pak 51 MB (measured 2026-09-05, gate 44 of 44). This is the input the style-without-copying rung consumes: procedural parameters fitted to measured assets, never copied bytes. Adoption: LIB-WIRED importers=3 nonval=2 — fully adopted (top of its ladder).Pros Source symbol found; stronger capability claim is authored; ahead of Steam Reviews (native), download-steam-reviews, Appbot, Research line, Platform APIs; fully adopted on the estate ladderCons none on the measured axes (rival marks are documented presence, not depth) | ◉ | ○ | ○ | ○ | ○ | ○ |
| FEED | ||||||
mined intelligence rendered on every board -- the one renderer of Source present; authored stronger claim: | ◉ | ○ | ○ | ○ | ○ | ○ |
the platform's own title for an appid -- nx_steam_reviews name Measured: | ● | ● | ○ | ● | ○ | ● |
Aspect extraction, supervised SEQUENCE model: averaged structured perceptron with Viterbi BIO decoding (the winners class of model, integer weights, nofloat)Measured:sp_eval exists in runtime/nx_absa_seq.nx, verified at emit. MEASURED 2026-09-05 by nx_absa_seqextract on the SemEval-2014 Task 4 TRAIN+TEST splits, PROMOTED 12925751 reproduced on the NAS: restaurants F1 448 permil (P 798, R 311, 162 of 520 gold terms) and laptops F1 429 (P 721, R 305, 119 of 389) [semeval14-paper]. Features per token hashed into one weight table (word, prefix and suffix, previous and next word, digit shape, training-dictionary membership, bias) with BIO transitions; trained 8 epochs on 2018 and 1491 merged sentences. The record MERGE was the decisive fix: a .seg emits one record per aspect so a multi-aspect sentence labels its other aspects O, contradictory supervision that left 2915 of 3607 sentences still updating in epoch 8 at F1 294; folding same-sentence records into one example took it to 448 with updates down to 658. Precision is far above the dictionary tagger (798 vs 672) and recall below it (311 vs 351), so the two supervised arms sit at the published-baseline tier together; the winners DLIREC 840 and IHS RD 745 add POS and parse features and a CRF objective the estate has no tagger for yet, which is the remaining rung [semeval14]. Gate nx_absa_seq_gate 16 of 16 GREEN on the NAS Adoption: LIB-WIRED importers=2 nonval=1 — fully adopted (top of its ladder).Pros Implementing source symbol found; runtime acceptance separate; ahead of Steam Reviews (native), download-steam-reviews, Appbot, Platform APIs; fully adopted on the estate ladderCons behind Research line (leads) | ● | ○ | ○ | ○ | ◉ | ○ |
Aspect extraction, ENSEMBLE: the sequence model UNION the training-dictionary tagger (the estate's best number on both domains)Source present; authored stronger claim:sp_eval in runtime/nx_absa_seq.nx, verified at emit. MEASURED 2026-09-05 by nx_absa_seqextract (PROMOTED fb11ee0d) on the SemEval-2014 Task 4 TRAIN+TEST splits: restaurants F1 502 permil (P 646, R 411, 214 of 520 gold terms) and laptops F1 500 (P 640, R 411, 160 of 389) [semeval14-paper]. The perceptron (16 epochs, 13 hashed features incl. prev2/next2, prev+cur and cur+next conjunctions, 4-char suffix; converged at 170 and 128 epoch-16 updates) contributes precision (786/773 alone) and the dictionary contributes recall; their union exceeds both arms alone (perceptron 454/448, dictionary 462/473) and exceeds the paper's published dictionary baseline (471/356) on both domains [semeval14]. Still below the winners DLIREC 840 and IHS RD 745, whose extra points come from POS and dependency features and a CRF objective the estate has no tagger for yet -- the open rung. Gate nx_absa_seq_gate 20 of 20 GREEN on the NAS, union teeth included Adoption: LIB-WIRED importers=2 nonval=1 — fully adopted (top of its ladder).Pros Source symbol found; stronger capability claim is authored; ahead of Steam Reviews (native), download-steam-reviews, Appbot, Platform APIs; fully adopted on the estate ladderCons none on the measured axes (rival marks are documented presence, not depth) | ◉ | ○ | ○ | ○ | ◉ | ○ |
Aspect extraction scored on the PAPER'S metric: per-occurrence F1 across the test sentences (SemEval-2014 Task 4 eq. 1-2), the ruler the winners are quoted onSource present; authored stronger claim:sp_eval in runtime/nx_absa_seq.nx, verified at emit. MEASURED 2026-09-05 by nx_absa_seqextract (PROMOTED 8d924e46) on the full SemEval TRAIN+TEST: restaurants perceptron F1 535 permil (P 801, R 401, 449 of 1117 gold occurrences over 615 sentences) and perceptron-UNION-dictionary 619 (P 550, R 708); laptops perceptron 467 (P 678, R 356, 226 of 634 over 418 sentences) and union 502 (P 466, R 544) [semeval14-paper]. MAJORITY RULE, later the same day (PROMOTED 9ced9326, gate 31 of 31): a dictionary hit enters the union only if the term was an aspect in at least half its training occurrences (1068 of 1202 restaurant terms and 828 of 949 laptop terms pass) and the perceptron reads each term's training reliability as a graded feature; union F1 rises to 679 restaurants (P 706, R 653) and 533 laptops (P 609, R 474) while the perceptron-only lines stay within noise (535 and 456), so the estate stands at 81 and 72 percent of the winners. The board's earlier SB1 numbers were DISTINCT-term set overlap (each gold term once), a harder ruler that under-scores a model getting frequent terms right; both are now published and the set lines are unchanged. On the paper's ruler the estate stands at 619 of DLIREC's 840 and 502 of IHS RD's 745, above the organisers dictionary baseline 471 and 356 on both domains [semeval14]. Next levers in order: a validation-split-tuned combination (the union's laptop precision 466 is the dictionary over-predicting), then POS and dependency features and a CRF objective. Gate nx_absa_seq_gate 27 of 27 GREEN on the NAS with an occurrence fixture (one term as the aspect of two sentences counts once as a term and twice as an occurrence) Adoption: LIB-WIRED importers=2 nonval=1 — fully adopted (top of its ladder).Pros Source symbol found; stronger capability claim is authored; ahead of Steam Reviews (native), download-steam-reviews, Appbot, Platform APIs; fully adopted on the estate ladderCons none on the measured axes (rival marks are documented presence, not depth) | ◉ | ○ | ○ | ○ | ◉ | ○ |
Part-of-speech tagging, the estate's own tagger (nx_postag: greedy averaged perceptron over the 17 Universal POS tags, integer weights, a CoNLL-U reader) and POS features in the sequence modelMeasured:sp_set_treebank exists in runtime/nx_absa_seq.nx, verified at emit. MEASURED 2026-09-05 and 06 on the NAS. The tagger: 927 permil token accuracy on the held-out UD English EWT test split (23286 of 25094 tokens, 2077 sentences) after 5 epochs over 12544 sentences / 204578 tokens, through the PROMOTED nx_postag_eval; inside the published band for a feature-based greedy tagger and below neural taggers, stated as such [ud-ewt-train] [ud-ewt-test]. The treebank is a DATA asset with its CC BY-SA 4.0 license beside it [ud-ewt-license]. POS features (this, previous and next tag and the two tag bigrams) on the full SemEval splits, the paper's per-occurrence metric: restaurants union F1 679 -> 689 (P 706 -> 714, R 653 -> 666), perceptron 535 -> 548; laptops union 533 -> 538 (P 609 -> 612, R 474 -> 481), perceptron 456 -> 470 [semeval14-paper] -- a real gain on both domains and in both arms, and the modest one the literature says POS alone buys; 82 and 72 percent of the winners on their own ruler [semeval14]. Gates: nx_postag_gate 20 of 20 and nx_absa_seq_gate 36 of 36 GREEN on the NAS. THE TAGGER RUNG, 2026-09-06: the three standard features it lacked (tag bigram, word two back, word two ahead), a deterministic per-epoch shuffle and 8 epochs lift the held-out EWT accuracy to 931 permil (23374 of 25094; pre-declared bar EXCEED 927, met) -- and the aspect model does not move: restaurants 683 / 542 and laptops 532 / 457 on the rebuilt binary against 687 / 547 and 528 / 452 on the previous one, inside the five-to-ten permil noise band, so the aspect perceptron is saturated with respect to tag quality at this level and the best published figures stay 689 / 538 [semeval14-paper]. Served gates on the rebuilt fleet: nx_postag_gate 20 of 20, nx_absa_seq_gate 42 of 42, nx_depparse_gate 33 of 33 Adoption: LIB-WIRED importers=2 nonval=1 — fully adopted (top of its ladder).Pros Implementing source symbol found; runtime acceptance separate; ahead of Steam Reviews (native), download-steam-reviews, Appbot, Platform APIs; fully adopted on the estate ladderCons behind Research line (leads) | ● | ○ | ○ | ○ | ◉ | ○ |
Dependency parsing, the estate's own parser (nx_depparse: arc-standard transitions with a greedy averaged perceptron, the static oracle, 24 core features, reading the treebank through the tagger's reader)Measured:dp_parse_stream exists in runtime/nx_depparse.nx, verified at emit. MEASURED 2026-09-06 on the NAS through the PROMOTED nx_depparse_eval: UAS 804 permil (20188 of 25094 tokens) and LAS on the base relation names 763 on the held-out UD English EWT test split, with the tagger's predicted tags on both splits (one tag generator, no gold-tag optimism); trained 5 epochs on 12544 sentences, 287 non-projective sentences skipped by the static oracle, 36 relation labels [ud-ewt-train] [ud-ewt-test]. HONEST READING: below the middle-to-high eighties a feature-based greedy parser reaches on EWT -- 17777 updates in the last epoch say it has not converged, and a dynamic oracle or beam would lift it; both are named rungs. Gate nx_depparse_gate 33 of 33 GREEN on the NAS (learns a planted grammar to UAS and LAS 1000, skips the planted crossing-arc sentence, an untrained parser scores 0). AT 12 EPOCHS, same day: UAS 805 and LAS 765 against 804 and 763, last-epoch updates 17777 -> 7181 -- epochs were not the bottleneck, the design plateaus near 80 UAS; the three structural parts of the gap (static oracle, 24 of 72 templates, predicted tags) are named on the plan as rungs Adoption: LIB-WIRED importers=3 nonval=2 — fully adopted (top of its ladder).Pros Implementing source symbol found; runtime acceptance separate; ahead of Steam Reviews (native), download-steam-reviews, Appbot, Platform APIs; fully adopted on the estate ladderCons behind Research line (leads) | ● | ○ | ○ | ○ | ◉ | ○ |
Aspect extraction with dependency features, the ABLATION on one binary (the parser's relation, head word, head tag, relation+own tag and the outermost dependents' relations as five more hashed families; a mode, off by default)Measured:sp_set_parse exists in runtime/nx_absa_seq.nx, verified at emit. MEASURED 2026-09-06 on the NAS, four runs of the PROMOTED nx_absa_seqextract on the full SemEval splits with the same treebank, the paper's per-occurrence metric: restaurants tagger-only union 687 / perceptron 547 versus tagger PLUS the 5-epoch parser 683 / 542; laptops tagger-only 528 / 452 versus 521 / 454 [semeval14-paper]. The parse features from this parser do not help and lean negative on both domains: DLIREC's exceed came from a much stronger parser and dependency-PATH features to opinion words, not head-word features off an 80-UAS greedy parser [semeval14]. DECISION, measured not guessed: the default with a treebank is the tagger alone (the arm that measured best) and the parser is a mode (the CLI's parse argument), kept and gated, never stripped; laptops carries about ten permil of build-to-build noise (the previous generation's tagger-only run read 538), restaurants two. Gate nx_absa_seq_gate 42 of 42 GREEN on the NAS with the parse and ablation teeth. Next, principled not tuning: the parser to convergence (12 epochs) and the dependency-path family the winners used Adoption: LIB-WIRED importers=2 nonval=1 — fully adopted (top of its ladder).Pros Implementing source symbol found; runtime acceptance separate; ahead of Steam Reviews (native), download-steam-reviews, Appbot, Platform APIs; fully adopted on the estate ladderCons behind Research line (leads) | ● | ○ | ○ | ○ | ◉ | ○ |
Training-order sensitivity of the sequence model, the per-epoch SHUFFLE mode (epoch 0 records every merged-sentence group, later epochs walk a deterministic permutation shared with the tagger; off by default)Measured:sp_set_shuffle exists in runtime/nx_absa_seq.nx, verified at emit. MEASURED 2026-09-06 on the NAS against a rule declared BEFORE the run (the shuffle becomes the default only if the paper-metric union F1 rises on both domains): restaurants 683 -> 679 union and 542 -> 533 perceptron, laptops 532 -> 536 and 457 -> 465 [semeval14-paper]. One domain down, one up, both inside the ten-permil band this board measures as build-to-build noise, so the shuffle ships as a mode and file order stays the default; the same change lifted the tagger by four permil, which says the averaged perceptron's averaging already absorbs most of the order sensitivity here. Gate nx_absa_seq_gate 49 of 49 GREEN on the NAS: groups recorded equal the merged sentences, unusable groups counted too, off by default, on when set, still learns, deterministic. A non-result published as one, not tuned into a result [semeval14] Adoption: LIB-WIRED importers=2 nonval=1 — fully adopted (top of its ladder).Pros Implementing source symbol found; runtime acceptance separate; ahead of Steam Reviews (native), download-steam-reviews, Appbot, Platform APIs; fully adopted on the estate ladderCons behind Research line (leads) | ● | ○ | ○ | ○ | ◉ | ○ |
Word clusters for the sequence model, the CLUSTERS mode (nx_wordclust: k-medoids over the estate's own PPMI cosine at 32, 128 and 256 clusters, the sovereign stand-in for the Brown clusters every SemEval-2014 winner fed its tagger; five hashed families per token, a word the model does not know spells a single byte and degrades to the base features; off by default)Measured:sp_set_clusters exists in runtime/nx_absa_seq.nx, verified at emit. MEASURED 2026-09-06 on the NAS against a rule declared BEFORE the run (clusters become the default only if the paper-metric union F1 rises on BOTH domains beyond the ten-permil noise band on at least one): laptops 532 -> 543 union and 457 -> 476 perceptron, both above the band; restaurants 683 -> 680 union and 542 -> 534 perceptron, inside it [semeval14-paper]. One domain up, one flat, so clusters ship as a mode and the file-order tagger build stays the default. The asymmetry is itself a measurement: the general PPMI model built from the estate's corpus knows 863 permil of the laptop training vocabulary and 803 permil of the restaurant one, so the domain the model covers better is the domain the clusters help, which is the winners' in-domain-text lever restated as a coverage number. Gate nx_wordclust_gate 25 of 25 GREEN on the NAS on a planted model (synonym pairs grouped, pairs separated, on-demand assignment, fail-closed without a model) and nx_absa_seq_gate 54 of 54 with five cluster teeth. Next rung: in-domain clusters from review text the estate is licensed to hold, the corpus decision the operator owns [semeval14] Adoption: LIB-WIRED importers=2 nonval=1 — fully adopted (top of its ladder).Pros Implementing source symbol found; runtime acceptance separate; ahead of Steam Reviews (native), download-steam-reviews, Appbot, Platform APIs; fully adopted on the estate ladderCons behind Research line (leads) | ● | ○ | ○ | ○ | ◉ | ○ |
The CRF objective for the sequence model, the CRF mode (nx_logadd_lib: fixed-point log-sum-exp in Q10 nats with tables derived from the Taylor series and the estate's integer logarithm; forward-backward in the log domain under the decoder's own masks; one stochastic-gradient step per merged sentence from the token and pair marginals, a quarter-nat step decayed by one over one plus the epoch, the existing averaging as the regulariser; off by default)Measured:sp_set_crf exists in runtime/nx_absa_seq.nx, verified at emit. MEASURED 2026-09-06 on the NAS against a rule declared BEFORE the run (the CRF becomes the default only if the paper-metric union F1 rises on BOTH domains beyond the ten-permil band on at least one): restaurants 683 -> 680 union and 542 -> 539 perceptron, laptops 532 -> 535 and 457 -> 462, every delta inside the band [semeval14-paper]. The objective did what an objective does: the summed negative log-likelihood fell from 37.6 million to 0.84 million Q10 units on restaurants and from 18.7 to 0.49 million on laptops, the marginals partitioned to one within six Q10 units with no partition below its gold path, and the training-set mistakes halved (282 to 132 last-epoch updates on restaurants, 179 to 90 on laptops), yet the test F1 did not move. With the same feature families the conditional likelihood and the averaged perceptron generalise alike here, so the CRF ships as a mode and the perceptron stays the default; the winners' gap over this model is their in-domain data and their dependency features, not their objective. Gates: nx_logadd_gate 29 of 29 GREEN on the NAS on hand-derived known answers, nx_absa_seq_gate 65 of 65 with eleven CRF teeth. The estate now owns fixed-point log-domain arithmetic and a linear-chain CRF from the first byte [semeval14] Adoption: LIB-WIRED importers=2 nonval=1 — fully adopted (top of its ladder).Pros Implementing source symbol found; runtime acceptance separate; ahead of Steam Reviews (native), download-steam-reviews, Appbot, Platform APIs; fully adopted on the estate ladderCons behind Research line (leads) | ● | ○ | ○ | ○ | ◉ | ○ |
Dense embedding features for the sequence model, the EMBED mode (nx_embfeat_lib: the estate's own trained word vectors, 24 Q10 coordinates per word from embed_v1.bin, each quantised to a signed bucket at half-RMS steps derived from the table, one hashed family per coordinate behind a per-slot feature mask so an absent feature casts no vote and the default model stays byte-identical; off by default)Measured:sp_set_embed exists in runtime/nx_absa_seq.nx, verified at emit. MEASURED 2026-09-06 on the NAS against a rule declared BEFORE the run (default only if the paper-metric union F1 rises on BOTH domains beyond ten permil on at least one): restaurants 683 -> 682 union and 542 -> 540 perceptron, laptops 532 -> 528 and 457 -> 446 [semeval14-paper]. Flat on one domain and down on the other, so the mode stays off, published as a negative result. The receipt carries the two reasons: the table knows only 675 permil of restaurant and 711 permil of laptop training TOKENS (the earlier 803 and 863 were vocabulary types, and the tokens the vocabulary lacks are the ones a review is made of), and the last-epoch training mistakes rose from 282 to 436 and 179 to 305, so twenty-four nine-way buckets per known token add capacity the two thousand training sentences cannot fit in sixteen epochs. Gate nx_embfeat_gate 32 of 32 GREEN on the NAS and nx_absa_seq_gate 72 of 72 with seven embedding teeth, including the mask proof: without it twenty-four constant bias votes had turned two POS teeth RED. A capability built from the first byte and a number that says the next lever is still data [semeval14] Adoption: LIB-WIRED importers=2 nonval=1 — fully adopted (top of its ladder).Pros Implementing source symbol found; runtime acceptance separate; ahead of Steam Reviews (native), download-steam-reviews, Appbot, Platform APIs; fully adopted on the estate ladderCons behind Research line (leads) | ● | ○ | ○ | ○ | ◉ | ○ |
| ORACLE 2026 | ||||||
dated bars for aspect extraction and quad prediction, read from the field's 2025 to 2026 record (every number carries its year)Open — watchingruntime/nx_absa_llm.nx : al_extract, re-measured on every compare beat. Ship that symbol and this mark flips itself; the comparewatch- plane row flips with it. WHAT THE CURRENT MONTH SAYS (rule, operator 2026-09-06: a bar older than the current month is a hard fail unless the current month has nothing, and then the row names the month it fell back to): SEPTEMBER 2026 HAS NO ENTRY on arXiv for aspect-based sentiment as of 2026-09-06, so the bar month is AUGUST 2026 [absa2026aug]: STAR-OPD (2026-08-21) distils chain-of-thought LLM teachers on-policy into a Qwen3-4B student with set-structured rewards for quadruple extraction on SemEval-2014 and E-ABSA20K, and SeqLab with aspect-code switching (2026-08-31, EMNLP 2026) sets the end-to-end ABSA state of the art across eleven languages with a sequence-to-sequence model whose encoder also sequence-labels; for the dimensional task the freshest month is JULY 2026 [dimabsa2026sys] (a transformer-ensemble regressor plus a fine-tuned decoder LLM for extraction with scores; the March 2026 first-place system was uncertainty-weighted multitask learning, and April 2026 measured task-specific fine-tuning beating few-shot LLM prompting on every development set). OLDER BARS WITH YEARS, read from the abstracts in two more arXiv listings mirrored the same day [asqp2026feed] [atellm2026feed]: (2023-10) a fine-tuned GPT-3.5 scores F1 83.8 on the SemEval-2014 Task 4 JOINT aspect-term-plus-polarity task, 5.7 points over InstructABSA, at a thousand times the parameters of the models it beat; (2025-02) zero and few-shot LLM prompting on Rest16 quad prediction reaches F1 51.54 at 20 shots against 60.39 for the fine-tuned MVP, and target-aspect-sentiment detection 68.93 against 72.76; (2026-03) lightweight models trained on LLM-annotated examples reach Rest16 quad F1 49.85 from 50 seed examples against 51.10 for a 27B model prompted in context, at a fraction of the energy; (2026-03 to 2026-04) the frontier is generative quad prediction with a single-shot global corrector and stepwise syntax-integration tuning, with listwise preference optimisation (2025-11) and stepwise task augmentation (2025-01) as the rungs before them; and the 2026 shared task is dimensional valence-arousal ABSA [dimabsa2026]. What this board's ladder climbed toward (DLIREC 840 and IHS RD 745 per-occurrence F1) is the 2014 bar on subtask 1 alone; the 2023 fine-tuned-LLM number is the dated bar on the SemEval-2014 sets today, though on a joint metric this board does not yet score, and the 2025 to 2026 numbers are on a different task (four-element quads on Rest15 and Rest16) whose data the estate has not admitted. So the rungs before any climb are the data admissions (ASQP Rest15 and Rest16, DimABSA) with licenses beside them, the sovereign generative arm (nx_absa_llm over nx_qwen_extract, WATCHING here), and the joint term-plus-polarity ruler in nx_absa_bench; every bar on this row states its year, and the emitter flag for a bar older than the field's turnover is the owed mechanism.Pros none measured yetCons behind Research line (leads); open contract; expected source declaration not established | ○ | ○ | ○ | ○ | ◉ | ○ |
The 2026 data admitted with licences: ASQP Rest15 and Rest16 quads and the DimABSA valence-arousal setsDARK —runtime/nx_absa_lib.nx EXISTS but does not declare ab_quad_load: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. Rung IM29, substrate for the frontier: every 2026 number is on quads (aspect, category, opinion, polarity) or on valence-arousal pairs, and the estate holds neither set; the reader is the one record decoder with CRLF tolerance, mirrored through nx_research_fetch with the licence beside the data [asqp2026feed] [dimabsa2026].Pros none measured yetCons behind Research line (leads); open contract; expected source declaration not established | ○ | ○ | ○ | ○ | ◉ | ○ |
The paper rulers for the 2026 task: joint term-plus-polarity F1, quad F1 and the continuous F1 of DimABSADARK —runtime/nx_absa_bench.nx EXISTS but does not declare ab_eval_quad: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. Rung IM30, substrate for best-in-class: the numbers this board must quote (83.8 joint, 60.39 quads, cF1 on dimensions) are on rulers nx_absa_bench does not yet carry; each ruler is reproduced on a published system output before it scores ours [atellm2026feed] [asqp2026feed].Pros none measured yetCons behind Research line (leads); open contract; expected source declaration not established | ○ | ○ | ○ | ○ | ◉ | ○ |
The dimensional arm: valence-arousal regression on the nofloat encoder, scored by cF1Open — watchingruntime/nx_absa_dim.nx : ab_va_regress, re-measured on every compare beat. Ship that symbol and this mark flips itself; the comparewatch- plane row flips with it. Rung IM32, contender for the dimensional frontier: an integer regression head on the estate's own encoder, trained on the DimABSA split, scored by cF1 with the gap to the SemEval-2026 systems stated [dimabsa2026sys].Pros none measured yetCons behind Research line (leads); open contract; expected source declaration not established | ○ | ○ | ○ | ○ | ◉ | ○ |
| Triangulation | ||||||
the mechanistic arm and the generative arm adjudicated per sentence by census classOpen — watchingruntime/nx_absa_triangulate.nx : ab_triangulate, re-measured on every compare beat. Ship that symbol and this mark flips itself; the comparewatch- plane row flips with it. Rung IM33, the exceed candidate: the field runs one arm per system; this board runs the integer perceptron (which cannot hallucinate a span) beside the generative arm and adjudicates disagreements by the error census class, with the rule declared before the run and a hallucinated span refused by construction. No rival column carries this, which is why it is the lead the ranker prices as an option.Pros none measured yetCons open contract; expected source declaration not established | ○ | ○ | ○ | ○ | ○ | ○ |
The 2026 task shape: LLM-class structured extraction and DimABSAOpen — watchingruntime/nx_absa_llm.nx : al_extract, re-measured on every compare beat. Ship that symbol and this mark flips itself; the comparewatch- plane row flips with it. THE HONEST FRAME FOR THIS LADDER: the bar above (840 and 745 on Subtask 1) is the 2014 bar, and every rung on this board so far is the 2014-to-2018 class (feature perceptron, CRF, clusters, embeddings). The task as the field runs it in 2026 is structured extraction of aspect, opinion, category and polarity by an encoder or a generative model, and SemEval-2026 Task 3 moves the target to dimensional sentiment (valence and arousal on a numeric scale) over broader domains than restaurants and laptops [dimabsa2026]. The estate is not without the modern class: it runs a sovereign integer-arithmetic Qwen in-process (nx_nofloat_serve_core, the qwen extraction library the research reader already composes, a 384-token context and a proven 900-character prompt guard). This row is the build contract: nx_absa_llm prompts the sovereign model per test sentence with one demonstration from the training split, parses the structured list it emits, and scores it on the SAME per-occurrence scorer as the perceptron, appending one row per sentence to a resumable journal so an interrupted run keeps what it has. Rule declared before any run: the LLM arm is published as measured, becomes the union's third arm only if the paper-metric union F1 rises on BOTH domains beyond ten permil on at least one, and the rung after it is the no-float fine-tune on the estate's own autograd. DimABSA itself enters this board as data admission (its splits mirrored with their license beside them) before any number is claimed [semeval14]Pros none measured yetCons behind Research line; open contract; expected source declaration not established | ○ | ○ | ○ | ○ | ◐ | ○ |
| Class | Count | Note |
|---|---|---|
| rows with rival marks | 42 | rows carrying a Yes, Best or Part in a rival column |
| cited | 42 | a reference mark resolves to a pinned mirror |
| uncited | 0 | an observation read, badged until a reference lands |
| rows, summed | 42 | RECONCILED: the parts sum to the total 42 |
Delivery and evidence
Inspect risks, technical debt, rendered observations, experiments and references. Read scope and limitations alongside every result.
Release history and work log
| When | Rung | Kind | Entry |
|---|---|---|---|
| 2026-09-05 | IM0 | measure | Palworld appid 1623730 (2099 cents): 3000 most recent English reviews, positive 947 permil; rubric EXCEEDS 401 MEETS 2358 MIXED 82 DOES-NOT-MEET 159 (sum 3000); playtime bands lt1h 26 at 346 permil positive, 1-10h 326 at 911, 10-100h 1326 at 945, gt100h 1322 at 968; refund window 40 docs at 400 permil; value mentions EXCEEDS 46 MEETS 125 MIXED 36 DNM 21; top defects progress 35 docs (DNM 5), unplayable 10 (lift 13.6x), bugs 32, lost 31, crashes 11 (lift 10.9x), wiped 4 (lift 14.9x), error 6 (lift 13.3x); top features pals 419 (demanded 124), base 250 (93), world 242 (90), survival 223, building 206 (76), friends 146. Instrument: nx_steam_reviews rubric 1623730 english 20 3 on the laptop build sha af365865. |
| 2026-09-05 | IM0 | measure | VR HOT appid 1571340 (4499 cents): the whole English population, 711 reviews (stop=empty-page), positive 610 permil, all written during early access, 57 refunded flags; rubric EXCEEDS 69 MEETS 338 MIXED 27 DOES-NOT-MEET 277 (sum 711); bands lt1h 246 at 443 permil, 1-10h 349 at 656, 10-100h 104 at 836, gt100h 12 at 750; refund window 384 docs at 468 permil; value mentions EXCEEDS 13 MEETS 31 MIXED 11 DNM 82; top defects bugs 27, buggy 26, broken 14 (DNM 13, meets 0), crashes 17, glitches 17, unplayable 11; features complained more than praised: controls 46 vs 21 (demanded 35), physics 26 vs 15, menu 14 vs 5, controller 13 vs 4, tracking 8 vs 3; praised more than complained: updates 21 vs 6, customization 20 vs 13, graphics 19 vs 13. |
| 2026-09-05 | IM0 | lesson | The reading the operator asked for, stated as numbers not adjectives: VR HOT at 4499 cents carries a value-proposition signal (value talk sits in 296 permil of does-not-meet reviews against 188 permil of exceeds, and 54 percent of its reviewers wrote inside the refund window) AND a defect signal (controls, physics, tracking, menu complained about more than praised are leaky teapots wearing feature names); Palworld at 2099 cents carries almost no value signal (947 permil positive, 968 among players past 100 hours) and a narrow defect signal concentrated in progress loss, wipes and crashes -- the brand-degradation class, cheap to name and expensive to leave. What we must do BETTER than both to lead: no lost-progress class at all (Palworld's top defect), controls and tracking that are praised more than complained about (VR HOT's top complaint), and the demanded features (pals, base, building, friends coop; customization, interaction) shipped as capability, which is the target list the goal map now reads. |
| 2026-09-05 | IM0 | lesson | Two fetch facts earned the hard way: the Chrome-hello leg alone fails the TLS handshake against store.steampowered.com (status 0, code -3) while the full ladder (minimal 1.3 hello first) succeeds -- compose nx_https_fetch_follow_best, the entry nx_research_fetch rides; and the laptop's _hdl_build/nx_crawl_pace.nx was an 8 KB fossil from 08-07 missing every _tbl function the pacer hook needs -- the NAS copy (27,045 B, sha 2abc63a3) was adopted by hash before the first build, per the tree-divergence law. |
| 2026-09-05 | IM0 | queue | NAS build of nx_steam_reviews REFUSED by build admission (I/O storm) and QUEUED as BQ-nx_steam_reviews; laptop artifacts (program sha af365865, gate sha 6bf93f26) staged through nx_content_put for /api/promote; NAS gate run, tools/register, the .gates row, nishi_compare_regen, nx_domain_admit and nx_compare_rank follow the promote. |
| 2026-09-05 | IM0 | land | PROMOTED on the NAS 2026-09-05: nx_steam_reviews.elf 552,180 B sha af365865 (the /api/promote reply was a 503 read-after-accept and the artifact proved it had landed) and nx_steam_reviews_gate.elf 99,750 B sha 6bf93f26 (PROMOTED prev=1); both REGISTERED callable; sources on the NAS build tree nx_reviewmine_lib.nx sha 22c47f51, nx_steam_reviews.nx sha 59366f18, nx_steam_reviews_gate.nx sha 46bba0b6 (a 503 on its content-put HAD landed; the retry was refused stale-expect, which is the proof); lexicons and stopwords under knowledge/reviewmine/ on the NAS; the NAS gate run read 92/92 GREEN (pid 2412) and the NAS live fetch of Portal 2 read status=200 decoded=100 new=100 (pid 2481); knowledge/compare/intelmine.gates carries the row; nx_domain_admit VERDICT=ADMIT; nx_compare_rank ranks IM1 im_beat first (priority 20000), then IM3, IM14, IM18, IM4. The artifacts are LAPTOP builds shipped through the content door because NAS admission refused the build (I/O storm): the closure files that differed were adopted by hash (nx_crawl_pace), and the queued NAS build BQ-nx_steam_reviews will yield the NAS-built twin for a contentdiff when it fires. |
| 2026-09-05 | IM20 | measure | Laptop Steam library 2026-09-05 (maxdepth 4): 16 titles, all on disk, fingerprints 51 rows. Palworld 1623730: Unreal, Wwise, EpicOnlineServices, Python, ModsDir, 41,177,764,991 B, reviews journaled 3000, score 9, positive 196,730, negative 8,781. VR HOT 1571340: Unity, OpenXR, FMOD, 24,626,600,946 B, reviews 711, score 5, positive 434, negative 277. Terraria: XNA, SteamAPI, Workshop, DotNet. VaMX: Unity plus Chromium, OpenVR plus Oculus, DirectXRedist. Corruption of Champions II: Chromium. Mirage: Unity, OpenVR plus Oculus, Mono. Instrument: nx_installed_census steam /mnt/c/Program Files (x86)/Steam 4 on the laptop build; census at knowledge/reviews/installed/steam.census (2,670 B). |
| 2026-09-05 | IM20 | lesson | The install tree is the second witness the board needed: a review says controls and tracking are bad, the tree says Unity plus OpenXR, and the two together are a gameengine and a hapticcare row rather than a broad stroke. Reviews say what players FEEL, the tree says what the product IS MADE OF; joined by appid they are rows a small local model can read without context -- the direction the operator named (mechanistic structure so a smaller model does the last mile). |
| 2026-09-05 | IM3 | land | nx_intelmine_lib + nx_intelmine_propose + nx_intelmine_propose_gate landed on the laptop 2026-09-05: one call `nx_intelmine_propose <appid>` runs the rubric, reads the census row, routes through knowledge/reviewmine/capability_map.conf (133 rows) and appends deduped <domain>.proposed rows with a SIGNAL (DEFECT, WE-DO-BETTER, DEMANDED, THEY-DO-WELL, SHIPS) and the counts. DanceXR (1905510, 12 English reviews, tiers 3/7/0/2): 10 rows -- THEY-DO-WELL character and characters (charsim), steam (sharehub); WE-DO-BETTER headset (hapticcare), physics (softbody); SHIPS Unity (gameengine), Chromium (browser), OpenXR (hapticcare), FMOD (synthroom), SteamAPI (sharehub). Written under buildroot/knowledge/compare/<domain>.proposed; the emitter does not render .proposed yet (that is the next emitter rung), and nx_goalmap reads the boards the rows name. |
| 2026-09-05 | IM24 | land | installed-mode proposals are the same call (ip_propose_installed): every fingerprint class label with a map row becomes a SHIPS row on the board that owns the class; FMOD, Chromium and OpenXR routed on DanceXR; an unmapped label is COUNTED (unmapped=) never dropped. |
| 2026-09-05 | IM20 | measure | asset-format census added to the installed mode (ic_assets_summary, ext:files:bytes, top eight by bytes, walk_bytes per title): VR HOT bundle 740 files 13.5 GB, assets 9 files 3.9 GB, bin 17 files 2.9 GB, ress 1.3 GB, dll 43 files 488 MB; Palworld pak 1 file 40.5 GB, exe 4 files 189 MB, dll 15 files 79 MB; DanceXR assets 9 files 984 MB, dll 76 files 641 MB, ress 511 MB, exe 7 files 209 MB, pak 58 files 51 MB. Gate 44 of 44. The models, textures and audio of a title are read from its archive formats by the artifact, which is the input the style-without-copying rung (procedural parameters fitted to measured assets, never copied bytes) will consume. |
| 2026-09-05 | IM3 | lesson | A gate that runs its unknown-key control AFTER loading the real row measures a cleared buffer: ip_census_load clears its outputs on a miss (correct), so the fixture read 20 of 32 while the organ was right; re-ordered the control first. Same family as the estate's fixture-reached-the-condition law. |
| 2026-09-05 | IM3 | measure | DanceXR as the operator's worked target [appdetails-dancexr]: the store record says it is a character model viewer and motion player for PMX, XNALara/XPS, VMD and BVH models; the install tree says Unity + OpenXR + FMOD + a Chromium runtime with 9 .assets files of 984 MB and 76 DLLs; its 12 English reviews grade 3 exceeds / 7 meets / 0 mixed / 2 does-not-meet with character and characters praised (THEY-DO-WELL, to charsim), headset and physics complained as often as praised (WE-DO-BETTER, to hapticcare and softbody). The estate already reads every format DanceXR reads (nx_pmx, nx_vmd, nx_bvhfk), so the WebGPU door for those capabilities is a gameengine and charsim rung the proposal rows now name, not a discovery. |
| 2026-09-05 | IM20 | land | PROMOTED + REGISTERED on the NAS 2026-09-05: nx_installed_census.elf 51,712 B sha 2a1b39ae and nx_installed_census_gate.elf 71,942 B sha 9e9094b1 (gate 44/44 on the NAS, pid 2443); sources on the build tree nx_installed_census_lib.nx sha 51b30287, nx_installed_census.nx sha 5c3221ec (a content-put that answered unknown-transfer-id HAD landed -- proven by the stale-expect refusal naming the new sha), nx_installed_census_gate.nx sha 27749463; fingerprints.conf on the NAS. The NAS has no Steam library, so the census runs where a client exists (the laptop today, through the WSL mount) and the beat rung IM23 carries that. |
| 2026-09-05 | IM3 | land | PROMOTED + REGISTERED on the NAS 2026-09-05: nx_intelmine_propose.elf 52,006 B sha 5673b776 and nx_intelmine_propose_gate.elf 69,293 B sha 0a494ab5 (gate 33/33 on the NAS, pid 8392); sources nx_intelmine_lib.nx sha f919bc53, nx_intelmine_propose.nx sha 7db0c0db, nx_intelmine_propose_gate.nx sha f01f575a; capability_map.conf on the NAS. Live on the NAS over Portal 2 (appid 620, 100 journaled reviews, tiers 17/82/0/1): six THEY-DO-WELL rows -- story to gen, coop to gameengine, voice and dialogue to companionchat, music to synthroom, visuals to graphics -- written under buildroot/knowledge/compare/<domain>.proposed; census_row=0 there because the NAS holds no Steam library, so the name fell back to the appid (the census tie-out is laptop-side until IM23). |
| 2026-09-05 | IM25 | measure | DanceXR as the miner test, 2026-09-05: nx_intelmine_propose (12 EN reviews plus installed fingerprints) proposed 10 rows on 7 boards; a hand census of the vendor feature index and docs mirrored in charsim.refs (site, features.md, actors.md, motion.md, physics.md, vr_operations.md, download.md) lists 37 capability rows -- PMX XPS FBX ingest, ZIP packaging, VMD and BVH motion, universal retarget with bone fixes, bone mapper, VMD camera, dance sets and music timing, auto dance, idle catwalk lifelike, blink breath eye contact, keyframe animation, override and remix, PMX physics, per-part physics tools, XPBD cloth and mesh-to-cloth, particles fluid tentacles, dressing outfit bodypaint accessory, per-slot materials and toon shading, sky lighting HDR, water, weather particles, stage props mirror laser screen, six camera modes, multi-actor formation playlist attach, AI voice chat TTS lipsync STT, offline render 2D SBS VR180 VR360, ray-tracing build, web WebGL player, Android iOS Quest, VR operations and AR, Native path-traced app, scene save bundle presets, audio options spatial audio video player, Steam itch Patreon distribution and activation; the 10 proposal rows collapse to 4 of those 37 (physics, VR headset door, audio middleware, Steam distribution) = 108 permil recall, 3 rows are engine and runtime fingerprints (Unity, Chromium, SteamAPI) that name no capability, 2 rows are review sentiment on the word character with 2 praises |
| 2026-09-05 | IM25 | lesson | reviews name what annoys and fingerprints name what ships in the binary; neither names what the product DOES, and a 12-review title has almost no signal at all -- the feature index the vendor publishes is the cheapest high-recall source class and it is already the shape capability_map.conf consumes (kind, term, domain, rung title); the seven .proposed files the proposer wrote on 2026-09-05 were laptop-local and are now on the NAS publishing tree (buildroot/knowledge/compare/<domain>.proposed) for the emitter rung that renders them |
| 2026-09-05 | IM25 | retract | the IM25 measure row above says nx_intelmine_propose and nx_installed_census were SOURCE-ONLY and STAGED on the NAS; that was the catalog reading at 1788625300 and a sibling lane promoted, registered and ran all four organs (proposer, census, both gates) within the hour -- nx_catalog at 1788628800 reads PROMOTED 52006 B and 51712 B, REGISTERED, INVOKED; the recall number (4 of 37, 108 permil) is unaffected because it was measured on the proposer's own output rows |
| 2026-09-05 | IM3 | land | RULE-11 HOIST ACROSS THE FIVE MINER SOURCES (operator 2026-09-05: magic numbers everywhere): nx_magic map at threshold 2 read nx_reviewmine_lib 103 sites 17 distinct, nx_installed_census_lib 37 and 9, nx_intelmine_lib 43 and 13, nx_steam_reviews 45 and 9, nx_intelmine_propose 17 and 5; every site is now a const named for its MEANING (RM_I64_BYTES beside RM_BITS_PER_BYTE, the UTF-8 lead and continuation bytes, the JSON key quotes, the row escape length, the class indices, the summary field indices, argv positions and exit codes), the {title} token length is derived from the literal, the tier sums are loops over RM_TIER_N, and the duplicate class-name table in nx_intelmine_lib is retired in favour of ic_class_name (one table, imported); gates on the rebuilt laptop artifacts nx_steam_reviews_gate 92 of 92, nx_installed_census_gate 44 of 44, nx_intelmine_propose_gate 33 of 33 GREEN; nx_installed_census_gate rebuilt BYTE-IDENTICAL to the promoted binary (9e9094b1), the other five differ only where unrolled sums became loops and argc tests changed shape; all five sources landed on the NAS whole under CAS (nx_fs_write write expect=h<hash>) |
| 2026-09-05 | IM3 | retract | the intelmine.matrix IM3 note carried three stray pipes inside its prose (kind |
| 2026-09-05 | IM3 | measure | NAS builds from the hoisted sources: nx_installed_census BUILT 60472 B sha 7eb423bf (src_path names the target, src_stable=1) and PROMOTED prev=1 (laptop lane had built the same source to 51712 B: the known cross-lane band); nx_steam_reviews BUILT 552180 B sha af365865 which is BYTE-IDENTICAL to the already-promoted binary (nx_filehash cmp identical=1) although the source changed (three loops replaced unrolled sums; the laptop lane compiled the same source to 5582ad7a 552162 B) -- the signature the estate already recorded on 2026-09-05 as /api/build serving a stale cached artifact with an unchanged output sha across changed source; NOT promoted (a no-op) and named here so the next build of this target is checked by hash against its predecessor before it is believed fresh |
| 2026-09-05 | IM26 | land | GROW THE EMITTER (operator 2026-08-31): the .proposed renderer is prop_pass in nx_swcompare_lib, the compare BASE lib, called by both generators (nx_swcompare_matrix HTML band and api.json key, nx_swcompare_sota the same two sites) so all ten domains that already carry a .proposed file (gen, gameengine, companionchat, synthroom, graphics, charsim, softbody, browser, hapticcare, sharehub) inherit the MINED FROM THE FIELD band on their next regen with no per-domain work; rows prop |
| 2026-09-05 | IM26 | queue | NAS builds of nx_swcompare_lib consumers (nx_swcompare_matrix, nx_swcompare_sota) and nx_prop_pass_gate are NOT yet fired: nx_build_admit check reads VERDICT=QUEUE (load1_centi 3307 vs ceiling 1643, procs_blocked 4 of 8); recipe when it clears: nx_mgmt POST /api/build target=<t> (read src_path), nx_contentdiff live vs staged, /api/promote with expect_sha256, nx_offc_install <t>, then nx_restage for buildroot/_offc (the regen forks that third twin) and nishi_compare_regen; acceptance is the receipt prev= field moving and nx_page_verify on /compare/gameengine carrying the band |
| 2026-09-05 | IM3 | measure | the live .proposed rows on the NAS carry name == appid (gameengine.proposed: prop |
| 2026-09-05 | IM26 | land | NAS: /api/build nx_swcompare_matrix BUILT 379232 B sha 56997071 (src_path names the target, src_stable=1), nx_contentdiff live vs staged GREEN strict superset (+19 runs, every one the new band), PROMOTED prev=1, nx_offc_install fresh, nx_restage RESTAGED buildroot/_offc/nx_swcompare_matrix.elf 379232 B from the PROMOTED copy (the third twin the regen forks); nx_prop_pass_gate BUILT 78880 B sha 71d36ada, PROMOTED, REGISTERED, nx_offc_install installed=1, and run ON THE NAS through nx_job_run: 35 of 35 GREEN, rows_html=2 rows_json=2 big_rows=524 read_cap_bytes=65536 -- byte-identical values to the laptop run; nishi_compare_regen launched (job 1788632139) so every matrix domain with a .proposed file carries the band on this pass |
| 2026-09-05 | IM26 | measure | THREE BUILDS OF ONE SOTA SOURCE IN ONE HOUR, THREE SIZES: /api/build (this seat) 232064 B sha 9c7b2c5f, the build queue firing BQ-nx_swcompare_sota through nx_sov_build_run --build-only 198619 B sha 69ac40fb (TWIN HELD, installed nothing), and a stage of 208150 B sha 24ec855d written by a sibling between this seat's build and its promote -- /api/promote refused artefact-mismatch, LIVE UNTOUCHED. Source hash b843ef51 (50076 B) unchanged across all three, so the deltas are LANE FLAVOUR: nx_contentdiff of the 208150 stage vs live reads lost 186 runs = 15 source paths + 168 symbol names + 3 section names + 0 other (the -g class) while GAINING the band; this seat's own /api/build of the same source is a strict superset, which is the matched-lane control. Remedy taken: rebuild through /api/build (the lane live was built with) and promote that sha; the sibling's stage is not promoted by this seat |
| 2026-09-05 | IM27 | land | the proposer's census miss printed the appid as the name on every NAS-side run (the census is laptop-side until IM23), so the boards carried a number where a title belongs; fixed at the source: rm_json_name + rm_name_file_load in nx_reviewmine_lib (composing rm_key and rm_str, the decoder every review already goes through), sr_name + the name verb in nx_steam_reviews, and a platform-api fallback in nx_intelmine_propose that names its source in the receipt; nx_steam_reviews_gate 92 to 100 teeth GREEN on the laptop build (102459 B sha db7c6db5) with the decode of Café \"Portal\" 2 to UTF-8, the success:false body, the over-cap name and the absent and empty files as controls; LIVE on the laptop: nx_steam_reviews name 620 -> status=200 bytes=6726 name=Portal 2 wrote=9, then nx_intelmine_propose 620 -> name=Portal 2 name_src=platform-api and the new rows carry the title; sources landing on the NAS under CAS, NAS builds wait on admission |
| 2026-09-05 | IM27 | measure | the ten .proposed files already on the NAS keep their name == appid rows (dedupe is per appid+kind+term, and data is additive), so prop_pass renders those as an unresolved appid until a NAS-side nx_steam_reviews name <appid> run precedes the next proposer run; new rows carry the title |
| 2026-09-05 | IM27 | land | NAS: /api/build nx_steam_reviews BUILT 647608 B sha 24ad43ff (a prior 552180 B stage was banked as .prev, not overwritten), nx_steam_reviews_gate 117232 B sha 754b1c00, nx_intelmine_propose 62712 B sha e7910806 -- src_path names each target, src_stable=1; nx_contentdiff live vs staged GREEN strict superset on all three (+915, +159, +102 runs, every GAINED line the new verb, its receipts and the gate teeth); all three PROMOTED prev=1 (the gate promote answered 503 read-after-accept and HAD landed: the retry read NOTHING-STAGED with live_sha256 equal to the built sha) and nx_offc_install refreshed the runner twins; the gate run ON THE NAS through nx_job_run: 100 of 100 GREEN; LIVE ON THE NAS: nx_job_run nx_steam_reviews name 620 -> status=200 bytes=6726 name=Portal 2 wrote=9 and knowledge/reviews/steam/620.name reads Portal 2, so the next NAS-side proposer run for 620 names the title (name_src=platform-api) |
| 2026-09-05 | IM26 | measure | nx_swcompare_sota is now PROMOTED at 232064 B (the /api/build lane's size for this source, promoted by another seat after the stage race; source 50080 B, a 4-byte sibling edit on top of this seat's call sites) and the promoted binary carries the band (nx_txtscan count of the band heading in nx_swcompare_sota.elf = 1); nx_restage RESTAGED buildroot/_offc/nx_swcompare_sota.elf 232064 B from the promoted copy, so both generators the regen forks are the prop_pass generation; nishi_compare_regen relaunched under GRANT (job 1788633070) -- acceptance is nx_page_verify on /compare/gameengine carrying the MINED FROM THE FIELD band |
| 2026-09-05 | IM26 | measure | ACCEPTANCE ON THE LIVE SURFACE: the clock-beat regen (holder regen-1788632942, fork-freshness stamp checked=4 fresh=4 stale=0) republished /compare/gameengine at 559036 B; nx_page_verify GREEN (status 200, a11y-issues=0, broken=0) and nx_txtscan count of the band heading in sites/nishifamily/compare/gameengine/index.html = 1 -- the MINED FROM THE FIELD band is live, rendered from gameengine.proposed by prop_pass in the base lib; shipped, gate 35 of 35 on both hosts, referee grade and operator ACCEPT row still owed before the rung reads complete |
| 2026-09-05 | IM23 | land | RENDER-TIME TITLE (the honest half of IM23 that needs no census): the ten live .proposed files keep their appid-named rows because the writer dedupes and never rewrites, so prop_pass now reads the banked <appid>.name at render time from BOTH roots the generators run under (knowledge/reviews/steam/ for the mgmt daemon, ../knowledge/reviews/steam/ for the regen with CWD=buildroot) and says name_src=row, banked or appid per row -- a number stands in only when nothing banked it, and the page says so; nx_prop_pass_gate 35 to 41 teeth (a banked 620 renders Portal 2, an unbanked 999 stays an announced appid, JSON carries name_src), GREEN 41 of 41 on the laptop and on the NAS; lib landed under CAS (102163 to 104127 B), nx_swcompare_matrix BUILT 381072 B sha a960d963 (contentdiff: one reworded message lost, three runs gained), promote and sota rebuild in flight; with 620.name already banked on the NAS the gameengine band reads Portal 2 on the next regen |
| 2026-09-05 | IM23 | land | both generators carry the render-time title: nx_swcompare_matrix PROMOTED 381072 B sha a960d963 (contentdiff: the one reworded unresolved message lost, the two name roots and the new wording gained), nx_swcompare_sota PROMOTED 233912 B sha a3d328da (same single named loss; its first /api/build was refused on run-queue saturation and queued, the re-issue under GRANT landed), both nx_offc_install fresh and nx_restage from the promoted copies into buildroot/_offc; nx_prop_pass_gate PROMOTED 82392 B and 41 of 41 GREEN on the NAS; acceptance is the next regen showing Portal 2 beside 620 on /compare/gameengine |
| 2026-09-05 | IM23 | measure | ON THE LIVE SURFACE: the regen republished /compare/gameengine at 566928 B (from 560113) with the promoted generators; the docroot page now reads Portal 2 beside appid 620 (nx_txtscan count 1) and carries ZERO title-unresolved rows -- the banked name landed by nx_steam_reviews name 620 on the NAS is read at render time, so the appid-named .proposed rows show their titles without any data rewrite; shipped and measured, referee grade and operator ACCEPT row owed |
| 2026-09-05 | IM2 | measure | EVIDENCE AGAINST THE STANDARD (operator 2026-09-05: make sure this is all /compare benchmarked with evidence against standards): the pre-declared bar for mined aspects is SemEval-2014 Task 4 subtask 1 (ref semeval14, paper mirrored and pinned); the GOLD SETS are now banked through nx_research_fetch with provenance rows -- knowledge/fetched/cmp_intelmine_semeval14_rest_test_gold.seg 115810 B sha 9492e951 and cmp_intelmine_semeval14_lap_test_gold.seg 61851 B sha 991c33ca (the ABSA-PyTorch mirror of the official test gold, three lines per record: sentence with a $T$ placeholder, aspect term, polarity); the bench organ nx_absa_bench (watch row ORACLE SemEval-2014, symbol _ABSENT_) scores the miner's frequency-ranked vocabulary (the Hu-Liu frequent-term baseline, ref hu-liu-2004) against these gold terms and prints recall, precision and F1 in permil beside the published winning F1s, the ORACLE Steam score stays the platform oracle; nx_capsearch absa semeval aspect term bench f1 returned no incumbent (7400 considered, corpus_complete=1), so the organ is a build, not a retrieval miss. Same pass: intelmine.gates gained the nx_prop_pass_gate row (41 of 41 on the NAS), the IM27 row now cites the appdetails record [appdetails-vrhot], Appbot [appbot] and the community downloader [dsr], and the stray pipes in the INSTALLED SHIPS note that made the regen refuse the whole domain (row-index 39 read 12 fields) are commas -- the regen was IO-storm refused twice after, the clock beat republishes |
| 2026-09-05 | IM17 | measure | ABSA BENCH SUBTASK 1 MEASURED (nx_absa_bench: a unigram document-frequency baseline over the reconstructed SemEval-2014 test sentences, K = distinct gold terms, exact normalised term-set match, stopwords knowledge/reviewmine/stopwords.conf 1056 B): restaurants gold 520 distinct terms predicted 520 matched 126 P 242 R 242 F1 242 permil (content vocab 1717); laptops gold 389 predicted 389 matched 93 P 239 R 239 F1 239 permil (vocab 1171). Published bars from Table 4 of the mirrored paper (knowledge/fetched/cmp_intelmine_semeval14_paper.pdf sha f2c18570 188688 B, text via nx_pdf_text, ref semeval14-paper): restaurants winner DLIREC 84.01, laptops winner IHS RD 74.55, organisers dictionary baseline 47.15 and 35.64. Run on the laptop against byte-identical copies of the NAS gold (laptops 61851 B exact; restaurants 115808 of 115810 B, the trailing newline) because the NAS build was admission-refused under the I/O storm and queued (BQ-nx_absa_bench rc=0); the scorer is deterministic so the NAS run reproduces it |
| 2026-09-05 | IM17 | land | nx_absa_lib (the ONE SB1 scorer: composes rm_next_token through rm_mine_doc and rm_mine_rank, F1 = 2 inter over S plus G from counts), nx_absa_bench (CLI) and nx_absa_bench_gate (27 of 27 GREEN on the laptop: F1 arithmetic at exact permil, zero-prediction and no-gold controls, distinct-term dedupe, CRLF tolerance, case and whitespace normaliser, the unigram-cannot-match-multiword control, a non-vacuous end-to-end eval) landed in the laptop tree and on the NAS at runtime/ and buildroot/runtime/ (lib 11891, bench 3392, gate 6416 B). NAS builds queued BQ-nx_absa_bench and BQ-nx_absa_bench_gate behind admission; promote, register, offc_install, the intelmine.gates row and the NAS gate run follow when the queue fires. The ORACLE watch row now names runtime/nx_absa_bench.nx ab_eval with the measured F1 in its note. RUNG IM17 IS PARTIAL: subtask 1 scored, subtask 2 polarity accuracy not yet |
| 2026-09-05 | IM17 | lesson | THE GATE CAUGHT A MASKED CORPUS: the .seg sentence line replaces the aspect term with $T$, so the first predictor mined sentences that could never contain a gold term and matched 0 of 3 on the planted fixture; the fix reconstructs each sentence by substituting the term back before tokenising. A bench that scored the masked corpus would have published a confident zero. Also measured: a NAS build refused by admission is QUEUED (rc=0), not dead, and its .claim reads CLAIMED until the refusal body lands in .out; a 115 KB nx_fs read persisted as plain text while a 62 KB read persisted as a JSON-wrapped result, so a large read is not a file copy until its shape is checked |
| 2026-09-05 | IM17 | measure | REFEREES AFTER THE ORACLE FLIP: nx_swcompare_evidence intelmine verdict=MEASURED-HONEST present_axes=30 grounded=30 ungrounded=0 gates_green=4 of 4, the ORACLE row grounding on sym=ab_eval x2 at runtime/nx_absa_lib.nx (the first flip named runtime/nx_absa_bench.nx, which only CALLS ab_eval, and the ONE SYMBOL RULER correctly refused it SUBSTRING-ONLY rule=decl -- a watch row must name the organ that DECLARES the symbol, not a caller); nx_compare_refs_gate 44 of 44 GREEN fleet-wide with the new semeval14-paper row (files 109 rows 1561 pins matched 1495 of 1495 marks 3755 uncited 0, the earlier redirect-ratchet RED re-baselined by its lane at open=14). Both NAS builds are queued behind admission (BQ-nx_absa_bench, BQ-nx_absa_bench_gate, queue_launch_rc=0); the intelmine page (181849 B after the earlier publish) does not yet carry the F1 note, the regen relaunched after the lease holder |
| 2026-09-05 | IM17 | measure | ABSA BENCH SUBTASK 2 MEASURED (nx_absa_bench, accuracy over the gold aspect terms, two arms): restaurants records 1120 (positive 728 negative 196 neutral 196 other 0) majority arm positive 650 permil, lexicon arm 286 permil (defect and not-met cues vs exceed cues through the ONE tokenizer, 133 lexicon terms loaded, predicted positive 131 negative 15 neutral 974); laptops records 638 (341 128 169 0) majority 534 permil, lexicon 327 permil (predicted 42 54 542). Published Table 6 bars from the mirrored paper: winners DCU 80.95 restaurants, DCU and NRC-Canada 70.48 laptops, organisers baseline 64.28 and 51.37, majority 64.19 and 52.14. PROVENANCE CHECK FOR FREE: the gold class counts reproduce Table 2 of the paper exactly (RST-TE 728 196 196, LPT-TE 341 128 169) once the conflict class the .seg mirror drops is removed (14 and 16 records), so the mirrored gold IS the official test set minus conflict. FINDING: the lexicon arm sits BELOW the majority arm in both domains because the estate cue lexicons are Steam-review vocabulary and read 974 of 1120 restaurant sentences as neutral -- a domain-general sentiment lexicon and sentence-level orientation (rm_opinion_sent) is the rung, not a bigger game lexicon. Gate 49 of 49 on the laptop (SB2 teeth on planted lexicons, a no-lexicon control that predicts every record neutral, an absent-gold control that divides nothing). RUNG IM17 done-rule now MET mechanically (both subtasks printed with counts, the gate proves the scorer with a zero-prediction control); referee and operator acceptance still owed; the SB2 deltas shipped to the NAS sources under CAS so the queued BQ builds compile the complete organ |
| 2026-09-05 | IM17 | queue | WAITING ON THE BUILD QUEUE, RECIPE FOR THE NEXT SEAT: nx_absa_lib, nx_absa_bench and nx_absa_bench_gate sources are on the NAS at runtime/ AND buildroot/runtime/ hash-identical to the laptop-proven tree (lib 32ff1e2b 17972 B, bench 1f066abc 5417 B, gate 10cf927f 9998 B). Every /api/build this session was admission-refused at fire time (run queue 13 of 8 CPUs, an I/O storm before that) and absorbed as BQ-nx_absa_bench and BQ-nx_absa_bench_gate with queue_launch_rc=0; nx_orchestrate fires them on its first pass with build headroom (the gate's first queued fire already produced the SB1-only artifact 17d5bcf4 50127 B, byte-identical to the laptop build of that source, so the lane and the queue are proven). When knowledge/store/planrun-build-<target>- carries a result: (1) POST /api/promote target=nx_absa_bench&confirm=yes&expect_sha256=<sha> (2) /api/tools/register name=nx_absa_bench&elf=nx_absa_bench.elf&confirm=yes (3) nx_offc_install nx_absa_bench (4) nx_job_run nx_absa_bench /tmp/absa_rest.out knowledge/fetched/cmp_intelmine_semeval14_rest_test_gold.seg 0 restaurants and the laptops twin -- expect restaurants F1 242 SB2 majority 650 lexicon 286 and laptops F1 239 majority 534 lexicon 327 (deterministic, must reproduce the laptop numbers) (5) promote the gate, nx_job_run nx_absa_bench_gate /tmp/absa_gate.out, expect 49 of 49 GREEN, then append to knowledge/compare/intelmine.gates: nx_absa_bench_gate.elf |
| 2026-09-05 | IM17 | land | SHIPPED ON THE NAS: once the box calmed (load 10.2, 2 running) /api/build compiled both targets from the hash-verified sources (src_path buildroot/runtime, src_stable=1): nx_absa_bench 49456 B ff2a8df2, nx_absa_bench_gate 69640 B a45131d6 (mgmt-lane sizes; the queue's own sov-lane fire had produced 59833 B 2836552f, byte-identical to the laptop build of the same gate source). PROMOTED both with expect_sha256 (live hashes re-read and equal), REGISTERED both (callable), nx_offc_install both (installed=1). REPRODUCTION: nx_job_run nx_absa_bench over the NAS gold prints exactly the laptop numbers -- restaurants F1 242 (520 gold, 126 matched) SB2 majority 650 lexicon 286 (records 1120: 728 196 196), laptops F1 239 (389, 93) majority 534 lexicon 327 (638: 341 128 169) -- two build lanes, one output, so the number is a measurement of the gold and the method, not of a binary. nx_absa_bench_gate 49 of 49 GREEN on the NAS (pid 21710); intelmine.gates row appended; the compare beat republished /compare/intelmine (191879 B) carrying the SB1 and SB2 notes on the ORACLE row. The IM17 done-rule is met mechanically; referee panel grade and the operator ACCEPT row remain owed, and the honest reading stays: a weak baseline far below the published systems, the gap named as rm_aspects and rm_opinion_sent |
| 2026-09-06 | IM28 | land | matrix generator PROMOTED 708d15d7 455816 B and sota generator PROMOTED c9d4db7e 303136 B from buildroot/runtime, both carrying the plan_pass sotatarget and rungrole rendering and the Ladder verdict line; both refreshed on all three roots (serving root, nishihost _offc, buildroot _offc) so the regen forks the new emitters; ranker nx_compare_rank PROMOTED 0281d2e2 162128 B with the exit 6 LADDER-PARTIAL refusal; nx_barfresh CLI PROMOTED 764a5e04 37680 B (sotabar spelling); nx_ladder_gate PROMOTED 79fa8529, 42/42 GREEN on the NAS pid 15133, registered, _offc installed, roster-admitted via trial4 GREEN; nx_barfresh_gate re-run on the PROMOTED fc697e69: 48/48 GREEN pid 19316 |
| 2026-09-06 | IM28 | lesson | the first matrix promote e9f582f6 was read by the content ruler as a capability loss (the filter-chip run LOST) and was not one: a sibling seat had added a Dark chip and a dark-tag sentence to the same source, so the live run was MODIFIED not deleted; the discriminator was reading each LOST run against the source line (Dark present in source, absent in the banked binary) beside the ruler's own symmetry=BIDIRECTIONAL; the pre-change binary 4e99272e 422144 B is banked at knowledge/retired/nx_swcompare_matrix.elf.pre-ladder-4e99272e, verified by hash |
| 2026-09-06 | IM28 | queue | nx_ladder CLI build refused twice by build admission (I/O storm), re-issue paced a minute apart; regen job 1788715218 launched to publish the Ladder to SOTA sections; nx_page_verify and the evidence referee follow its completion |
| 2026-09-06 | IM28 | land | READ ON THE LIVE PAGE: /compare/intelmine after regen 1788715218 (four forks FRESH, 233 pages published) renders the Ladder verdict line: targets 3 (best in class 1, frontier 2), rungs 34 placed 34 (substrate 29, arm 2, contender 3), LADDERED, bars 2 attested FRESH against 2026-09; nx_page_verify GREEN 347481 B; nx_ladder CLI PROMOTED f30570b8 and registered, nx_ladder intelmine LADDERED and nx_ladder all 112 domains laddered=1 partial=0; the ranker's false LADDER-PARTIAL (rk_split NUL-terminated fields) is fixed at 1038b9be, so the board hands out work again |
| 2026-09-05 | IM17 | land | N-GRAM ARM SHIPPED (rung rm_aspects, first cut): nx_absa_lib gained a frequent n-gram extractor with Hu and Liu (2004) p-support redundancy pruning (bigrams beside unigrams through the ONE tokenizer, a stopword ends a phrase, min support 1 percent of sentences, a unigram inside a frequent bigram with p-support below 3 is a pruned fragment); nx_absa_bench prints ABSA-BENCH-NGRAM beside the unigram arm, gate 66/66 laptop AND NAS (pid 669, PROMOTED 39870409) with a repeated-bigram fixture, a p-support pruning proof, a beats-the-unigram-arm tooth and a support-above-frequency abstain control. MEASURED on the real gold (reproduced NAS == laptop): restaurants precision 429 recall 146 F1 218 permil (177 candidates, 20 frequent bigrams, 6 matched, 12 pruned, min support 11 of 1120); laptops precision 333 recall 185 F1 238 (216 candidates, 26 bigrams, 12 matched, 21 pruned, min support 6 of 638). READING: the n-gram arm nearly DOUBLES precision (242 -> 429 restaurants, 239 -> 333 laptops) and recovers multi-word gold terms the unigram arm structurally cannot (0 -> 6 and 12 matched bigrams), but the 1-percent support floor cuts recall so F1 is roughly flat -- the documented frequency-mining tradeoff. It is NOT SOTA and says so: the winners are CRF sequence labellers with POS, parsing and external lexicons, so the remaining gap is rung IM28 (nx_absa_seqextract), a supervised tagger, not a support knob tuned on the test set. rm_vocab_stop accessor added to nx_reviewmine_lib for the phrase-boundary check |
| 2026-09-05 | IM28 | land | SUPERVISED DICTIONARY TAGGER SHIPPED (IM28 first cut, the organisers' own SB1 baseline): nx_absa_lib gained a generic handle string set (hs_) and ab_dict_eval -- learn the aspect-term dictionary D from the TRAIN split, predict every n<=3 gram of the TEST sentences that is in D, score vs the test gold. nx_absa_bench takes a 4th arg (train.seg) and prints ABSA-BENCH-DICT; gate 75/75 laptop AND NAS with a planted train+test carrying a false positive (keyboard in dict not gold) and a miss (mouse in gold not dict) so precision and recall are each below one. MEASURED on the real SemEval gold (TRAIN + TEST, PROMOTED 14d36791 bench / 697221c4 gate, reproduced): restaurants F1 462 permil (P672 R351, 183 of 520 matched, dict 1202 terms) vs the paper's published dictionary baseline 471 -- reproduced within 2 percent, a strong correctness proof; laptops F1 473 permil (P672 R365, 142 of 389, dict 949) vs the published 356 -- EXCEEDS it (our n<=3 gram matching and normalisation catch more than the exact-span dictionary). This roughly DOUBLES the unsupervised arms (unigram 242/239, n-gram 218/238) and is the first result to reach the published baseline: supervision is the lever, exactly as the field says. STILL below the CRF winners (DLIREC 84.01, IHS RD 74.55) -- the gap now is the sequence model (POS + context + Viterbi), which is a further rung, and the honest ladder is unigram -> n-gram -> dictionary -> CRF. Train gold mirrored and pinned (rest 386645 B sha not-yet-a-ref, lap 271591 B fcc7574e); TRAIN sets are needed for D so they must be a .refs row (owed) |
| 2026-09-06 | IM28 | queue | SEQUENCE MODEL BUILT (IM28 the real SOTA gap): nx_absa_seq (LIB, 17848 B sha 96cdd0a7) = an AVERAGED STRUCTURED PERCEPTRON with Viterbi BIO decoding, integer weights only (nofloat) -- features word/prefix3/suffix3/prevword/nextword/has-digit shape/training-dictionary membership/bias hashed into one 2^20 weight table, BIO transitions with I only from B or I, lazy averaging; nx_absa_seqextract CLI <train.seg> <test.seg> [label]; nx_absa_seq_gate 12/12 GREEN on the laptop: the model LEARNS (tags the two always-aspect words and predicts both, F1 1000 on the planted set), is deterministic (identical F1 on a second run), and a model trained on nothing (every record skipped, zero weights) predicts nothing -- the first cut had an INVALID control (an unseen aspect word in a learned context WAS predicted: that is correct generalisation from prevword=the nextword=is, not a defect; replaced with the zero-training control). Smoke on the laptop's TRUNCATED train (1498 of ~3000 records, 163 KB read cap): restaurants P804 R150 F1 252 -- precision already high, recall bounded by the missing half of the train and 8 epochs still updating (1207 updates in epoch 8). All three sources landed in buildroot/runtime (byte-verified), NAS builds of gate and CLI in flight; the real-data number needs the FULL train on the NAS. Honest expectation: no POS tagger and no parse features, so this reaches the feature-based sequence class the winners used but not their feature set -- the number will be reported wherever it lands |
| 2026-09-06 | IM28 | land | SEQUENCE MODEL LIVE ON THE NAS AND MEASURED ON THE FULL SEMEVAL SPLITS: nx_absa_seq (LIB 20433 B sha 1d0af25e), nx_absa_seqextract (PROMOTED 12925751, 57776 B), nx_absa_seq_gate (PROMOTED 0bc2c81c, 73416 B) -- gate 16/16 GREEN on the NAS (pid 15392). FIRST full-train run: restaurants F1 294 (P796 R180) laptops 340 (P765 R218) with 2915 of 3607 sentences STILL UPDATING in epoch 8 -- not converging. DIAGNOSIS from the receipt, not a guess: a .seg emits ONE record per aspect, so a sentence with three aspects appears three times each labelling the other two O -- contradictory supervision a sequence model cannot settle on. FIX: consecutive records that reconstruct to the same sentence are merged into ONE example carrying every aspect (sp_same_sent / sp_acc_or / sp_flush), proven by a gate fixture (two records of one sentence fold into one training sentence and the model learns both). MEASURED after the merge: restaurants F1 448 (P798 R311, 162 of 520, 2018 merged sentences, epoch-8 updates 658) laptops F1 429 (P721 R305, 119 of 389, 1491 sentences, 464 updates). The sequence arm now matches the dictionary arm (462/473) with far higher precision and lower recall; both supervised arms sit at the published-baseline tier. REMAINING GAP TO THE WINNERS (840/745): POS and parse features plus a CRF objective -- the estate has no POS tagger, so that is the next rung, not a tuning step. Cheap next experiments before that rung: the UNION of the perceptron (high precision) and dictionary (high recall) predictions, wider context features (prev2/next2, word-pair conjunctions), and more epochs (updates are still a third of sentences) |
| 2026-09-06 | IM28 | land | SEQUENCE MODEL v3 LIVE (nx_absa_seq 24804 B sha a1848442, nx_absa_seqextract PROMOTED fb11ee0d 63376 B debug flavour, nx_absa_seq_gate PROMOTED efcc71b1 20/20 GREEN on the NAS pid 16158): three levers shipped in one cycle and measured on the full SemEval splits. (1) 16 epochs (was 8): epoch-16 updates 170 of 2018 sentences restaurants and 128 of 1491 laptops -- converged. (2) the standard sequence-tagging feature set added to the 8 base features: prev2 and next2 words, prev+cur and cur+next conjunctions, a 4-char suffix family (13 features hashed into one weight table). (3) the UNION arm: perceptron predictions unioned with the training-dictionary tagger's n<=3-gram hits, scored as its own line so the perceptron-only number stays comparable. MEASURED: perceptron-only restaurants F1 454 (P786 R319) laptops 448 (P773 R316); UNION restaurants F1 502 (P646 R411, 214 of 520) laptops 500 (P640 R411, 160 of 389). The union is the estate's best number on both domains: above the dictionary arm (462/473) and above the paper's published organisers baseline (471/356) on both. Gate gained union teeth (never loses a perceptron hit; an untrained model contributes nothing, every union hit is the dictionary's). SHIP LESSON: the mgmt build lane stalled twice on this target (per-target lease, receipts lagging 10 min, one admission refusal absorbed to BQ), so the CLI shipped through the sovereign lane; its release-flavour build was REFUSED CAPLOSS 354 permil against the mgmt-built live -- nx_contentdiff partitioned all 78 lost runs as 9 source paths + 66 symbol names + 3 section names with lost_other=0 and prescribed --debug; the debug rebuild (subprograms=72) promoted without any flag. REMAINING GAP to the winners (840/745): POS and dependency features plus a CRF objective; the estate has no POS tagger, so that is the next rung |
| 2026-09-06 | IM28 | retract | THE COMPARATOR WAS THE WRONG RULER: every SB1 number this board published before this row was scored on DISTINCT-term set overlap (each gold term counted once), while the paper (Pontiki et al. 2014 eq. 1-2) scores per OCCURRENCE across the test sentences -- a term that is the aspect of forty sentences is forty gold items. A sequence model that gets frequent terms right is systematically under-scored by the set ruler, so 502/500 vs 840/745 compared two different metrics. The set lines are KEPT (they are a harder, distinct-vocabulary view) and the paper's metric is now published beside them as ABSA-SEQEXTRACT-OCC and -UNION-OCC (nx_absa_seq scores each merged test sentence once: gold = that sentence's aspect terms, predicted = spans in that sentence; gate fixture: one term as the aspect of two sentences = 1 distinct term, 2 occurrences, 27/27 GREEN on the NAS pid 22083) |
| 2026-09-06 | IM28 | measure | ON THE PAPER'S PER-OCCURRENCE METRIC, full SemEval TRAIN+TEST, PROMOTED 8d924e46: restaurants perceptron F1 535 (P801 R401, 449 of 1117 gold occurrences over 615 sentences) and UNION 619 (P550 R708, 791 matched of 1436 predicted); laptops perceptron 467 (P678 R356, 226 of 634 over 418 sentences) and UNION 502 (P466 R544). Versus the winners on the same ruler: restaurants 619 of 840 (74 percent), laptops 502 of 745 (67 percent); versus the organisers baseline 471/356: above on both. The set-metric lines are unchanged (454/448 perceptron, 502/500 union), which proves the rewrite left that path intact. Honest signal in the laptops numbers: the union's precision (466) is dragged by the dictionary over-predicting, so the perceptron alone is the more precise arm there -- a validation-split-tuned combination is the next cheap lever; the winners' remaining margin is POS and dependency features plus a CRF objective (no tagger in the estate yet) |
| 2026-09-06 | IM28 | land | DICTIONARY RELIABILITY + THE MAJORITY RULE (nx_absa_seq 36932 B sha ce9aac8c, nx_absa_seqextract PROMOTED 9ced9326 78224 B, nx_absa_seq_gate PROMOTED 0940840a 31/31 GREEN on the NAS pid 27487; nx_absa_lib gained hs_slot_raw so a caller can keep per-term counters beside the handle set): the training dictionary is every term that was EVER an aspect, including words that are mostly not aspects in the training data itself, which is where the union's laptop precision of 466 came from. The train split already knows each term's reliability -- sentences it appears in versus times it is gold, both counted per merged sentence -- so it is now (a) a GRADED feature the perceptron weighs (reliability quantised to fifths) instead of a binary in-dictionary bit, and (b) the MAJORITY RULE for the union: a dictionary hit is admitted only if the term was an aspect in at least half its training occurrences, a derived bar not a tuned one (gate fixture: a term that is the aspect of one sentence and a plain word in three is excluded, an always-aspect term admitted). MEASURED on the paper's per-occurrence metric, full train: restaurants UNION F1 619 -> 679 (P 550 -> 706, R 708 -> 653; 1068 of 1202 dictionary terms pass), laptops UNION 502 -> 533 (P 466 -> 609, R 544 -> 474; 828 of 949 pass). The perceptron-only lines did NOT benefit from the graded feature: restaurants 535 unchanged, laptops 467 -> 456, within noise -- recorded, not hidden. Versus the winners on their own ruler: 679 of 840 (81 percent) and 533 of 745 (72 percent) |
| 2026-09-06 | IM28 | queue | NEXT RUNGS, measured order of value: (1) a POS tagger -- nx_capsearch over 7433 organs (corpus_complete=1) finds NO tagger and NO treebank in the estate, so this is a licensed DATA asset (a UD English treebank, CC BY-SA, mirrored with its LICENSE beside it under knowledge/) plus the same averaged-perceptron engine trained on it, then POS features into nx_absa_seq; (2) dependency features (head word and relation, DLIREC's main exceed) from the same treebank; (3) a CRF objective; (4) in-domain word clusters. Each is a rung with its own gate; none is tuning |
| 2026-09-06 | IM28 | lesson | FLEET REFS GATE READ RED 43/44 AFTER THIS LEG AND THE FAILING TOOTH IS NOT THIS DOMAIN: cite-marks-resolve-every-one fails on three UNRESOLVED-MARK rows in buildroot/knowledge/compare/dcc.plan (keys unirig, rignet, magicarticulate) -- a sibling lane's auto-rig work whose cite marks landed before its .refs rows (its memory index says those refs went to modding.refs, but marks resolve per domain). intelmine reads uncited_keys=0 and every one of its marks resolves; the evidence referee deferred this pass on storm budget (its last full pass read MEASURED-HONEST with the gate executed). Named for the dcc lane, not edited: never touch another seat's board unilaterally |
| 2026-09-06 | IM28 | measure | THE ESTATE HAS A POS TAGGER: nx_postag (LIB, greedy averaged perceptron over the 17 Universal POS tags, integer weights, 12 hashed features: bias, word, suffix, first char, previous two predicted tags, previous tag+word, previous and next word and their suffixes, has-digit; a CoNLL-U reader that skips comments, multiword ranges and empty nodes and tolerates CRLF; pt_tag_stream tags any token stream) + nx_postag_eval (PROMOTED 81be3fd3 35696 B, registered) + nx_postag_gate 20/20 GREEN on the laptop (NAS build in flight). DATA ASSET, license beside it: UD English EWT (CC BY-SA 4.0) mirrored as knowledge/fetched/cmp_intelmine_ud_ewt_train.conllu (15034493 B sha d68e0612), _test.conllu (1900101 B sha fa024f43) and _LICENSE.txt (20014 B) with provenance rows. MEASURED on the NAS: token accuracy 927 permil on the EWT test split (23286 of 25094 tokens, 2077 sentences) after 5 epochs over 12544 sentences / 204578 tokens, 0 unknown gold tags -- inside the published band for a feature-based greedy tagger on EWT UPOS (roughly 93 to 95 percent); 8003 updates in the last epoch say more epochs would add a little. This closes the capability gap named on the previous row: every SemEval-2014 winner used POS features and the estate had no tagger |
| 2026-09-06 | IM28 | land | POS FEATURES WIRED INTO THE SEQUENCE MODEL (nx_absa_seq 40235 B sha 8f8c9f15: sp_set_treebank, the tagger trained once in sp_eval, every sentence tagged after tokenising at both sites, five hashed POS families -- this, previous and next tag and the two tag bigrams -- SP_NFEAT 14 to 19; nx_absa_seqextract PROMOTED e80bb6ff 93720 B with a fourth argument, the treebank; nx_absa_seq_gate PROMOTED 918e2247 112240 B, 36/36 GREEN on the NAS pid 6605 with five POS teeth: off by default, the tagger trained on the planted treebank's eight tokens, on when set, still learns both aspects, F1 stays high). The treebank rows are pinned as data: [ud-ewt-train] the training split the tagger learns from, [ud-ewt-test] the held-out split its 927 permil is read on, [ud-ewt-license] CC BY-SA 4.0 beside the bytes. SHIP LESSON: three writes returned 503 read-after-accept and every one HAD landed (the artifact hashes decided, never the reply); the box was in an I/O storm (procs_blocked 8 of 8, load 19.9 on 8 cpus) and the mgmt builds took twelve minutes but compiled from the verified sources (src_path and src_sha256 checked on the receipts) |
| 2026-09-06 | IM28 | measure | POS FEATURES ON THE FULL SEMEVAL SPLITS, the paper's per-occurrence metric, tagger trained on 204578 EWT tokens: restaurants UNION F1 679 -> 689 (P 706 -> 714, R 653 -> 666; 744 matched of 1117 gold occurrences, 1041 predicted), perceptron-only 535 -> 548 (P 814, R 413); laptops UNION 533 -> 538 (P 609 -> 612, R 474 -> 481; 305 of 634), perceptron-only 456 -> 470 (P 680, R 359). The set-metric lines moved the same way (restaurants 454 -> 468 perceptron, 502 -> 519 union; laptops 448 -> 460, 500 -> 503). A real gain on both domains and in both arms, and a modest one, which is what the literature says POS alone buys; versus the winners on their own ruler: 689 of 840 (82 percent) and 538 of 745 (72 percent). The remaining margin is the parse features (DLIREC) and the CRF objective |
| 2026-09-06 | IM28 | land | THE ESTATE HAS A DEPENDENCY PARSER: nx_depparse (LIB, arc-standard transitions SHIFT / LEFT-ARC(rel) / RIGHT-ARC(rel) with a greedy averaged perceptron over the actions, integer weights, 24 Zhang-and-Nivre core features, the static oracle, non-projective training sentences skipped and counted, a single-root constraint, relation labels interned in first-seen order, dp_parse_stream for any tagged token stream) reading the same CoNLL-U treebank through nx_postag's reader, which grew the HEAD and DEPREL columns additively (one reader, two organs; the tagger gate stayed 20/20). nx_depparse_eval PROMOTED 774ee104 51438 B (tagger first, the parser reads ITS tags on both splits: one tag generator, no gold-tag optimism); nx_depparse_gate 33/33 GREEN on the laptop (reader heads and base names, label table, learns a planted grammar to UAS and LAS 1000, converges, deterministic, skips the planted crossing-arc sentence, stream parse identical, an untrained parser scores 0) and promoted 8affc1ae 71760 B. nx_capsearch over 7437 organs found no parser (every hit was the software-dependency homonym); the word-cluster rung has an incumbent to compose instead (nx_ppmi_lib, nx_embed_train) |
| 2026-09-06 | IM28 | queue | PARSE FEATURES WIRED IN SOURCE, MEASUREMENT PENDING: nx_absa_seq 44211 B sha 8b10ea29 (the parser trained after the tagger on the same treebank, every sentence parsed after tagging, five hashed families: relation, head word, head tag, relation+own tag, the relations of the outermost dependents; SP_NFEAT 24; sp_set_parse(0) is the ablation switch and the CLI's fifth argument noparse drives it), gate 42/42 GREEN on the laptop with parse and ablation teeth; NAS builds through the sovereign lane in flight. Next: promote, run both domains with the treebank, and publish the POS-plus-parse number beside the POS-only one -- an ablation on one binary, not two build generations. After that: the parser's own UAS on EWT test (nx_depparse_eval), then the CRF objective and word clusters |
| 2026-09-06 | IM28 | measure | THE PARSER'S OWN NUMBER, held-out UD English EWT test through the PROMOTED nx_depparse_eval (pid 2412): UAS 804 permil (20188 of 25094 tokens), LAS on the base relation names 763 (19155 of 25094), over 2077 test sentences, with the tagger's predicted tags (927) on both splits; trained 5 epochs on 12544 sentences / 204578 tokens, 287 non-projective sentences skipped by the static oracle, 36 relation labels interned, 17777 updates in the last epoch. HONEST READING: this sits BELOW the middle-to-high eighties a feature-based greedy arc-standard parser reaches on EWT -- the last-epoch update count says it has not converged at 5 epochs, the static oracle discards 2.3 percent of the training trees, and a dynamic oracle or beam would lift it; all three are named rungs, none is tuning. It is enough to produce parse features for the aspect model, which is what this rung needed; the parser's own SOTA gap is journaled beside it, not folded into the aspect number. nx_depparse_gate 33/33 GREEN on the NAS (pid 3289) and nx_postag_gate 20/20 GREEN on the NAS (pid 5405) both carry executed-evidence rows now |
| 2026-09-06 | IM28 | measure | THE PARSE-FEATURE ABLATION ON ONE BINARY (nx_absa_seqextract PROMOTED 61d518aa 119112 B, the parse-wired model, nx_absa_seq_gate PROMOTED 209760ac 42/42 GREEN on the NAS): four runs on the full SemEval splits with the same treebank, the paper's per-occurrence metric. Restaurants: tagger only 687 union / 547 perceptron; tagger PLUS the 5-epoch parser (UAS 804) 683 / 542. Laptops: tagger only 528 / 452; tagger plus parser 521 / 454 union-and-perceptron. Beside them the previous build generation with the tagger alone read 689 / 548 and 538 / 470, so laptops carries about ten permil of build-to-build noise (the constant parse bytes shift the hash slots) while restaurants is stable to two. VERDICT: parse features from this parser do not help and lean negative on both domains -- DLIREC's exceed came from a much stronger parser (Stanford, low nineties UAS) and dependency-PATH features to opinion words, not from head-word features off an 80-UAS greedy parser. DECISION, measured not guessed: the parser stays a MODE (the CLI's fifth argument parse) and the default with a treebank is the tagger alone -- the arm that measured best; never a strip, the capability ships and is gated. NEXT EXPERIMENT, principled not tuning: the parser has not converged (17777 last-epoch updates at 5 epochs), so DP_EPOCHS 5 -> 12 and re-measure its UAS and the parse arm; then the dependency-path feature family the winners actually used |
| 2026-09-06 | IM28 | land | THE PARSER DEFAULT FLIPPED OFF, MEASURED NOT GUESSED: nx_absa_seq 44608 B sha ded50909 (sp_set_treebank now leaves the parser off, sp_set_parse(1) adds it), nx_absa_seqextract PROMOTED e74a71aa 119432 B (fifth argument parse adds the parser, noparse spells the default), nx_absa_seq_gate 42/42 GREEN on the laptop with the default teeth renamed (parse on when the parse mode is set, off with a treebank unless the mode is set, the model still learns either way). The gate promote was REFUSED CAPLOSS 19 permil (5 of 252 live tokens) and the flag was passed only after nx_contentdiff enumerated the five lost runs as the five renamed tooth names -- parse-features-on-when-a-treebank-is-set, parse-features-off-by-default-without-a-treebank, parse-switch-off-keeps-the-tagger, parse-switch-off-drops-the-parser, parse-switch-off-the-model-still-learns-both-aspects -- each with its GAINED replacement (symmetry BIDIRECTIONAL, lost_other=5, a rename). The guard was right to ask; the answer is written here beside the flag. Runs in flight on the promoted binary: the parse mode with the 12-epoch parser on both domains, and the parser's own 12-epoch UAS |
| 2026-09-06 | IM28 | measure | THE PARSER AT 12 EPOCHS (nx_depparse_eval PROMOTED 54d5a27f, pid 13420): UAS 805 permil (20218 of 25094) and LAS-base 765 on the held-out EWT test, against 804 and 763 at 5 epochs, with last-epoch updates down from 17777 to 7181. VERDICT: epochs were NOT the bottleneck -- this design plateaus near 80 UAS. The gap to the middle-to-high eighties is structural, three named parts: (1) a greedy STATIC oracle that discards 287 non-projective trees and never learns to recover from its own errors (a dynamic oracle is the published fix), (2) 24 of Zhang and Nivre's 72 templates (no third-order stack context, no valency, no label-set features), (3) predicted tags at 927 permil feeding every tag feature (parsers lose two to three UAS points between gold and predicted tags at this accuracy). Each is a rung; the tagger's accuracy is the shared root of both the POS and the parse arms, so it is the first one to lift |
| 2026-09-06 | IM28 | measure | THE PARSE MODE WITH THE 12-EPOCH PARSER, same promoted binary (e74a71aa), paper metric: restaurants union 681 / perceptron 538 against 687 / 547 with the tagger alone -- still negative; laptops 533 / 463 against 528 / 452 -- inside that domain's ten-permil noise. The decision stands and is now measured twice: the parser is a mode, the default is the tagger alone. nx_absa_seq_gate 42/42 GREEN on the NAS (pid 24331) on the build that carries that default |
| 2026-09-06 | IM28 | queue | THE TAGGER RUNG, authored and gate-proven on the laptop, measurement on EWT next: nx_postag grows the three standard features it lacked (the tag bigram, the word two back, the word two ahead -- 15 hashed families), a DETERMINISTIC per-epoch shuffle (Fisher-Yates over a small LCG seeded by the epoch, so two runs still agree and the determinism tooth holds; epoch 0 stays in file order and records every sentence start) and 8 epochs (5 left 8003 last-epoch updates). nx_postag_gate 20/20, nx_depparse_gate 33/33 and nx_absa_seq_gate 42/42 all GREEN on the laptop against the new lib. Accept rule, pre-declared: the tagger's held-out EWT accuracy must EXCEED 927 permil or the change does not ship to the aspect model; if it does, the POS-only arm is re-measured on both domains and published beside 689 / 538 |
| 2026-09-06 | IM28 | measure | THE TAGGER RUNG MET ITS BAR: nx_postag_eval PROMOTED 7a961c85 (pid 9361) reads 931 permil on the held-out EWT test (23374 of 25094 tokens, 88 more than the 927 of the 12-feature 5-epoch tagger) with last-epoch updates 8003 -> 4212; accept rule EXCEED 927, met, so the library ships to the aspect model. Honest scale: four permil, the kind of gain the three standard features and a shuffle buy a perceptron tagger; the ceiling of this design on web text is the low nineties, and the tagger stays the shared root of both arms. Rebuilds of the aspect CLI and gate against the new library are in flight; the POS-only arm is re-measured next |
| 2026-09-06 | IM28 | measure | THE BETTER TAGGER DID NOT MOVE THE ASPECT MODEL: nx_absa_seqextract PROMOTED 53cebf5c 121584 B (the 931-permil tagger inside, parser off by default), full SemEval splits, paper metric: restaurants union 683 / perceptron 542 (P 710 R 658; 735 of 1117) and laptops 532 / 457 (P 604 R 476; 302 of 634), against 687 / 547 and 528 / 452 from the previous build of the same design -- minus four and plus four, inside the noise band this board has measured at five to ten permil. The four-permil tagger gain is invisible downstream: the aspect perceptron is saturated with respect to tag quality at this level. The best figures this board has published stay 689 / 538 (build e80bb6ff, 19 features); the served binary reads 683 / 532 and both are the same number within noise. Every gate is GREEN on the served binaries built against the new library: nx_postag_gate 20/20 (pid 15712, aa3e5bf5), nx_absa_seq_gate 42/42 (pid 18927, 5860bbc5), nx_depparse_gate re-run in flight (72889f6f). WHERE THE GAP IS NOW, stated without optimism: 689 of 840 and 538 of 745 with in-estate data only; the winners' remaining margin is a CRF objective (one to two points in the literature), external in-domain unlabeled text for word clusters and name lists (the DLIREC ablation's largest single gains, three to five points, from Yelp data the estate has not licensed or fetched), and the neural class (BERT-family systems read 87 to 90 on laptops). Each is a rung with its own data question; none is a parameter to turn |
| 2026-09-06 | IM28 | lesson | THE EVIDENCE REFEREE ABSTAINED THREE TIMES THIS LEG (nx_swcompare_evidence intelmine: HEAVYIO running=2 width=4 storm_budget=3, then running=4 width=4 storm_budget=3, then running=3 width=4 storm_budget=0 -- DEFERRED each time, the estate's heavy-I/O budget spent by other lanes), so its MEASURED-HONEST verdict for this leg is NOT re-read; the last full pass read MEASURED-HONEST with the gate executed, and every row added since carries a served run named by pid and elf. The fleet refs gate did run: 44/44 GREEN, marks 3854 all resolved, uncited_keys 0, the three treebank refs pinned and cited. A referee that abstains on budget is the right behaviour and it is written here rather than retried into the same budget; the next quiet pass re-reads it |
| 2026-09-06 | IM28 | queue | THE SHUFFLE RUNG FOR THE ASPECT MODEL, authored, accept rule PRE-DECLARED BEFORE THE RUN: nx_absa_seq trains sixteen epochs in FILE ORDER, the tagger's lesson says a perceptron trained in file order learns the file's order. Epoch 0 now records where every merged-sentence group starts (unusable groups too, so the count is a census not a tally) and epochs 1 to 15 walk the groups in a fresh deterministic permutation through nx_postag's pt_permute -- ONE shuffle shared by the tagger and the aspect model, seeded by the epoch, so two runs still agree. Gate teeth: groups equal the merged sentences (six), the merge fixture reads one group, the empty train reads two groups with zero usable records; the determinism tooth runs the whole schedule twice. ACCEPT RULE: the shuffled model ships as the default if the paper-metric union F1 rises on BOTH domains against the served same-design build (683 restaurants, 532 laptops); if it rises on one and falls on the other, or moves either by less than the ten-permil noise band, the numbers are published and the order stays a measured non-result -- no cherry-picking a domain |
| 2026-09-06 | IM28 | lesson | THE REGEN WAS REFUSED BY THE I/O STORM (nishi_compare_regen 1788692222: REFUSED-IO-STORM procs_blocked=10 ncpu=8, exit 4) -- the same storm line the build gate refuses on, and the organ says it plainly: a regen started now publishes nothing sooner. The compare beat defers itself through clock_heavy.conf and republishes this board's new rows (three matrix rows, three roster rows, the refs and eleven log rows) on its first pass with headroom; a seat that spun on the refusal would only deepen the storm. The data is on the board now; the page follows the beat, and nx_page_verify is owed after it |
| 2026-09-06 | IM28 | measure | THE SHUFFLE RUNG MEASURED AGAINST ITS PRE-DECLARED RULE: nx_absa_seqextract PROMOTED b79b0a83 125216 B (epochs 1 to 15 in a deterministic per-epoch shuffle; 2018 restaurant and 1500 laptop groups recorded, the nine laptop groups beyond the 1491 usable sentences being records whose term is not a contiguous token run), nx_absa_seq_gate 45/45 GREEN on the NAS (pid 22950). Paper metric, full splits: restaurants union 679 / perceptron 533 against 683 / 542 in file order; laptops 536 / 465 against 532 / 457. One domain down four, one up four, both inside the ten-permil band -- the rule said both must rise, so the shuffle does NOT become the default. It ships as a MODE beside the parser (the CLI's mode tokens now read parse, noparse, shuffle), the default stays file order, and the result is journaled as the measured non-result it is: the averaged perceptron's averaging already removes most of the order sensitivity the tagger showed, and this model's variance is build-to-build, not order-to-order. Best published figures unchanged: 689 restaurants, 538 laptops |
| 2026-09-06 | IM28 | land | THE SHUFFLE SHIPPED AS A MODE, THE DEFAULT RESTORED TO FILE ORDER: nx_absa_seq 49333 B sha 19c022c4 (sp_set_shuffle, off unless asked; epoch 0 still records the groups so the census stays in the receipt), nx_absa_seqextract PROMOTED 6aeda96c 125936 B (every argument from the fifth on is a mode token: parse, noparse, shuffle), nx_absa_seq_gate PROMOTED fb281996 145504 B, 49/49 GREEN on the NAS (pid 14353) with four more teeth: shuffle off by default, on when the mode is set, the model still learns, and the seeded permutation gives the same F1 twice. Three modes now ride one binary -- parser, shuffle, and the tagger by treebank -- each measured on the full splits before its default was chosen, and each default is the arm that measured best. The regen was re-issued under a GRANT (procs_blocked 3, running 4) and nx_page_verify follows it |
| 2026-09-06 | IM28 | land | PUBLISHED: nishi_compare_regen 1788693326 (ADMIT, storm_budget 4, forkchecked 4 fresh 4) republished this board -- api.json 53679 -> 55827 bytes, index.html 247616 -> 258899 bytes, the prev= fields moving being the receipt that something was published -- after a run of about twenty-six minutes under the loaded array (its band is eight to fourteen; no generator sat in D-state, it was slow not stuck). nx_page_verify on the live page read VERDICT=GREEN at exactly 258899 bytes (status 200, zero broken assets, zero accessibility issues), so the verified page IS the republished one. The regen's fleet verdict was RED for ONE domain, performersearch (three unevidenced Best cells on its sota field), a sibling lane's board that stays on its previous page by the regen's own rule and is named here, not edited. Everything this leg shipped is now on the surface: the POS tagger and its 931, the parser and its 805, the POS gain, the parse and shuffle ablations as measured non-results, the three executed-evidence rows and the three pinned treebank refs |
| 2026-09-06 | IM28 | queue | THE WORD-CLUSTER RUNG, authored, accept rule PRE-DECLARED BEFORE THE RUN: the winners' other lever was name lists and Brown clusters from in-domain text (DLIREC's largest single gains). The estate's own index was probed for in-domain review text (95802 hits for restaurant terms, 48277 for laptop terms, the top pages general and multilingual, coverage incomplete by the index's own note) -- a filtering rung of its own, not a corpus today. What the estate does own is knowledge/index/semppmi_v1.bin (43383896 B, sha be39c91f, built by nx_semppmi_build) with ONE loader and cosine, nx_ppmi_lib. New LIB nx_wordclust composes it: k-medoids over PPMI cosine at three granularities (32, 128, 256), medoids seeded by the training split's word frequencies, three deterministic rounds, a word unseen at build time assigned on demand to its nearest medoid, a word the model does not know reading -1; nx_wordclust_gate 25/25 GREEN on the laptop on a six-word planted model written in the loader's own format (synonym pairs grouped, pairs separated, on-demand assignment, determinism, a missing model fails closed). Wired into nx_absa_seq as five hashed families (this token at three granularities, the neighbours at the middle one), a MODE off by default (sp_set_clusters, the CLI token clusters). ACCEPT RULE: the clustered model becomes the default only if the paper-metric union F1 rises on BOTH domains against the served file-order build (683 restaurants, 532 laptops) by more than the ten-permil noise band on at least one; otherwise the numbers publish as a measured result and the mode stays off. The honest prior: clusters from a GENERAL corpus are weaker than the winners' in-domain ones, so the expected gain is below theirs |
| 2026-09-06 | IM28 | measure | CLUSTERS on the full splits, one binary (nx_absa_seqextract PROMOTED df0a209d, NAS pids 27381 restaurants and 27425 laptops, treebank plus the clusters token), against the served file-order build 683 restaurants and 532 laptops: restaurants union-occ 680 and perceptron-occ 534 (was 542), vocabulary 3624 with 2911 in the model; laptops union-occ 543 and perceptron-occ 476 (was 457), vocabulary 2977 with 2570 in the model. Under the rule declared before the run (a rise on BOTH domains, beyond ten permil on at least one) the mode stays OFF: laptops rose 11 union and 19 perceptron, restaurants fell 3 and 8 inside the band. Published as a measured result, not tuned into one [semeval14-paper] |
| 2026-09-06 | IM28 | land | nx_wordclust LIB 6c52cc23 (15261 B) composing nx_ppmi_lib; nx_wordclust_gate 9ee0e951 built 52509 B, PROMOTED bac540d6, REGISTERED, _offc refreshed, 25/25 GREEN on the NAS pid 26913; nx_absa_seq 53801 B d0deb88b (SP_NFEAT 24 to 29, five cluster families, sp_set_clusters, out slots 37 to 39, SP_O_N 40); nx_absa_seqextract 7142 B 1698b92e built 147960 B PROMOTED df0a209d (token clusters reads knowledge/index/semppmi_v1.bin); nx_absa_seq_gate 18010 B 390517dd built 171272 B PROMOTED 276e3069, 54/54 GREEN on the NAS pid 26945 with five cluster teeth; organ_kind.conf declares nx_wordclust_gate oracle; evidence rows on intelmine.gates for both gates; matrix row sp_set_clusters. All five sources byte-identical on the laptop and the NAS |
| 2026-09-06 | IM28 | lesson | THE COVERAGE NUMBER IS THE FINDING. The general PPMI model knows 863 permil of the laptop training vocabulary and 803 permil of the restaurant one, and the clusters helped exactly the domain the model covers better. That is the winners' in-domain-text lever restated as a measurement, and it says the next unit of gain is a corpus, not a tweak: K, the iteration count and the medoid sample were declared once with their reasoning and are deliberately not tuned against the test split, because a number moved to fit a split is a magic number wearing a result |
| 2026-09-06 | IM28 | queue | IN-DOMAIN CLUSTERS: build a domain PPMI model with nx_semppmi_build over review text the estate is licensed to hold (the corpus decision is the operator's; Amazon Reviews 2023 laptops is the lawful candidate already named on this plan), pass it through sp_set_clusters and re-run both domains under the same rule. Recipe, one call per domain: nx_job_run nx_absa_seqextract <out> <train.seg> <test.seg> <label> <treebank.conllu> clusters; the model path is SE_CLUST_MODEL, so the first edit of that rung is a CLI flag naming the model file |
| 2026-09-06 | IM28 | queue | THE CRF OBJECTIVE, authored and gate-proven on the laptop, accept rule PRE-DECLARED BEFORE THE NAS RUN: both winners trained a linear-chain CRF and the literature's controlled comparisons put the CRF a point or two over a structured perceptron on the same features. The estate had no CRF and no fixed-point log-domain arithmetic (nx_capsearch, 7462 organs), so both are built from the first byte: nx_logadd_lib (Q10 nats, e^(-1/S) from its Taylor series, the powers by recurrence, softplus through the ONE integer logarithm nx_intlog, the horizon derived by scanning the table, minus infinity the decoder's own sentinel; nx_logadd_gate 29/29 on hand-derived known answers) and a CRF MODE inside nx_absa_seq: the same hashed features, transition table, lazy averaging and Viterbi decoder, weights read as Q10 nats, forward-backward in the log domain with the decoder's hard masks, one stochastic-gradient step per merged sentence w += eta (empirical - expected) from the token and pair marginals. The step is derived and not tuned: eta_0 = 1/4 nat per unit gradient (four full-confidence errors in an epoch reach the perceptron's one-vote step), decayed as eta_0/(1+epoch), averaging as the regulariser. nx_absa_seq_gate 65/65 on the laptop: off by default, likelihood rises, marginals partition to one within four units, no partition below its gold path, learns, deterministic, trained on nothing predicts nothing. ACCEPT RULE: the CRF becomes the default objective only if the paper-metric union F1 rises on BOTH domains against the served file-order perceptron build (683 restaurants, 532 laptops) by more than the ten-permil band on at least one; otherwise it publishes as measured and stays a mode (the CLI token crf). Honest prior: averaged-perceptron-versus-CRF gaps on shared features are often inside noise, so a mixed result is the expected shape and will be published as one |
| 2026-09-06 | IM28 | measure | CRF on the full splits, one binary (nx_absa_seqextract PROMOTED 1b6c4581, NAS pids 17263 restaurants and 17341 laptops, treebank plus the crf token) against the served file-order perceptron 683 restaurants and 532 laptops: restaurants union-occ 680 and perceptron-occ 539 (was 542), NLL 37557181 to 843177 Q10 across the 16 epochs, marginal deviation 6 Q10 units, impossible sentences 0, last-epoch training mistakes 132 (perceptron 282); laptops union-occ 535 and perceptron-occ 462 (was 457), NLL 18661101 to 488358, deviation 6, impossible 0, mistakes 90 (perceptron 179). Under the rule declared before the run every delta is inside the ten-permil band, so the CRF stays a MODE (the CLI token crf) and the perceptron stays the default. Published as measured, not spun [semeval14-paper] |
| 2026-09-06 | IM28 | land | nx_logadd_lib 992d0d1d (5160 B, composes nx_intlog) + nx_logadd_gate f21515c2 built 32600 B on the NAS byte-identical to the laptop build, PROMOTED 75aee3f0, REGISTERED, _offc refreshed, 29/29 GREEN NAS pid 2286 with every emitted value identical on both hosts; nx_absa_seq 63816 B ee6b659d (the CRF mode: sp_set_crf, sp_crf_fb, sp_crf_gold_score, sp_crf_update, five receipt slots, SP_O_N 45); nx_absa_seqextract 7818 B c38aabad built 159256 B PROMOTED 1b6c4581 (token crf, five crf fields on the receipt); nx_absa_seq_gate 19873 B b2ceb9bc built 183648 B PROMOTED 86c88bb4, 65/65 GREEN NAS pid 6815; organ_kind.conf declares nx_logadd_gate oracle; evidence rows on intelmine.gates for both gates; matrix row sp_set_crf. All five sources byte-identical on the laptop and the NAS; the eleven library edits were a size ladder predicted to the byte (53801 to 63816), two reordered edits refused by the size CAS and re-issued, none double-applied |
| 2026-09-06 | IM28 | lesson | AN OBJECTIVE THAT FITS THE TRAINING SET TIGHTER AND MOVES THE TEST NUMBER NOWHERE SAYS THE FEATURES ARE THE CEILING. The CRF halved the training-set mistakes and drove the likelihood down forty-fold while every test delta sat inside noise: with the same feature families the conditional likelihood and the averaged perceptron generalise alike, so the winners' gap over this model is their in-domain data (clusters and name lists from review text) and their dependency features, not their objective. RETRACTED from the queue row above: the phrase about the literature's controlled comparisons putting a CRF a point or two over a structured perceptron carried no ref on this board and is withdrawn as unsupported here; what stands is the measurement. The marginal-partition bar of four Q10 units was set on the planted set and read six on real sentences of up to eighty tokens, a rounding-chain effect the gate's fixture cannot reach, published rather than widened. The step schedule and the tolerance are declared with their reasoning, not tuned; a validation-split schedule search is its own rung with its own pre-declared rule, never a tweak against the test split |
| 2026-09-06 | IM28 | queue | THE NEURAL CLASS, declared as a ladder with its rule BEFORE any build. What the estate already owns (nx_capsearch, 7464 organs): dense embeddings from its own PPMI matrix (nx_embed_train, nx_ppmi_lib vectors), a no-float linear-attention recurrent kernel (nx_nofloat_linattn), software-f32 training ops (nx_f32_train_ops), the no-float autograd, layernorm, attention and AdamW gates, and since today a fixed-point CRF layer (nx_logadd_lib + the CRF mode). RUNG N1, the smallest honest step: the estate's own word vectors as FEATURES of the existing model (each dimension quantised to a signed bucket, plus nearest-centroid ids, the same five-family shape the clusters use), measured under the standing rule: default only if the paper-metric union F1 rises on BOTH domains beyond ten permil on at least one. RUNG N2: a recurrent encoder (nx_nofloat_linattn over embedding plus character features) feeding the CRF layer, trained with the estate's f32 ops, the same rule. Honest prior, stated before the run: the published neural gains on this task came with embeddings pretrained on corpora far larger than the estate's, so both rungs are bounded by the same coverage number the clusters measured (863 permil of laptop vocabulary known, 803 restaurant); the rungs build the capability from the first byte either way, and the number will be published as measured. Referee re-run (nx_swcompare_evidence intelmine) and the roster admit of the ten intelmine gates are queued behind the current regen |
| 2026-09-06 | IM28 | land | ROSTER ADOPTION through the roster's own verbs, no hand edit: nx_gate_roster_run trial over knowledge/status/intelmine_roster_trial.list (ten gates: logadd, wordclust, absa_seq, postag, depparse, absa_bench, steam_reviews, installed_census, intelmine_propose, prop_pass) read 10 GREEN of 10 with the slowest at 674 ms against the 14750 ms roster deadline (journal knowledge/status/intelmine_roster_trial.jrnl, pid 28030), then admit wrote admitted_new=10 already_in_conf=0 suspects=0 rejected=0 into knowledge/gateroster.conf (pid 9055, partition reconciles). Before this the domain's gates executed only through the evidence map; they now also run on the roster beat, so a regression fires without a seat re-running them |
| 2026-09-06 | IM28 | measure | RUNG N1 EMBEDDING FEATURES on the full splits, one binary (nx_absa_seqextract PROMOTED a03419de, NAS pids 20030 restaurants and 20038 laptops, treebank plus the embed token) against the served file-order perceptron 683 restaurants and 532 laptops: restaurants union-occ 682 and perceptron-occ 540 (was 542), table coverage 271904 hits of 402720 training-token lookups = 675 permil, last-epoch mistakes 436 (was 282); laptops union-occ 528 and perceptron-occ 446 (was 457), coverage 233248 of 327808 = 711 permil, mistakes 305 (was 179). Under the rule declared before the run (a rise on BOTH beyond ten permil on one) the mode stays OFF: flat on restaurants, down on laptops. Published as a negative result [semeval14-paper] |
| 2026-09-06 | IM28 | land | nx_embfeat_lib eb7c2c70 (6957 B, composes nx_ppmi_lib, the ONE reader of embed_v1.bin, buckets at a derived half-RMS step) + nx_embfeat_gate f944daba built 46455 B, PROMOTED f23c223f, REGISTERED, _offc, 32/32 GREEN NAS pid 14232; nx_absa_seq 67487 B 6b8edb51 (embed mode: sp_set_embed, 24 coordinate families, a per-slot feature mask sp_fmask consulted by scoring and both updates, receipt slots SP_O_EMB/DIM/LOOKUPS/HITS, SP_O_N 49); nx_absa_seqextract 8607 B eaeacd2d built 165080 B PROMOTED a03419de (token embed, four fields); nx_absa_seq_gate 21799 B e214b2ee built 192368 B PROMOTED c1ab37ce, 72/72 GREEN NAS pid 19857; organ_kind.conf declares nx_embfeat_gate oracle; evidence rows on intelmine.gates; matrix row sp_set_embed. All five sources byte-identical laptop and NAS (the eleven library edits a size ladder 63816 to 67487, four reorder refusals, none double-applied) |
| 2026-09-06 | IM28 | lesson | A MODE THAT IS OFF MUST LEAVE THE MODEL BYTE-IDENTICAL, AND A CONSTANT FEATURE IS NOT NOTHING. The first cut spelled '@' into all twenty-four embedding slots when the mode was off; on the planted set those twenty-four constant votes turned two POS teeth RED that had been GREEN for days, because a perceptron reads a constant feature as a bias and twenty-four of them outvote the informative ones. The fix is a per-slot mask the scoring and update loops consult, so an absent feature casts no vote; a known word carries its twenty-four buckets and an unknown word one marker vote, never twenty-four copies of the same ignorance. The gate proved it in the only way that counts: the POS teeth went back to GREEN. The measurement then said what the CRF rung said from the other side: with two thousand training sentences the winners' gap is data, and a dense table that knows two thirds of the tokens adds capacity faster than evidence. Retire nothing: the mode ships off, the library is the estate's one embedding reader, and the next rung is the corpus decision |
| 2026-09-06 | IM28 | land | nx_embfeat_gate ADMITTED to knowledge/gateroster.conf through trial (1 GREEN of 1, 2 ms, journal knowledge/status/intelmine_roster_trial2.jrnl, pid 26921) and admit (admitted_new=1, pid 27520, partition reconciles): every one of the domain's eleven gates now runs on the roster beat as well as on the evidence map. The gate's two arithmetic tooth names that quoted the pre-correction step were corrected on both trees (source cc10f142), rebuilt (54048 B) and PROMOTED 89ab2a8c, 32/32 on the served binary pid 23642; the evidence row names both elfs. Page republished by the compare beat's own regen (this lane's third regen was refused LS-BUSY, correctly: two regens double the fsync load and publish nothing sooner), verified GREEN at 286549 B. REFEREE STATUS, stated plainly: nx_swcompare_evidence intelmine abstained twice today on the heavy-I/O budget (HEAVYIO running=3 of width 4, verdict DEFER) and a third call lost its reply at the edge; the last full referee pass on this domain remains the earlier MEASURED-HONEST, so the eleven executed-evidence rows await their next referee read rather than being counted as refereed now |
| 2026-09-06 | IM28 | lesson | ARE WE BUILDING OLD TECH (operator, 2026-09-06)? YES, stated plainly: every rung on this ladder is the 2014-to-2018 class and the bar it chases (840 restaurants, 745 laptops on Subtask 1) is the 2014 winners' bar; matching it would be state of the art for 2014. The field in 2026 extracts aspect, opinion, category and polarity together with encoder or generative models, and SemEval-2026 Task 3 (mirrored knowledge/fetched/cmp_intelmine_dimabsa2026.html, 429641 B, sha 0e77f92e) moves the target to dimensional valence-arousal sentiment over broader domains [dimabsa2026]. What the climb bought is not nothing: a sovereign POS tagger, dependency parser, word clusterer, fixed-point log-domain arithmetic, a linear-chain CRF, the ONE embedding reader and an error census, each a capability the estate lacked, each gate-proven; and the measurements say the same thing four ways -- with two thousand training sentences the gap is data and model class, not the objective. RETRACTED as a target: reaching 840 and 745 on Subtask 1 with feature models is no longer this board's definition of state of the art |
| 2026-09-06 | IM28 | queue | RUNG L1, THE LLM-CLASS EXTRACTOR ON THE ESTATE'S OWN MODEL, declared with its rule and envelope BEFORE any build: nx_absa_llm composes nx_nofloat_serve_core the way the research reader's extraction stage already does (nx_qwen_extract: the model loaded once, prompts under a 900-character guard because the tokenizer overflows its ids past 192 tokens before its own length check, NSV_MAXT 384, greedy generation in-process, i32 lossless mode), prompts one test sentence with one demonstration drawn from the training split, asks for the aspect terms exactly as written or NONE, parses the list, and scores it through the SAME lists and per-occurrence predicate the perceptron uses. Resource envelope: one generation per test sentence (615 restaurants, 418 laptops), each row appended to a journal as it is decided so a killed run keeps its rows and resumes with --from; the run is paced by the box's admission and never launched beside a regen. Rule: published as measured; joins the union as a third arm only if the paper-metric union F1 rises on BOTH domains beyond ten permil on at least one. RUNG L2: the no-float fine-tune (nx_nofloat_autograd: embed, matmul, row softmax cross-entropy, AdamW) of the extraction head on the training split, same rule. RUNG D1: DimABSA 2026 admitted as data (splits mirrored with license beside them, the valence-arousal scorer built from the task definition) before any number is claimed on it. The census rung in flight (perceptron misses partitioned by cause) tells which of these to run first |
| 2026-09-06 | IM28 | lesson | HOW A BOARD BUILT OUT-OF-DATE TECH FOR A DAY (operator, 2026-09-06: how did we build something that was way out of date). Root cause in order: (1) the bar was pinned from the ONE source this domain had mirrored, the SemEval-2014 paper's results table, and the bar row never carried its year, so a 2014 number read as the current bar; (2) the seat inherited its target from the previous session's summary (reach the 2014 winners) and climbed without re-deriving the target from the field's present state; (3) the estate's search discipline asks whether an ORGAN exists before building one and never asks whether a BAR is current -- nx_capsearch and nx_spendgate guard duplication, nx_sota_status guards claim-binding, nothing guards bar age; (4) a single source with no second referee, the same shape as an LLM hallucination trusted alone, caught only when the operator brought a second source. Not a wasted day: every rung built a sovereign capability the estate lacked and each measurement was honest under a pre-declared rule; the target was stale, not the work. MECHANISM, declared as a build contract on the compare emitter rather than a rule to remember: a bar row carries its source year, and the sota generator flags a bar older than the field's turnover as DATED beside STALE-UNDER and UNBACKED, so a page cannot call a ten-year-old number state of the art without saying so. Until that ships, every bar this board cites states its year in the cell |
| 2026-09-06 | IM28 | measure | SOTA 2026 RESEARCHED FROM READ BYTES (operator: research sota 2026 is a pretty hard line): two arXiv API listings mirrored over the estate's own TLS on 2026-09-06 (aspect sentiment quad, 15 entries, sha 3f3d9bf8 33881 B; aspect term extraction AND large language, 2 entries, sha e3d14456 4710 B; the plain-http form was refused status 0 three times, https fetched first try) and every abstract read from the mirrored bytes, refs asqp2026feed and atellm2026feed. The field's current line is generative quad prediction (aspect, category, opinion, polarity) on Rest15 and Rest16: LLM fine-tuning with a correction pass (G2C 2026-03), stepwise syntax-integration tuning (S2IT 2026-04), listwise preference optimisation (2025-11), stepwise task augmentation (STAR 2025-01), LLM-as-annotator for lightweight models (LA-ABSA, LREC 2026: Rest16 quad F1 49.85 from 50 seeds against 51.10 for a 27B in-context model), few-shot prompting at 51.54 against fine-tuned MVP 60.39 (Hellwig 2025-02); and on the exact SemEval-2014 sets this board scores, a fine-tuned GPT-3.5 at F1 83.8 on the joint term-plus-polarity task (Simmering 2023-10) is the dated bar. Landed as the matrix row ORACLE 2026 with a year on every number. What the estate lacks, in order: the ASQP and DimABSA data (D1), a sovereign generative arm (L1 nx_absa_llm over nx_qwen_extract, resumable, one generation per test sentence, accept rule declared before the run), the joint term-plus-polarity ruler in nx_absa_bench, and the emitter DATED-bar flag |
| 2026-09-06 | IM28 | land | THE 2014 LADDER IS CLOSED OUT, NOT ABANDONED (operator: do not leave the 2014 stuff half built): the census dedupe defect is fixed at the source (nx_absa_seq skips the census for a gold term repeated as the aspect of one sentence, the scorer's list dedupes so the census counts once too) and nx_absa_seq_gate carries a duplicated-gold fixture with four teeth, 82 of 82 GREEN on the laptop; the NAS rebuild, promote, registry refresh and served re-run follow in this pass and the gates map row moves with them. Every rung on the ladder (tagger, parser, clusterer, log-domain arithmetic, CRF, embedding reader, error census) stays a promoted, rostered sovereign capability; only the target was retracted |
| 2026-09-06 | IM28 | measure | CURRENT-MONTH RULE APPLIED (operator 2026-09-06: hard fail on anything less than the current month unless there is nothing current month, then say what month of what year says is sota): two more listings mirrored the same hour (all aspect-based sentiment, 30 of 368 entries, sha 54cddab4 69330 B; DimABSA, 9 entries, sha 809c01bb 20361 B), every abstract read from the bytes. September 2026 has NO arXiv entry on the fetch date (the month is six days old), so the bar month is August 2026: STAR-OPD 2608.20831 (2026-08-21, on-policy reward distillation of chain-of-thought LLM teachers into a Qwen3-4B student for quadruple extraction, SemEval-2014 and E-ABSA20K) and SeqLab plus aspect-code switching 2608.30425 (2026-08-31, EMNLP 2026, seq2seq with an encoder labelling task, state of the art on end-to-end ABSA over eleven languages). Dimensional task: July 2026 (The Classics 2607.03414; first place in March 2026 was LogSigma's uncertainty-weighted multitask learning). The ORACLE 2026 matrix row now leads with the month and the fallback, refs absa2026aug and dimabsa2026sys pinned. MECHANISM OWED AS A HARD FAIL, not a rule to remember: a bar carries its source month and the checker refuses any bar older than the current month unless a listing row attests the current month has nothing newer; built in this pass as a sovereign organ over the compare data |
| 2026-09-06 | IM28 | measure | CENSUS RE-MEASURED ON THE PROMOTED BUILD (nx_absa_seqextract 24581208, nx_absa_seq_gate be9bc844 82 of 82 on the NAS pid 17992, both _offc twins fresh): restaurants gold occurrences 1117, perceptron matched 456, parts 1 untokenisable + 97 unseen single + 221 unseen multi + 319 seen single + 23 seen multi = 661 = 1117 - 456; laptops 634 gold, 220 matched, parts 18 + 62 + 184 + 104 + 46 = 414 = 634 - 220 (the duplicate was one seen-single record, 63 became 62). Union per-occurrence F1 684 restaurants (P 711, R 659) and 533 laptops (P 606, R 476), perceptron 542 and 457, inside the ten-permil noise band of the published 683 and 532. The partition claim now holds on both domains by construction, the content ruler read the gate a strict superset (six gained runs, nothing lost) and the CLI identical content, and the 2014 ladder is CLOSED OUT: every rung promoted, rostered and gate-green, only the target retracted |
| 2026-09-06 | IM28 | land | THE HARD FAIL IS IN THE PATH (operator 2026-09-06: hard fail on anything less than the current month; the logic must force the seat from the /compare domain): nx_barfresh_lib (bar |
| 2026-09-06 | IM28 | measure | THE REFUSAL WITNESSED LIVE, BOTH DIRECTIONS: a planted domain zzbarprobe (one rung, one 2026-07 bar, no attestation) made nx_compare_rank print BARFRESH bars=1 unattested=1 verdict=STALE then RANK REFUSED BAR-STALE and rank nothing (the probe is retired reversibly under knowledge/retired/); intelmine printed BARFRESH bars=2 attested=2 verdict=FRESH and the 29-rung ranking proceeded (PM filed 3); nx_barfresh intelmine under the clock read both bars ATTESTED with newest seen 2026-08 and 2026-07, verdict FRESH, and under a forced 2026-10 read both UNATTESTED with the REMEDY printed, verdict STALE. Also fixed on this board while reading the ranker: rungs IM28 and IM17 carried organ names as their symbols (nx_absa_seqextract, nx_absa_bench), so the ranker priced them UNMAPPED at zero; they now carry the matrix symbols sp_eval and ab_eval, and both rungs are done by their pre-declared rules (IM28 exceeds the n-gram arm at 454 and 453 against 218 and 238; IM17 scores both subtasks) |
| 2026-09-06 | IM28 | land | THE LADDER TO SOTA AS DATA (operator 2026-09-06: how you framed it here is how all the /compare domains should be emitting, with a clear target on what is best in class and what is frontier): this board now carries three dated targets (sotatarget T-BIC best in class, T-FRONTIER the August 2026 frontier, T-DIM the July 2026 dimensional frontier, each dated by a sotabar row and attested this month), a rungrole row on every one of its 34 rungs (substrate, arm, contender, superseded) naming what each grows toward, five new rungs for the 2026 gap under milestone M4 (IM29 data with licences, IM30 the joint, quad and cF1 rulers, IM31 the sovereign generative arm, IM32 the dimensional arm, IM33 triangulation, the exceed candidate) with matrix watch rows for their symbols, and the plan header documents the four row kinds. The row tags were re-chosen after reading the renderer: bar and ladder already belonged to the research-bar and market-entry kinds, so sotabar, barscan, sotatarget and rungrole are the vocabulary. Mechanism in the estate, not prose: nx_ladder_lib, nx_ladder (one domain or all over regen.list), nx_ladder_gate 42 of 42, nx_compare_rank refusing LADDER-PARTIAL and labelling NO-LADDER, plan_pass in nx_swcompare_lib rendering the targets with their bar state, the rung-role table with what each rung stands on, and a Ladder verdict on every page (NOT DECLARED when a board has none); sources hash-identical on both trees, NAS builds storm-paced |
| 2026-09-06 | IM28 | lesson | WHAT OF THE 2014 WORK APPLIES TO 2026, AS DATA NOW: the ruler and the data (IM17) are substrate the frontier still evaluates on; the syntax tools and the perceptron (IM28) are the mechanistic ARM, the very labelling SeqLab adds as an encoder task and one leg of triangulation; the n-gram arm (IM2) is an arm superseded as a contender; the corpus, beat, spine, policy and census rungs are substrate; the target itself was the only thing retracted. The contenders for 2026 are new rungs: the generative arm on quads, the dimensional arm on cF1, and triangulation, which no rival column carries |
| 2026-09-06 | IM28 | measure | THE ERROR CENSUS (the instrument the closing of the 2014 ladder owed): every perceptron miss on the test split partitioned by the reason it could be missed, on the PROMOTED default build (nx_absa_seqextract fbe33bd7, NAS pids 31676 and 31814, treebank on, no mode). Restaurants: 1117 gold occurrences, 456 matched, 661 missed = 1 not tokenisable in its sentence + 97 unseen single-token + 221 unseen multi-token + 319 dictionary-seen single-token + 23 dictionary-seen multi-token (parts sum 661); the union arm still misses 380. Laptops: 634 gold, 220 matched, 414 missed, and the parts summed to 415 = 18 + 63 + 184 + 104 + 46: THE PARTITION CLAIM FAILED BY ONE ON ITS FIRST REAL RUN, which is the instrument working. The gold list dedupes a term repeated as the aspect of one sentence (the scorer counts one occurrence) while the census counted every record; one laptop sentence carries the same term twice. Fixed at the source (a duplicate record is skipped before the census) with a duplicated-gold fixture and four teeth in the gate, so the parts equal gold minus matched by construction; the union arm still misses 333. Reading: the tokenisation ceiling is small (1 and 18); the largest generalisation class is a multi-word term the training set never showed (221 and 184, a third of all misses); the largest modelling class is a single word the dictionary knows and the perceptron still skipped (319 and 104), which is exactly the class the union arm recovers (661 to 380, 415 to 333). The 2014 ladder's own numbers now say where it stopped: unseen multi-word terms, which a linear model over 2000 sentences cannot compose and a generative model reads off the sentence [semeval14-paper] |
Person · product · place — not yet measured for this domain
knowledge/compare/intelmine.ppp (rows surface|nishi or c1..c4|label|url|connect naming OUR live surface and each rival's front door), run nx_ppp_probe domain intelmine, and this section fills itself on the next beat: the same ruler on both sides — privacy and CX (third-party hosts, tracker classes, cookies, security headers), design and longevity (design hygiene, computed WCAG contrast, render-blocking resources, unsized media, script weight, theme and motion queries), findability (landmarks, skip link, on-site search, breadcrumb, headings, internal links).The field — discovered, not chosen
Rows written by nx_field_discover from intelmine.seeds: the industry's own lists (Wikipedia wikitext, GitHub topics, awesome lists) read mechanically, every candidate counted across seeds. The matrix columns above are a SEAT'S pick; this band is the population they were picked from, and the stats line measures one against the other. A rival here is a lead, never a verdict — it earns a column when its capabilities are read and pinned.
| Class | Count | Note |
|---|---|---|
| seeds | 3 | |
| scanned | 3 | |
| fetched | 3 | |
| reused | 0 | |
| failed | 0 | |
| named | 3 | |
| candidates | 3 | |
| mentions | 3 | |
| capped | 0 |
| Rank | Rival | Seeds | Mentions | First seed | Kind | Link |
|---|---|---|---|---|---|---|
| 1 | Steam Reviews (native) | 1 | 1 | col0-steam | named | https://partner.steamgames.com/doc/store/getreviews |
| 2 | download-steam-reviews | 1 | 1 | col1-download | named | https://raw.githubusercontent.com/woctezuma/download-steam-reviews/master/README.md |
| 3 | Appbot | 1 | 1 | col2-appbot | named | https://appbot.co/features/ |
field candidates 3|shown 3 of 3|matrix columns in the field 3 of 5|discovered rivals with no column 0|malformed rows 0 (counted, never rendered)|read-capped 0
Exclusive and shared capabilities
This board grades 59 capabilities: 57 exclusive to it and 2 shared with other boards. Shared rows on this page: 2 = home here 1 + home elsewhere 0 + ambiguous 0 + undecided 1 + refused 0 (partition 2); undecided = unmapped 0 + unproven 1 + unevidenced 0; homonyms 1; since the previous census: new 0, resolved 0. Census FRESH age_s=7149.
| Capability | Organ | Boards grading it | Home | Rule | Evidence | Standing on this board |
|---|---|---|---|---|---|---|
| rm_trend | - | loadgov:runtime/_hdl_build/nx_resmon.nx, intelmine:runtime/nx_reviewmine_lib.nx | — | homonym | - | homonym |
| fs_scan_source | nx_frontier_scan.nx | intelmine, researchreach | — | none | unproven | undecided |
| ic_libraries | nx_installed_census_lib.nx | intelmine*+, modding | intelmine | rung | plan | home here |
Gaps from the record — what the estate does that no board carries
The record census (nx_goalmap record) reads the invoked-tool population and every plan queue row and files each organ or directive that NO matrix, plan or gates row names. A row here is a callout the boards missed: adjudicate it onto a board or declare it infrastructure. Census state STALE (age 1396254 s), sources read 4 of 7 declared — a BLIND census is a FLOOR: unread sources can only add rows.
| kind | name | board | source | evidence |
|---|---|---|---|---|
| directive | nx_depparse_eval | intelmine | plan-queue | rung=IM28 |
| directive | nx_ppmi_lib | intelmine | plan-queue | rung=IM28 |
| directive | nx_wordclust | intelmine | plan-queue | rung=IM28 |
| directive | nx_logadd_lib | intelmine | plan-queue | rung=IM28 |
| directive | nx_f32_train_ops | intelmine | plan-queue | rung=IM28 |
rows shown 5|this board's directives 5|estate-wide un-boarded organs 452 (listed in full on /compare/ecosystem)|census rows 639|malformed 0 (counted, never rendered)
References
- [steam-getreviews] Valve. Steamworks Documentation, User Reviews - Get List: GET store.steampowered.com/appreviews/appid?json=1 with filter recent or updated or all, language, day_range, cursor (pass * first, then the returned cursor URL-encoded), review_type, purchase_type, num_per_page up to 100, filter_offtopic_activity (review bombs excluded by default); response fields query_summary (num_reviews, review_score, review_score_desc, total_positive, total_negative, total_reviews), cursor, and per review recommendationid, author (steamid, num_games_owned, num_reviews, playtime_forever, playtime_last_two_weeks, playtime_at_review, last_played), language, review, timestamp_created, timestamp_updated, voted_up, votes_up, votes_funny, weighted_vote_score, comment_count, steam_purchase, received_for_free, written_during_early_access, developer_response, primarily_steam_deck; strings may need unescaping. Fetched 2026-09-05. publisher · read in our library
knowledge/fetched/cmp_reviewmine_steam_getreviews.html· pinh24bd2e4f24c663b1d1007b7772f6f8052a8235f47742f2becf96cf33875bdc61· accessed 2026-09-05 · vendor-docGrounds: The Steam fetch, cursor pagination, page banking and decoder rows: every field the adapter journals is read from this page, and the off-topic default the adapter keeps is stated here. - [steam-policy] Valve. Steamworks Documentation, User Reviews: users with recorded playtime write reviews indicating whether they recommend the product; reviews appear depending on how many other users find them helpful; the aggregate of positive and negative reviews forms a review score shown for the last 30 days and over the lifetime; a copy received for free should be disclosed; off-topic reviews are typically not upvoted and moderators may flag them, reducing visibility. Fetched 2026-09-05. publisher · read in our library
knowledge/fetched/cmp_reviewmine_steam_reviews_policy.html· pinhdcfc017eb6ee6c8ee040797b4e6c019ea53e09365a4d08dcc429bb91a72c7272· accessed 2026-09-05 · vendor-docGrounds: The Steam native column on the rubric, trend and near-duplicate rows: a binary recommend vote, a helpfulness-weighted surface, a recent-versus-lifetime score and a moderation flag are what the platform itself provides. - [steam-isteamapps] Valve. Steamworks Documentation, ISteamApps Interface: GetAppList v2 is deprecated because it can no longer scale to the number of items on Steam, use IStoreService/GetAppList instead; GetPartnerAppListForWebAPIKey needs a publisher key and must be called from a secure server. Fetched 2026-09-05. publisher · read in our library
knowledge/fetched/cmp_reviewmine_steam_isteamapps.html· pinhfee6d6591734f82093b01e2724308a3aef93c3f0a26d306a3be4cecafa885bc9· accessed 2026-09-05 · vendor-docGrounds: The app-list and cohort row: the deprecation notice decides which endpoint the applist rung composes. - [appdetails-palworld] Valve. Steam store appdetails for appid 1623730 (Palworld), filters price_overview, basic, genres, release_date, recommendations, cc=us: price_overview final 2099 USD cents as read on 2026-09-05. Fetched 2026-09-05. publisher · read in our library
knowledge/fetched/cmp_intelmine_steam_appdetails_1623730.json· pinha6379e4f1d03b78a9df40f1b9eac391c207e7a759cab658487cecf300918bc4d· accessed 2026-09-05 · vendor-docGrounds: The value rows and the Palworld measurement: the price the rubric reports beside the tiers is read from this record, not typed. - [appdetails-vrhot] Valve. Steam store appdetails for appid 1571340 (VR HOT), same filters, cc=us: price_overview final 4499 USD cents as read on 2026-09-05. Fetched 2026-09-05. publisher · read in our library
knowledge/fetched/cmp_intelmine_steam_appdetails_1571340.json· pinhf9462a0598b4be9ea8470d86981cedab899829990ff6cefd7bdf6b06e5dd3f15· accessed 2026-09-05 · vendor-docGrounds: The value rows and the VR HOT measurement: the price beside the tiers. - [dsr] woctezuma. download-steam-reviews README (master): Python code to download every Steam review for chosen appIDs; the Steam API is rate-limited so about 10 reviews per second; batch by idlist.txt; load_review_dict and download_reviews_for_app_id; request parameters language, review_type, purchase_type, filter, day_range; caveat that review_type positive or negative makes total_reviews misleading, compute it as total_positive plus total_negative; with filter all only a few reviews in a time window can be downloaded. Fetched 2026-09-05. publisher · read in our library
knowledge/fetched/cmp_reviewmine_dsr_woctezuma.md· pinhd17d788088f888e10f47afdfa8cbfa9d6760160748e21bf787a9dd07d0f7405e· accessed 2026-09-05 · source-readGrounds: The download-steam-reviews column: the open-source downloader every Steam review study starts from, its fixed-rate pacing figure (which this board's inter-page delay is derived from), its incremental update and its stated limits. - [appbot] Appbot. Features page: review and ratings analytics across app-store channels for product managers (data-driven roadmap decisions), voice of the customer (map trends in sentiment and content across all channels of user feedback), developers (close the feedback loop to spot bugs faster) and customer support; an Appbot MCP; help centre, changelog, and a compare-to-other-tools page. Fetched 2026-09-05 (59,934 B; a Windows browser fetch of the same URL returned a 12,959 B shell with no title). publisher · read in our library
knowledge/fetched/cmp_reviewmine_appbot.html· pinh514ba361d531cfe96604da5d649937fc80a4c4716f926bbef36d6068b865adbb· accessed 2026-09-05 · vendor-docGrounds: The Appbot column: the commercial review-analytics bar (sentiment and content trends, multi-channel, bug spotting) graded as presence from its own feature copy, not depth. - [amazon-2023] McAuley Lab, UC San Diego. Amazon Reviews 2023: 571.54M reviews (245.2 percent larger than the previous release), interactions from May 1996 to September 2023, richer item metadata, second-level timestamps, standard splits; a review record carries rating, title, text, images, asin, parent_asin, user_id, timestamp, helpful_vote, verified_purchase; loaded from JSONL. Fetched 2026-09-05. publisher · read in our library
knowledge/fetched/cmp_reviewmine_amazon_reviews_2023.html· pinhcf0e6cdb219ce81489b2e9a51a2b6ad916fa5134bf8a5de3adb542f7662c45cf· accessed 2026-09-05 · datasetGrounds: The Amazon adapter row and the research column: the lawful Amazon review corpus and the record shape the second adapter must read; also the scale bar (hundreds of millions of rows) the journal codec is measured against. - [semeval14] Pontiki, M., Galanis, D., Pavlopoulos, J., Papageorgiou, H., Androutsopoulos, I., Manandhar, S. SemEval-2014 Task 4: Aspect Based Sentiment Analysis. Proceedings of the 8th International Workshop on Semantic Evaluation (SemEval 2014), Dublin, August 2014, ACL Anthology S14-2004. Fetched 2026-09-05. publisher · read in our library
knowledge/fetched/cmp_reviewmine_semeval14_absa.html· pinhe558fad72850f727ccb1bc1b6a35f7106dfd700c20718f7096c2dca480b83fc1· accessed 2026-09-05 · published-paperGrounds: The aspect-extraction and opinion-orientation rows and the ABSA bench oracle: the benchmark the mined-aspect rung is pre-declared to be scored against. - [hu-liu-2004] Hu, M., Liu, B. Mining and Summarizing Customer Reviews. KDD 2004, University of Illinois at Chicago. Abstract and introduction read from the PDF: mine the product features customers have commented on, identify opinion sentences and decide whether each is positive or negative, summarise per feature (Feature: picture quality, Positive 253, Negative 6); features mined with data mining plus NLP, opinion words are adjectives with orientation bootstrapped from WordNet; evaluated on customer reviews of five products. Mirrored 2026-09-05 through nx_content_put after the sovereign fetcher could not reach the TLS-1.2-only host. publisher · accessed 2026-09-05 · published-paperGrounds: The research column on the mine rows: feature-based summarisation is the classic shape this board's defect and feature tables answer, and mined (not hand-listed) features are its bar.
- [lin2019] Lin, D., Bezemer, C.-P., Zou, Y., Hassan, A. E. An empirical study of game reviews on the Steam platform. Empirical Software Engineering, Springer, 2019 (doi 10.1007/s10664-018-9627-4). Abstract: an empirical study of the reviews of 6224 games on Steam, whether game reviews share characteristics with mobile app reviews, the relation between game-specific characteristics and daily review counts, and the useful information reviews carry for developers. Fetched 2026-09-05 (article page, 346,513 B). publisher · read in our library
knowledge/fetched/cmp_reviewmine_lin2019_steam.html· pinhd59a5ad1c58a36426af8922e1de9a599ce4e6ec7d1fa4ddb49a74273234af485· accessed 2026-09-05 · published-paperGrounds: The playtime-band and trend rows: the published Steam-review study whose population (6224 games) and questions (what developers can learn) this board's Steam adapter is measured against. - [github-releases] GitHub Docs. REST API endpoints for releases: list, get the latest, get by tag, create, update, delete releases and generate release notes. Fetched 2026-09-05. publisher · read in our library
knowledge/fetched/cmp_intelmine_github_releases.html· pinh7c787e9f22da1d1ea6bfbfba9b423da1344d1f10f6e6f616a31b42a591f84992· accessed 2026-09-05 · vendor-docGrounds: The releases and changelog row: the machine feed a release miner reads, and the one nx_barcheck already pins versions from. - [github-issues] GitHub Docs. REST API endpoints for issues: list, create, get, update, lock and unlock issues, with labels, milestones and assignees. Fetched 2026-09-05. publisher · read in our library
knowledge/fetched/cmp_intelmine_github_issues.html· pinh8c0fff0101e1aa0ae1b8e4dffe7628a3503009857ff1e642e7f2b6da5bb28268· accessed 2026-09-05 · vendor-docGrounds: The bug-tracker row: the machine feed a defect miner reads for rivals that track in the open. - [arxiv-api] arXiv. API Basics: the arXiv API lets programmatic access to the e-print metadata via HTTP queries returning Atom feeds, with search_query, id_list, start and max_results, and requests paced by the user. Fetched 2026-09-05. publisher · read in our library
knowledge/fetched/cmp_intelmine_arxiv_api.html· pinhd526512780a04aa9ff1830ae9972c7c64fc29bb95c0b7fc96e6b1c87824582d4· accessed 2026-09-05 · vendor-docGrounds: The research-mining row: the feed the arXiv scan rung composes with the estate's own Atom extractor and frontier scanner. - [wolfram-listing] Wolfram Research. Wolfram Language Documentation, Alphabetical Listing of every built-in symbol (guide page, 1,181,595 B as mirrored). Fetched 2026-09-05. publisher · read in our library
knowledge/fetched/cmp_intelmine_wolfram_listing.html· pinh266f2b39897ddaf82ba5d66c88a4874188082fea02d8bea2e5fc1889b4b47dbd· accessed 2026-09-05 · vendor-docGrounds: The rival feature-census row: the operator's worked target (what does Wolfram have, all of it) is this page parsed into candidate rows for computational.matrix, whose bars are declared UNPINNED today. - [appdetails-dancexr] Valve. Steam store appdetails for appid 1905510 (DanceXR), filters price_overview, basic, genres, release_date, recommendations, cc=us: a character model viewer and motion player that animates models in PMX, XNALara/XPS, VMD and BVH formats, with DLC 2063770 and 2819100, as read on 2026-09-05. Fetched 2026-09-05. publisher · read in our library
knowledge/fetched/cmp_intelmine_steam_appdetails_1905510.json· pinhe03cc58b226df0601f33e9c94432475bf67dd9c271c9ca26cb61104904b58cce· accessed 2026-09-05 · vendor-docGrounds: The DanceXR worked example on the proposer rung: the store record names the model and motion formats the title reads, which are the formats the estate's own nx_pmx, nx_vmd and nx_bvhfk organs already read -- the tie-out from a mined title to existing estate capability. - [semeval14-paper] Pontiki, M., Galanis, D., Pavlopoulos, J., Papageorgiou, H., Androutsopoulos, I., Manandhar, S. SemEval-2014 Task 4: Aspect Based Sentiment Analysis, Table 4 results for aspect term extraction (SB1). Proceedings of SemEval 2014, ACL Anthology S14-2004, the PDF. Fetched 2026-09-05, text extracted with nx_pdf_text. publisher · read in our library
knowledge/fetched/cmp_intelmine_semeval14_paper.pdf· pinhf2c18570379d66a6f2200ac6cf3213934f79234a28a726c80a82700e4b92e592· accessed 2026-09-05 · published-paperGrounds: ORACLE: SemEval-2014 aspect-term F1 as the pre-declared bar for mined aspects - [semeval14-rest-train] Pontiki et al. SemEval-2014 Task 4 RESTAURANTS training split (ABSA-PyTorch mirror of the official train set), the labelled data the supervised dictionary tagger learns its aspect-term dictionary from. Fetched 2026-09-05. publisher · read in our library
knowledge/fetched/cmp_intelmine_semeval14_rest_train_gold.seg· pinh179e03965ad30f9c6348b5eb3ea0f285fd6952c7914489c5539ed65ffef5c66a· accessed 2026-09-05 · datasetGrounds: ORACLE: SemEval-2014 aspect-term F1 as the pre-declared bar for mined aspects - [semeval14-lap-train] Pontiki et al. SemEval-2014 Task 4 LAPTOPS training split (ABSA-PyTorch mirror of the official train set), the labelled data the supervised dictionary tagger learns its aspect-term dictionary from. Fetched 2026-09-05. publisher · read in our library
knowledge/fetched/cmp_intelmine_semeval14_lap_train_gold.seg· pinhfcc7574e20bc5af850d643ecaacf8f675a7c6b7979923ac5a0d571f237398a67· accessed 2026-09-05 · datasetGrounds: ORACLE: SemEval-2014 aspect-term F1 as the pre-declared bar for mined aspects - [ud-ewt-train] Silveira, N., Dozat, T., de Marneffe, M.-C., Bowman, S., Connor, M., Bauer, J., Manning, C. D. et al. Universal Dependencies English Web Treebank (UD_English-EWT), training split en_ewt-ud-train.conllu, CoNLL-U with UPOS in column 4; a DATA asset the estate's own POS tagger (nx_postag) trains on, redistributed under CC BY-SA 4.0 with the license beside it. Fetched 2026-09-05 (15,034,493 B). publisher · read in our library
knowledge/fetched/cmp_intelmine_ud_ewt_train.conllu· pinhd68e06122a702464c613076523d56740f047e5bbe89dd90ec32737e04d952143· accessed 2026-09-05 · datasetGrounds: The POS-tagger rung and the POS-feature arm of the sequence model: the licensed treebank the tagger learns from; every SemEval-2014 winner used POS features and the estate had no tagger until this asset. - [ud-ewt-test] Universal Dependencies English Web Treebank (UD_English-EWT), test split en_ewt-ud-test.conllu, the held-out sentences the tagger's UPOS token accuracy is measured on (never trained on). Fetched 2026-09-05 (1,900,101 B). publisher · read in our library
knowledge/fetched/cmp_intelmine_ud_ewt_test.conllu· pinhfa024f43dc5da3c5ac02563bc9bd0e974f46cbb1560823976a8f342a37dc494a· accessed 2026-09-05 · datasetGrounds: The POS-tagger accuracy row: the held-out split the 927 permil UPOS token accuracy is read on, so the number is a measurement on unseen text. - [ud-ewt-license] Universal Dependencies English Web Treebank LICENSE.txt: Creative Commons Attribution-ShareAlike 4.0 International, the license under which the treebank data is redistributed; shipped beside the data in knowledge/fetched so the foreign bytes carry their license (DATA assets are the only foreign bytes allowed inside the estate). Fetched 2026-09-05 (20,014 B). publisher · read in our library
knowledge/fetched/cmp_intelmine_ud_ewt_LICENSE.txt· pinhb3d1b0f4c6ae151f7eb78738f46ebd5ee140f8a7f76501ba26af123140d35ae7· accessed 2026-09-05 · datasetGrounds: The license row for the treebank asset: a data asset inside the estate carries its license beside it, and this is that license, pinned. - [dimabsa2026] SemEval-2026 Task 3: Dimensional Aspect-Based Sentiment Analysis (DimABSA), arXiv 2604.07066v1 (HTML rendering, LaTeXML). The task definition the 2026 rung is admitted against: aspect-based sentiment on numeric valence-arousal dimensions rather than categorical polarity, over broader domains than the 2014 restaurant and laptop sets. Fetched 2026-09-06 (429,641 B). publisher · read in our library
knowledge/fetched/cmp_intelmine_dimabsa2026.html· pinh0e77f92eb92380fb4168d1cef087190a08eabbf91334992585ea78690f235a7d· accessed 2026-09-06 · published-paperGrounds: The 2026 task shape: LLM-class structured extraction and DimABSA - [asqp2026feed] arXiv API listing for all:aspect sentiment quad sorted by submission date, 15 entries with abstracts, fetched 2026-09-06 over the estate's own TLS: S2IT 2604.23296 (2026-04, stepwise syntax integration tuning of LLMs for quad prediction), G2C 2603.13777 (2026-03, generate then correct on Rest15 and Rest16), LA-ABSA 2603.01778 (2026-03, LREC 2026, LLM-annotated examples train lightweight models: ASQP Rest16 F1 49.85 from 50 seeds against 51.10 for Gemma-3-27B in-context prompting), listwise preference optimisation over element-wise confusions 2511.23184 (2025-11), Hellwig et al 2502.13044 (2025-02, 20-shot LLM prompting F1 51.54 on Rest16 ASQP against 60.39 for the fine-tuned MVP, TASD 68.93 against 72.76), STAR 2501.16093 (2025-01) and the 2021 to 2024 generative line back to Paraphrase 2110.00796. publisher · read in our library
knowledge/fetched/cmp_intelmine_arxiv_asqp_recent.atom· pinh3f3d9bf8761585b1827d74dbdfbfd842ac7b3311ea742127197e81713ec5ac64· accessed 2026-09-06 · mirrored-indexGrounds: ORACLE 2026: dated bars for aspect extraction and quad prediction, read from the field's 2025 to 2026 record (every number carries its year) - [absa2026aug] arXiv API listing for all:aspect-based sentiment sorted by submission date, 30 of 368 entries with abstracts, fetched 2026-09-06 over the estate's own TLS: NO SEPTEMBER 2026 ENTRY EXISTS on the fetch date, so the freshest month is AUGUST 2026 with two papers: STAR-OPD 2608.20831 (2026-08-21, chain-of-thought LLM teachers distilled on-policy into a Qwen3-4B student with set-structured cascade-aware rewards for quadruple extraction, evaluated on E-ABSA20K and SemEval-2014) and SeqLab with aspect-code switching 2608.30425 (2026-08-31, EMNLP 2026, a sequence-to-sequence model with an encoder sequence-labelling auxiliary task surpassing the prior state of the art on end-to-end ABSA across eleven languages and three domains); July 2026 adds Arabic implicit-aspect knowledge graphs 2607.20056 (fine-tuning an 8B LLM lifts explicit-extraction micro-F1 from at most 0.13 zero-shot to 0.66 to 0.76) and constraint-aware counterfactual editing 2607.13977. publisher · read in our library
knowledge/fetched/cmp_intelmine_arxiv_absa_newest.atom· pinh54cddab4ca4bb153efc714c9f715ee0698d3f8573e392f77ea3a0ee387b39dc6· accessed 2026-09-06 · mirrored-indexGrounds: ORACLE 2026: dated bars for aspect extraction and quad prediction, read from the field's 2025 to 2026 record (every number carries its year) - [dimabsa2026sys] arXiv API listing for all:DimABSA OR all:dimensional aspect-based sorted by submission date, 9 entries with abstracts, fetched 2026-09-06: the freshest is JULY 2026 (The Classics at SemEval-2026 Task 3, 2607.03414: a weighted ensemble of transformer encoders for valence-arousal regression and a fine-tuned decoder LLM for structured extraction with scores), then NCL-BU 2604.08923 (2026-04, XLM-RoBERTa dual regression heads, task-specific fine-tuning outperforming few-shot LLMs on every development set), the task paper 2604.07066 (2026-04-08, 112 final submissions, 42 system papers, the cF1 metric), LogSigma 2603.24896 (2026-03, uncertainty-weighted multitask learning, first place on five datasets across both tracks) and QuadAI 2603.07766 (2026-03, hybrid RoBERTa plus LLM ensemble). publisher · read in our library
knowledge/fetched/cmp_intelmine_arxiv_dimabsa_newest.atom· pinh809c01bb460f3b44134943fbd2a8f3b3cc8521497e3187d4d7e93c67982a0b67· accessed 2026-09-06 · mirrored-indexGrounds: ORACLE 2026: dated bars for aspect extraction and quad prediction, read from the field's 2025 to 2026 record (every number carries its year) - [atellm2026feed] arXiv API listing for all:aspect term extraction AND all:large language, 2 entries with abstracts, fetched 2026-09-06 over the estate's own TLS: Negi, Sarkar, Zayed and Buitelaar 2403.17254 (2024-03, LLM annotations complemented by syntactic dependencies for aspect term extraction) and Simmering and Huoviala 2310.18025 (2023-10, a fine-tuned GPT-3.5 scores F1 83.8 on the SemEval-2014 Task 4 joint aspect term extraction and polarity task, 5.7 points over InstructABSA, at a thousand times the parameters). publisher · read in our library
knowledge/fetched/cmp_intelmine_arxiv_ate_llm_recent.atom· pinhe3d14456912b129c967213073caa2f16ea6a77e52ab8319e78ed48e1238b430c· accessed 2026-09-06 · mirrored-indexGrounds: ORACLE 2026: dated bars for aspect extraction and quad prediction, read from the field's 2025 to 2026 record (every number carries its year)
generated by nx_swcompare_matrix (sovereign NishiLang organ) from knowledge/compare/intelmine.matrix · source checks show implementation presence; runtime and user-outcome evidence are reported separately · JavaScript supports page controls