Nishi Family › Compare › LLM and Inference Stack
Nishi Compare · capabilities, evidence and delivery
LLM and Inference Stack
Compare capabilities and delivery evidence. Source discovery, qualification, deployment and accepted outcomes are separate; an open contract names work still to verify.
Nishi vs llama.cpp and vLLM and Ollama and TensorRT-LLM
Overview
The purpose, declared position and evidence coverage of this domain. Source presence and completed acceptance are different measures.
Where we are. The sovereign inference stack runs real open weights bits-up: integer no-float forward pass, attention, layernorm, own BPE, GGUF loading of Qwen2.5-0.5B, Q4-K dot kernels, AVX2 integer GEMM, an OpenAI-shaped served chat API, and a tensor autograd substrate the inference-only peers lack; two exceeds -- the whole stack is ours with zero PyTorch CUDA or BLAS beneath, and inference is bit-exact by construction. Measured honestly behind llama.cpp on decode (about 15 tok/s vs a cited 20-60) with prefill at about 9 tok/s the remaining wall; absent: KV cache, continuous batching, speculative decoding, MoE, long context, a fused dequant GEMM, GPU offload.
Where we need to go. Serve at llama.cpp-class CPU speed with the determinism they cannot offer: batched prefill first (the measured wall), a KV cache so decode stops recomputing, a fused dequant GEMM (the named next rung), continuous batching across requests, then speculative decoding, long context and MoE -- and the GPU as a delivery cable behind the same bit-exact contract.
Research bar. llama.cpp is measured on CPU int4 K-quants, KV cache, speculative decoding, 20-60 tok/s at 0.5B. Theirs: the CPU reference. Ours: LM1-LM4 LM6 measured on this page.
Research bar. vLLM is measured on PagedAttention, continuous batching. Theirs: the serving reference. Ours: LM3 LM5.
Research bar. Marlin (arXiv 2408.11743) is measured on fused dequant GEMM for quantized weights. Theirs: the kernel reference. Ours: LM4.
Latest recorded release
2026-09-04 · M4
SEPTEMBER 2026 SOTA ADMITTED FOR INTEGER-ONLY INFERENCE AS COMPARE DATA: 22 pinned refs, 12 measurement rows, 6 pre-declared contracts. The sweep's LLM domain returned 26 findings and its adversarial verifier -- instructed to REFUTE -- confirmed 22 against primary sources, dropping 1 ALREADY-COMMON, 2 UNDATED and 1 REFUTED; the dropped four are named in the sweep record. Every confirmed source was fetched through the sovereign lane: 21 at status=200 on the first pass and ONE definitive 403 -- a vendor article behind a bot wall -- for which the finding was re-grounded on its primary, the llm-compressor 0.9.0 release page, at status=200 with the fetcher's own provenance sha, because a ref without a witnessed mirror is a fabrication here whatever the verifier said. Organ paths were RESOLVED, not guessed: three of the four nofloat gates whose subjects I needed import nx_nofloat_autograd.nx, located by nx_absent at runtime/nx_nofloat_autograd.nx with coverage_complete=1, and the linear-attention and serving organs at their _hdl_build paths -- a mispointed contract can never flip, so the path is part of the row. THE FINDINGS THAT CHANGE THE LANE, each pinned: integer softmax and LayerNorm whose normalization is GUARANTEED by arithmetic rather than compared to a float twin [intsoftmax26], with a fully integer attention pipeline needing no exponential at all [intattention25] and a per-head clipped-linear surrogate whose table is conf data [hccs26] -- rated the highest value-per-line item in the sweep and the only row on this section claiming an exceed on the kernel itself, because no rival runtime is float-free; MXFP4 closing its accuracy gap to under 1 percent with two software-only integer scaling fixes [mxfp4oas26], block-diagonal Hadamard at the MX block size as both the rotation fix [blockrot25] and the rotate half of the best real-serving KV quantizer [sawint4]; compression ratio a POOR predictor of end-to-end KV performance [kvbench26] and a KV method with an ICLR paper still unshipped in SGLang [turboquant-sglang], which together make the adoption GATE the deliverable rather than any method; hybrid linear attention shipped at frontier scale three-to-one [qwen35-397b] and independently by a second vendor [hybridmoe25], with chain-of-thought fine-tuning DESTROYING long-range recall in exactly that architecture [cotrecall26] -- so the interleave ratio is admitted as conf DATA under a NIAH gate, never a constant; bit-reproducible inference solved as a PROHIBITION on batch-dependent reductions [tm-determinism], made cheap by sparse token flips [tokenflips26] and a scheduler flag [llm42] -- and an integer-only stack has no float reassociation to defeat, so the prohibition is the whole fix; and ternary did NOT scale to a frontier generative model [bitnet], so the estate-shaped extraction is a ternary EMBEDDING scored by retrieval, with generative ternary named as do-not-build. Six contracts LM10 to LM15 under milestone M4 with ver 3.0, done-rules pre-declared with controls: the softmax sum-to-scale tooth must fail on a planted off-by-one, pack-then-unpack must be the identity, a full-dimension rotation must measurably degrade a planted MX block, batch 1 and batch 8 must emit identical token ids while a batch-dependent split is refused, an all-linear stack must be refused by the NIAH gate, and a small-model score without its output-token cost must be refused. All three appends verified single by row-unique counts on the NAS.
Release entries describe recorded changes; they do not establish that every capability passed evaluation.
12 of 32 capability source symbols found|2 of them authored stronger-claims|20 open|coverage 375/1000|adoption 8 full / 4 partial
Evidence profile — what the gaps on this board actually are
Measured by nx_swcompare_evidence, read back by nx_evprofile_lib. Every figure is a count with its denominator — there is deliberately no score, no grade and no percentage anywhere in this band, because a stored scalar is a field a seat can edit and a counted partition is not.
evidence|grounded 12/12|unsupported 0|gates green 2/2|proven able to fail 2/2|never bitten 0|green at 0/0 0|open gaps 20|of them unnamed 0|of them proof withheld 0|flips ready 1
proven able to fail counts the gates that have a RECORDED RED — nx_gate_bite mutated the gate subject, rebuilt it, watched the gate go red, and that record is inside the shared TTL. never bitten is its complement over the same denominator: those gates ran and were green, and nothing has ever shown them able to detect anything, so their green is a statement about this run and not about the gate. green at 0/0 is a separate and much weaker observation — the gate printed GREEN on a zero denominator, so its own tooth counter says it examined nothing. A gate can be green, non-zero, and still never bitten; that is the common case and it is now visible instead of implied.
partition: grounded + unsupported = 12 vs present 12 · named + unnamed + withheld = 20 vs open 20 · both reconcile
liar-kill conj=GPQN · all four conjuncts held
graded document: BUILDROOT tree, 12821 bytes · gates map: PRIMARY · stamped 2d 7h ago · source ../knowledge/status/evstamp_llm.verdict
| Gap class | What it is, and the work it names |
|---|---|
| FLIP-READY | A watch contract symbol is now present in the organ it named: the cell can flip on a pure data edit with no new code. These are the cheapest closures on this board and they belong before any new work. |
nx_swcompare_evidence llm itself and are not carried on the stamp, so this page names the classes and the producer names the rows. That split is stated rather than hidden: a count without a worklist is not actionable, and this band is honest about which half of that it is.Production map
Follow the dependencies, declared acceptance criteria and recorded priorities. Inspect source binding before treating a rank as executable work.
Ranking source binding: PLAN_MATRIX_BOUND_ONLY. Recorded priorities require current acceptance evidence and resource checks before execution.
Ranking matches the captured plan and matrix only. Latest execution outcome, research freshness, accepted delivery and investment return are unverified.
Recorded priority estimates
Order from nx_compare_rank (nx_dr_ocm: (deficit + cost-of-delay + option + enables) x sponsor x self-sufficiency x momentum / cost). FINISH rows are rungs whose symbol is present but whose organ is short of full adoption: listed before new work by this heuristic. Priority is not measured delivery cost or execution readiness. Stamp: # asof=1790081624 domain=llm target_version=0.1 rungs=21 done=5 open=16 finish=1 ranker=nx_dr_ocm
| # | Stage | Rung | Priority | Derivation |
|---|---|---|---|---|
| F | FINISH | AVX2 integer GEMM (LL2) i32x8_hsum dossier | LIB-GATE-ONLY importers=3 | imported only by validation organs (gates, tests, benches): wire it into a shipping program |
| #1 | 0.1 | Batched prefill (LM1) nsv_prefill_batch dossier | 1866 | v=14 m=2 c=15 |
| #2 | 0.1 | Speed bench on the beat (LM2) csb_decode_bar dossier | 600 | v=3 m=2 c=10 |
| #3 | later | KV cache (LM3) kv_paged_attn dossier | 1000 | v=10 m=2 c=20 |
| #4 | later | GPU offload (LM9) gpul_offload_layer dossier | 1000 | v=10 m=2 c=20 |
| #5 | later | MXFP4 pack and unpack are the identity on a planted tensor and match the shipped uint8 layout (LM11) nf_mxfp4_pack dossier | 1000 | v=10 m=1 c=10 |
| #6 | later | Mixture of experts (LM8) moe_route_experts dossier | 266 | v=4 m=2 c=30 |
| #7 | later | Long context (LM7) lctx_rope_scale dossier | 200 | v=4 m=1 c=20 |
| #8 | later | Speculative decoding (LM6) sd_draft_verify dossier | 150 | v=3 m=1 c=20 |
| #9 | later | Continuous batching (LM5) bs_continuous_batch dossier | 120 | v=3 m=1 c=25 |
| #10 | later | Every published small-model score carries its output-token cost and a discriminative control (LM15) ns_smallmodel_receipt dossier | 100 | v=1 m=1 c=10 |
| #11 | later | Integer softmax and LayerNorm whose normalization is proven by arithmetic on the emitted values (LM10) nf_softmax_exact dossier | 50 | v=1 m=1 c=20 |
| #12 | later | Block-diagonal Hadamard at the MX block size, fused with the quantizer (LM12) nf_block_hadamard dossier | 0 | v=0 m=1 c=20 |
| #13 | later | Reductions are batch-invariant by prohibition, and two batch sizes produce identical tokens (LM13) ns_batch_invariant dossier | 0 | v=0 m=1 c=30 |
| #14 | later | The hybrid interleave ratio is a conf row swept and measured, never a constant (LM14) la_interleave_conf dossier | 0 | v=0 m=1 c=20 |
| #15 | later | Estate-trained instruct model replaces the Qwen2.5 weights on the serve seat (LM16) nsv_estate_weights dossier | 0 | v=0 m=1 c=200 |
| #16 | later | The reasoning battery through the engine dispatcher (LK1) ed_reason_battery dossier | 0 | v=0 m=2 c=30 |
Declared roadmap — contract, acceptance, executor, effort
| Rung | Closes with | Definition of done (pre-declared) | Executor | Est. |
|---|---|---|---|---|
| Integer forward pass (LL0) | qmul | No-float transformer forward -- LANDED | Organ | 0 u |
| Q4-K dot kernels (LL1) after LL0 | nx_q4k_dot_row_col | Bit-exact quantized dot, 50.4 G mult/s dequant-dot -- LANDED | Organ | 0 u |
| AVX2 integer GEMM (LL2) after LL0 | i32x8_hsum | 7x pooled -- LANDED | Organ | 0 u |
| Served chat API (LL3) after LL0 | ls_extract_prompt | Sovereign seat on :11434 serving real Qwen -- LANDED | Organ | 0 u |
| Batched prefill (LM1) after LL2 | nsv_prefill_batch | Prefill as ONE batched GEMM over the prompt instead of m looped m=1 matmuls; pass-fail tooth: per-token prefill cost FALLS with prompt length on nx_embed_bench at m=8,32,64,125 -- flat means we did not enter the batched regime and must not claim it | Organ | 1.5 u |
| Speed bench on the beat (LM2) after LL3 | csb_decode_bar | An organ that measures decode and prefill tok/s at 0.5B on the beat and publishes them beside the declared bar (20 tok/s decode) with thread count and model sha; gate proves the numbers parse back from its log and a stale measurement abstains | Organ | 1 u |
| KV cache (LM3) after LL0 | kv_paged_attn | Cached K and V per layer with paged blocks so decode attends over the cache instead of recomputing; gate proves token-for-token bit-identical output against the uncached path and a per-token time that stops growing with position | Organ | 2 u |
| Fused dequant GEMM (LM4) after LL1,LL2 | mq_fused_dequant_gemm | A Marlin-class kernel reading quantized weights and accumulating in integer without the F32 re-dequant (the measured wall); gate proves bit-identical results to LL1 and a measured speedup on the same bench | Organ | 2 u |
| Continuous batching (LM5) after LM3 | bs_continuous_batch | Requests join and leave a running batch between steps in the serve loop; gate proves two concurrent requests complete with outputs identical to their solo runs and aggregate tok/s above a single stream | Organ | 2.5 u |
| Speculative decoding (LM6) after LM3,LM1 | sd_draft_verify | A draft pass proposes k tokens the target verifies in one batched step, accepting the longest matching prefix; gate proves output identical to plain decode and acceptance rate published | Organ | 2 u |
| Long context (LM7) after LM3 | lctx_rope_scale | RoPE scaling with the KV cache to 100K-class windows under a declared memory budget; gate proves a needle-in-haystack fixture at the declared length is retrieved and the memory stays inside budget | Organ | 2 u |
| Mixture of experts (LM8) after LL0 | moe_route_experts | Top-k expert routing in the forward pass over an MoE GGUF; gate proves a reference MoE layer matches the float reference greedy-for-greedy as the dense path already does | Organ | 3 u |
| GPU offload (LM9) after LM4 | gpul_offload_layer | Per-layer offload through the estate's GPU delivery cable with the bit-exact contract kept (integer kernels on device); gate proves an offloaded layer produces bit-identical activations to CPU | Organ | 2 u |
Milestones
| Milestone | Rungs | Cumulative |
|---|---|---|
| M1 · The prefill wall | LM1,LM2 | 2.5 u |
| M2 · llama.cpp-class decode | LM3,LM4 | 6.5 u |
| M3 · A serving stack and beyond | LM5,LM6,LM7,LM8,LM9 | 18 u |
| Rung | Closes with | Definition of done (pre-declared) | Executor | Est. |
|---|---|---|---|---|
| Integer softmax and LayerNorm whose normalization is proven by arithmetic on the emitted values (LM10) | nf_softmax_exact | DONE-RULE PRE-DECLARED 2026-09-04. The softmax accumulator sums to the scale factor and the LayerNorm output variance equals one, asserted with gv_check_eq on the kernels' own outputs [intsoftmax26] [intattention25]; a planted off-by-one in the reciprocal must fail the sum tooth. No float twin is consulted. | Organ | 2 u |
| MXFP4 pack and unpack are the identity on a planted tensor and match the shipped uint8 layout (LM11) | nf_mxfp4_pack | DONE-RULE PRE-DECLARED 2026-09-04. pack then unpack reproduces the input byte-for-byte [llmcompressor090]; a planted layout offset error must break the identity. Pure integer bit manipulation. | Organ | 1 u |
| Block-diagonal Hadamard at the MX block size, fused with the quantizer (LM12) after LM11 | nf_block_hadamard | DONE-RULE PRE-DECLARED 2026-09-04. Rotation is block-diagonal at 32 and applied in one pass with token-wise INT4 [blockrot25] [sawint4]; the control is a full-dimension rotation on the same tensor, which must measurably degrade a planted MX block. | Organ | 2 u |
| Reductions are batch-invariant by prohibition, and two batch sizes produce identical tokens (LM13) | ns_batch_invariant | DONE-RULE PRE-DECLARED 2026-09-04. A gate refuses any kernel whose tiling reads a batch-dependent quantity [tm-determinism]; the margin monitor publishes its trigger rate [tokenflips26]; the per-request flag routes to the pinned path [llm42]. Proof: batch 1 and batch 8 on the same prompt emit identical token ids, and a deliberately batch-dependent split must be refused. | Organ | 3 u |
| The hybrid interleave ratio is a conf row swept and measured, never a constant (LM14) | la_interleave_conf | DONE-RULE PRE-DECLARED 2026-09-04. A layer-stack descriptor names which layers are linear and which are full [qwen35-397b] [hybridmoe25]; a sweep over ratios runs and reports recall per ratio; a planted all-linear stack is refused by the NIAH gate. | Organ | 2 u |
| Every published small-model score carries its output-token cost and a discriminative control (LM15) | ns_smallmodel_receipt | DONE-RULE PRE-DECLARED 2026-09-04. The receipt carries score, output tokens per task and the encoder-baseline result [aa-smallmodels] [smallvsfrontier26]; a score row without the token field is refused by the refs gate's version tooth. | Organ | 1 u |
Milestones
| Milestone | Rungs | Cumulative |
|---|---|---|
| M4 · September 2026 SOTA: the field's integer-only inference findings admitted as bars, watches and pre-declared contracts | LM10,LM11,LM12,LM13,LM14,LM15 | 11 u |
| Rung | Closes with | Definition of done (pre-declared) | Executor | Est. |
|---|---|---|---|---|
| Estate-trained instruct model replaces the Qwen2.5 weights on the serve seat (LM16) after LM9,LM1 | nsv_estate_weights | The serve seat loads a model whose weights the estate trained (the nofloat lane's own training stack, on the GPU door once LM9 lands) from licensed data, and its KAT battery through nx_engine_dispatch matches or exceeds the Qwen2.5 seat it replaces at the same size class; the foreign GGUF leaves the run path and llm.assets flips its rows to retired. The 0.5B lands first (the size the laptop can train end to end), the 7B follows on the door. | Organ | 20 u |
| The reasoning battery through the engine dispatcher (LK1) after LL3 | ed_reason_battery | DONE-RULE PRE-DECLARED: GPQA Diamond, MMLU-Pro, a licensed Humanity's Last Exam sample and the ARC-AGI-2 public evaluation set are mirrored with licences and run through nx_engine_dispatch on the local no-float seat, the external U tier and the frontier seat; every score is judged by the benchmark's own answer key (KAT judging), published per engine with n and the 96-token ceiling named, and the local seat's expected loss is the build target, never hidden [gpqa23] [mmlupro24] [hle26] [arcprize26] | Organ | 3 u |
| Class | Count | Note |
|---|---|---|
| bars | 2 | sotabar rows on the plan |
| fresh | 0 | the bar month is the current month |
| attested | 0 | an older bar with a this-month barscan reporting no newer entry |
| stale | 0 | a this-month scan saw a newer month the bar ignores |
| unattested | 2 | nobody looked this month |
| malformed | 0 | a sotabar row missing a field |
| duplicate | 0 | bar ids an earlier row already carries |
| bars, summed | 2 | RECONCILED: the parts sum to the total 2 |
| current month | 2026-10 | the month every bar is judged against |
Inspect a rung and its prerequisites
Declared nodes 21. Rank input binding: PLAN_MATRIX_BOUND_ONLY. Dependency order is authored. Implementation, acceptance evidence, authority and resource readiness are unverified. No action is recommended or dispatched here.
Plan SHA-256 26553551631466ae01b43febb5cdb628ef6b61d268935a19707551e12d3de5ff. Target rows 0; role rows 0. Existing risks and release worklog retain their own scope; no node completion is inferred.
Runtime observation coverage: 0 of 21 rungs have current, identity-bound execution observations. Observation may report RED. Accepted completion remains unknown; source presence, qualification and deployment do not establish it.
Use Enter or Space on a rung to inspect its contract. Prerequisite links locate another rung in this list; open its summary to inspect it. Estimates are authored effort, not forecasts.
LL0 — Integer forward pass
Prerequisites: None declared; this does not establish execution eligibility.
Contract:
qmulAcceptance: No-float transformer forward -- LANDED
Authored effort: 0. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.LL1 — Q4-K dot kernels
Prerequisites: LL0 (acceptance unverified)
Contract:
nx_q4k_dot_row_colAcceptance: Bit-exact quantized dot, 50.4 G mult/s dequant-dot -- LANDED
Authored effort: 0. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.LL2 — AVX2 integer GEMM
Prerequisites: LL0 (acceptance unverified)
Contract:
i32x8_hsumAcceptance: 7x pooled -- LANDED
Authored effort: 0. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.LL3 — Served chat API
Prerequisites: LL0 (acceptance unverified)
Contract:
ls_extract_promptAcceptance: Sovereign seat on :11434 serving real Qwen -- LANDED
Authored effort: 0. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.LM1 — Batched prefill
Prerequisites: LL2 (acceptance unverified)
Contract:
nsv_prefill_batchAcceptance: Prefill as ONE batched GEMM over the prompt instead of m looped m=1 matmuls; pass-fail tooth: per-token prefill cost FALLS with prompt length on nx_embed_bench at m=8,32,64,125 -- flat means we did not enter the batched regime and must not claim it
Authored effort: 1.5. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.LM2 — Speed bench on the beat
Prerequisites: LL3 (acceptance unverified)
Contract:
csb_decode_barAcceptance: An organ that measures decode and prefill tok/s at 0.5B on the beat and publishes them beside the declared bar (20 tok/s decode) with thread count and model sha; gate proves the numbers parse back from its log and a stale measurement abstains
Authored effort: 1. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.LM3 — KV cache
Prerequisites: LL0 (acceptance unverified)
Contract:
kv_paged_attnAcceptance: Cached K and V per layer with paged blocks so decode attends over the cache instead of recomputing; gate proves token-for-token bit-identical output against the uncached path and a per-token time that stops growing with position
Authored effort: 2. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.LM4 — Fused dequant GEMM
Prerequisites: LL1 (acceptance unverified), LL2 (acceptance unverified)
Contract:
mq_fused_dequant_gemmAcceptance: A Marlin-class kernel reading quantized weights and accumulating in integer without the F32 re-dequant (the measured wall); gate proves bit-identical results to LL1 and a measured speedup on the same bench
Authored effort: 2. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.LM5 — Continuous batching
Prerequisites: LM3 (acceptance unverified)
Contract:
bs_continuous_batchAcceptance: Requests join and leave a running batch between steps in the serve loop; gate proves two concurrent requests complete with outputs identical to their solo runs and aggregate tok/s above a single stream
Authored effort: 2.5. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.LM6 — Speculative decoding
Prerequisites: LM3 (acceptance unverified), LM1 (acceptance unverified)
Contract:
sd_draft_verifyAcceptance: A draft pass proposes k tokens the target verifies in one batched step, accepting the longest matching prefix; gate proves output identical to plain decode and acceptance rate published
Authored effort: 2. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.LM7 — Long context
Prerequisites: LM3 (acceptance unverified)
Contract:
lctx_rope_scaleAcceptance: RoPE scaling with the KV cache to 100K-class windows under a declared memory budget; gate proves a needle-in-haystack fixture at the declared length is retrieved and the memory stays inside budget
Authored effort: 2. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.LM8 — Mixture of experts
Prerequisites: LL0 (acceptance unverified)
Contract:
moe_route_expertsAcceptance: Top-k expert routing in the forward pass over an MoE GGUF; gate proves a reference MoE layer matches the float reference greedy-for-greedy as the dense path already does
Authored effort: 3. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.LM9 — GPU offload
Prerequisites: LM4 (acceptance unverified)
Contract:
gpul_offload_layerAcceptance: Per-layer offload through the estate's GPU delivery cable with the bit-exact contract kept (integer kernels on device); gate proves an offloaded layer produces bit-identical activations to CPU
Authored effort: 2. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.LM10 — Integer softmax and LayerNorm whose normalization is proven by arithmetic on the emitted values
Prerequisites: None declared; this does not establish execution eligibility.
Contract:
nf_softmax_exactAcceptance: DONE-RULE PRE-DECLARED 2026-09-04. The softmax accumulator sums to the scale factor and the LayerNorm output variance equals one, asserted with gv_check_eq on the kernels' own outputs [@intsoftmax26] [@intattention25]; a planted off-by-one in the reciprocal must fail the sum tooth. No float twin is consulted.
Authored effort: 2. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.LM11 — MXFP4 pack and unpack are the identity on a planted tensor and match the shipped uint8 layout
Prerequisites: None declared; this does not establish execution eligibility.
Contract:
nf_mxfp4_packAcceptance: DONE-RULE PRE-DECLARED 2026-09-04. pack then unpack reproduces the input byte-for-byte [@llmcompressor090]; a planted layout offset error must break the identity. Pure integer bit manipulation.
Authored effort: 1. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.LM12 — Block-diagonal Hadamard at the MX block size, fused with the quantizer
Prerequisites: LM11 (acceptance unverified)
Contract:
nf_block_hadamardAcceptance: DONE-RULE PRE-DECLARED 2026-09-04. Rotation is block-diagonal at 32 and applied in one pass with token-wise INT4 [@blockrot25] [@sawint4]; the control is a full-dimension rotation on the same tensor, which must measurably degrade a planted MX block.
Authored effort: 2. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.LM13 — Reductions are batch-invariant by prohibition, and two batch sizes produce identical tokens
Prerequisites: None declared; this does not establish execution eligibility.
Contract:
ns_batch_invariantAcceptance: DONE-RULE PRE-DECLARED 2026-09-04. A gate refuses any kernel whose tiling reads a batch-dependent quantity [@tm-determinism]; the margin monitor publishes its trigger rate [@tokenflips26]; the per-request flag routes to the pinned path [@llm42]. Proof: batch 1 and batch 8 on the same prompt emit identical token ids, and a deliberately batch-dependent split must be refused.
Authored effort: 3. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.LM14 — The hybrid interleave ratio is a conf row swept and measured, never a constant
Prerequisites: None declared; this does not establish execution eligibility.
Contract:
la_interleave_confAcceptance: DONE-RULE PRE-DECLARED 2026-09-04. A layer-stack descriptor names which layers are linear and which are full [@qwen35-397b] [@hybridmoe25]; a sweep over ratios runs and reports recall per ratio; a planted all-linear stack is refused by the NIAH gate.
Authored effort: 2. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.LM15 — Every published small-model score carries its output-token cost and a discriminative control
Prerequisites: None declared; this does not establish execution eligibility.
Contract:
ns_smallmodel_receiptAcceptance: DONE-RULE PRE-DECLARED 2026-09-04. The receipt carries score, output tokens per task and the encoder-baseline result [@aa-smallmodels] [@smallvsfrontier26]; a score row without the token field is refused by the refs gate's version tooth.
Authored effort: 1. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.LM16 — Estate-trained instruct model replaces the Qwen2.5 weights on the serve seat
Prerequisites: LM9 (acceptance unverified), LM1 (acceptance unverified)
Contract:
nsv_estate_weightsAcceptance: The serve seat loads a model whose weights the estate trained (the nofloat lane's own training stack, on the GPU door once LM9 lands) from licensed data, and its KAT battery through nx_engine_dispatch matches or exceeds the Qwen2.5 seat it replaces at the same size class; the foreign GGUF leaves the run path and llm.assets flips its rows to retired. The 0.5B lands first (the size the laptop can train end to end), the 7B follows on the door.
Authored effort: 20. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.LK1 — The reasoning battery through the engine dispatcher
Prerequisites: LL3 (acceptance unverified)
Contract:
ed_reason_batteryAcceptance: DONE-RULE PRE-DECLARED: GPQA Diamond, MMLU-Pro, a licensed Humanity's Last Exam sample and the ARC-AGI-2 public evaluation set are mirrored with licences and run through nx_engine_dispatch on the local no-float seat, the external U tier and the frontier seat; every score is judged by the benchmark's own answer key (KAT judging), published per engine with n and the 96-token ceiling named, and the local seat's expected loss is the build target, never hidden [@gpqa23] [@mmlupro24] [@hle26] [@arcprize26]
Authored effort: 3. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.
Learning and practice paths
No structured learning path is declared for this plan. Existing research, roadmap and worklog remain available above.
Rung dossiers — every record that bears on a rung, in one place
nx_swcompare_evidence llm writes it beside its stamp); every gate below reads UNRECORDED until it runs.knowledge/organ_gate.conf read from this working directory (1 rows) and from the estate root (196 rows); rows in both counted once: 0; declarations read: 197. Every declaration in either copy counts, so a stub beside the publisher can never hide the root.LL0 Integer forward pass · cell PRESENT · gate NO-GATE-DECLARED
| Contract | qmul · executor Organ · 0 u · stands on nothing |
|---|---|
| Definition of done | No-float transformer forward -- LANDED |
| Matrix cell | Transformer forward pass · runtime/nx_nofloat_llm.nx · PRESENT declSovereign -- own language, compiler, kernels; zero PyTorch / CUDA / BLAS beneath · runtime/nx_nofloat_llm.nx · PRESENT decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_nofloat_llm; declare nx_nofloat_llm TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
LL1 Q4-K dot kernels · cell PRESENT · gate NO-GATE-DECLARED
| Contract | nx_q4k_dot_row_col · executor Organ · 0 u · stands on LL0 |
|---|---|
| Definition of done | Bit-exact quantized dot, 50.4 G mult/s dequant-dot -- LANDED |
| Matrix cell | Int4 quantized inference · runtime/nx_q4k_matmul.nx · PRESENT declInteger-deterministic bit-exact inference by construction · runtime/nx_q4k_matmul.nx · PRESENT decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_q4k_matmul; declare nx_q4k_matmul TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
LL2 AVX2 integer GEMM · cell PRESENT · gate NO-GATE-DECLARED
| Contract | i32x8_hsum · executor Organ · 0 u · stands on LL0 |
|---|---|
| Definition of done | 7x pooled -- LANDED |
| Matrix cell | SIMD-tuned CPU kernels · runtime/nx_nofloat_gemm.nx · PRESENT decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_nofloat_gemm; declare nx_nofloat_gemm TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
LL3 Served chat API · cell PRESENT · gate NO-GATE-DECLARED
| Contract | ls_extract_prompt · executor Organ · 0 u · stands on LL0 |
|---|---|
| Definition of done | Sovereign seat on :11434 serving real Qwen -- LANDED |
| Matrix cell | Served chat API (OpenAI-shaped) · runtime/nx_f32_llm_serve.nx · PRESENT decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_f32_llm_serve; declare nx_f32_llm_serve TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
LM1 Batched prefill · cell WATCHING · gate NO-GATE-DECLARED
| Contract | nsv_prefill_batch · executor Organ · 1.5 u · stands on LL2 |
|---|---|
| Definition of done | Prefill as ONE batched GEMM over the prompt instead of m looped m=1 matmuls; pass-fail tooth: per-token prefill cost FALLS with prompt length on nx_embed_bench at m=8,32,64,125 -- flat means we did not enter the batched regime and must not claim it |
| Matrix cell | Batched prefill (the prefill wall) · runtime/nx_nofloat_serve_core.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_nofloat_serve_core; declare nx_nofloat_serve_core TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
LM2 Speed bench on the beat · cell WATCHING · gate NO-GATE-DECLARED
| Contract | csb_decode_bar · executor Organ · 1 u · stands on LL3 |
|---|---|
| Definition of done | An organ that measures decode and prefill tok/s at 0.5B on the beat and publishes them beside the declared bar (20 tok/s decode) with thread count and model sha; gate proves the numbers parse back from its log and a stale measurement abstains |
| Matrix cell | Competitive CPU speed (20+ tok/s at 0.5B) · runtime/nx_cpu_speed_bar.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_cpu_speed_bar; declare nx_cpu_speed_bar TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
LM3 KV cache · cell WATCHING · gate NO-GATE-DECLARED
| Contract | kv_paged_attn · executor Organ · 2 u · stands on LL0 |
|---|---|
| Definition of done | Cached K and V per layer with paged blocks so decode attends over the cache instead of recomputing; gate proves token-for-token bit-identical output against the uncached path and a per-token time that stops growing with position |
| Matrix cell | KV-cache / paged attention · runtime/nx_kvcache.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_kvcache; declare nx_kvcache TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
LM4 Fused dequant GEMM · cell LANDED · gate NO-GATE-DECLARED
| Contract | mq_fused_dequant_gemm · executor Organ · 2 u · stands on LL1, LL2 |
|---|---|
| Definition of done | A Marlin-class kernel reading quantized weights and accumulating in integer without the F32 re-dequant (the measured wall); gate proves bit-identical results to LL1 and a measured speedup on the same bench |
| Matrix cell | Marlin-class fused dequant GEMM · runtime/nx_nofloat_q4k.nx · LANDED decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_nofloat_q4k; declare nx_nofloat_q4k TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | 2026-09-02 land mq_fused_dequant_gemm SHIPPED in runtime/nx_nofloat_q4k.nx (laptop and NAS source): Q4_K weights stay in the file map and are dotted by the fused SIMD kernel nx_q4k_dot_simd_lib; bit-identical to the scalar Q4_K dot (bench organ bit_exact=1) at 2.09x its speed; nx_nofloat_q4k_gate 17 of 17 GREEN; the watch row now points at the file that shipped 2026-09-02 measure Qwen2.5-Coder-7B Q4_K_M serves on the 16 GB laptop through the q4k route at 8.32 GB RSS and 1690 to 1868 ms per token (two identical greedy runs); 1.5B 428 to 506 ms per token at 2.27 GB versus 254 ms per token at 10.4 GB on the i16 cache route, text identical; the residual is the per-row nibble unpack in scalar code, so the next lever is a SIMD unpack intrinsic in nx_cc, not more cache 2026-09-02 measure with the nx_cc intrinsic __q4k_unpack32s (lang LN28) in the fused dot: 7B Q4_K_M 819 ms per token warm (1283 cold, first touch of the 3.1 GB file map), 1.5B 413 ms warm, greedy text unchanged across all four kernel cuts; the fused dot is bit-exact against the scalar Q4_K dot and 3.94x faster than the scalar-unpack SIMD dot on the 14-super-block row; the serve gained less than the kernel, so the remainder is being attributed with per-route ns accumulators on /health before the next cut |
LM5 Continuous batching · cell WATCHING · gate NO-GATE-DECLARED
| Contract | bs_continuous_batch · executor Organ · 2.5 u · stands on LM3 |
|---|---|
| Definition of done | Requests join and leave a running batch between steps in the serve loop; gate proves two concurrent requests complete with outputs identical to their solo runs and aggregate tok/s above a single stream |
| Matrix cell | Continuous batching throughput · runtime/nx_batch_serve.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_batch_serve; declare nx_batch_serve TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
LM6 Speculative decoding · cell WATCHING · gate NO-GATE-DECLARED
| Contract | sd_draft_verify · executor Organ · 2 u · stands on LM3, LM1 |
|---|---|
| Definition of done | A draft pass proposes k tokens the target verifies in one batched step, accepting the longest matching prefix; gate proves output identical to plain decode and acceptance rate published |
| Matrix cell | Speculative decoding · runtime/nx_specdec.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_specdec; declare nx_specdec TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
LM7 Long context · cell WATCHING · gate NO-GATE-DECLARED
| Contract | lctx_rope_scale · executor Organ · 2 u · stands on LM3 |
|---|---|
| Definition of done | RoPE scaling with the KV cache to 100K-class windows under a declared memory budget; gate proves a needle-in-haystack fixture at the declared length is retrieved and the memory stays inside budget |
| Matrix cell | Long-context inference (100K+) · runtime/nx_longctx.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_longctx; declare nx_longctx TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
LM8 Mixture of experts · cell WATCHING · gate NO-GATE-DECLARED
| Contract | moe_route_experts · executor Organ · 3 u · stands on LL0 |
|---|---|
| Definition of done | Top-k expert routing in the forward pass over an MoE GGUF; gate proves a reference MoE layer matches the float reference greedy-for-greedy as the dense path already does |
| Matrix cell | Mixture-of-experts · runtime/nx_moe.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_moe; declare nx_moe TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
LM9 GPU offload · cell WATCHING · gate NO-GATE-DECLARED
| Contract | gpul_offload_layer · executor Organ · 2 u · stands on LM4 |
|---|---|
| Definition of done | Per-layer offload through the estate's GPU delivery cable with the bit-exact contract kept (integer kernels on device); gate proves an offloaded layer produces bit-identical activations to CPU |
| Matrix cell | GPU acceleration · runtime/nx_gpu_llm.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_gpu_llm; declare nx_gpu_llm TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
LM10 Integer softmax and LayerNorm whose normalization is proven by arithmetic on the emitted values · cell WATCHING · gate NO-GATE-DECLARED
| Contract | nf_softmax_exact · executor Organ · 2 u · stands on nothing |
|---|---|
| Definition of done | DONE-RULE PRE-DECLARED 2026-09-04. The softmax accumulator sums to the scale factor and the LayerNorm output variance equals one, asserted with gv_check_eq on the kernels' own outputs [intsoftmax26] [intattention25]; a planted off-by-one in the reciprocal must fail the sum tooth. No float twin is consulted. |
| Matrix cell | Integer softmax and LayerNorm with guaranteed normalization · runtime/nx_nofloat_autograd.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_nofloat_autograd; declare nx_nofloat_autograd TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
LM11 MXFP4 pack and unpack are the identity on a planted tensor and match the shipped uint8 layout · cell WATCHING · gate NO-GATE-DECLARED
| Contract | nf_mxfp4_pack · executor Organ · 1 u · stands on nothing |
|---|---|
| Definition of done | DONE-RULE PRE-DECLARED 2026-09-04. pack then unpack reproduces the input byte-for-byte [llmcompressor090]; a planted layout offset error must break the identity. Pure integer bit manipulation. |
| Matrix cell | MXFP4 pack and unpack matching the shipped uint8 layout · runtime/nx_nofloat_autograd.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_nofloat_autograd; declare nx_nofloat_autograd TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
LM12 Block-diagonal Hadamard at the MX block size, fused with the quantizer · cell WATCHING · gate NO-GATE-DECLARED
| Contract | nf_block_hadamard · executor Organ · 2 u · stands on LM11 |
|---|---|
| Definition of done | DONE-RULE PRE-DECLARED 2026-09-04. Rotation is block-diagonal at 32 and applied in one pass with token-wise INT4 [blockrot25] [sawint4]; the control is a full-dimension rotation on the same tensor, which must measurably degrade a planted MX block. |
| Matrix cell | Block-diagonal Hadamard at the MX block size · runtime/nx_nofloat_autograd.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_nofloat_autograd; declare nx_nofloat_autograd TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
LM13 Reductions are batch-invariant by prohibition, and two batch sizes produce identical tokens · cell WATCHING · gate NO-GATE-DECLARED
| Contract | ns_batch_invariant · executor Organ · 3 u · stands on nothing |
|---|---|
| Definition of done | DONE-RULE PRE-DECLARED 2026-09-04. A gate refuses any kernel whose tiling reads a batch-dependent quantity [tm-determinism]; the margin monitor publishes its trigger rate [tokenflips26]; the per-request flag routes to the pinned path [llm42]. Proof: batch 1 and batch 8 on the same prompt emit identical token ids, and a deliberately batch-dependent split must be refused. |
| Matrix cell | Batch-invariant reductions, a margin monitor and a determinism flag · runtime/_hdl_build/nx_nofloat_serve.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_nofloat_serve; declare nx_nofloat_serve TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
LM14 The hybrid interleave ratio is a conf row swept and measured, never a constant · cell WATCHING · gate NO-GATE-DECLARED
| Contract | la_interleave_conf · executor Organ · 2 u · stands on nothing |
|---|---|
| Definition of done | DONE-RULE PRE-DECLARED 2026-09-04. A layer-stack descriptor names which layers are linear and which are full [qwen35-397b] [hybridmoe25]; a sweep over ratios runs and reports recall per ratio; a planted all-linear stack is refused by the NIAH gate. |
| Matrix cell | Hybrid interleave ratio as data · runtime/_hdl_build/nx_nofloat_linattn.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_nofloat_linattn; declare nx_nofloat_linattn TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
LM15 Every published small-model score carries its output-token cost and a discriminative control · cell WATCHING · gate NO-GATE-DECLARED
| Contract | ns_smallmodel_receipt · executor Organ · 1 u · stands on nothing |
|---|---|
| Definition of done | DONE-RULE PRE-DECLARED 2026-09-04. The receipt carries score, output tokens per task and the encoder-baseline result [aa-smallmodels] [smallvsfrontier26]; a score row without the token field is refused by the refs gate's version tooth. |
| Matrix cell | Small-model receipt: token cost beside the score and a discriminative control · runtime/_hdl_build/nx_nofloat_serve.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_nofloat_serve; declare nx_nofloat_serve TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
LM16 Estate-trained instruct model replaces the Qwen2.5 weights on the serve seat · cell NO-MATRIX-ROW · gate NO-MATRIX-ROW
| Contract | nsv_estate_weights · executor Organ · 20 u · stands on LM9, LM1 |
|---|---|
| Definition of done | The serve seat loads a model whose weights the estate trained (the nofloat lane's own training stack, on the GPU door once LM9 lands) from licensed data, and its KAT battery through nx_engine_dispatch matches or exceeds the Qwen2.5 seat it replaces at the same size class; the foreign GGUF leaves the run path and llm.assets flips its rows to retired. The 0.5B lands first (the size the laptop can train end to end), the 7B follows on the door. |
| Matrix cell | NO-MATRIX-ROW — no matrix row carries nsv_estate_weights; the ranker reads this rung as unmapped and no cell can flip for it. Add the row and the join completes on the next publish. |
| Gate | the gate join needs a matrix row: no organ is named for this rung |
| Work log | 2026-09-16 queue FOREIGN ASSETS ON THIS BOARD, PRICED (operator 2026-09-16: open weights now as licensed data assets, ours over time, with the lift to replace each shown on /compare): llm.assets lists the Qwen2.5-Coder-7B Q4_K_M and the Qwen2.5-0.5B GGUFs as runpath weights (apache-2.0) replaced by LM16 at 12 / 20 / 40 u (components named on the rows), rendered by the compare base through nx_assets_lib and priced through nx_costest_lib; the hours conversion comes from knowledge/status/costcal.ledger, the calibration nx_costcal derives from every board's own journal rows |
LK1 The reasoning battery through the engine dispatcher · cell NO-MATRIX-ROW · gate NO-MATRIX-ROW
| Contract | ed_reason_battery · executor Organ · 3 u · stands on LL3 |
|---|---|
| Definition of done | DONE-RULE PRE-DECLARED: GPQA Diamond, MMLU-Pro, a licensed Humanity's Last Exam sample and the ARC-AGI-2 public evaluation set are mirrored with licences and run through nx_engine_dispatch on the local no-float seat, the external U tier and the frontier seat; every score is judged by the benchmark's own answer key (KAT judging), published per engine with n and the 96-token ceiling named, and the local seat's expected loss is the build target, never hidden [gpqa23] [mmlupro24] [hle26] [arcprize26] |
| Matrix cell | NO-MATRIX-ROW — no matrix row carries ed_reason_battery; the ranker reads this rung as unmapped and no cell can flip for it. Add the row and the join completes on the next publish. |
| Gate | the gate join needs a matrix row: no organ is named for this rung |
| Work log | no log row names this rung yet |
dossiers=21 cells_joined=19 no_matrix_row=2 (sum 21) gates_recorded=0 gates_unrecorded=0 no_gate_declared=19 (sum 19 of cells_joined) evgates=UNSTAMPED
Capability comparisons
Compare the field, search individual capabilities and open their source and adoption evidence. Documented presence does not establish comparative quality.
Position map — centrality and distinctiveness
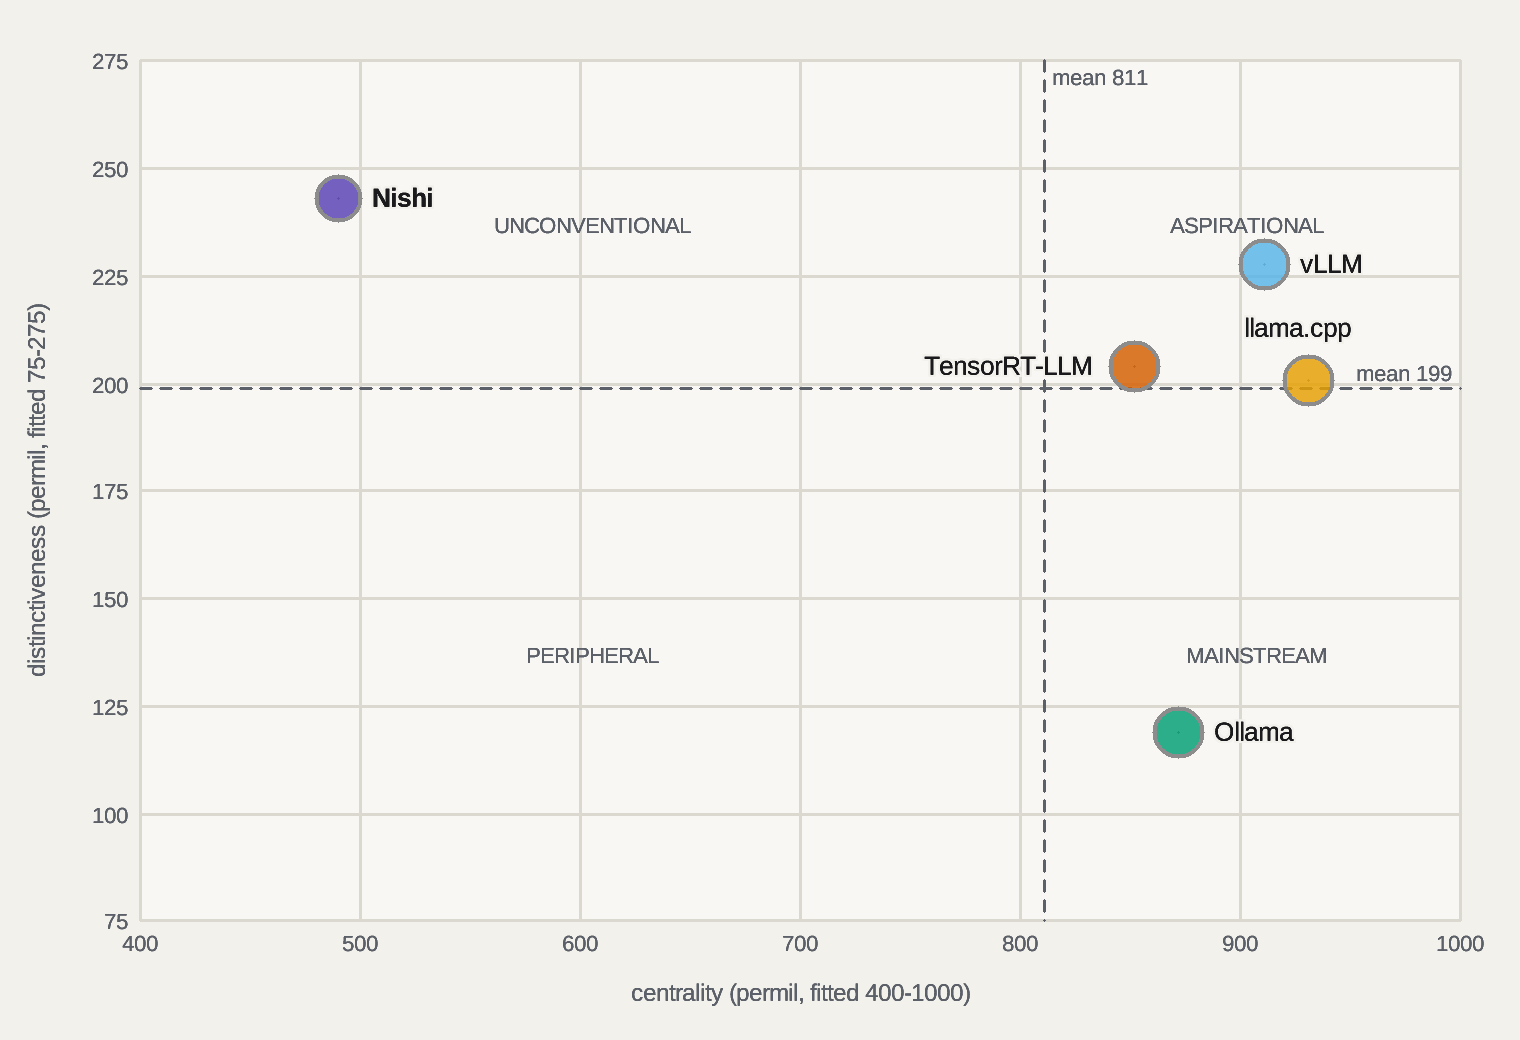
The four-quadrant map the field uses for brand strategy (Dawar and Bagga, HBR June 2015), re-derived from this matrix on every publish. Centrality is the share of the category's feature mass a player covers, each feature weighted by how many hold it; distinctiveness is the average lead over each rival on the rows the player holds; breadth is the depth-weighted share of the whole matrix (the bubble); depth is how deeply the rows held are held; momentum is the day-over-day move off the spine (green rising, red falling, grey until day two); the dashed path runs first day → previous day → today. Dividers are the category means. Axes are fitted to the field of play, so read the tick numerals, not the frame. Rival marks are documented presence, so a rival's position reads the record, never its quality. The picture grades its own readability below; the table beside it is the same data for a screen reader or a second method.
knowledge/compare/llm.cdmap (cut|x|y, cube|x|y|z); absent = the HBR defaultsbubble area = breadth · ring = momentum (green rising, red falling, grey until day two) · dashed = category means · axes fitted to the field of play: centrality 400–1000, distinctiveness 75–275 of 0–1000 permil (the full range put every player in one corner)
readability of the 2D cut, self-graded by the layout ruler: label overlaps 0 · labels over marks 0 · off-canvas 0 · unresolved labels 0 · mark overlaps 0 (a fact of the data: two players that close are that close) · data spread 677 permil of the plot · quadrant words unseated 0
text contrast, measured with wcag2-ratio (floors from contrast.conf), light theme: labels 16.24 (floor 4.50) · notes 16.24 (floor 4.50) · quadrant words 5.89 (floor 4.50) · tick numerals 5.89 (floor 4.50) · axis titles 5.59 (floor 4.50) · dark theme: labels 13.78 (floor 4.50) · quadrant words 5.55 (floor 4.50) · axis titles 5.97 (floor 4.50) · dark classes under their floor 0 (one figure serves both themes: a dark shortfall is a token to fix, never a class to hide) · classes refused under their floor 0 (a refused class is not drawn; the scale classes are measured, never hidden) · export: SVG PNG (receipt, rendered by the estate's own rasteriser from this page)

readability of the 3D cube, self-graded by the layout ruler: label overlaps 0 · labels over marks 0 · off-canvas 0 · unresolved labels 0 · mark overlaps 1 (a fact of the data: two players that close are that close) · data spread 388 permil of the plot
10 panels over 5 registered axes, every pair once (the lower axis on x, the higher on y) · each panel fitted to its own field of play, first and last tick numerals shown · no labels in a small cut, the legend names the colours; the grade below reports the mark terms only (MM summed over the panels, spread averaged)
readability of the small multiples, self-graded by the layout ruler: label overlaps 0 · labels over marks 0 · off-canvas 0 · unresolved labels 0 · mark overlaps 7 (a fact of the data: two players that close are that close) · data spread 541 permil of the plot
| Player | Quadrant | centrality | distinctiveness | breadth | depth | momentum | Rows held | Days on spine | First seen |
|---|---|---|---|---|---|---|---|---|---|
| Nishi | Unconventional | 490 | 243 | 270 | 722 | 0 since 2026-09-23 | 12 | 10 | 2026-09-15 |
| llama.cpp | Aspirational | 931 | 201 | 468 | 625 | 0 since 2026-09-23 | 24 | 10 | 2026-09-15 |
| vLLM | Aspirational | 911 | 228 | 479 | 666 | 0 since 2026-09-23 | 23 | 10 | 2026-09-15 |
| Ollama | Mainstream | 872 | 119 | 375 | 571 | 0 since 2026-09-23 | 21 | 10 | 2026-09-15 |
| TensorRT-LLM | Aspirational | 852 | 204 | 437 | 636 | 0 since 2026-09-23 | 22 | 10 | 2026-09-15 |
| Day | Matrix rows reviewed | Players recorded |
|---|---|---|
| 2026-09-15 | 32 | 5 |
| 2026-09-16 | 32 | 5 |
| 2026-09-17 | 32 | 5 |
| 2026-09-18 | 32 | 5 |
| 2026-09-19 | 32 | 5 |
| 2026-09-20 | 32 | 5 |
| 2026-09-21 | 32 | 5 |
| 2026-09-22 | 32 | 5 |
| 2026-09-23 | 32 | 5 |
| 2026-10-08 | 32 | 5 |
players 5|matrix rows 32|feature mass 102|centrality mean 811|distinctiveness mean 199|axes 5|spine days 10 (shown 10)|rows written today 0|readability defects 2D 0 cube 0|spine knowledge/status/cdmap/llm.spine
Capability matrix — measured against source
◉ authored stronger claim; source present● present◐ partial○ absent? unassessed; excluded from relative comparison · click any capability for its evidence
Peer cell coverage: authored assessed 128, unassessed 0. Authored assessments are not verified outcomes.
No capabilities match this filter or search.
| Capability | Nishi | llama.cpp | vLLM | Ollama | TensorRT-LLM |
|---|---|---|---|---|---|
Transformer forward passMeasured:qmul exists in runtime/nx_nofloat_llm.nx, verified at emit. Integer no-float forward; the core every engine has rival marks uncited — the Yes, Best or Part codes on this row are an observation read with no reference mark behind them Adoption: LIB-WIRED importers=34 nonval=8 — fully adopted (top of its ladder).Pros Implementing source symbol found; runtime acceptance separate; fully adopted on the estate ladderCons none on the measured axes (rival marks are documented presence, not depth) | ● | ● | ● | ● | ● |
Attention kernelsMeasured:nx_attn_score_matrix exists in runtime/nx_attention.nx, verified at emit. Score matrix + softmax attention rival marks uncited — the Yes, Best or Part codes on this row are an observation read with no reference mark behind them Adoption: LIB-WIRED importers=8 nonval=5 — fully adopted (top of its ladder).Pros Implementing source symbol found; runtime acceptance separate; fully adopted on the estate ladderCons none on the measured axes (rival marks are documented presence, not depth) | ● | ● | ● | ● | ● |
LayerNorm / normalizationMeasured:nx_layernorm_forward exists in runtime/nx_layernorm.nx, verified at emit. Forward normalization rival marks uncited — the Yes, Best or Part codes on this row are an observation read with no reference mark behind them Adoption: SOURCE-ONLY — PARTIAL: source exists, never compiled: /api/build it.Pros Implementing source symbol found; runtime acceptance separateCons not adopted yet: source exists, never compiled: /api/build it | ● | ● | ● | ● | ● |
BPE tokenizerMeasured:nx_bpe_vocab_new exists in runtime/nx_bpe.nx, verified at emit. Own byte-pair tokenizer rival marks uncited — the Yes, Best or Part codes on this row are an observation read with no reference mark behind them Adoption: SOURCE-ONLY — PARTIAL: source exists, never compiled: /api/build it.Pros Implementing source symbol found; runtime acceptance separateCons not adopted yet: source exists, never compiled: /api/build it | ● | ● | ● | ● | ● |
Open-weights GGUF loadingMeasured:nx_gguf_load_model_weights exists in runtime/nx_gguf_load_model.nx, verified at emit. Real Qwen2.5-0.5B loads; llama.cpp is the GGUF home; vLLM/TRT prefer safetensors rival marks uncited — the Yes, Best or Part codes on this row are an observation read with no reference mark behind them Adoption: LIB-WIRED importers=2 nonval=1 — fully adopted (top of its ladder).Pros Implementing source symbol found; runtime acceptance separate; ahead of vLLM, TensorRT-LLM; fully adopted on the estate ladderCons behind llama.cpp (leads) | ● | ◉ | ◐ | ● | ◐ |
Int4 quantized inferenceMeasured:nx_q4k_dot_row_col exists in runtime/nx_q4k_matmul.nx, verified at emit. Q4-K dot kernels; llama.cpp K-quants lead CPU int4 rival marks uncited — the Yes, Best or Part codes on this row are an observation read with no reference mark behind them Adoption: LIB-WIRED importers=15 nonval=9 — fully adopted (top of its ladder).Pros Implementing source symbol found; runtime acceptance separate; fully adopted on the estate ladderCons behind llama.cpp (leads) | ● | ◉ | ● | ● | ● |
SIMD-tuned CPU kernelsMeasured:i32x8_hsum exists in runtime/nx_nofloat_gemm.nx, verified at emit. AVX2 integer GEMM (7x pooled); llama.cpp hand-tuned CPU leads; TRT is GPU-only rival marks uncited — the Yes, Best or Part codes on this row are an observation read with no reference mark behind them Adoption: LIB-GATE-ONLY importers=3 — PARTIAL: imported only by validation organs (gates, tests, benches): wire it into a shipping program.Pros Implementing source symbol found; runtime acceptance separate; ahead of vLLM, TensorRT-LLMCons behind llama.cpp (leads); not adopted yet: imported only by validation organs (gates, tests, benches): wire it into a shipping program | ● | ◉ | ◐ | ● | ○ |
Served chat API (OpenAI-shaped)Measured:ls_extract_prompt exists in runtime/nx_f32_llm_serve.nx, verified at emit. Sovereign seat on :11434 serving real Qwen (loopback seam); vLLM leads production serving rival marks uncited — the Yes, Best or Part codes on this row are an observation read with no reference mark behind them Adoption: RUN-BY:daemon — fully adopted (top of its ladder).Pros Implementing source symbol found; runtime acceptance separate; fully adopted on the estate ladderCons behind vLLM (leads) | ● | ● | ◉ | ● | ● |
Training / autodiff substrateMeasured:ta_new exists in runtime/nx_autograd_tensor.nx, verified at emit. Tensor reverse-mode autograd; peers are inference-only (llama.cpp partial LoRA) rival marks uncited — the Yes, Best or Part codes on this row are an observation read with no reference mark behind them Adoption: SOURCE-ONLY — PARTIAL: source exists, never compiled: /api/build it.Pros Implementing source symbol found; runtime acceptance separate; ahead of llama.cpp, vLLM, Ollama, TensorRT-LLMCons not adopted yet: source exists, never compiled: /api/build it | ● | ◐ | ○ | ○ | ○ |
KV-cache / paged attentionDARK —runtime/nx_kvcache.nx EXISTS but does not declare kv_paged_attn: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. vLLM invented PagedAttention; Nishi re-computes rival marks uncited — the Yes, Best or Part codes on this row are an observation read with no reference mark behind themPros none measured yetCons behind llama.cpp, vLLM (leads), Ollama, TensorRT-LLM; open contract; expected source declaration not established | ○ | ● | ◉ | ● | ● |
Continuous batching throughputOpen — watchingruntime/nx_batch_serve.nx : bs_continuous_batch, re-measured on every compare beat. Ship that symbol and this mark flips itself; the comparewatch- plane row flips with it. vLLM continuous batching leads; Nishi single-stream rival marks uncited — the Yes, Best or Part codes on this row are an observation read with no reference mark behind themPros none measured yetCons behind llama.cpp, vLLM (leads), Ollama, TensorRT-LLM; open contract; expected source declaration not established | ○ | ◐ | ◉ | ◐ | ● |
Speculative decodingDARK —runtime/nx_specdec.nx EXISTS but does not declare sd_draft_verify: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. Draft-model acceleration; Nishi none rival marks uncited — the Yes, Best or Part codes on this row are an observation read with no reference mark behind themPros none measured yetCons behind llama.cpp, vLLM, Ollama, TensorRT-LLM; open contract; expected source declaration not established | ○ | ● | ● | ◐ | ● |
Mixture-of-expertsDARK —runtime/nx_moe.nx EXISTS but does not declare moe_route_experts: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. Sparse expert routing; Nishi dense-only rival marks uncited — the Yes, Best or Part codes on this row are an observation read with no reference mark behind themPros none measured yetCons behind llama.cpp, vLLM, Ollama, TensorRT-LLM; open contract; expected source declaration not established | ○ | ● | ● | ● | ● |
Long-context inference (100K+)Open — watchingruntime/nx_longctx.nx : lctx_rope_scale, re-measured on every compare beat. Ship that symbol and this mark flips itself; the comparewatch- plane row flips with it. RoPE scaling / context extension; Nishi short-context rival marks uncited — the Yes, Best or Part codes on this row are an observation read with no reference mark behind themPros none measured yetCons behind llama.cpp, vLLM, Ollama, TensorRT-LLM; open contract; expected source declaration not established | ○ | ● | ● | ● | ● |
Marlin-class fused dequant GEMMMeasured:mq_fused_dequant_gemm exists in runtime/nx_nofloat_q4k.nx, verified at emit. Fused quantized-read GEMM; the named Nishi next rung (F32 re-dequant is the measured wall) rival marks uncited — the Yes, Best or Part codes on this row are an observation read with no reference mark behind them Adoption: LIB-WIRED importers=3 nonval=1 — fully adopted (top of its ladder).Pros Implementing source symbol found; runtime acceptance separate; ahead of Ollama; fully adopted on the estate ladderCons behind vLLM (leads) | ● | ● | ◉ | ◐ | ● |
GPU accelerationOpen — watchingruntime/nx_gpu_llm.nx : gpul_offload_layer, re-measured on every compare beat. Ship that symbol and this mark flips itself; the comparewatch- plane row flips with it. CUDA/Metal offload; Nishi CPU-integer by design today; TRT is NVIDIA-optimal rival marks uncited — the Yes, Best or Part codes on this row are an observation read with no reference mark behind themPros none measured yetCons behind llama.cpp, vLLM, Ollama, TensorRT-LLM (leads); open contract; expected source declaration not established | ○ | ● | ● | ● | ◉ |
Competitive CPU speed (20+ tok/s at 0.5B)Open — watchingruntime/nx_cpu_speed_bar.nx : csb_decode_bar, re-measured on every compare beat. Ship that symbol and this mark flips itself; the comparewatch- plane row flips with it. Measured honest (F-004 remeasure 2026-07-17, healthy 17-thread build): Nishi i8 DECODE ~15 tok/s bench / 23 warm vs llama.cpp cited 20-60 = ~1-4x behind on decode; PREFILL ~9 tok/s = the remaining wall. The prior 1.5 tok/s conflated prefill with decode. The contract is the BENCH organ that publishes decode and prefill tok/s on the beat against the declared bar -- the flip says the ruler exists; the bar itself is the rung's done-rule rival marks uncited — the Yes, Best or Part codes on this row are an observation read with no reference mark behind themPros none measured yetCons behind llama.cpp (leads), vLLM, Ollama; open contract; expected source declaration not established | ○ | ◉ | ◐ | ● | ○ |
Batched prefill (the prefill wall)DARK —runtime/nx_nofloat_serve_core.nx EXISTS but does not declare nsv_prefill_batch: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. Prefill runs the prompt as m looped m=1 matmuls today (~9 tok/s, FLAT across m -- the diagnostic that we are not batching); every serving stack batches prefill. ONE contract shared with /compare/coding: the symbol lives in the serve core and both cells flip together when it lands rival marks uncited — the Yes, Best or Part codes on this row are an observation read with no reference mark behind themPros none measured yetCons behind llama.cpp (leads), vLLM (leads), Ollama (leads), TensorRT-LLM; open contract; expected source declaration not established | ○ | ◉ | ◉ | ◉ | ● |
Sovereign -- own language, compiler, kernels; zero PyTorch / CUDA / BLAS beneathSource present; authored stronger claim:qmul in runtime/nx_nofloat_llm.nx, verified at emit. Whole stack bits-up ours; llama.cpp lean C++ but still foreign toolchain/runtime rival marks uncited — the Yes, Best or Part codes on this row are an observation read with no reference mark behind them Adoption: LIB-WIRED importers=34 nonval=8 — fully adopted (top of its ladder).Pros Source symbol found; stronger capability claim is authored; ahead of llama.cpp, vLLM, Ollama, TensorRT-LLM; fully adopted on the estate ladderCons none on the measured axes (rival marks are documented presence, not depth) | ◉ | ◐ | ○ | ○ | ○ |
Integer-deterministic bit-exact inference by constructionSource present; authored stronger claim:nx_q4k_dot_row_col in runtime/nx_q4k_matmul.nx, verified at emit. No-float integer path reproduces bit-identically; GPU stacks are nondeterministic rival marks uncited — the Yes, Best or Part codes on this row are an observation read with no reference mark behind them Adoption: LIB-WIRED importers=15 nonval=9 — fully adopted (top of its ladder).Pros Source symbol found; stronger capability claim is authored; ahead of llama.cpp, vLLM, Ollama, TensorRT-LLM; fully adopted on the estate ladderCons none on the measured axes (rival marks are documented presence, not depth) | ◉ | ◐ | ○ | ○ | ○ |
MXFP4 with overflow-aware block scalingDARK —runtime/nx_nofloat_autograd.nx EXISTS but does not declare nf_mxfp4_oas: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. WATCH nf_mxfp4_oas. Two software-only scaling fixes close MXFP4's roughly 10 percent accuracy gap to NVFP4 to under 1 percent [mxfp4oas26]: an integer max-exponent scan that picks the power-of-two block exponent maximising range without overflow, and a second higher-precision scale over N blocks. Done when both routines exist over the existing MXFP4 quantizer and a planted block that overflows under naive scaling is reconstructed within a declared bound. llama.cpp and Ollama carry MXFP4 (Part); vLLM and TensorRT-LLM ship it with the fixes (Best).Pros none measured yetCons behind llama.cpp, vLLM (leads), Ollama, TensorRT-LLM (leads); open contract; expected source declaration not established | ○ | ◐ | ◉ | ◐ | ◉ |
Block-diagonal Hadamard at the MX block sizeDARK —runtime/nx_nofloat_autograd.nx EXISTS but does not declare nf_block_hadamard: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. WATCH nf_block_hadamard. Full-dimension rotation is fundamentally incompatible with MXFP4 and block rotation at exactly the MX block size is the fix [blockrot25]; the same block-diagonal Hadamard is the rotate half of the best real-serving KV quantizer, token-wise INT4 [sawint4]. A 32-point Hadamard is shifts and adds with no multiplier. Done when the rotation is block-diagonal at 32, applied in one fused pass with the quantizer, and a full-dimension rotation on the same tensor measurably degrades a planted MX block.Pros none measured yetCons behind vLLM, TensorRT-LLM; open contract; expected source declaration not established | ○ | ○ | ◐ | ○ | ◐ |
Stochastic rounding and a random Hadamard transform for 4-bit trainingDARK —runtime/nx_nofloat_autograd.nx EXISTS but does not declare nf_stoch_round: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. WATCH nf_stoch_round. 4-bit PRETRAINING is validated at 12B parameters over 10 trillion tokens [nvfp4pretrain25] on two primitives that are both integer-friendly: unbiased rounding via a PRNG bit in the gradient quantizer, and a per-block random Hadamard before quantization. Done when both exist in the nofloat optimizer path and the stochastic rounder's expectation is proven unbiased by a counted trial rather than asserted.Pros none measured yetCons behind TensorRT-LLM; open contract; expected source declaration not established | ○ | ○ | ○ | ○ | ● |
MXFP4 pack and unpack matching the shipped uint8 layoutDARK —runtime/nx_nofloat_autograd.nx EXISTS but does not declare nf_mxfp4_pack: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. WATCH nf_mxfp4_pack. Attention and KV-cache quantization at arbitrary precision shipped in llm-compressor 0.9.0 with MXFP4 support [llmcompressor090]. Done when a pack and unpack pair matches the uint8 weights-and-scales layout so an estate-built quantizer emits artifacts other runtimes load, with the free oracle: pack then unpack must be the identity, proven on a planted tensor.Pros none measured yetCons behind llama.cpp, vLLM (leads), Ollama, TensorRT-LLM (leads); open contract; expected source declaration not established | ○ | ◐ | ◉ | ◐ | ◉ |
Integer softmax and LayerNorm with guaranteed normalizationDARK —runtime/nx_nofloat_autograd.nx EXISTS but does not declare nf_softmax_exact: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. WATCH nf_softmax_exact. THE HIGHEST VALUE-PER-LINE ITEM IN THE SWEEP. Integer softmax and LayerNorm whose normalization is GUARANTEED -- the softmax accumulator provably sums to the scale factor, the LayerNorm output variance provably equals one via integer inverse square root [intsoftmax26]; a fully integer attention pipeline needs no exponential at all, using a 32-entry LUT surrogate and integer reciprocal normalization [intattention25]; and a per-head clipped-linear surrogate makes the calibration table DATA in a conf row rather than a constant in code [hccs26]. Done when both kernels exist and their invariants ARE the teeth: the sum-to-scale and unit-variance checks are asserted by arithmetic on the emitted values, not by comparison to a float twin. Exceed claimed: no rival runtime carries a normalization-guaranteed integer softmax, because none of them is float-free.Pros none measured yetCons open contract; expected source declaration not established | ○ | ○ | ○ | ○ | ○ |
A ternary embedding model, not a ternary chat modelDARK —runtime/nx_nofloat_autograd.nx EXISTS but does not declare nf_ternary_embed: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. WATCH nf_ternary_embed. Ternary and 1.58-bit did NOT scale to a frontier generative model in 2026; the live activity is CPU kernels [bitnet]. The estate-shaped extraction is a ternary EMBEDDING model, where weights in minus one, zero, plus one make the matvec a sign-and-accumulate with no multiplier and the quality bar is retrieval nDCG against a corpus the estate already indexes. Done when the sign-and-accumulate kernel exists and a ternary embedding scores within a declared bound of the estate's incumbent on its own judged set. Generative ternary is a do-not-build finding.Pros none measured yetCons behind llama.cpp, Ollama; open contract; expected source declaration not established | ○ | ◐ | ○ | ◐ | ○ |
KV consolidation then sparse selectionDARK —runtime/nx_nofloat_autograd.nx EXISTS but does not declare nf_kv_consolidate: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. WATCH nf_kv_consolidate. A million-token context at 27 percent of predecessor FLOPs and 10 percent of its KV cache comes from consolidating every m KV entries into one merged entry and then applying sparse top-k selection over the merged entries, with a second high-compression dense path [deepseekv4]. Done when the consolidate-then-select path exists over the nofloat KV cache and a planted needle survives consolidation at a declared m, with the recall reported per m.Pros none measured yetCons behind vLLM, TensorRT-LLM; open contract; expected source declaration not established | ○ | ○ | ◐ | ○ | ◐ |
End-to-end KV harness and the adoption gate it impliesDARK —runtime/_hdl_build/nx_nofloat_serve.nx EXISTS but does not declare ns_kv_e2e_bench: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. WATCH ns_kv_e2e_bench. Compression ratio is a POOR predictor of end-to-end KV performance -- four leading methods rank differently by task quality, throughput and time-to-first-token, and declared compression differs from realized [kvbench26]; and a KV method with an ICLR 2026 paper and circulated numbers is still NOT shipped in SGLang [turboquant-sglang]. Done when the harness reports task quality, output throughput, TTFT and REALIZED compression bucketed by context length, printing the declared-versus-realized gap as a partition that must reconcile, and a gate refuses to adopt any KV method until that harness is green on the target serving path. Exceed claimed: the adoption GATE, which no rival ships as a mechanism.Pros none measured yetCons open contract; expected source declaration not established | ○ | ○ | ○ | ○ | ○ |
Hybrid interleave ratio as dataDARK —runtime/_hdl_build/nx_nofloat_linattn.nx EXISTS but does not declare la_interleave_conf: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. WATCH la_interleave_conf. Hybrid linear attention SHIPPED at frontier scale, three Gated DeltaNet layers per one full-attention layer [qwen35-397b], and a second independent vendor shipped a hybrid Mamba-Transformer MoE at 1M context trained in NVFP4 [hybridmoe25]. The estate-shaped extraction is the layer-stack descriptor: which layer indices are linear and which are full attention, read from conf so the ratio is DATA that can be swept and measured rather than hardcoded and assumed. Done when the descriptor exists, a sweep over ratios runs, and a planted all-linear stack is refused by its own recall gate.Pros none measured yetCons behind llama.cpp, vLLM, Ollama, TensorRT-LLM; open contract; expected source declaration not established | ○ | ◐ | ◐ | ◐ | ◐ |
NIAH regression gate around every fine-tuneDARK —runtime/_hdl_build/nx_nofloat_linattn.nx EXISTS but does not declare la_niah_gate: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. WATCH la_niah_gate. Chain-of-thought fine-tuning DESTROYS long-range recall in hybrid linear-attention models, and QK-Restore -- copying two tensors between checkpoints, no training -- recovers it [cotrecall26]; a pretrained Transformer converts to hybrid for 2.3B tokens by ranking layers on replacement cost with no new architecture [convert-hybrid26]. Done when needle-in-a-haystack runs BEFORE and AFTER every fine-tune of a hybrid model at its ADVERTISED context length, the delta is the verdict, and a planted CoT fine-tune is caught by it.Pros none measured yetCons open contract; expected source declaration not established | ○ | ○ | ○ | ○ | ○ |
Batch-invariant reductions, a margin monitor and a determinism flagDARK —runtime/_hdl_build/nx_nofloat_serve.nx EXISTS but does not declare ns_batch_invariant: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. WATCH ns_batch_invariant. Bit-reproducible inference is solved in principle -- the cause is batch-size-dependent reduction order, and the fix is a PROHIBITION: no tiling or split decision may read a batch-dependent quantity [tm-determinism]; token flips under nondeterminism are sparse at 0.3 to 1.3 percent, so a margin monitor that re-runs only low-margin steps under a pinned reduction order beats always-on determinism [tokenflips26]; and a per-request determinism flag honored by the scheduler decouples reproducibility from kernel choice [llm42]. Done when the prohibition is a gate over the kernels, the monitor publishes its TRIGGER RATE, and the flag routes a request to the pinned path -- proven by two runs at different batch sizes producing identical tokens. Exceed claimed narrowly: an integer-only stack has no float reassociation to defeat, so the prohibition is the whole fix.Pros none measured yetCons behind vLLM, TensorRT-LLM; open contract; expected source declaration not established | ○ | ○ | ◐ | ○ | ◐ |
Small-model receipt: token cost beside the score and a discriminative controlDARK —runtime/_hdl_build/nx_nofloat_serve.nx EXISTS but does not declare ns_smallmodel_receipt: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. WATCH ns_smallmodel_receipt. Sub-1B in 2026 means natively multimodal, 262K context, hybrid attention and tool calling [qwen35-08b]; a third-party ruler confirms real but modest gains, Intelligence Index 6.5 to 9 [aa-smallmodels]; and a task-adapted sub-billion model beats zero-shot frontier LLMs -- but a plain RoBERTa-class encoder beats them too, so the finding is about task adaptation [smallvsfrontier26]. Done when every small-model score the estate publishes carries its OUTPUT-TOKEN COST beside it and the accept rule names a discriminative baseline as a required control before any small-beats-frontier claim.Pros none measured yetCons open contract; expected source declaration not established | ○ | ○ | ○ | ○ | ○ |
| Class | Count | Note |
|---|---|---|
| rows with rival marks | 28 | rows carrying a Yes, Best or Part in a rival column |
| cited | 8 | a reference mark resolves to a pinned mirror |
| uncited | 20 | an observation read, badged until a reference lands |
| rows, summed | 28 | RECONCILED: the parts sum to the total 28 |
Delivery and evidence
Inspect risks, technical debt, rendered observations, experiments and references. Read scope and limitations alongside every result.
Release history and work log
| When | Rung | Kind | Entry |
|---|---|---|---|
| 2026-09-02 | LM4 | land | mq_fused_dequant_gemm SHIPPED in runtime/nx_nofloat_q4k.nx (laptop and NAS source): Q4_K weights stay in the file map and are dotted by the fused SIMD kernel nx_q4k_dot_simd_lib; bit-identical to the scalar Q4_K dot (bench organ bit_exact=1) at 2.09x its speed; nx_nofloat_q4k_gate 17 of 17 GREEN; the watch row now points at the file that shipped |
| 2026-09-02 | LM4 | measure | Qwen2.5-Coder-7B Q4_K_M serves on the 16 GB laptop through the q4k route at 8.32 GB RSS and 1690 to 1868 ms per token (two identical greedy runs); 1.5B 428 to 506 ms per token at 2.27 GB versus 254 ms per token at 10.4 GB on the i16 cache route, text identical; the residual is the per-row nibble unpack in scalar code, so the next lever is a SIMD unpack intrinsic in nx_cc, not more cache |
| 2026-09-02 | LM4 | measure | with the nx_cc intrinsic __q4k_unpack32s (lang LN28) in the fused dot: 7B Q4_K_M 819 ms per token warm (1283 cold, first touch of the 3.1 GB file map), 1.5B 413 ms warm, greedy text unchanged across all four kernel cuts; the fused dot is bit-exact against the scalar Q4_K dot and 3.94x faster than the scalar-unpack SIMD dot on the 14-super-block row; the serve gained less than the kernel, so the remainder is being attributed with per-route ns accumulators on /health before the next cut |
Risk register
| Risk | Likelihood x impact | Mitigation |
|---|---|---|
| A throughput claim taken on a loaded box is noise with a decimal point | certain x medium | LM2 records load and thread count with every number and the gate abstains above a declared load. |
| Any kernel change that drifts a single bit destroys the determinism exceed | possible x high | Every LM rung's done-rule is bit-identity against the incumbent path before speed is even read. |
Release history continued
| When | Rung | Kind | Entry |
|---|---|---|---|
| 2026-09-04 | M4 | land | SEPTEMBER 2026 SOTA ADMITTED FOR INTEGER-ONLY INFERENCE AS COMPARE DATA: 22 pinned refs, 12 measurement rows, 6 pre-declared contracts. The sweep's LLM domain returned 26 findings and its adversarial verifier -- instructed to REFUTE -- confirmed 22 against primary sources, dropping 1 ALREADY-COMMON, 2 UNDATED and 1 REFUTED; the dropped four are named in the sweep record. Every confirmed source was fetched through the sovereign lane: 21 at status=200 on the first pass and ONE definitive 403 -- a vendor article behind a bot wall -- for which the finding was re-grounded on its primary, the llm-compressor 0.9.0 release page, at status=200 with the fetcher's own provenance sha, because a ref without a witnessed mirror is a fabrication here whatever the verifier said. Organ paths were RESOLVED, not guessed: three of the four nofloat gates whose subjects I needed import nx_nofloat_autograd.nx, located by nx_absent at runtime/nx_nofloat_autograd.nx with coverage_complete=1, and the linear-attention and serving organs at their _hdl_build paths -- a mispointed contract can never flip, so the path is part of the row. THE FINDINGS THAT CHANGE THE LANE, each pinned: integer softmax and LayerNorm whose normalization is GUARANTEED by arithmetic rather than compared to a float twin [intsoftmax26], with a fully integer attention pipeline needing no exponential at all [intattention25] and a per-head clipped-linear surrogate whose table is conf data [hccs26] -- rated the highest value-per-line item in the sweep and the only row on this section claiming an exceed on the kernel itself, because no rival runtime is float-free; MXFP4 closing its accuracy gap to under 1 percent with two software-only integer scaling fixes [mxfp4oas26], block-diagonal Hadamard at the MX block size as both the rotation fix [blockrot25] and the rotate half of the best real-serving KV quantizer [sawint4]; compression ratio a POOR predictor of end-to-end KV performance [kvbench26] and a KV method with an ICLR paper still unshipped in SGLang [turboquant-sglang], which together make the adoption GATE the deliverable rather than any method; hybrid linear attention shipped at frontier scale three-to-one [qwen35-397b] and independently by a second vendor [hybridmoe25], with chain-of-thought fine-tuning DESTROYING long-range recall in exactly that architecture [cotrecall26] -- so the interleave ratio is admitted as conf DATA under a NIAH gate, never a constant; bit-reproducible inference solved as a PROHIBITION on batch-dependent reductions [tm-determinism], made cheap by sparse token flips [tokenflips26] and a scheduler flag [llm42] -- and an integer-only stack has no float reassociation to defeat, so the prohibition is the whole fix; and ternary did NOT scale to a frontier generative model [bitnet], so the estate-shaped extraction is a ternary EMBEDDING scored by retrieval, with generative ternary named as do-not-build. Six contracts LM10 to LM15 under milestone M4 with ver 3.0, done-rules pre-declared with controls: the softmax sum-to-scale tooth must fail on a planted off-by-one, pack-then-unpack must be the identity, a full-dimension rotation must measurably degrade a planted MX block, batch 1 and batch 8 must emit identical token ids while a batch-dependent split is refused, an all-linear stack must be refused by the NIAH gate, and a small-model score without its output-token cost must be refused. All three appends verified single by row-unique counts on the NAS. |
| 2026-09-16 | LM16 | queue | FOREIGN ASSETS ON THIS BOARD, PRICED (operator 2026-09-16: open weights now as licensed data assets, ours over time, with the lift to replace each shown on /compare): llm.assets lists the Qwen2.5-Coder-7B Q4_K_M and the Qwen2.5-0.5B GGUFs as runpath weights (apache-2.0) replaced by LM16 at 12 / 20 / 40 u (components named on the rows), rendered by the compare base through nx_assets_lib and priced through nx_costest_lib; the hours conversion comes from knowledge/status/costcal.ledger, the calibration nx_costcal derives from every board's own journal rows |
SOTA field — 12 peers, 42 axes, measured bindings
12 engines, 42 axes, 7 categories. Competitor cells sourced from each project's own docs (researcher-banked 2026-07-09); Nishi cells measured by our gates. Frontier ladder: /compare/llm/frontier
| Class | Count | Note |
|---|---|---|
| consistent | 0 | the grade and the symbol agree |
| stale-under | 1 | the grade says No while the organ carries the symbol; published with the badge, named by the gate until raised |
| unbacked | 0 | a claim over an absent symbol refuses to publish |
| unresolved | 0 | |
| unreadable | 0 | |
| unserved | 6 | the organ carries the symbol in source while its binary is not on the serving surface: built nowhere, invisible to symbol presence; published with the badge, never refused |
| partition sum | 7 | RECONCILED: the parts sum to the total 7 |
Speed and scale (quantitative)
Nishi REMEASURED 2026-07-17 (F-004, Qwen2.5-0.5B i8, 16T healthy 17-thread build): decode ~15 tok/s bench / 23 warm -- the prior 2.40 was PREFILL mislabeled as decode; vs cited llama.cpp 20-60 = ~1-4x behind on decode (prefill ~9 tok/s remains the wall)
vLLM n/a GPU-firstSGLang n/a GPU-firstTensorRT-LLM n/a GPU-onlyllama.cpp ~20-60LMDeploy n/a GPU-firstTGI n/a CPU subparMLC-LLM ~10-30Ollama ~20-60ExLlamaV2 n/a GPU-onlyCTranslate2 ~10-40 int8DeepSpeed-MII n/a GPU-firstAphrodite n/a GPU-first
from each project README/model table (LMDeploy lists Intern-S1-Pro 1TB); Nishi = Qwen2.5-0.5B end-to-end proven
vLLM 670B+ DeepSeek-V3SGLang 670B+ (96xH100 EP)TensorRT-LLM 670B+ Blackwellllama.cpp 670B GGUFLMDeploy 1TB Intern-S1-ProTGI 180B FalconMLC-LLM 70B-classOllama 670B libraryExLlamaV2 120B-class multi-GPUCTranslate2 20B-class enc-decDeepSpeed-MII 530B MT-NLGAphrodite 670B+ vLLM-parity
counts from each README quant list; Nishi = Q4_K/Q5_0/Q6_K/Q8_0 read + in-memory Q8_0 repack (measured arc) [gptq2022] [awq2023]
vLLM 10+ (FP8 MXFP4 NVFP4 INT8/4 GPTQ AWQ GGUF...)SGLang 5+ (FP4 FP8 INT4 AWQ GPTQ)TensorRT-LLM 6+ (FP8 FP4 INT4 AWQ)llama.cpp 25+ (1.5- to 8-bit GGUF)LMDeploy 6+ (AWQ GPTQ W4A16 MXFP4 KV int8/4)TGI 7 (bnb GPTQ EETQ AWQ Marlin fp8 NF4)MLC-LLM 3-4 group-quantOllama GGUF setExLlamaV2 EXL2 2-8 bpwCTranslate2 3 (INT8 INT16 AWQ)DeepSpeed-MII 2-3Aphrodite 10+ vLLM-derived
vLLM README claims 200+ [vllm-docs]; LMDeploy README model table; Nishi loads Qwen2-class GGUF plus its own trained nofloat transformer
vLLM 200+SGLang wide (LLM embed reward diffusion)TensorRT-LLM 50+llama.cpp 150+ GGUFLMDeploy 60+ LLM + 40+ VLMTGI 20+ optimizedMLC-LLM 40+Ollama 100s libraryExLlamaV2 Llama-family+CTranslate2 20+ (enc-dec incl Whisper)DeepSpeed-MII 20+Aphrodite vLLM-parity
backend lists from each README; llama.cpp is the portability king of the natives, MLC of browser/mobile
vLLM 10+ (NV AMD x86 ARM PPC TPU Gaudi Ascend Apple...)SGLang 6+ (NV AMD Xeon TPU Ascend)TensorRT-LLM 1 vendor (NVIDIA all gens)llama.cpp 10+ (CPU CUDA Metal Vulkan HIP SYCL MUSA CANN OpenCL RPC)LMDeploy 3 (NV V100+ Ascend Jetson)TGI 6 (NV AMD Inferentia Intel Gaudi TPU)MLC-LLM 8+ (CUDA ROCm Vulkan Metal WebGPU iOS Android)Ollama 4 (Mac Win Linux; NV AMD)ExLlamaV2 2 (NVIDIA ROCm)CTranslate2 2 (x86 CPU NVIDIA)DeepSpeed-MII 1-2 (NVIDIA)Aphrodite 4+ (NV AMD CPU Win)
self-reported README claims (SGLang: 400k GPUs; TGI: CAUTION maintenance mode)
vLLM 2000+ contributors, industry standardSGLang 400k+ GPUs, trillions tok/dayTensorRT-LLM NVIDIA enterprise stackllama.cpp ubiquitous local standardLMDeploy InternLM productionTGI HF prod, now maintenance modeMLC-LLM browser+mobile nicheOllama dominant local runnerExLlamaV2 enthusiast standardCTranslate2 prod MT/Whisper stacksDeepSpeed-MII dormant since ~2024Aphrodite community serving (Kobold lineage)
KV cache and memory
vLLM invented PagedAttention (SOSP 2023) [kwon2023]; Nishi nx_kvcache BUILT + gate GREEN (paged==contiguous bit-exact, fork+COW) but not yet wired into serving; ExLlamaV2 paged via flash-attn; llama.cpp unified cache
SGLang zero-overhead scheduler + vLLM set the bar; LMDeploy persistent batch; MII Dynamic SplitFuse; CT2 dynamic offline batching; Nishi serves one request at a time (top gap)
SGLang RadixAttention (5x claim, banked blog list); TRT-LLM KV Cache Reuse; LMDeploy automatic prefix caching; llama.cpp prompt cache
Nishi WIRED + measured 2026-07-09 (one m=n forward, ~17x fewer prefill passes, TTFT collapse); LMDeploy dynamic split-and-fuse; MII SplitFuse
ExLlamaV2 Q4 cache pioneer (README); LMDeploy online int8/int4 KV (README); llama.cpp q8/q4 KV flags
Speed techniques
Marlin-class W4A16 is the SOTA bar [marlin2024]; Nishi CPU-Marlin: __f32_i8dot32 SSE intrinsic blessed, Q8_0 path 10.2x measured, Q5/Q4 unpack proven compute-bound on CPU (honest partial)
SGLang DFlash/Spec-V2 (2026-06 blog = current frontier); TGI claims ~2x; Nishi BUILT prompt-lookup + bit-identical gate, 58 pct accept, wall 0.94x = no net win yet (honest)
TRT engine compilation [trtllm] and MLC whole-model TVM compilation are the two compilation identities; vLLM CUDA graphs + torch.compile; Nishi is AOT-native by construction but has no GPU graphs
vLLM README lists FlashAttention FlashInfer TRTLLM-GEN FlashMLA Triton; LMDeploy FlashMLA; Nishi has own GQA offset-causal attention [vaswani2017], scalar+SSE, no flash-class tiling
bound to runtime/nx_attention.nx:nx_attn_score_matrix · measured PRESENT (decl) · UNSERVED — the hand grade claims the capability and the organ carries the symbol in SOURCE, but its binary is not on the serving surface: built nowhere -- this cell over-reports what RUNS and stays flagged until the organ is promoted
Parallelism and distribution
TGI NCCL TP (README); CTranslate2 tensor parallelism (README); llama.cpp row/layer split
vLLM/SGLang/TRT READMEs; llama.cpp RPC layer split
SGLang large-scale EP (96xH100 + GB200 blogs) leads; LMDeploy DeepEP/eplb (README); Nishi has no MoE (remaining census opportunity)
SGLang GB200 P/D blogs (3.8x prefill 4.8x decode); LMDeploy via DLSlime+Mooncake (README); TRT via Dynamo
llama.cpp RPC; LMDeploy proxy server multi-machine (README); MII replicas + load balancing (README)
Nishi MEASURED 7.34x q4k matmul on 8T + 16T decode (sovereign pool, no pthread); llama.cpp AVX/AMX/NUMA is the CPU king; CT2 MKL/oneDNN/Ruy
Model I/O and sampling
llama.cpp owns the format [llamacpp]; Nishi nx_gguf loader + tensor-type census (Q4_K/Q5_0/Q6_K/Q8_0/F32) measured; Ollama/Aphrodite GGUF native
bound to runtime/nx_gguf_load_model.nx:nx_gguf_load_model_weights · measured PRESENT (decl) · UNSERVED — the hand grade claims the capability and the organ carries the symbol in SOURCE, but its binary is not on the serving surface: built nowhere -- this cell over-reports what RUNS and stays flagged until the organ is promoted
Nishi sovereign BPE verified == Qwen2 digit-split behavior (nx_tok_probe); llama.cpp own tokenizer; the rest ship HF tokenizers
bound to runtime/nx_bpe.nx:nx_bpe_vocab_new · measured PRESENT (decl) · UNSERVED — the hand grade claims the capability and the organ carries the symbol in SOURCE, but its binary is not on the serving surface: built nowhere -- this cell over-reports what RUNS and stays flagged until the organ is promoted
llama.cpp deepest (min-p mirostat DRY XTC ecosystem); TGI logits warpers (README); Nishi greedy + temperature + top-k measured, no top-p/penalties yet
SGLang compressed-FSM 3x JSON decoding (banked blog list); llama.cpp GBNF grammars; vLLM xgrammar/guidance (README); Ollama JSON schema
vLLM tool calling + reasoning parsers (README); LMDeploy TOOLS CALLING (README); Ollama tool calling (README)
LMDeploy VLM table is the largest (InternVL home, README); llama.cpp multimodal; Ollama vision models
llama.cpp embedding + rerank (README); SGLang e5/gte/reward (README); Nishi sovereign SGNS embeddings power live in-corpus search but expose no embed-API endpoint
Nishi sovereign autograd + stable Q16 integer training recipe (trained real models: reader, neural image codec); SGLang = RL rollout backend for external trainers; the field is inference-only
bound to runtime/nx_autograd_tensor.nx:ta_new · measured PRESENT (decl) · UNSERVED — the hand grade claims the capability and the organ carries the symbol in SOURCE, but its binary is not on the serving surface: built nowhere -- this cell over-reports what RUNS and stays flagged until the organ is promoted
Serving and API
universal in the field (each README); Nishi serve organ is bespoke HTTP + MCP-first plane instead - an honest drop-in-adoption gap
bound to runtime/nx_f32_llm_serve.nx:ls_extract_prompt · measured PRESENT (decl) · STALE-UNDER — the hand grade says No while the organ carries the symbol: this cell under-reports and stays flagged until the grade is raised
vLLM README explicitly ships Anthropic Messages API alongside OpenAI + gRPC
TGI Rust gRPC core (README); MII gRPC (README); TRT via Triton
Nishi live sovereign MCP plane (compare/status/search tools served to agents today); absent from every banked engine README
TGI SSE (README); Ollama stream (README); Nishi serve returns full completions (gap)
TGI Prometheus + OpenTelemetry distributed tracing (README) = the production bar; Nishi has logs only
Ollama one-command install is the consumer bar (README) [ollama]; Nishi = sovereign ELF drop, zero deps, but self-hosted only
Sovereignty and determinism (Nishi lane)
Nishi: own language + compiler to x86 ELF, own HTTP/TLS, no libc/BLAS/PyTorch/CUDA; llama.cpp minimal C/C++ but on OS toolchain; the rest sit on PyTorch/CUDA/HF. EVIDENCE (MEASURED 2026-08-13, and this cell carried none until 2026-08-14): a return-42 static ELF out of this toolchain is 188 bytes with --no-crash-guard and 5,105 bytes with the default crash guard. A binary of that size cannot contain a libc -- which states the claim as a number somebody can re-measure instead of as an adjective
bound to runtime/nx_nofloat_llm.nx:qmul · measured PRESENT (decl) · UNSERVED — the hand grade claims the capability and the organ carries the symbol in SOURCE, but its binary is not on the serving surface: built nowhere -- this cell over-reports what RUNS and stays flagged until the organ is promoted
Nishi gates prove bit-identical decode (spec==plain, paged==contiguous, cross-run); batched GPU float engines are nondeterministic by construction; llama.cpp reproducible only single-config
bound to runtime/nx_q4k_matmul.nx:nx_q4k_dot_row_col · measured PRESENT (decl) · UNSERVED — the hand grade claims the capability and the organ carries the symbol in SOURCE, but its binary is not on the serving surface: built nowhere -- this cell over-reports what RUNS and stays flagged until the organ is promoted
Nishi integer-only Q16 training (grad-clip + LR-decay recipe, measured) - no engine in the field claims this
Nishi: every line from compiler to syscall is in-house readable; llama.cpp compact C++ auditable but sits on drivers/CUDA beneath. EVIDENCE (this cell carried none until 2026-08-14): the chain is nx_cc -> nxasm -> ELF with no LLVM, GCC or libc beneath, and it compiles on the NAS over the mgmt API (build-over-API GREEN 2026-07-06). The compiler SELF-HOSTS, and nx_cc_equiv_gate -- a differential build-and-stdout-equality gate plus a self-host stage -- runs 10/10 GREEN before any toolchain promotion, so auditable-in-house is backed by a gate that rebuilds the reader itself rather than by an assertion about readability
DOWNGRADED Best -> Yes 2026-08-14, and the reason was sitting in this row's own note: it already said llama.cpp and Ollama are fully local. Four rivals hold Yes on this axis, so claiming Best over them was an overclaim that the evidence-counted liar-kill correctly refused to publish. Nishi never phones home by construction and that is a real property -- it is simply not a lead here. The honest fix for an unevidenced Best is sometimes to lower the grade rather than to go looking for a citation that would justify keeping it
from banked READMEs: TGI = CAUTION maintenance mode recommending vLLM/SGLang; MII dormant; vLLM/SGLang/llama.cpp are the active frontier
Foreign assets — licence, bytes, and the lift to replace each with ours
nx_assets_lib, priced by nx_costest_lib. One u is calibrated at 0.11 / 1.44 / 25.33 hours (P10 / P50 / P90 of wall-clock per declared u over 267 landed rungs on 118 boards, from their own journals through nx_costcal; a ceiling on effort, since wall-clock includes waiting). Hours below use the P50 rate.| Key | State | Kind | Asset | Used by | Replaced by | Lift u P10 / P50 / P90 | Hours at P50 | Basis | Verdict |
|---|---|---|---|---|---|---|---|---|---|
qwen25_coder_7b_q4km | runpath | weights | Qwen2.5-Coder-7B-Instruct Q4_K_M GGUF, the nofloat serve seat's 7B model licence apache-2.0 · bytes unmeasured | runtime/nx_nofloat_serve_core.nx (LM4 measure: 819 ms per token warm on the 16 GB laptop, a 3.1 GB file map) | LM16 | 12 / 20 / 40 | 28.80 | components: the nofloat lane has trained a model without float (nx_nofloat_lm_gate) but never a 7B-class instruct model; licensed pretraining corpus 4u, the training loop at scale on the GPU door 8u (llm LM9 first), instruction data 3u, evaluation against the model card 2u; P90 carries the GPU door slipping and a second data pass the weights the estate's own seat runs; bytes unmeasured here (the file lives on the laptop; the LM4 row records a 3.1 GB map) | OK |
qwen25_0p5b | runpath | weights | Qwen2.5-0.5B GGUF, the local no-float seat's small model (the pos row names it: GGUF loading of Qwen2.5-0.5B) licence apache-2.0 · bytes unmeasured | runtime/nx_nofloat_serve_core.nx (the local seat behind nx_engine_dispatch, 96 new tokens ceiling by data) | LM16 | 12 / 20 / 40 | 28.80 | components as the 7B row; the 0.5B is the first size the estate can train end to end on the laptop, so it lands first under the same rung bytes unmeasured here | OK |
assets rows=2 runpath=2 candidate=0 oracle=0 unavailable=0 bad_state=0 (partition sums) · defects=0 norung=0 badrung=0 lift_missing=0 badlift=0 · runpath bytes=0 (unmeasured rows 2) · runpath lift u P10/P50/P90 = 28.7 / 40 / 68.2 over 2 priced rows (independent components; the correlated ceiling is 80 u) = 57.60 h at the P50 rate · candidate lift u P50 = 0 over 0 rows = 0.00 h · verdict=CLEAN
ledger: knowledge/compare/llm.assets · a rung named here is the one whose landing retires the asset; the lift is the estimate on record and the calibration converts it to hours from what the boards themselves journaled.
Person · product · place — not yet measured for this domain
knowledge/compare/llm.ppp (rows surface|nishi or c1..c4|label|url|connect naming OUR live surface and each rival's front door), run nx_ppp_probe domain llm, and this section fills itself on the next beat: the same ruler on both sides — privacy and CX (third-party hosts, tracker classes, cookies, security headers), design and longevity (design hygiene, computed WCAG contrast, render-blocking resources, unsized media, script weight, theme and motion queries), findability (landmarks, skip link, on-site search, breadcrumb, headings, internal links).The field — discovered, not chosen
Rows written by nx_field_discover from llm.seeds: the industry's own lists (Wikipedia wikitext, GitHub topics, awesome lists) read mechanically, every candidate counted across seeds. The matrix columns above are a SEAT'S pick; this band is the population they were picked from, and the stats line measures one against the other. A rival here is a lead, never a verdict — it earns a column when its capabilities are read and pinned.
| Class | Count | Note |
|---|---|---|
| seeds | 4 | |
| scanned | 4 | |
| fetched | 4 | |
| reused | 0 | |
| failed | 0 | |
| named | 4 | |
| candidates | 4 | |
| mentions | 4 | |
| capped | 0 |
| Rank | Rival | Seeds | Mentions | First seed | Kind | Link |
|---|---|---|---|---|---|---|
| 1 | llama.cpp | 1 | 1 | col0-llama | named | https://github.com/ggml-org/llama.cpp |
| 2 | vLLM | 1 | 1 | col1-vllm | named | https://docs.vllm.ai/en/latest/ |
| 3 | Ollama | 1 | 1 | col2-ollama | named | https://github.com/ollama/ollama |
| 4 | TensorRT-LLM | 1 | 1 | col3-tensorrt | named | https://github.com/NVIDIA/TensorRT-LLM |
field candidates 4|shown 4 of 4|matrix columns in the field 4 of 4|discovered rivals with no column 0|malformed rows 0 (counted, never rendered)|read-capped 0
Exclusive and shared capabilities
This board grades 30 capabilities: 18 exclusive to it and 12 shared with other boards. Shared rows on this page: 12 = home here 5 + home elsewhere 0 + ambiguous 3 + undecided 4 + refused 0 (partition 12); undecided = unmapped 0 + unproven 4 + unevidenced 0; homonyms 0; since the previous census: new 0, resolved 0. Census FRESH age_s=6172.
| Capability | Organ | Boards grading it | Home | Rule | Evidence | Standing on this board |
|---|---|---|---|---|---|---|
| qmul | nx_nofloat_llm.nx | llm*, lang, modelwright | llm | rung | plan | home here |
| nx_attn_score_matrix | nx_attention.nx | llm, modelwright | — | none | unproven | undecided |
| nx_bpe_vocab_new | nx_bpe.nx | llm, modelwright | — | none | unproven | undecided |
| nx_gguf_load_model_weights | nx_gguf_load_model.nx | llm, modelwright | — | none | unproven | undecided |
| nx_q4k_dot_row_col | nx_q4k_matmul.nx | llm*, modelwright | llm | rung | plan | home here |
| i32x8_hsum | nx_nofloat_gemm.nx | llm*, modelwright | llm | rung | plan | home here |
| ls_extract_prompt | nx_f32_llm_serve.nx | llm*, modelwright | llm | rung | plan | home here |
| ta_new | nx_autograd_tensor.nx | llm, modelwright | — | none | unproven | undecided |
| kv_paged_attn | nx_kvcache.nx | llm*, engineshift* | — | ambiguous | plan | ambiguous |
| mq_fused_dequant_gemm | nx_nofloat_q4k.nx | llm*, engineshift | llm | rung | plan | home here |
| gpul_offload_layer | nx_gpu_llm.nx | llm*, engineshift* | — | ambiguous | plan | ambiguous |
| nsv_prefill_batch | nx_nofloat_serve_core.nx | llm*, coding* | — | ambiguous | plan | ambiguous |
Gaps from the record — what the estate does that no board carries
The record census (nx_goalmap record) reads the invoked-tool population and every plan queue row and files each organ or directive that NO matrix, plan or gates row names. A row here is a callout the boards missed: adjudicate it onto a board or declare it infrastructure. Census state STALE (age 1395277 s), sources read 4 of 7 declared — a BLIND census is a FLOOR: unread sources can only add rows.
| kind | name | board | source | evidence |
|---|---|---|---|---|
| directive | nx_costest_lib | llm | plan-queue | rung=LM16 |
| directive | nx_costcal | llm | plan-queue | rung=LM16 |
rows shown 2|this board's directives 2|estate-wide un-boarded organs 452 (listed in full on /compare/ecosystem)|census rows 639|malformed 0 (counted, never rendered)
References
- [llamacpp] ggml-org. llama.cpp: LLM inference in C/C++ (project README, GitHub). Accessed August 2026. publisher · read in our library
knowledge/fetched/cmp_llm_llamacpp.html· pinh8f4ccd064eee25e9c5294a49af67e94126cf3c7c21070677fc7c0eb55eb8a1a0· accessed 2026-08-18 · vendor-docGrounds: The llama.cpp column codes: the GGUF home (Open-weights GGUF loading row, Best), K-quant CPU int4 kernels (Int4 quantized inference, Best), hand-tuned CPU/SIMD plus CUDA Metal Vulkan HIP SYCL backends (SIMD-tuned CPU kernels Best; llm.sota Hardware targets 10+ and CPU multithread scaling Best), GBNF grammars and the deepest sampling suite in llm.sota. - [vllm-docs] vLLM project. vLLM documentation: easy, fast, and cheap LLM serving for everyone -- PagedAttention, continuous batching, OpenAI-compatible server, quantization support (docs.vllm.ai, latest). Accessed August 2026. publisher · read in our library
knowledge/fetched/cmp_llm_vllm-docs.html· pinhcb6c8aac74d457992a5eebb7eb4100ccc89ea95c565955674f5121b9656d32bb· accessed 2026-08-18 · vendor-docGrounds: The vLLM column: Served chat API (OpenAI-shaped) Best, Continuous batching throughput Best, KV-cache / paged attention Best, and the llm.sota Weight-quant formats (10+), Model architectures (200+), OpenAI-compatible API and Anthropic Messages API cells -- the docs are where those counts and features are stated. - [ollama] Ollama. Get up and running with large language models (project README, GitHub). Accessed August 2026. publisher · read in our library
knowledge/fetched/cmp_llm_ollama.html· pinhe69552ff3d50c1c01461902d181ab39a4edb65b37e09fbcc74a8b2dba12e3a29· accessed 2026-08-18 · vendor-docGrounds: The Ollama column: llm.sota Turnkey local install Best (one-command install is the consumer bar), GGUF-native local runner, JSON-schema structured output and tool calling cells, and the local-runner decode class the Competitive CPU speed row is set beside. - [trtllm] NVIDIA. TensorRT-LLM: an open-source library for optimizing large language model inference on NVIDIA GPUs (project README, GitHub). Accessed August 2026. publisher · read in our library
knowledge/fetched/cmp_llm_trtllm.html· pinhad275cd77ef2d37ab454d140cef77014cbcb0364929f55326b8dda2e3e04eef7· accessed 2026-08-18 · vendor-docGrounds: The TensorRT-LLM column: GPU acceleration Best (NVIDIA-optimal), llm.sota Compiled / graph execution Best (engine compilation), KV Cache Reuse, FP8 FP4 INT4 AWQ quant formats -- and the GPU-only cells that read No or n/a on the CPU rows (SIMD-tuned CPU kernels, single-stream CPU decode). - [kwon2023] Kwon, Li, Zhuang, Sheng, Zheng, Yu, Gonzalez, Zhang, Stoica. Efficient Memory Management for Large Language Model Serving with PagedAttention. SOSP 2023. arXiv:2309.06180. publisher · read in our library
knowledge/fetched/cmp_llm_kwon2023.html· pinhde9353854db4e16af0c63f73502f7e463f03bdc4f3c98f3fcd377fe1c625ed08· accessed 2026-08-18 · published-paperGrounds: The KV-cache / paged attention row (vLLM invented PagedAttention; Nishi re-computes) and the llm.sota Paged / blocked KV cache cell: this paper defines the paged-KV bar that nx_kvcache is gated paged==contiguous bit-exact against, and the continuous-batching serving model the Continuous batching throughput row cites as vLLM-led. - [vaswani2017] Vaswani, Shazeer, Parmar, Uszkoreit, Jones, Gomez, Kaiser, Polosukhin. Attention Is All You Need. NeurIPS 2017. arXiv:1706.03762. publisher · read in our library
knowledge/fetched/cmp_llm_vaswani2017.html· pinh29e42a996471db9c019f1122825cdac0e6d64c96767d9ee5c0b8891de6204bee· accessed 2026-08-18 · published-paperGrounds: The Transformer forward pass, Attention kernels and LayerNorm / normalization rows: the scaled dot-product and multi-head attention that nx_nofloat_llm and nx_attention implement integer-exact -- the core every engine in the column set has, and the reference the no-float forward greedy-matches 4-for-4. - [gptq2022] Frantar, Ashkboos, Hoefler, Alistarh. GPTQ: Accurate Post-Training Quantization for Generative Pre-trained Transformers. ICLR 2023. arXiv:2210.17323. publisher · read in our library
knowledge/fetched/cmp_llm_gptq2022.html· pinhd840ca42e5f79a247194d888c7578ef49224097051f6dace49fdad8378defd26· accessed 2026-08-18 · published-paperGrounds: The llm.sota Weight-quant formats row: GPTQ is one of the named 4-bit post-training weight formats that vLLM, LMDeploy, TGI and Aphrodite serve -- the int4 accuracy bar our GGUF K-quant reads and in-memory Q8_0 repack are counted beside. - [awq2023] Lin, Tang, Tang, Yang, Chen, Wang, Xiao, Dang, Gan, Han. AWQ: Activation-aware Weight Quantization for LLM Compression and Acceleration. MLSys 2024. arXiv:2306.00978. publisher · read in our library
knowledge/fetched/cmp_llm_awq2023.html· pinh9498fecaa8aa13cdbbdd7b3b1098137c0efaf57efb7d2b47115233fafed8e756· accessed 2026-08-18 · published-paperGrounds: The llm.sota Weight-quant formats row: AWQ is the second named 4-bit weight format (vLLM, SGLang, TensorRT-LLM, LMDeploy, TGI) and its activation-aware scaling is the on-device int4 kernel bar the Int4 quantized inference row and our CPU int4 lane are graded against. - [marlin2024] Frantar, Castro, Chen, Hoefler, Alistarh. MARLIN: Mixed-Precision Auto-Regressive Parallel Inference on Large Language Models. arXiv:2408.11743, August 2024. publisher · read in our library
knowledge/fetched/cmp_llm_marlin2024.html· pinh96d7bedab4af9730d3cbfe35f48aa88306ae87eae712c925860563506182bb74· accessed 2026-08-18 · published-paperGrounds: The Marlin-class fused dequant GEMM row (the named Nishi next rung; F32 re-dequant is the measured wall) and the llm.sota Fused quantized-read GEMM cell: Marlin-class W4A16 is the SOTA bar, and the CPU-Marlin Q8_0 path (10.2x measured) is graded against this kernel's fused dequant-and-multiply design. - [mxfp4oas26] MXFP4 reaches near-NVFP4 accuracy with software-only scaling fixes (OAS and MBS). arXiv 2603.08713, Mar 2026. publisher · read in our library
knowledge/fetched/cmp_llm_arxiv260308713.html· pinh9b58ef66160758a8dab55711c3feccb0d95b548f21bf2321f49fe88ce3b56fca· accessed 2026-09-04 · published-paperGrounds: MXFP4 with overflow-aware block scaling - [blockrot25] Rotation-based PTQ is incompatible with MXFP4; block-diagonal rotation at the MX block size is the fix. arXiv 2511.04214, Nov 2025. publisher · read in our library
knowledge/fetched/cmp_llm_arxiv251104214.html· pinh703d7f53bd197bf401536ceebf925a409ebed9ad5574a66fbd85298db543361b· accessed 2026-09-04 · published-paperGrounds: Block-diagonal Hadamard at the MX block size - [nvfp4pretrain25] 4-bit pretraining validated at 12B parameters over 10 trillion tokens in NVFP4. arXiv 2509.25149, Sep 2025. publisher · read in our library
knowledge/fetched/cmp_llm_arxiv250925149.html· pinhbbcf3d19ecfd86b013258e90eef56c46a304ac5a17b449b91ba15a7b9c5fd267· accessed 2026-09-04 · published-paperGrounds: Stochastic rounding and a random Hadamard transform for 4-bit training - [intattention25] IntAttention: a fully integer attention pipeline, training-free, on commodity edge CPUs. arXiv 2511.21513, Nov 2025. publisher · read in our library
knowledge/fetched/cmp_llm_arxiv251121513.html· pinh79603c404a7b9f68d13823f24b33fad12e63f2017d05516e8fade8f0caa6db8e· accessed 2026-09-04 · published-paperGrounds: Integer softmax and LayerNorm with guaranteed normalization - [intsoftmax26] Integer softmax and LayerNorm with guaranteed normalization, 942 and 1199 square micrometres on Samsung 28nm. arXiv 2604.23647, Apr 2026. publisher · read in our library
knowledge/fetched/cmp_llm_arxiv260423647.html· pinh0b01d01a436f44fc88595ec5cad946ab5044d24eb1840ab5deb4acdff8240326· accessed 2026-09-04 · published-paperGrounds: Integer softmax and LayerNorm with guaranteed normalization - [hccs26] HCCS: a clipped-linear softmax surrogate calibrated per attention head for int8 MACs. arXiv 2604.02292, Apr 2026. publisher · read in our library
knowledge/fetched/cmp_llm_arxiv260402292.html· pinh628d6b7435008ab491a12a9c510b224d1ed33fbfda778afffb3e193471a3e1e6· accessed 2026-09-04 · published-paperGrounds: Integer softmax and LayerNorm with guaranteed normalization - [bitnet] microsoft/BitNet: ternary and 1.58-bit inference kernels; no frontier generative model shipped ternary in 2026. publisher · read in our library
knowledge/fetched/cmp_llm_githubbitnet.html· pinhb86af33a5c2856a14c48f11353c2f266e17246188294daf0994b1211214758bb· accessed 2026-09-04 · source-readGrounds: A ternary embedding model, not a ternary chat model - [deepseekv4] DeepSeek-V4: 1M-token context at 27 percent of predecessor inference FLOPs and 10 percent of its KV cache. arXiv 2606.19348, Jun 2026. publisher · read in our library
knowledge/fetched/cmp_llm_arxiv260619348.html· pinhfe89d8f32de038d4b0daeee279ab90d3e087bc5a1c7889aac38250dc9d9482a4· accessed 2026-09-04 · published-paperGrounds: KV consolidation then sparse selection - [sawint4] SAW-INT4: under real serving constraints the best KV quantizer is token-wise INT4 plus block-diagonal Hadamard. arXiv 2604.19157, Apr 2026. publisher · read in our library
knowledge/fetched/cmp_llm_arxiv260419157.html· pinh25cf34c68061ddc51c28933093612bb964409344c2cc8db82dd3aae94b90dd0e· accessed 2026-09-04 · published-paperGrounds: Block-diagonal Hadamard at the MX block size - [kvbench26] Compression ratio is a poor predictor of end-to-end KV performance: four leading methods rank differently by task quality, throughput and TTFT. arXiv 2607.05399, Jul 2026. publisher · read in our library
knowledge/fetched/cmp_llm_arxiv260705399.html· pinh39c01815081b79b37948383ff047c3141babef9a316d4a64aa1db788af276d84· accessed 2026-09-04 · published-paperGrounds: End-to-end KV harness and the adoption gate it implies - [turboquant-sglang] sgl-project/sglang issue 21618: TurboQuant KV quantization not shipped despite an ICLR 2026 paper and circulated numbers. publisher · read in our library
knowledge/fetched/cmp_llm_github21618.html· pinhcd9ee20645c2223959a05b1709e0c0a8e04cd4abb41eb00174feae5554bcda64· accessed 2026-09-04 · source-readGrounds: End-to-end KV harness and the adoption gate it implies - [qwen35-397b] Qwen3.5-397B-A17B model card: hybrid linear attention at frontier scale, 3 Gated DeltaNet layers per 1 full-attention layer. publisher · read in our library
knowledge/fetched/cmp_llm_huggingfaceqwen35397ba17b.html· pinh1a37ffa78817dc14f44be4b1a27fb869937149a8672fb73573e123eb167c5be5· accessed 2026-09-04 · vendor-docGrounds: Hybrid interleave ratio as data - [hybridmoe25] Hybrid Mamba-Transformer MoE at 1M context trained in NVFP4, from a second independent vendor. arXiv 2512.20856, Dec 2025. publisher · read in our library
knowledge/fetched/cmp_llm_arxiv251220856.html· pinhb1ed279ac04a747209998739ef1f32c7b7df413ca63215c118121379d41d06d6· accessed 2026-09-04 · published-paperGrounds: Hybrid interleave ratio as data - [cotrecall26] Chain-of-thought fine-tuning destroys long-range recall in hybrid linear-attention models; QK-Restore recovers it. arXiv 2606.11052, Jun 2026. publisher · read in our library
knowledge/fetched/cmp_llm_arxiv260611052.html· pinh5a687c8e2b293c38745b44c6107d49831c559601fefbc2644a9078f935878516· accessed 2026-09-04 · published-paperGrounds: NIAH regression gate around every fine-tune - [convert-hybrid26] A pretrained Transformer converts to hybrid for 2.3B tokens, under 0.01 percent of pretraining data. arXiv 2601.22156, Jan 2026. publisher · read in our library
knowledge/fetched/cmp_llm_arxiv260122156.html· pinh529ef64459db02ca11c9a0bc3e9ccf51692c9bfb2d2f659617c66bf302f5859b· accessed 2026-09-04 · published-paperGrounds: NIAH regression gate around every fine-tune - [tm-determinism] Thinking Machines: Defeating Nondeterminism in LLM Inference -- batch-size-dependent reduction order is the cause; batch-invariant kernels the fix. publisher · read in our library
knowledge/fetched/cmp_llm_thinkingmachinesdefeatingnondete.html· pinhaf199f54ef6c9cf89ad3132c35bf045492cde7c3e6b3f6c31ead32cc1944bffb· accessed 2026-09-04 · vendor-docGrounds: Batch-invariant reductions, a margin monitor and a determinism flag - [tokenflips26] Token flips under nondeterminism are sparse (0.3 to 1.3 percent), so selective verification beats always-on determinism. arXiv 2605.30218, May 2026. publisher · read in our library
knowledge/fetched/cmp_llm_arxiv260530218.html· pinh8b3d8e727db7163b7d08d827dfb81e423f1f24fab8c54ef351387bcb893416ca· accessed 2026-09-04 · published-paperGrounds: Batch-invariant reductions, a margin monitor and a determinism flag - [llm42] LLM-42: scheduling-based determinism decouples reproducibility from kernel implementation. arXiv 2601.17768, Jan 2026. publisher · read in our library
knowledge/fetched/cmp_llm_arxiv260117768.html· pinh80f8b61367a7c352369890cb0dad7983237382158135a8ad72f0cf842808330a· accessed 2026-09-04 · published-paperGrounds: Batch-invariant reductions, a margin monitor and a determinism flag - [qwen35-08b] Qwen3.5-0.8B model card: natively multimodal, 262K context, hybrid attention and tool calling under 1B parameters. publisher · read in our library
knowledge/fetched/cmp_llm_huggingfaceqwen3508b.html· pinhb3ef2fa6785c3be14f88389a70ab89b8d41de3bf99f6e698b614626d9b8940a8· accessed 2026-09-04 · vendor-docGrounds: Small-model receipt: token cost beside the score and a discriminative control - [aa-smallmodels] Artificial Analysis: Qwen3.5 small models -- Intelligence Index 6.5 to 9, a third-party ruler. publisher · read in our library
knowledge/fetched/cmp_llm_artificialanalysisqwen35smallmodel.html· pinh2828a9ad0c90a23129fb707a313deaa0f9f8dc4e5009774ddeed45f39f567d5f· accessed 2026-09-04 · vendor-docGrounds: Small-model receipt: token cost beside the score and a discriminative control - [smallvsfrontier26] A task-adapted sub-billion model beats zero-shot frontier LLMs, but a RoBERTa baseline beats them too. arXiv 2606.22606, Jun 2026. publisher · read in our library
knowledge/fetched/cmp_llm_arxiv260622606.html· pinh543993232aa68d5d1c8321a5ef66cb34e849403b68bc740577f8345afb40b02b· accessed 2026-09-04 · published-paperGrounds: Small-model receipt: token cost beside the score and a discriminative control - [llmcompressor090] vllm-project llm-compressor release 0.9.0: attention and KV-cache quantization at arbitrary precision, MXFP4 support. publisher · read in our library
knowledge/fetched/cmp_llm_llmcompressor090.html· pinh881d93838a11d78c97b250dcf36c18c97a8df3f2e7c2b1f1b0652c2b828844b4· accessed 2026-09-04 · source-readGrounds: MXFP4 pack and unpack matching the shipped uint8 layout - [gpqa23] Rein et al. GPQA: A Graduate-Level Google-Proof Q and A Benchmark (arXiv 2311.12022, submitted 2023-11-20), abstract page fetched and read 16 Sep 2026: 448 expert-written multiple-choice questions in biology, physics and chemistry; PhD experts reach 65 percent (74 discounting clear mistakes), skilled non-experts 34 percent with web access, and the strongest GPT-4 baseline 39 percent. publisher · read in our library
knowledge/fetched/cmp_llm_gpqa_abs.html· pinh89060474bd78a41ae61ce1575ecdaaff81478bddeea9a8a6da5fcc1669315afa· accessed 2026-09-16 · published-paperGrounds: Served chat API - [mmlupro24] MMLU-Pro README (TIGER-AI-Lab), fetched and read 16 Sep 2026: an enhanced MMLU with harder, reasoning-focused questions and ten answer choices that drops accuracy by 16 to 33 percent against MMLU; the leaderboard is a Hugging Face space and the newest dated README item is 2024-10-10. publisher · read in our library
knowledge/fetched/cmp_llm_mmlupro_readme.md· pinhdfbab62320e644f3682d4697e206160bbb59baafa324c59a17e4424328e3e5a5· accessed 2026-09-16 · source-readGrounds: Served chat API - [hle26] Humanity's Last Exam site (lastexam.ai), fetched 16 Sep 2026: a benchmark of expert-level academic questions to assess AI capabilities (its own citation carries the year 2026); the page renders its leaderboard client-side, so no number is read from this mirror. publisher · read in our library
knowledge/fetched/cmp_llm_hle.html· pinh857fe900033c28734e9c3ffb9ba0828d519a94fcf45aae0b21199e8870d1b766· accessed 2026-09-16 · vendor-docGrounds: Served chat API - [arcprize26] ARC Prize leaderboard page, fetched 16 Sep 2026: the ARC-AGI-1, ARC-AGI-2 and ARC-AGI-3 benchmark series with the 2024, 2025 and 2026 competitions; the scores are rendered client-side, so no number is read from this mirror. publisher · read in our library
knowledge/fetched/cmp_llm_arcprize_leaderboard.html· pinh1af05c4fcbbcb33dff6098211db029f6fd446da75028cb0438e1033c01dc75cf· accessed 2026-09-16 · mirrored-indexGrounds: Served chat API
generated by nx_swcompare_matrix (sovereign NishiLang organ) from knowledge/compare/llm.matrix · source checks show implementation presence; runtime and user-outcome evidence are reported separately · JavaScript supports page controls