Nishi Family › Compare › Evaluation and Grading (Referee)
Nishi Compare · capabilities, evidence and delivery
Evaluation and Grading (Referee)
Compare capabilities and delivery evidence. Source discovery, qualification, deployment and accepted outcomes are separate; an open contract names work still to verify.
Nishi vs OpenSSF Scorecard and openai-evals and EvalPlus and HELM
Overview
The purpose, declared position and evidence coverage of this domain. Source presence and completed acceptance are different measures.
Where we are. Measured 2026-08-19. The referee is the culture the roster answers to -- property-based oracles, liar-killed censuses, coaching that forced real corrections, abstaining safety grades, self-measurement on the public plane -- and it is narrow against the evaluation field: no scored qabench, an orphaned honesty grader, no intervals or paired tests, no standard suites, no contamination checks, no LLM or human-preference judging, no eval-over-time surface, no cost axis.
Where we need to go. Score what we already run, then add rigor (intervals, history), breadth (suites, contamination), judges (LLM and human preference under pre-declared agreement rules) and the supply-chain and cost axes -- so every claim the estate publishes carries an interval, a history and a cost.
Latest recorded release
2026-09-03 · R3
Renewal made IDEMPOTENT: nx_evclass_route now scans every existing row for the gate and renews only when the NEWEST epoch is older than the TTL (er_newest_epoch), so a re-run appends nothing. Witness: first run after the fix RENEWED=0 ALREADY=5 (before the fix every run re-appended 4 rows); shipped via nx_organ_ship sha 4c81e8b6, prove=NO-GATE-FOUND (named, UNPROVEN -- the organ has no gate of its own yet; its gate is the next referee rung)
Release entries describe recorded changes; they do not establish that every capability passed evaluation.
12 of 22 capability source symbols found|2 of them authored stronger-claims|10 open|coverage 545/1000|adoption 7 full / 5 partial
Evidence profile — what the gaps on this board actually are
Measured by nx_swcompare_evidence, read back by nx_evprofile_lib. Every figure is a count with its denominator — there is deliberately no score, no grade and no percentage anywhere in this band, because a stored scalar is a field a seat can edit and a counted partition is not.
evidence|grounded 12/12|unsupported 0|gates green 2/2|proven able to fail 2/2|never bitten 0|green at 0/0 2|open gaps 10|of them unnamed 0|of them proof withheld 0|flips ready 0
proven able to fail counts the gates that have a RECORDED RED — nx_gate_bite mutated the gate subject, rebuilt it, watched the gate go red, and that record is inside the shared TTL. never bitten is its complement over the same denominator: those gates ran and were green, and nothing has ever shown them able to detect anything, so their green is a statement about this run and not about the gate. green at 0/0 is a separate and much weaker observation — the gate printed GREEN on a zero denominator, so its own tooth counter says it examined nothing. A gate can be green, non-zero, and still never bitten; that is the common case and it is now visible instead of implied.
partition: grounded + unsupported = 12 vs present 12 · named + unnamed + withheld = 10 vs open 10 · both reconcile
liar-kill conj=GPQN · all four conjuncts held
graded document: BUILDROOT tree, 6908 bytes · gates map: PRIMARY · stamped 2d 7h ago · source ../knowledge/status/evstamp_referee.verdict
| Gap class | What it is, and the work it names |
|---|---|
| VACUOUS-GATE | A gate reported GREEN on a ZERO denominator. A gate with real teeth and a broken counter, and a gate with no teeth at all, are indistinguishable from outside; that indistinguishability is the finding, so it is reported here and never convicted. |
nx_swcompare_evidence referee itself and are not carried on the stamp, so this page names the classes and the producer names the rows. That split is stated rather than hidden: a count without a worklist is not actionable, and this band is honest about which half of that it is.Production map
Follow the dependencies, declared acceptance criteria and recorded priorities. Inspect source binding before treating a rank as executable work.
Ranking source binding: STALE_OR_INVALID_BINDING. Recorded priorities require current acceptance evidence and resource checks before execution.
Recorded ranking withheld
Retained ranking is not bound to the current plan and matrix: STALE_OR_INVALID_BINDING. Historical data remains retained. Refresh the ranking after resolving the input differences. Latest execution outcome is unverified.
Declared roadmap — contract, acceptance, executor, effort
| Rung | Closes with | Definition of done (pre-declared) | Executor | Est. |
|---|---|---|---|---|
| Score qabench (R0) | qa_score | Exact-match plus a rubric score per question on the 251-question bar; the per-question rows are printed and the aggregate is a ratchet floor; the harness that exists finally grades | Organ | 1 u |
| Wire the honesty grader (R1) | wc_honesty_gate | The coach consumes nx_honesty_grader on every rung claim; a planted overclaim is refused and a measured claim passes (bite both ways) | Organ | 0.5 u |
| Paired statistics on every bench (R2) | es_paired | Confidence intervals and a paired test over repeated bench runs (the Stabilizer-validated layout-variance bench is the precedent); a difference inside the interval is reported as NOT DISTINGUISHABLE, never as a win | Organ | 1.5 u |
| Eval history series (R3) after R2 | evh_series | Every gate and bench verdict appended with its epoch to one series and rendered as a regression dashboard on /compare/referee; a regression is a downward step on the series, visible without re-running | Organ | 1 u |
| Standardized suites (R4) after R0 | sb_run | MMLU and HumanEval-class suites run from banked datasets through the same harness the modelwright lane names (eh_run); results carry the interval from R2 | Organ | 2 u |
| Contamination detection (R5) after R4 | ct_scan | n-gram and perplexity-based overlap between training corpus and eval sets printed per suite; a planted leaked item is caught; required before any trained-model score is published | Organ | 1.5 u |
| LLM-as-judge (R6) after R2 | lj_grade | The sovereign seat grades text against a rubric; agreement with banked human labels is PRE-DECLARED; nx_dr_semjudge and nx_dr_densejudge are the lexical and dense control arms it must beat to be wired | Local model | 2 u |
| Human preference collection (R7) after R6 | hp_collect | Pairwise preference collection on the survey engine (anonymous, k-floored) feeding an arena-style rating; ties and abstentions counted, never dropped | Organ | 1.5 u |
| Repo supply-chain score (R8) | rsc_score | Scorecard-class checks over the estate's own repos and fetched sources: signed releases, pinned deps, branch protection where applicable; every check prints its evidence | Organ | 1.5 u |
| Cost and latency-aware eval (R9) after R3 | ec_meter | Every bench row carries wall time, tokens and joules where measurable; a quality score without its cost is refused at publish | Organ | 1 u |
Milestones
| Milestone | Rungs | Cumulative |
|---|---|---|
| M0 · Score what we already run | R0,R1 | 1.5 u |
| M1 · Rigor | R2,R3 | 4 u |
| M2 · Breadth | R4,R5 | 7.5 u |
| M3 · Judges | R6,R7 | 11 u |
| M4 · Supply chain and cost | R8,R9 | 13.5 u |
| Class | Count | Note |
|---|---|---|
| bars | 0 | sotabar rows on the plan |
| fresh | 0 | the bar month is the current month |
| attested | 0 | an older bar with a this-month barscan reporting no newer entry |
| stale | 0 | a this-month scan saw a newer month the bar ignores |
| unattested | 0 | nobody looked this month |
| malformed | 0 | a sotabar row missing a field |
| duplicate | 0 | bar ids an earlier row already carries |
| bars, summed | 0 | RECONCILED: the parts sum to the total 0 |
| current month | 2026-10 | the month every bar is judged against |
Inspect a rung and its prerequisites
Declared nodes 10. Rank input binding: STALE_OR_INVALID_BINDING. Dependency order is authored. Implementation, acceptance evidence, authority and resource readiness are unverified. No action is recommended or dispatched here.
Plan SHA-256 d325883e864c16e589f9fadf8cf4ae5a65c4eab93513b0ce34fffd742873929d. Target rows 0; role rows 0. Existing risks and release worklog retain their own scope; no node completion is inferred.
Runtime observation coverage: 0 of 10 rungs have current, identity-bound execution observations. Observation may report RED. Accepted completion remains unknown; source presence, qualification and deployment do not establish it.
Use Enter or Space on a rung to inspect its contract. Prerequisite links locate another rung in this list; open its summary to inspect it. Estimates are authored effort, not forecasts.
R0 — Score qabench
Prerequisites: None declared; this does not establish execution eligibility.
Contract:
qa_scoreAcceptance: Exact-match plus a rubric score per question on the 251-question bar; the per-question rows are printed and the aggregate is a ratchet floor; the harness that exists finally grades
Authored effort: 1. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.R1 — Wire the honesty grader
Prerequisites: None declared; this does not establish execution eligibility.
Contract:
wc_honesty_gateAcceptance: The coach consumes nx_honesty_grader on every rung claim; a planted overclaim is refused and a measured claim passes (bite both ways)
Authored effort: 0.5. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.R2 — Paired statistics on every bench
Prerequisites: None declared; this does not establish execution eligibility.
Contract:
es_pairedAcceptance: Confidence intervals and a paired test over repeated bench runs (the Stabilizer-validated layout-variance bench is the precedent); a difference inside the interval is reported as NOT DISTINGUISHABLE, never as a win
Authored effort: 1.5. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.R3 — Eval history series
Prerequisites: R2 (acceptance unverified)
Contract:
evh_seriesAcceptance: Every gate and bench verdict appended with its epoch to one series and rendered as a regression dashboard on /compare/referee; a regression is a downward step on the series, visible without re-running
Authored effort: 1. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.R4 — Standardized suites
Prerequisites: R0 (acceptance unverified)
Contract:
sb_runAcceptance: MMLU and HumanEval-class suites run from banked datasets through the same harness the modelwright lane names (eh_run); results carry the interval from R2
Authored effort: 2. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.R5 — Contamination detection
Prerequisites: R4 (acceptance unverified)
Contract:
ct_scanAcceptance: n-gram and perplexity-based overlap between training corpus and eval sets printed per suite; a planted leaked item is caught; required before any trained-model score is published
Authored effort: 1.5. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.R6 — LLM-as-judge
Prerequisites: R2 (acceptance unverified)
Contract:
lj_gradeAcceptance: The sovereign seat grades text against a rubric; agreement with banked human labels is PRE-DECLARED; nx_dr_semjudge and nx_dr_densejudge are the lexical and dense control arms it must beat to be wired
Authored effort: 2. Executor kind: Local model. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.R7 — Human preference collection
Prerequisites: R6 (acceptance unverified)
Contract:
hp_collectAcceptance: Pairwise preference collection on the survey engine (anonymous, k-floored) feeding an arena-style rating; ties and abstentions counted, never dropped
Authored effort: 1.5. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.R8 — Repo supply-chain score
Prerequisites: None declared; this does not establish execution eligibility.
Contract:
rsc_scoreAcceptance: Scorecard-class checks over the estate's own repos and fetched sources: signed releases, pinned deps, branch protection where applicable; every check prints its evidence
Authored effort: 1.5. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.R9 — Cost and latency-aware eval
Prerequisites: R3 (acceptance unverified)
Contract:
ec_meterAcceptance: Every bench row carries wall time, tokens and joules where measurable; a quality score without its cost is refused at publish
Authored effort: 1. Executor kind: Organ. Responsible, accountable and verifier not established. Inspect retained worklog.
Runtime observation: UNKNOWN; outcome UNKNOWN; observed epoch -1. Declared owner: . Receipt
, SHA-256. Identity-bound observation is not accepted completion. Qualification and deployment remain unverified by this projection.
Learning and practice paths
No structured learning path is declared for this plan. Existing research, roadmap and worklog remain available above.
Rung dossiers — every record that bears on a rung, in one place
nx_swcompare_evidence referee writes it beside its stamp); every gate below reads UNRECORDED until it runs.knowledge/organ_gate.conf read from this working directory (1 rows) and from the estate root (196 rows); rows in both counted once: 0; declarations read: 197. Every declaration in either copy counts, so a stub beside the publisher can never hide the root.R0 Score qabench · cell WATCHING · gate NO-GATE-DECLARED
| Contract | qa_score · executor Organ · 1 u · stands on nothing |
|---|---|
| Definition of done | Exact-match plus a rubric score per question on the 251-question bar; the per-question rows are printed and the aggregate is a ratchet floor; the harness that exists finally grades |
| Matrix cell | QA bench scoring (the named wall) · runtime/_hdl_build/nx_qabench.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_qabench; declare nx_qabench TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
R1 Wire the honesty grader · cell WATCHING · gate NO-GATE-DECLARED
| Contract | wc_honesty_gate · executor Organ · 0.5 u · stands on nothing |
|---|---|
| Definition of done | The coach consumes nx_honesty_grader on every rung claim; a planted overclaim is refused and a measured claim passes (bite both ways) |
| Matrix cell | Honesty grader wired to a consumer · runtime/_hdl_build/nx_ws_coach.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_ws_coach; declare nx_ws_coach TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
R2 Paired statistics on every bench · cell WATCHING · gate NO-GATE-DECLARED
| Contract | es_paired · executor Organ · 1.5 u · stands on nothing |
|---|---|
| Definition of done | Confidence intervals and a paired test over repeated bench runs (the Stabilizer-validated layout-variance bench is the precedent); a difference inside the interval is reported as NOT DISTINGUISHABLE, never as a win |
| Matrix cell | Statistical rigor (confidence intervals, paired tests) · runtime/nx_eval_stats.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_eval_stats; declare nx_eval_stats TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
R3 Eval history series · cell WATCHING · gate NO-GATE-DECLARED
| Contract | evh_series · executor Organ · 1 u · stands on R2 |
|---|---|
| Definition of done | Every gate and bench verdict appended with its epoch to one series and rendered as a regression dashboard on /compare/referee; a regression is a downward step on the series, visible without re-running |
| Matrix cell | Longitudinal regression dashboards · runtime/nx_eval_history.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_eval_history; declare nx_eval_history TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | 2026-09-03 measure nx_sota_status read PROVEN 0/105 with MECH-OK 71 awaiting a 2nd method class -- every second-class row in the 45 knowledge/status/evclass_<d>.conf files dated 2026-08-01..03 against the 604800 s TTL, i.e. expired; nx_evoracle_sweep re-derived 10 fresh oracle rows but nx_evclass_route counted a PRESENT expired row as ALREADY and appended nothing (ROUTED=0 ALREADY=4). Attestations expire on the stamp TTL and nothing renewed them: the referee was honest and the pipeline had no renewal leg 2026-09-03 land nx_evclass_route now RENEWS: a present row whose epoch is older than half the policy TTL (knowledge/evidence_policy.conf ttl_sec, else 604800) gets the fresh derivation APPENDED (additive-only; the loader counts freshness per row) and the outcome is named RENEWED beside ROUTED/ALREADY/UNROUTED. Shipped through nx_organ_ship (c9753fa9, no gate -- UNPROVEN named); first live run: RENEWED=4 ROUTED=4 (containers, deploy, authz, browser). Clock rows evoracle_sweep and evclass_route at 86400 s make the renewal a beat (half-life law: TTL 7 d, renewal 3.5 d, cadence 1 d). Still UNROUTED: md5, xxhash, bip39, bip39-wordlist, x509-pubkey-ed, voprf, crc32 -- real third-party evidence no <domain>.gates cites; wiring them is the next cheap PROVEN gain 2026-09-03 queue OPERATOR LEG: the renewed rows are UNSIGNED (nx_evoracle_sweep writes signer=nx_evoracle_sweep with no pub/sig ON PURPOSE -- its header refuses to mint a key to move the board, and nx_fs_write denies knowledge/attest_keys.conf), so at_verify_row refuses them and PROVEN stays 0/105 even with fresh derivations routed. The 2026-08-01 rows were signed by hand with machine key 2 (pub 72387edf..., registered) whose private half lived in /tmp and is gone. What flips the board: an operator-held key at a DURABLE path (nx_attest_ceremony keygen <priv>, paste role=machine or role=human pub into knowledge/attest_keys.conf), then the sweep signs its rows with it (or the operator runs nx_attest_ceremony sign over evclass_sovereign.conf rows). With that one act, containers, deploy, authz and browser read PROVEN on the next referee run and the daily evoracle_sweep + evclass_route beats keep them fresh; wiring the 7 UNROUTED KAT gates into their domains' .gates adds up to 7 more 2026-09-03 land The 7 UNROUTED KAT gates were adjudicated BY CLAIM, not blanket-wired (a .gates row is evidence FOR a claim the matrix makes; a KAT wired into a domain that never claims the algorithm is laundering). Grep over all 593 compare files: CRC-32 has one claimant (office.matrix row 14, the OOXML writer's own OPC/ZIP CRC) -> nx_crc32_gate appended to knowledge/compare/office.gates and routed; MD5's only hit is librarian's digest-LENGTH claim (not MD5 correctness) -> left; xxhash, BIP39 (x2), x509-ed25519, VOPRF have NO claimant anywhere -> left UNROUTED and honest. Net: one more domain carries a third-party oracle row; the operator key still gates PROVEN 2026-09-03 land Renewal made IDEMPOTENT: nx_evclass_route now scans every existing row for the gate and renews only when the NEWEST epoch is older than the TTL (er_newest_epoch), so a re-run appends nothing. Witness: first run after the fix RENEWED=0 ALREADY=5 (before the fix every run re-appended 4 rows); shipped via nx_organ_ship sha 4c81e8b6, prove=NO-GATE-FOUND (named, UNPROVEN -- the organ has no gate of its own yet; its gate is the next referee rung) |
R4 Standardized suites · cell WATCHING · gate NO-GATE-DECLARED
| Contract | sb_run · executor Organ · 2 u · stands on R0 |
|---|---|
| Definition of done | MMLU and HumanEval-class suites run from banked datasets through the same harness the modelwright lane names (eh_run); results carry the interval from R2 |
| Matrix cell | Standardized benchmark suites (MMLU HumanEval class) · runtime/nx_std_bench.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_std_bench; declare nx_std_bench TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
R5 Contamination detection · cell WATCHING · gate NO-GATE-DECLARED
| Contract | ct_scan · executor Organ · 1.5 u · stands on R4 |
|---|---|
| Definition of done | n-gram and perplexity-based overlap between training corpus and eval sets printed per suite; a planted leaked item is caught; required before any trained-model score is published |
| Matrix cell | Contamination and memorization detection · runtime/nx_contamination.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_contamination; declare nx_contamination TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
R6 LLM-as-judge · cell WATCHING · gate NO-GATE-DECLARED
| Contract | lj_grade · executor Local model · 2 u · stands on R2 |
|---|---|
| Definition of done | The sovereign seat grades text against a rubric; agreement with banked human labels is PRE-DECLARED; nx_dr_semjudge and nx_dr_densejudge are the lexical and dense control arms it must beat to be wired |
| Matrix cell | LLM-as-judge evaluation · runtime/nx_llm_judge.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_llm_judge; declare nx_llm_judge TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
R7 Human preference collection · cell WATCHING · gate NO-GATE-DECLARED
| Contract | hp_collect · executor Organ · 1.5 u · stands on R6 |
|---|---|
| Definition of done | Pairwise preference collection on the survey engine (anonymous, k-floored) feeding an arena-style rating; ties and abstentions counted, never dropped |
| Matrix cell | Human-preference evaluation · runtime/nx_human_pref.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_human_pref; declare nx_human_pref TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
R8 Repo supply-chain score · cell WATCHING · gate NO-GATE-DECLARED
| Contract | rsc_score · executor Organ · 1.5 u · stands on nothing |
|---|---|
| Definition of done | Scorecard-class checks over the estate's own repos and fetched sources: signed releases, pinned deps, branch protection where applicable; every check prints its evidence |
| Matrix cell | Supply-chain security scoring of repos · runtime/nx_repo_score.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_repo_score; declare nx_repo_score TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
R9 Cost and latency-aware eval · cell WATCHING · gate NO-GATE-DECLARED
| Contract | ec_meter · executor Organ · 1 u · stands on R3 |
|---|---|
| Definition of done | Every bench row carries wall time, tokens and joules where measurable; a quality score without its cost is refused at publish |
| Matrix cell | Cost and latency-aware evaluation · runtime/nx_eval_cost.nx · WATCHING decl |
| Gate | NO-GATE-DECLARED — knowledge/organ_gate.conf carries no row for nx_eval_cost; declare nx_eval_cost TAB <gate> and the ship loop proves it and the verdict lands here. |
| Work log | no log row names this rung yet |
dossiers=10 cells_joined=10 no_matrix_row=0 (sum 10) gates_recorded=0 gates_unrecorded=0 no_gate_declared=10 (sum 10 of cells_joined) evgates=UNSTAMPED
Capability comparisons
Compare the field, search individual capabilities and open their source and adoption evidence. Documented presence does not establish comparative quality.
Position map — centrality and distinctiveness
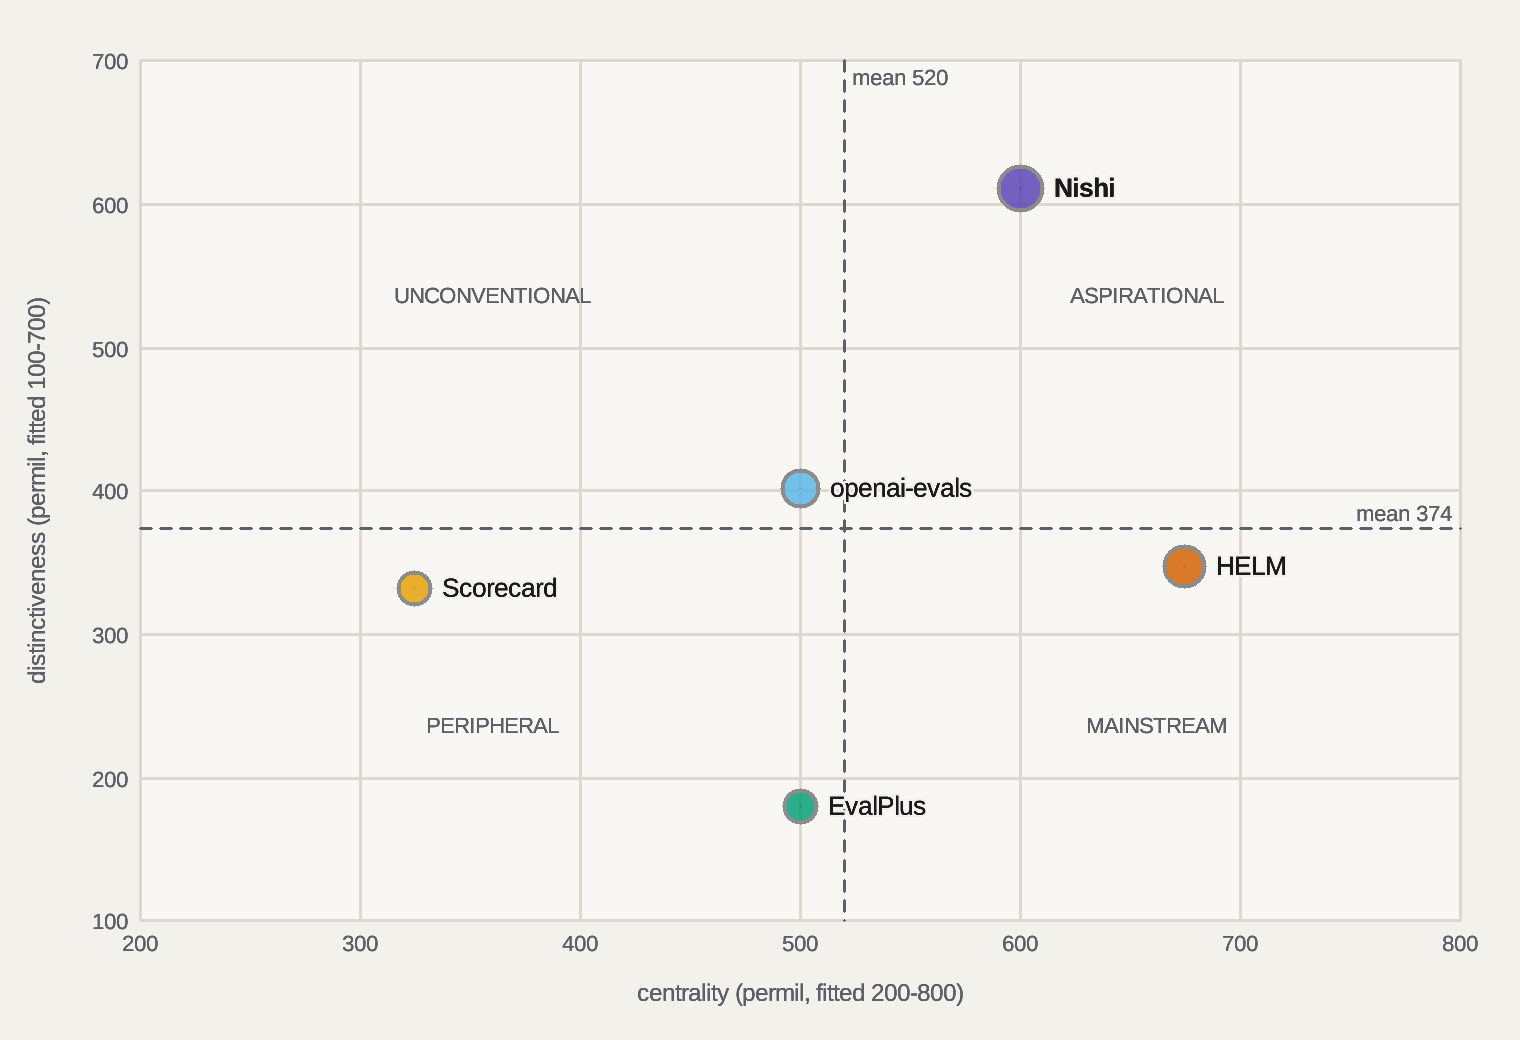
The four-quadrant map the field uses for brand strategy (Dawar and Bagga, HBR June 2015), re-derived from this matrix on every publish. Centrality is the share of the category's feature mass a player covers, each feature weighted by how many hold it; distinctiveness is the average lead over each rival on the rows the player holds; breadth is the depth-weighted share of the whole matrix (the bubble); depth is how deeply the rows held are held; momentum is the day-over-day move off the spine (green rising, red falling, grey until day two); the dashed path runs first day → previous day → today. Dividers are the category means. Axes are fitted to the field of play, so read the tick numerals, not the frame. Rival marks are documented presence, so a rival's position reads the record, never its quality. The picture grades its own readability below; the table beside it is the same data for a screen reader or a second method.
knowledge/compare/referee.cdmap (cut|x|y, cube|x|y|z); absent = the HBR defaultsbubble area = breadth · ring = momentum (green rising, red falling, grey until day two) · dashed = category means · axes fitted to the field of play: centrality 200–800, distinctiveness 100–700 of 0–1000 permil (the full range put every player in one corner)
readability of the 2D cut, self-graded by the layout ruler: label overlaps 0 · labels over marks 0 · off-canvas 0 · unresolved labels 0 · mark overlaps 0 (a fact of the data: two players that close are that close) · data spread 650 permil of the plot · quadrant words unseated 0
text contrast, measured with wcag2-ratio (floors from contrast.conf), light theme: labels 16.24 (floor 4.50) · notes 16.24 (floor 4.50) · quadrant words 5.89 (floor 4.50) · tick numerals 5.89 (floor 4.50) · axis titles 5.59 (floor 4.50) · dark theme: labels 13.78 (floor 4.50) · quadrant words 5.55 (floor 4.50) · axis titles 5.97 (floor 4.50) · dark classes under their floor 0 (one figure serves both themes: a dark shortfall is a token to fix, never a class to hide) · classes refused under their floor 0 (a refused class is not drawn; the scale classes are measured, never hidden) · export: SVG PNG (receipt, rendered by the estate's own rasteriser from this page)

readability of the 3D cube, self-graded by the layout ruler: label overlaps 0 · labels over marks 0 · off-canvas 0 · unresolved labels 0 · mark overlaps 1 (a fact of the data: two players that close are that close) · data spread 182 permil of the plot
10 panels over 5 registered axes, every pair once (the lower axis on x, the higher on y) · each panel fitted to its own field of play, first and last tick numerals shown · no labels in a small cut, the legend names the colours; the grade below reports the mark terms only (MM summed over the panels, spread averaged)
readability of the small multiples, self-graded by the layout ruler: label overlaps 0 · labels over marks 0 · off-canvas 0 · unresolved labels 0 · mark overlaps 3 (a fact of the data: two players that close are that close) · data spread 514 permil of the plot
| Player | Quadrant | centrality | distinctiveness | breadth | depth | momentum | Rows held | Days on spine | First seen |
|---|---|---|---|---|---|---|---|---|---|
| Nishi | Aspirational | 600 | 611 | 393 | 722 | 0 since 2026-09-23 | 12 | 10 | 2026-09-15 |
| Scorecard | Peripheral | 325 | 333 | 106 | 466 | 0 since 2026-09-23 | 5 | 10 | 2026-09-15 |
| openai-evals | Unconventional | 500 | 402 | 181 | 666 | 0 since 2026-09-23 | 6 | 10 | 2026-09-15 |
| EvalPlus | Peripheral | 500 | 180 | 121 | 444 | 0 since 2026-09-23 | 6 | 10 | 2026-09-15 |
| HELM | Mainstream | 675 | 348 | 257 | 515 | 0 since 2026-09-23 | 11 | 10 | 2026-09-15 |
| Day | Matrix rows reviewed | Players recorded |
|---|---|---|
| 2026-09-15 | 22 | 5 |
| 2026-09-16 | 22 | 5 |
| 2026-09-17 | 22 | 5 |
| 2026-09-18 | 22 | 5 |
| 2026-09-19 | 22 | 5 |
| 2026-09-20 | 22 | 5 |
| 2026-09-21 | 22 | 5 |
| 2026-09-22 | 22 | 5 |
| 2026-09-23 | 22 | 5 |
| 2026-10-08 | 22 | 5 |
players 5|matrix rows 22|feature mass 40|centrality mean 520|distinctiveness mean 374|axes 5|spine days 10 (shown 10)|rows written today 0|readability defects 2D 0 cube 0|spine knowledge/status/cdmap/referee.spine
Capability matrix — measured against source
◉ authored stronger claim; source present● present◐ partial○ absent? unassessed; excluded from relative comparison · click any capability for its evidence
Peer cell coverage: authored assessed 88, unassessed 0. Authored assessments are not verified outcomes.
No capabilities match this filter or search.
| Capability | Nishi | Scorecard | openai-evals | EvalPlus | HELM |
|---|---|---|---|---|---|
Property-based independent oracles (never author-supplied answers)Measured:INDEPENDENT oracle exists in runtime/nx_selfimprove_verified_gate.nx, verified at emit. Sort proven ordered AND a permutation, isqrt by bounds, pow by cross-method agreement; a deliberately BUGGY sort is CAUGHT (the verifier has teeth, gate GREEN 2026-07-06 era); EvalPlus test augmentation [evalplus23] is the partial peer [quickcheck00] Adoption: GATE:LIVE trial=GREEN — fully adopted (top of its ladder).Pros Implementing source symbol found; runtime acceptance separate; ahead of Scorecard, openai-evals, EvalPlus, HELM; fully adopted on the estate ladderCons none on the measured axes (rival marks are documented presence, not depth) | ● | ○ | ◐ | ◐ | ○ |
Liar-killed census generation (fabricated cells die)Measured:LIAR-KILL exists in runtime/nx_swcompare_matrix.nx, verified at emit. Every Nishi cell requires the implementing symbol on disk; neg-control + exceed-bounds + row-count checks fail the build -- 27 live comparisons carry it Adoption: RUN-BY:fork:nx_compare_regen — fully adopted (top of its ladder).Pros Implementing source symbol found; runtime acceptance separate; ahead of Scorecard, openai-evals, EvalPlus, HELM; fully adopted on the estate ladderCons none on the measured axes (rival marks are documented presence, not depth) | ● | ○ | ○ | ○ | ○ |
Anti-drift claim coaching (only COACH-OK claims a rung)Measured:wc_count exists in runtime/_hdl_build/nx_ws_coach.nx, verified at emit. U-axes, dated bars, claim-vs-proof ratio, freshness; it forced a real correction on the supervisor census 2026-07-10 (421 to 347 honest) Adoption: BUILT-UNPROMOTED — PARTIAL: compiled, never promoted to the serving root: /api/promote it.Pros Implementing source symbol found; runtime acceptance separate; ahead of Scorecard, openai-evals, EvalPlus, HELMCons not adopted yet: compiled, never promoted to the serving root: /api/promote it | ● | ○ | ○ | ○ | ○ |
Multi-profile industry quality gradingMeasured:nx_grade_profile_elm exists in runtime/nx_quality_grade.nx, verified at emit. Seven industry profiles (Elm, JPL, CERT...) with majority voting; Scorecard checks [scorecard-checks] and HELM multi-metrics [helm22] are partial peers Adoption: LIB-WIRED importers=5 nonval=4 — fully adopted (top of its ladder).Pros Implementing source symbol found; runtime acceptance separate; ahead of Scorecard, openai-evals, EvalPlus, HELM; fully adopted on the estate ladderCons none on the measured axes (rival marks are documented presence, not depth) | ● | ◐ | ○ | ○ | ◐ |
Safety-critical 8-axis grading that ABSTAINSMeasured:_sc_axis_bounded_loop exists in runtime/nx_safety_critical_grade.nx, verified at emit. JPL / IEC61508 / ISO26262 / DO-178C axes; abstains via UNMEASURED instead of guessing -- abstention as a grading verdict is rare in the field Adoption: LIB-GATE-ONLY importers=1 — PARTIAL: imported only by validation organs (gates, tests, benches): wire it into a shipping program.Pros Implementing source symbol found; runtime acceptance separate; ahead of Scorecard, openai-evals, EvalPlus, HELMCons not adopted yet: imported only by validation organs (gates, tests, benches): wire it into a shipping program | ● | ○ | ○ | ○ | ○ |
Honesty and overclaim grading of proseMeasured:nx_honesty_arc_report exists in runtime/nx_honesty_grader.nx, verified at emit. Grades claims vs evidence verbs; HONEST FLAG: found orphaned 2026-07-09 (zero importers) -- wiring it to a consumer is a named rung Adoption: LIB-UNIMPORTED — PARTIAL: nothing imports it: wire it into a consumer or retire it.Pros Implementing source symbol found; runtime acceptance separate; ahead of Scorecard, openai-evals, EvalPlus, HELMCons not adopted yet: nothing imports it: wire it into a consumer or retire it | ● | ○ | ○ | ○ | ○ |
QA benchmark harness with real question setsMeasured:qa_split_prose exists in runtime/_hdl_build/nx_qabench.nx, verified at emit. 251-question bar; SCORING is the named wall (2026-07-09); openai-evals registry harness is the bar [openai-evals] Adoption: SOURCE-ONLY — PARTIAL: source exists, never compiled: /api/build it.Pros Implementing source symbol found; runtime acceptance separate; ahead of ScorecardCons behind openai-evals (leads); not adopted yet: source exists, never compiled: /api/build it | ● | ○ | ◉ | ● | ● |
Census product-surface audit (U-axes enforcement)Measured:ua_find exists in runtime/_hdl_build/nx_census_uiaudit.nx, verified at emit. Flagged 83 of 160 censuses missing U-axes (2026-07-09) -- the instrument that audits the instruments Adoption: SOURCE-ONLY — PARTIAL: source exists, never compiled: /api/build it.Pros Implementing source symbol found; runtime acceptance separate; ahead of Scorecard, openai-evals, EvalPlus, HELMCons not adopted yet: source exists, never compiled: /api/build it | ● | ○ | ○ | ○ | ○ |
Live-derived ecosystem grading (anti-staleness)Measured:em_domain_level exists in runtime/_hdl_build/nx_ecomat_lib.nx, verified at emit. Grades re-derive from evidence files on every read; Scorecard per-commit re-runs [scorecard-checks] are the partial peer Adoption: LIB-WIRED importers=22 nonval=14 — fully adopted (top of its ladder).Pros Implementing source symbol found; runtime acceptance separate; ahead of Scorecard, openai-evals, EvalPlus, HELM; fully adopted on the estate ladderCons none on the measured axes (rival marks are documented presence, not depth) | ● | ◐ | ○ | ○ | ○ |
Public measured-results publicationMeasured:hub_card_json exists in runtime/nx_swcompare_hub.nx, verified at emit. The /compare hub publishes 27 liar-killed comparisons as REST+MCP; HELM public leaderboards are the bar [helm22] Adoption: RUN-BY:cron — fully adopted (top of its ladder).Pros Implementing source symbol found; runtime acceptance separate; ahead of Scorecard, openai-evals, EvalPlus; fully adopted on the estate ladderCons behind HELM (leads) | ● | ◐ | ◐ | ◐ | ◉ |
LLM-as-judge evaluationOpen — watchingruntime/nx_llm_judge.nx : lj_grade, re-measured on every compare beat. Ship that symbol and this mark flips itself; the comparewatch- plane row flips with it. openai-evals model-graded evals are the bar [openai-evals] [llmjudge23]; our reverse-AI-judge exists for IMAGES (nx_natstat, photoreal domain) but no text judgePros none measured yetCons behind openai-evals (leads), HELM; open contract; expected source declaration not established | ○ | ○ | ◉ | ○ | ◐ |
Standardized benchmark suites (MMLU HumanEval class)Open — watchingruntime/nx_std_bench.nx : sb_run, re-measured on every compare beat. Ship that symbol and this mark flips itself; the comparewatch- plane row flips with it. HELM living-benchmark breadth is the bar [helm22]; our benches are domain-organ KATsPros none measured yetCons behind openai-evals, EvalPlus, HELM (leads); open contract; expected source declaration not established | ○ | ○ | ◐ | ◐ | ◉ |
Contamination and memorization detectionOpen — watchingruntime/nx_contamination.nx : ct_scan, re-measured on every compare beat. Ship that symbol and this mark flips itself; the comparewatch- plane row flips with it. Critical for the coming TRAIN-our-own-model arc [contamination23]; EvalPlus [evalplus23] and HELM carry partial answersPros none measured yetCons behind EvalPlus, HELM; open contract; expected source declaration not established | ○ | ○ | ○ | ◐ | ◐ |
Supply-chain security scoring of reposOpen — watchingruntime/nx_repo_score.nx : rsc_score, re-measured on every compare beat. Ship that symbol and this mark flips itself; the comparewatch- plane row flips with it. Scorecard IS this [scorecard-checks]; ties to the janitor census SBOM gap (mom 1864)Pros none measured yetCons behind Scorecard (leads); open contract; expected source declaration not established | ○ | ◉ | ○ | ○ | ○ |
Statistical rigor (confidence intervals, paired tests)Open — watchingruntime/nx_eval_stats.nx : es_paired, re-measured on every compare beat. Ship that symbol and this mark flips itself; the comparewatch- plane row flips with it. The Stabilizer-validated paired bench [stabilizer13] (2026-05-20, layout variance) set the precedent but no organ generalizes itPros none measured yetCons behind HELM; open contract; expected source declaration not established | ○ | ○ | ○ | ○ | ◐ |
Human-preference evaluationOpen — watchingruntime/nx_human_pref.nx : hp_collect, re-measured on every compare beat. Ship that symbol and this mark flips itself; the comparewatch- plane row flips with it. Arena-style preference collection [chatbotarena24] absent; HELM instruction-following slices partialPros none measured yetCons behind HELM; open contract; expected source declaration not established | ○ | ○ | ○ | ○ | ◐ |
Longitudinal regression dashboardsOpen — watchingruntime/nx_eval_history.nx : evh_series, re-measured on every compare beat. Ship that symbol and this mark flips itself; the comparewatch- plane row flips with it. Ratchet floors track direction but no eval-over-time surface exists rival marks uncited — the Yes, Best or Part codes on this row are an observation read with no reference mark behind themPros none measured yetCons behind Scorecard, HELM; open contract; expected source declaration not established | ○ | ◐ | ○ | ○ | ◐ |
Cost and latency-aware evaluationOpen — watchingruntime/nx_eval_cost.nx : ec_meter, re-measured on every compare beat. Ship that symbol and this mark flips itself; the comparewatch- plane row flips with it. HELM efficiency metrics are the bar [helm22]; our zero-token loops make cost moot internally but externally-facing evals need itPros none measured yetCons behind HELM; open contract; expected source declaration not established | ○ | ○ | ○ | ○ | ◐ |
Cheat-proof grading BY CONSTRUCTIONSource present; authored stronger claim:prove_sort in runtime/nx_selfimprove_verified_gate.nx, verified at emit. Held-out scoring + property oracles [quickcheck00] + teeth-tested (the buggy-sort catch) + abstention verdicts: the grader CANNOT be gamed by the graded, in-substrate; the field's harnesses trust dataset answers and model judges Adoption: GATE:LIVE trial=GREEN — fully adopted (top of its ladder).Pros Source symbol found; stronger capability claim is authored; ahead of Scorecard, openai-evals, EvalPlus, HELM; fully adopted on the estate ladderCons none on the measured axes (rival marks are documented presence, not depth) | ◉ | ○ | ○ | ○ | ○ |
The evaluator grades ITSELF on the public planeSource present; authored stronger claim:em_rollup_store in runtime/_hdl_build/nx_ecomat_lib.nx, verified at emit. The maturity rollup grades the ecosystem INCLUDING the grading fleet, the coach gates the coach's own censuses, and this very page is liar-killed by the organ it measures -- self-measurement as culture, not feature Adoption: LIB-WIRED importers=22 nonval=14 — fully adopted (top of its ladder).Pros Source symbol found; stronger capability claim is authored; ahead of Scorecard, openai-evals, EvalPlus, HELM; fully adopted on the estate ladderCons none on the measured axes (rival marks are documented presence, not depth) | ◉ | ○ | ○ | ○ | ○ |
QA bench scoring (the named wall)DARK —runtime/_hdl_build/nx_qabench.nx EXISTS but does not declare qa_score: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. The 251-question bar has a harness and no scorer; exact-match plus a held-out graded score per question, printed per row rival marks uncited — the Yes, Best or Part codes on this row are an observation read with no reference mark behind themPros none measured yetCons behind openai-evals (leads), EvalPlus, HELM; open contract; expected source declaration not established | ○ | ○ | ◉ | ● | ● |
Honesty grader wired to a consumerDARK —runtime/_hdl_build/nx_ws_coach.nx EXISTS but does not declare wc_honesty_gate: something shipped at this path under another name, and this mark would read open forever. Repoint the contract to the real entry point (the plan rung AND this row) or rename the function; the flip follows on the next beat, and the comparewatch- plane row reads DARK until then. nx_honesty_grader is orphaned (zero importers, 2026-07-09); the coach consuming it turns overclaim grading from a file into a gatePros none measured yetCons open contract; expected source declaration not established | ○ | ○ | ○ | ○ | ○ |
| Class | Count | Note |
|---|---|---|
| rows with rival marks | 14 | rows carrying a Yes, Best or Part in a rival column |
| cited | 12 | a reference mark resolves to a pinned mirror |
| uncited | 2 | an observation read, badged until a reference lands |
| rows, summed | 14 | RECONCILED: the parts sum to the total 14 |
Delivery and evidence
Inspect risks, technical debt, rendered observations, experiments and references. Read scope and limitations alongside every result.
Release history and work log
| When | Rung | Kind | Entry |
|---|---|---|---|
| 2026-09-03 | R3 | measure | nx_sota_status read PROVEN 0/105 with MECH-OK 71 awaiting a 2nd method class -- every second-class row in the 45 knowledge/status/evclass_<d>.conf files dated 2026-08-01..03 against the 604800 s TTL, i.e. expired; nx_evoracle_sweep re-derived 10 fresh oracle rows but nx_evclass_route counted a PRESENT expired row as ALREADY and appended nothing (ROUTED=0 ALREADY=4). Attestations expire on the stamp TTL and nothing renewed them: the referee was honest and the pipeline had no renewal leg |
| 2026-09-03 | R3 | land | nx_evclass_route now RENEWS: a present row whose epoch is older than half the policy TTL (knowledge/evidence_policy.conf ttl_sec, else 604800) gets the fresh derivation APPENDED (additive-only; the loader counts freshness per row) and the outcome is named RENEWED beside ROUTED/ALREADY/UNROUTED. Shipped through nx_organ_ship (c9753fa9, no gate -- UNPROVEN named); first live run: RENEWED=4 ROUTED=4 (containers, deploy, authz, browser). Clock rows evoracle_sweep and evclass_route at 86400 s make the renewal a beat (half-life law: TTL 7 d, renewal 3.5 d, cadence 1 d). Still UNROUTED: md5, xxhash, bip39, bip39-wordlist, x509-pubkey-ed, voprf, crc32 -- real third-party evidence no <domain>.gates cites; wiring them is the next cheap PROVEN gain |
| 2026-09-03 | R3 | queue | OPERATOR LEG: the renewed rows are UNSIGNED (nx_evoracle_sweep writes signer=nx_evoracle_sweep with no pub/sig ON PURPOSE -- its header refuses to mint a key to move the board, and nx_fs_write denies knowledge/attest_keys.conf), so at_verify_row refuses them and PROVEN stays 0/105 even with fresh derivations routed. The 2026-08-01 rows were signed by hand with machine key 2 (pub 72387edf..., registered) whose private half lived in /tmp and is gone. What flips the board: an operator-held key at a DURABLE path (nx_attest_ceremony keygen <priv>, paste role=machine or role=human pub into knowledge/attest_keys.conf), then the sweep signs its rows with it (or the operator runs nx_attest_ceremony sign over evclass_sovereign.conf rows). With that one act, containers, deploy, authz and browser read PROVEN on the next referee run and the daily evoracle_sweep + evclass_route beats keep them fresh; wiring the 7 UNROUTED KAT gates into their domains' .gates adds up to 7 more |
| 2026-09-03 | R3 | land | The 7 UNROUTED KAT gates were adjudicated BY CLAIM, not blanket-wired (a .gates row is evidence FOR a claim the matrix makes; a KAT wired into a domain that never claims the algorithm is laundering). Grep over all 593 compare files: CRC-32 has one claimant (office.matrix row 14, the OOXML writer's own OPC/ZIP CRC) -> nx_crc32_gate appended to knowledge/compare/office.gates and routed; MD5's only hit is librarian's digest-LENGTH claim (not MD5 correctness) -> left; xxhash, BIP39 (x2), x509-ed25519, VOPRF have NO claimant anywhere -> left UNROUTED and honest. Net: one more domain carries a third-party oracle row; the operator key still gates PROVEN |
| 2026-09-03 | R3 | land | Renewal made IDEMPOTENT: nx_evclass_route now scans every existing row for the gate and renews only when the NEWEST epoch is older than the TTL (er_newest_epoch), so a re-run appends nothing. Witness: first run after the fix RENEWED=0 ALREADY=5 (before the fix every run re-appended 4 rows); shipped via nx_organ_ship sha 4c81e8b6, prove=NO-GATE-FOUND (named, UNPROVEN -- the organ has no gate of its own yet; its gate is the next referee rung) |
Person · product · place — not yet measured for this domain
knowledge/compare/referee.ppp (rows surface|nishi or c1..c4|label|url|connect naming OUR live surface and each rival's front door), run nx_ppp_probe domain referee, and this section fills itself on the next beat: the same ruler on both sides — privacy and CX (third-party hosts, tracker classes, cookies, security headers), design and longevity (design hygiene, computed WCAG contrast, render-blocking resources, unsized media, script weight, theme and motion queries), findability (landmarks, skip link, on-site search, breadcrumb, headings, internal links).The field — discovered, not chosen
Rows written by nx_field_discover from referee.seeds: the industry's own lists (Wikipedia wikitext, GitHub topics, awesome lists) read mechanically, every candidate counted across seeds. The matrix columns above are a SEAT'S pick; this band is the population they were picked from, and the stats line measures one against the other. A rival here is a lead, never a verdict — it earns a column when its capabilities are read and pinned.
| Class | Count | Note |
|---|---|---|
| seeds | 2 | |
| scanned | 2 | |
| fetched | 2 | |
| reused | 0 | |
| failed | 0 | |
| named | 2 | |
| candidates | 2 | |
| mentions | 2 | |
| capped | 0 |
| Rank | Rival | Seeds | Mentions | First seed | Kind | Link |
|---|---|---|---|---|---|---|
| 1 | Scorecard | 1 | 1 | col0-scorecard | named | https://github.com/ossf/scorecard/blob/main/docs/checks.md |
| 2 | openai-evals | 1 | 1 | col1-openai | named | https://github.com/openai/evals |
field candidates 2|shown 2 of 2|matrix columns in the field 2 of 4|discovered rivals with no column 0|malformed rows 0 (counted, never rendered)|read-capped 0
Exclusive and shared capabilities
This board grades 22 capabilities: 17 exclusive to it and 5 shared with other boards. Shared rows on this page: 5 = home here 0 + home elsewhere 1 + ambiguous 1 + undecided 3 + refused 0 (partition 5); undecided = unmapped 0 + unproven 3 + unevidenced 0; homonyms 1; since the previous census: new 0, resolved 0. Census FRESH age_s=6523.
| Capability | Organ | Boards grading it | Home | Rule | Evidence | Standing on this board |
|---|---|---|---|---|---|---|
| em_domain_level | nx_ecomat_lib.nx | supervisor, referee, ecosystem | — | none | unproven | undecided |
| sb_run | - | videocodec:runtime/nx_vcodec_stage_bench.nx, referee:runtime/nx_std_bench.nx | — | homonym | - | homonym |
| LIAR-KILL | nx_swcompare_matrix.nx | racing, referee | — | none | unproven | undecided |
| wc_count | nx_ws_coach.nx | referee, team | — | none | unproven | undecided |
| lj_grade | nx_llm_judge.nx | referee*, extllm* | — | ambiguous | plan | ambiguous |
| em_rollup_store | nx_ecomat_lib.nx | referee, ecosystem* | ecosystem | rung | plan | home elsewhere adopt: @xrow ecosystem|em_rollup_store|home by rung (fleet duplicate census) |
Gaps from the record — what the estate does that no board carries
The record census (nx_goalmap record) reads the invoked-tool population and every plan queue row and files each organ or directive that NO matrix, plan or gates row names. A row here is a callout the boards missed: adjudicate it onto a board or declare it infrastructure. Census state STALE (age 1395628 s), sources read 4 of 7 declared — a BLIND census is a FLOOR: unread sources can only add rows.
| kind | name | board | source | evidence |
|---|
rows shown 0|this board's directives 0|estate-wide un-boarded organs 452 (listed in full on /compare/ecosystem)|census rows 639|malformed 0 (counted, never rendered)
References
- [scorecard-checks] OpenSSF Scorecard: Check Documentation (docs/checks.md) -- the automated repository security checks (Branch-Protection, CI-Tests, Code-Review, Maintained, SAST, SBOM, Signed-Releases, Vulnerabilities and others). publisher · read in our library
knowledge/fetched/cmp_instrument_scorecard-checks.html· pinh0c8e0ca6826693f3b80261f35d8f4430187dd9fd687089dd9eefaf2e9c8979bb· accessed 2026-08-18 · vendor-docGrounds: The Scorecard column and the "Supply-chain security scoring of repos" row (Scorecard IS this, graded 2; Nishi _ABSENT_), plus the partial-peer codes on "Multi-profile industry quality grading" and "Live-derived ecosystem grading" (per-commit re-runs). Mirror shared with instrument.refs. - [openai-evals] OpenAI. evals -- a framework for evaluating LLMs and LLM systems, with an open-source registry of benchmarks and model-graded evals (GitHub repository README). publisher · read in our library
knowledge/fetched/cmp_referee_openai-evals.html· pinh4b287d1c163c5b01ad84f0d6e7183118a6a1cf1f134134f422f118e40cb9460d· accessed 2026-08-18 · vendor-docGrounds: The openai-evals column: "QA benchmark harness with real question sets" (openai-evals registry harness is the bar, graded 2) and "LLM-as-judge evaluation" (model-graded evals are the bar, graded 2; Nishi _ABSENT_ for text). - [evalplus23] Liu, Xia, Wang, Zhang. Is Your Code Generated by ChatGPT Really Correct? Rigorous Evaluation of Large Language Models for Code Generation (EvalPlus). arXiv:2305.01210, 2023. publisher · read in our library
knowledge/fetched/cmp_referee_evalplus23.html· pinh570b56cda244c325ef61ef5e3630513a83c4564c05c9ba4d8a4c40cd4294091e· accessed 2026-08-18 · published-paperGrounds: The EvalPlus column: "Property-based independent oracles (never author-supplied answers)" where EvalPlus test augmentation (HumanEval extended 80x by automated test generation) is the partial peer (3) to our defining-property oracles, and "Contamination and memorization detection" (partial, 3). - [helm22] Liang, Bommasani, Lee et al. Holistic Evaluation of Language Models (HELM). Transactions on Machine Learning Research, 2023 (arXiv:2211.09110). publisher · read in our library
knowledge/fetched/cmp_referee_helm22.html· pinh3d95aeb51499159d0652860c626f21c231f4150477148d51dec2dd284870e0d5· accessed 2026-08-18 · published-paperGrounds: The HELM column: "Standardized benchmark suites (MMLU HumanEval class)" (HELM living-benchmark breadth is the bar), "Public measured-results publication" (public leaderboards, graded 2), "Cost and latency-aware evaluation" (efficiency metrics) and the multi-metric partial peer on "Multi-profile industry quality grading". - [llmjudge23] Zheng, Chiang, Sheng, Zhuang, Wu, Zhuang, Lin, Li, Li, Xing, Zhang, Gonzalez, Stoica. Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena. NeurIPS 2023 Datasets and Benchmarks (arXiv:2306.05685). publisher · read in our library
knowledge/fetched/cmp_instrument_llmjudge23.html· pinh77854867787231a84724d8825cb1754bf14a29b8a93629cf9fc00d76a0734123· accessed 2026-08-18 · published-paperGrounds: The "LLM-as-judge evaluation" row (Nishi _ABSENT_ for text; the reverse-AI-judge exists only for images): the agreement-with-humans result and the position, verbosity and self-enhancement biases any sovereign text judge must carry as neg-controls. Mirror shared with instrument.refs. - [contamination23] Golchin, Surdeanu. Time Travel in LLMs: Tracing Data Contamination in Large Language Models. ICLR 2024 spotlight (arXiv:2308.08493). publisher · read in our library
knowledge/fetched/cmp_referee_contamination23.html· pinh80bbf7ee2b9e6fe89a701f87d1446e0bf70baac8f4597c0e7c63c3bb6e9a10d1· accessed 2026-08-18 · published-paperGrounds: The "Contamination and memorization detection" row (Nishi _ABSENT_, critical for the TRAIN-our-own-model arc): a published guided-instruction detection method (92-100 percent accuracy over seven datasets) that the coming contamination rung can adopt as its bar. - [stabilizer13] Curtsinger, Berger. STABILIZER: Statistically Sound Performance Evaluation. ASPLOS 2013. publisher · read in our library
knowledge/fetched/cmp_referee_stabilizer13.pdf· pinh819c930cc8f51a65a24cdc46452a29ec2c872391724974d21589a8729dac9c49· accessed 2026-08-18 · published-paperGrounds: The "Statistical rigor (confidence intervals, paired tests)" row: the Stabilizer-validated paired bench of 2026-05-20 (layout variance) that row cites as the precedent is this paper's method -- re-randomized layout so layout effects are Gaussian and ANOVA-testable; no organ yet generalizes it. - [chatbotarena24] Chiang, Zheng, Sheng et al. Chatbot Arena: An Open Platform for Evaluating LLMs by Human Preference. arXiv:2403.04132, 2024. publisher · read in our library
knowledge/fetched/cmp_referee_chatbotarena24.html· pinh4f458a9e882f2a76eb50dfb3f0410a385de550f475a90439cb42e6a67c891cf7· accessed 2026-08-18 · published-paperGrounds: The "Human-preference evaluation" row (Arena-style preference collection absent, Nishi _ABSENT_): the pairwise crowdsourced preference platform with Bradley-Terry ranking that the row's Arena-style bar names. - [quickcheck00] Claessen, Hughes. QuickCheck: A Lightweight Tool for Random Testing of Haskell Programs. ICFP 2000 (author PDF, UPenn course mirror). publisher · read in our library
knowledge/fetched/cmp_referee_quickcheck00.pdf· pinhe7c8837a1ef48a2acbca01f21b7b12fd636b56f01e2e0f212c973c0dc74b6c46· accessed 2026-08-18 · published-paperGrounds: The "Property-based independent oracles (never author-supplied answers)" row and the "Cheat-proof grading BY CONSTRUCTION" EXCEED: sort proven ordered AND a permutation, isqrt by bounds, is property-based testing in this paper's sense -- the defining property is the oracle, never an author-supplied expected value.
generated by nx_swcompare_matrix (sovereign NishiLang organ) from knowledge/compare/referee.matrix · source checks show implementation presence; runtime and user-outcome evidence are reported separately · JavaScript supports page controls